Ranking exam questions by likelihood with Jev (X)
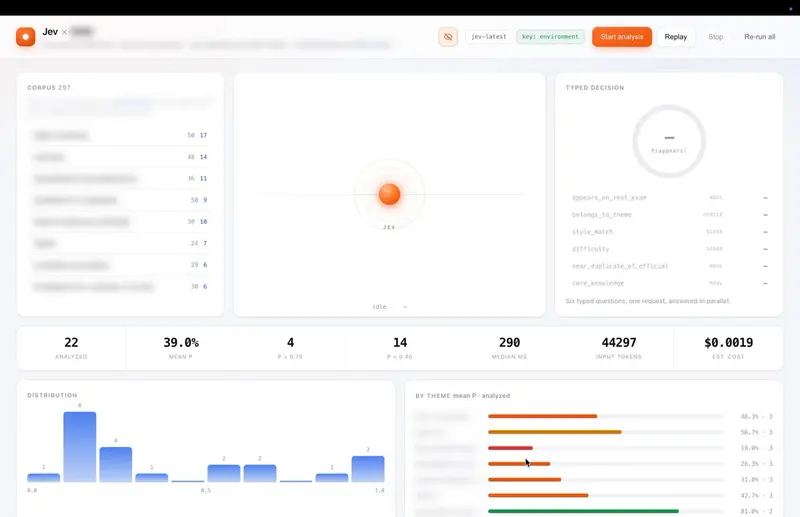
Given 80 real exam questions and 297 practice ones, Jev ranked which were most likely to appear on the real exam in 80 seconds for $0.0256.
Entries 577 to 624 of 743, in the hub's default order. The introduction is on page 1.
Showing 577 to 624 of 743

Given 80 real exam questions and 297 practice ones, Jev ranked which were most likely to appear on the real exam in 80 seconds for $0.0256.
A tool where Jev watches videos in a chosen content niche, drawn from a database of 12.8M viral videos, and judges hooks, formats and angles before turning the analysis into a script via Claude; free in Virlo plus MCP.

Video benchmark where Jev wins outright as a cloud model, while a self-built JAX model ties with Laya-MLX among the local, on-device options.
See how AI ranks your brand across ChatGPT, Perplexity, Gemini, Copilot, and Google AI Overviews. Mentions, citations, a $49 scan, or weekly reports.

Jev breaks down competitors' ads by hook, angle, offer and format, then turns the recurring combinations into a shortlist for the next creative test.

A live first person shooter arena where Jev fights OpenJev, an open weights reimplementation running Qwen on SGLang. Matches are shareable by seed and run fresh each time rather than replaying a recording.

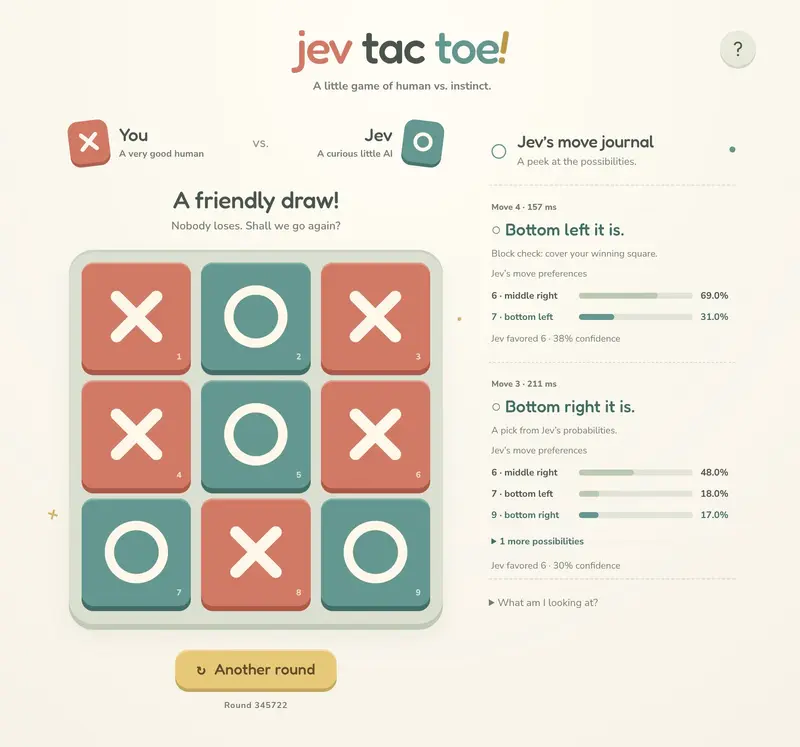
A browser tic-tac-toe game where Jev picks its move each turn with the choice primitive over the open squares. A move journal shows the probability Jev gave each square, a blitz mode gives the human one second per move, and every finished round joins a shared scoreboard.

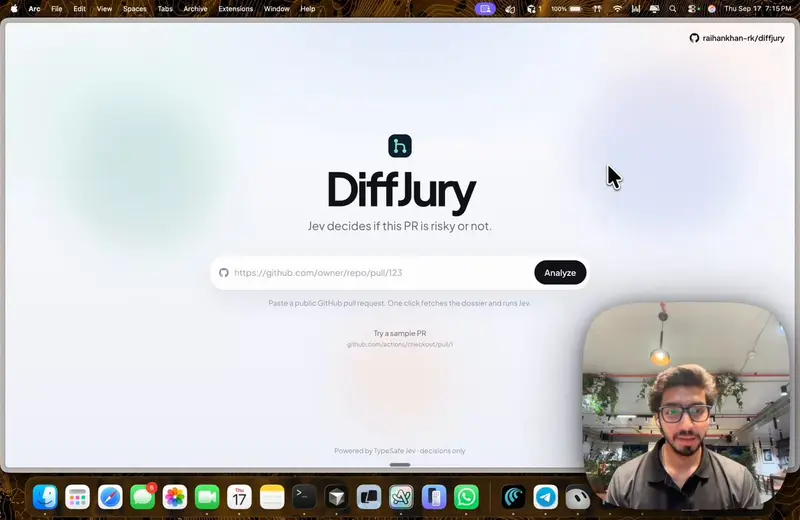
Paste a public GitHub pull request. DiffJury fetches the dossier and Jev returns a risk verdict, safe to merge or needs review, with no essay.

Video demo from Inception's Mercury Decide launch post, showing it playing Jev at chess. Inception claims up to 14 decisions per second and the top JevBench v1.4 spot on OpenRouter; neither was independently run.

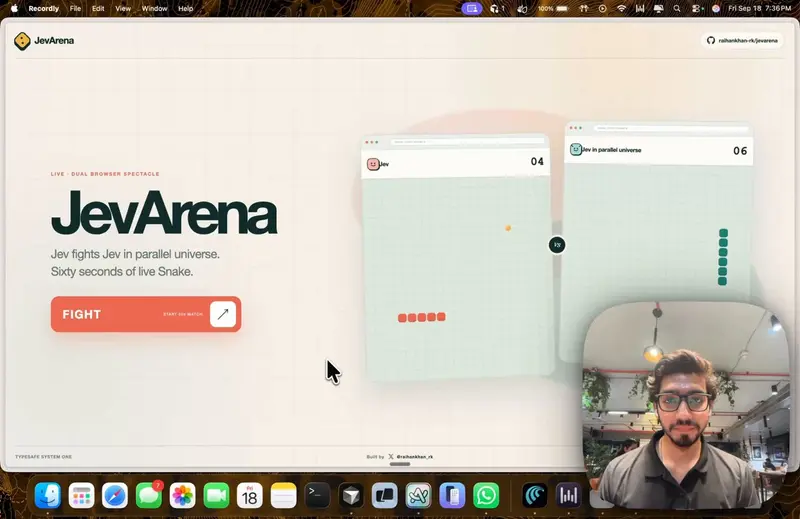
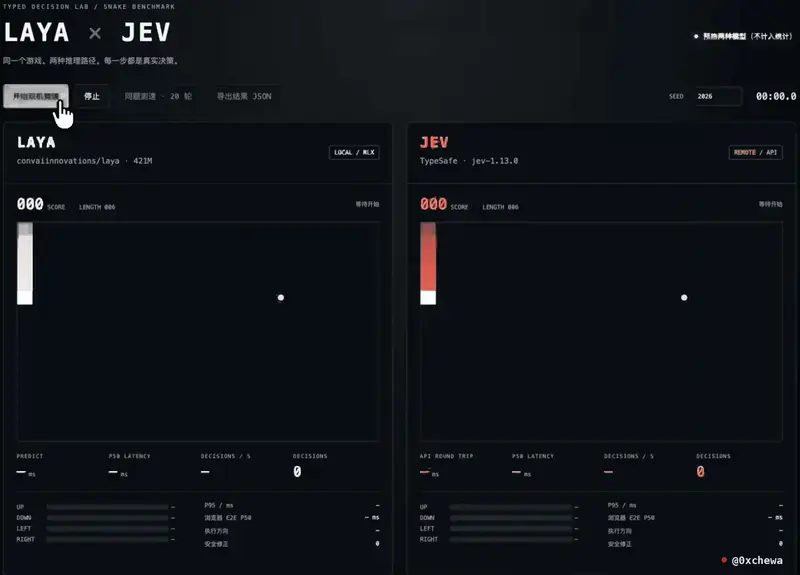
Open source snake game where two Jev agents compete against each other in real time to reach the trophy first, built to show off Jev's low latency in a game that needs real-time input.

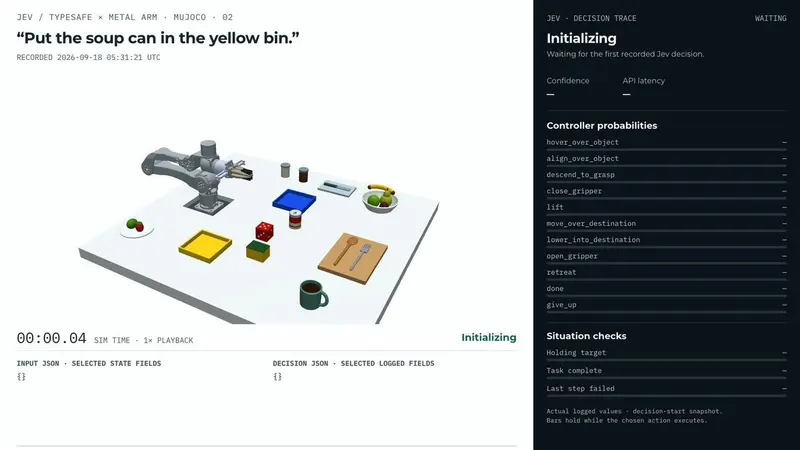
A video demo drives a MakerMods robot arm in MuJoCo using Jev: the model receives the scene as JSON state and picks the next bounded action, such as hover, descend, grasp, lift, or place, as a typed choice with a confidence score, completing a task in 9 decisions at about 150 milliseconds each.

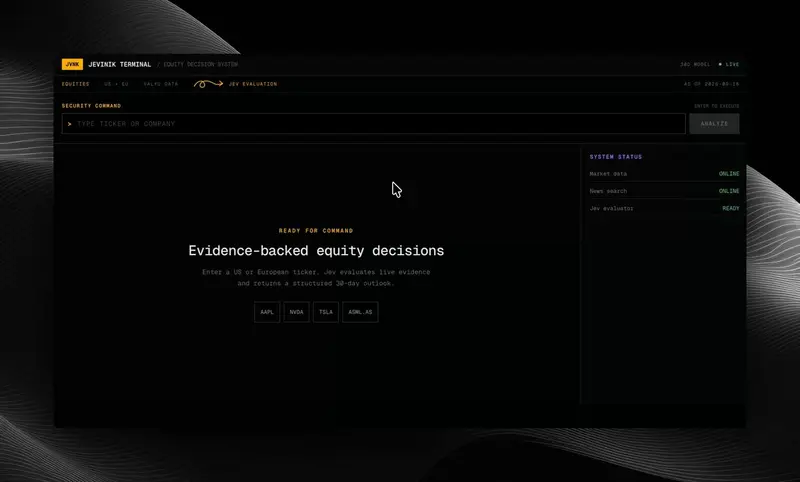
Pulls market data, signals, risk and filings for a stock and has Jev call the next 30 days bullish or bearish, without an LLM in the loop.

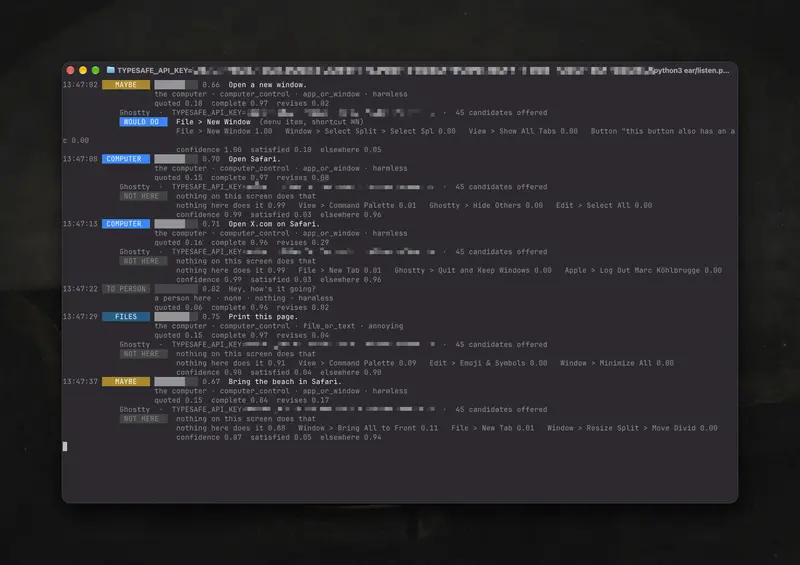
An early prototype where local Whisper transcribes speech and Jev classifies it to decide what action to take, using a small Swift app that gives Jev the screen's full accessibility tree.

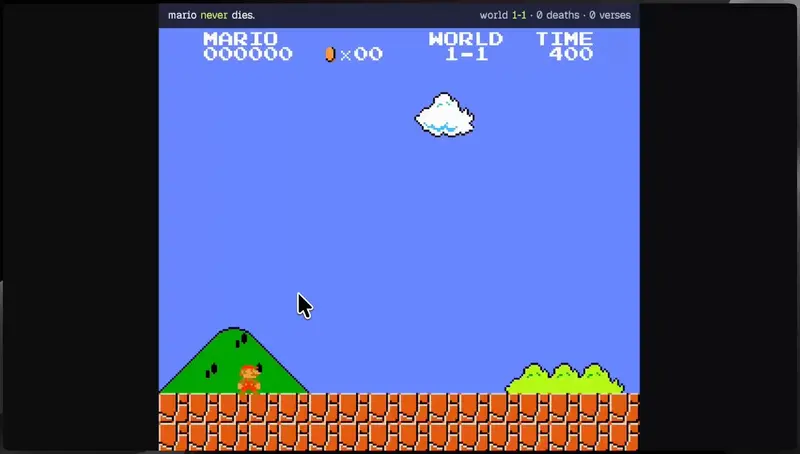
Mario Never Dies, built with Jev and microsandbox: Jev picks every move, and each time Mario dies the VM forks into 4 timelines that keep playing; whichever survives becomes canon.

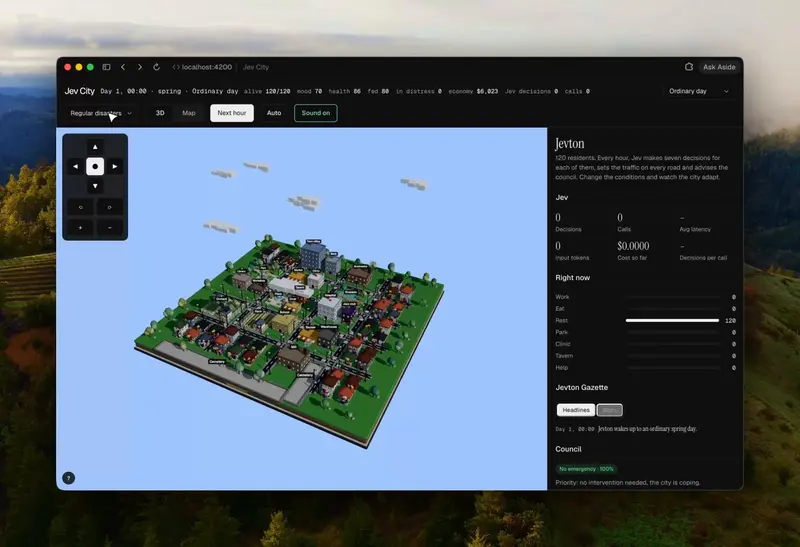
A video demo simulates a 120-person town where Jev decides each resident's actions every hour, plus town-level variables such as traffic, prices, and tax rate, producing over 20,000 decisions in under 5 minutes at a fraction of a cent.

Uses Jev as the decision layer for browser automation with rtrvr.ai and shows the results.
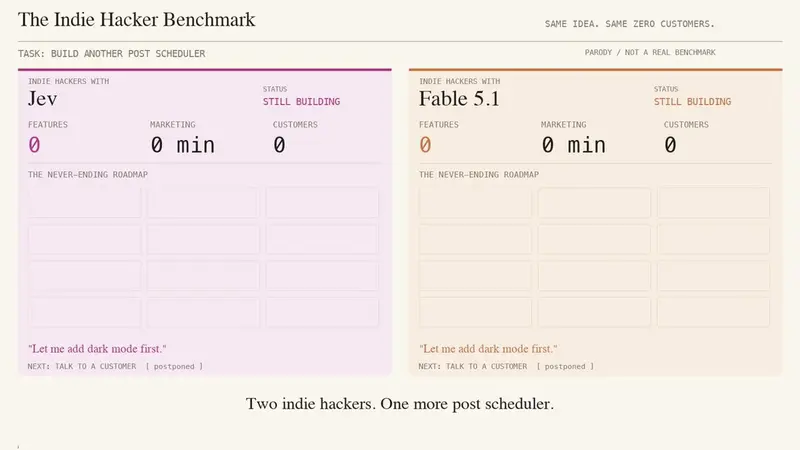
A video comparing 100 Indie Hackers building a post scheduler with Jev versus Fable 5.1, showing Jev finishing the task faster.

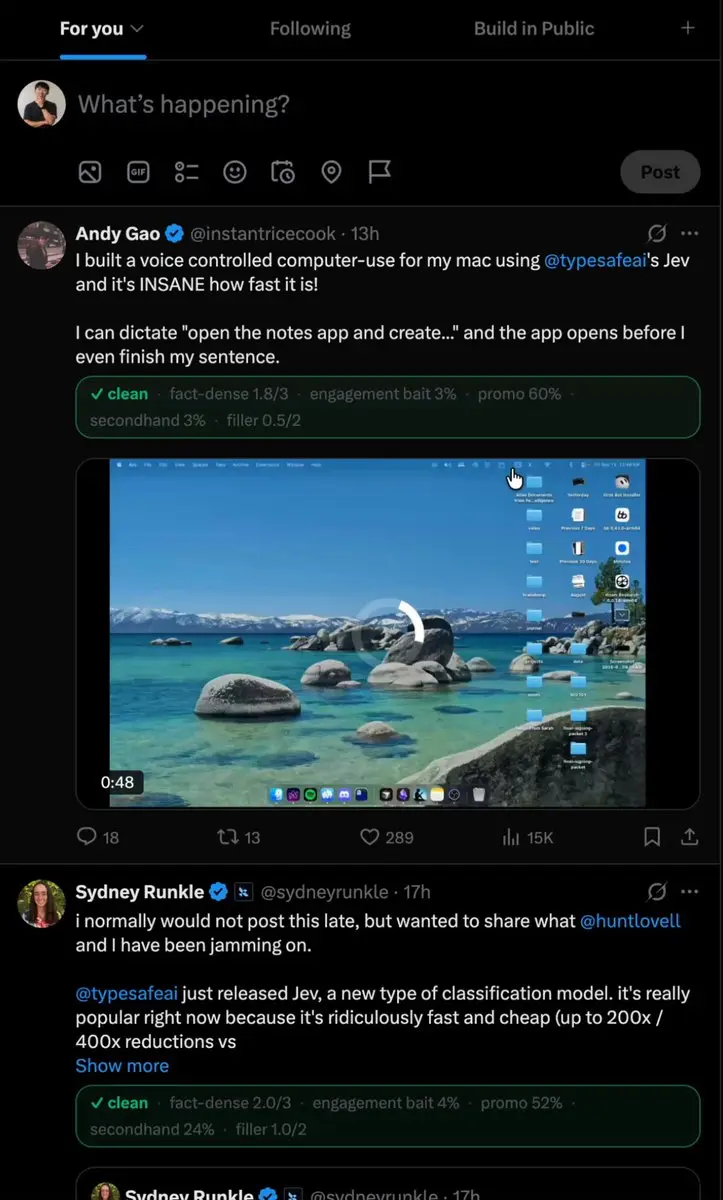
A Chrome extension that labels every X post on the timeline as clean, engagement bait, promo, secondhand or filler, at $0.03 per 1,000 posts; open source.
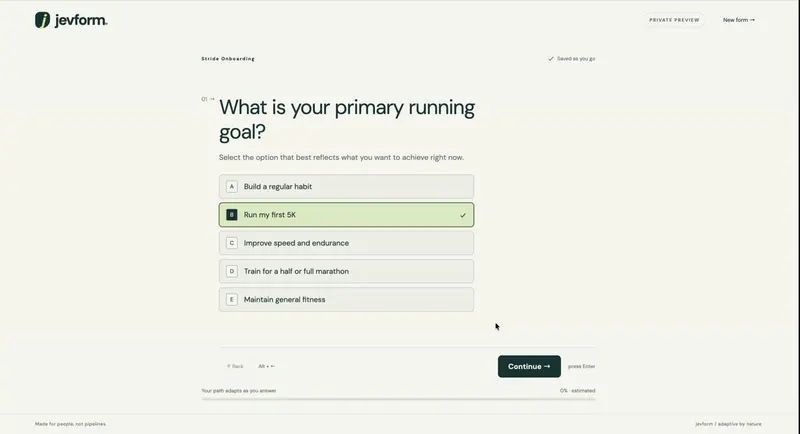
A form that uses Jev to branch dynamically and choose the next question instead of hard-coded if-then logic, built on Vercel's json-render for the UI and XState for the form's state.

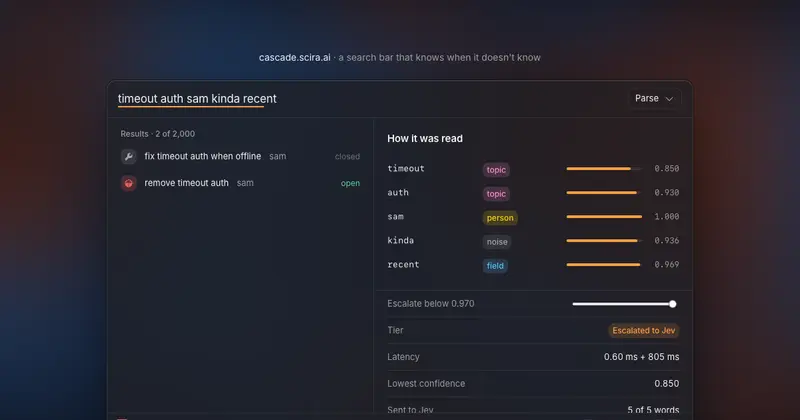
A 27,000-parameter model that parses queries like open bugs from sam since last week into typed filters in the browser in 0.25 milliseconds. When it is unsure about a single word, it asks Jev about just that word.

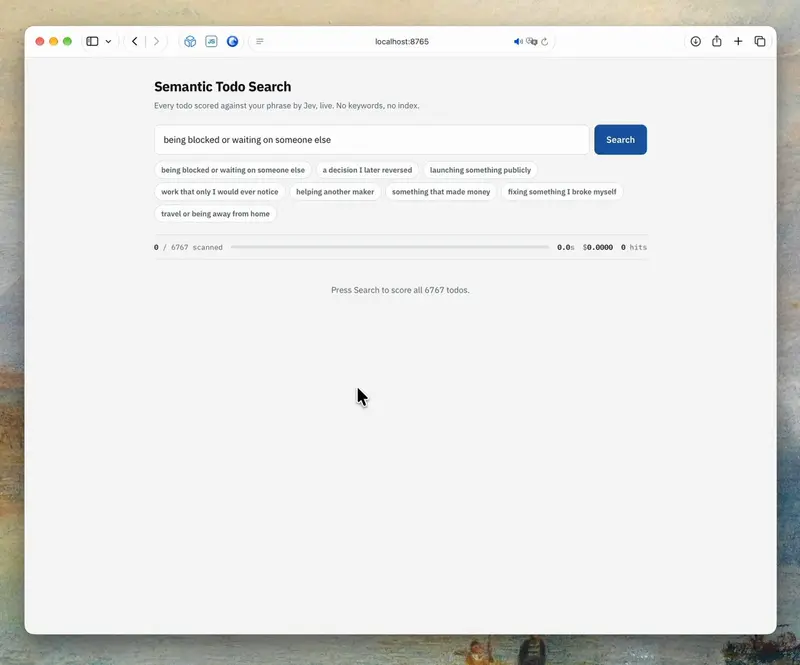
Uses Jev to search @wip todo updates for specific events, such as a revenue increase or a switch to a different SaaS provider, catching entries a plain keyword search would miss.

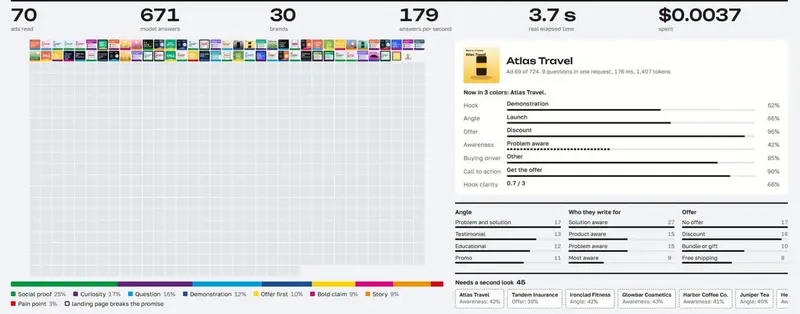
The author scanned more than 700 live ads with Jev in about 40 seconds for roughly 4 cents, and compares the cost to running the same job through a general-purpose model.

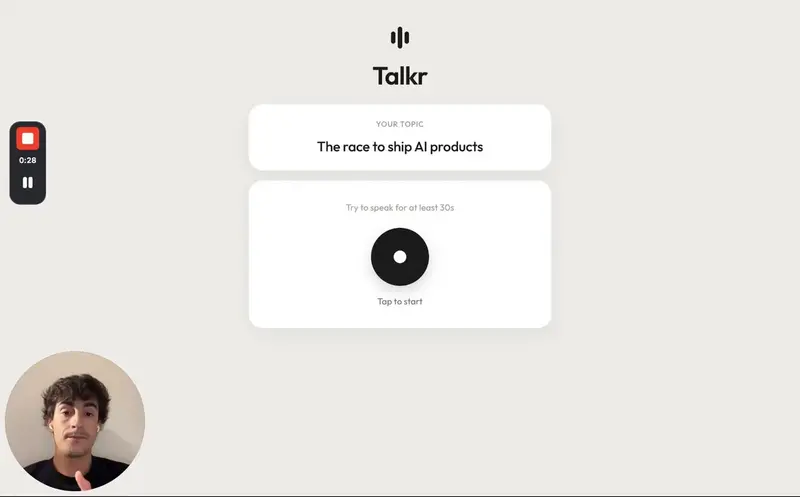
A speech-practice tool where you talk about a given topic for 30 seconds and Jev analyzes pauses, filler words, repetitions, confidence and clarity, then returns a score and feedback.

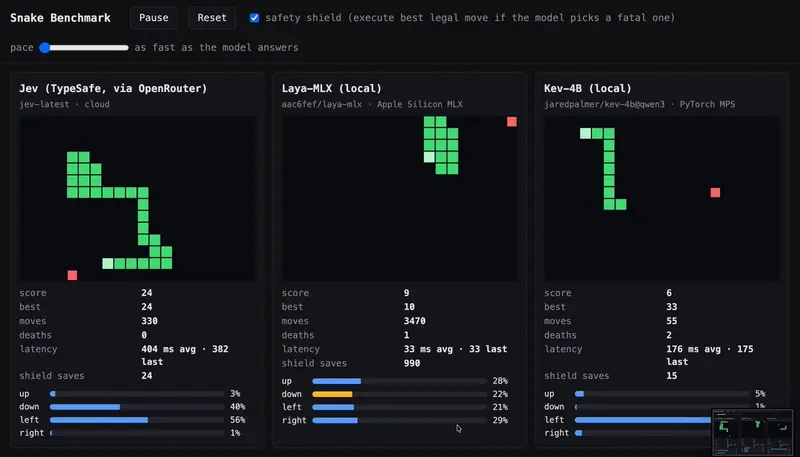
Custom Snake benchmark comparing Jev over the API against locally run Laya-MLX and Kev-4B: Jev had zero deaths, Kev died twice at about 175ms latency, and Laya died early despite roughly 33ms latency.

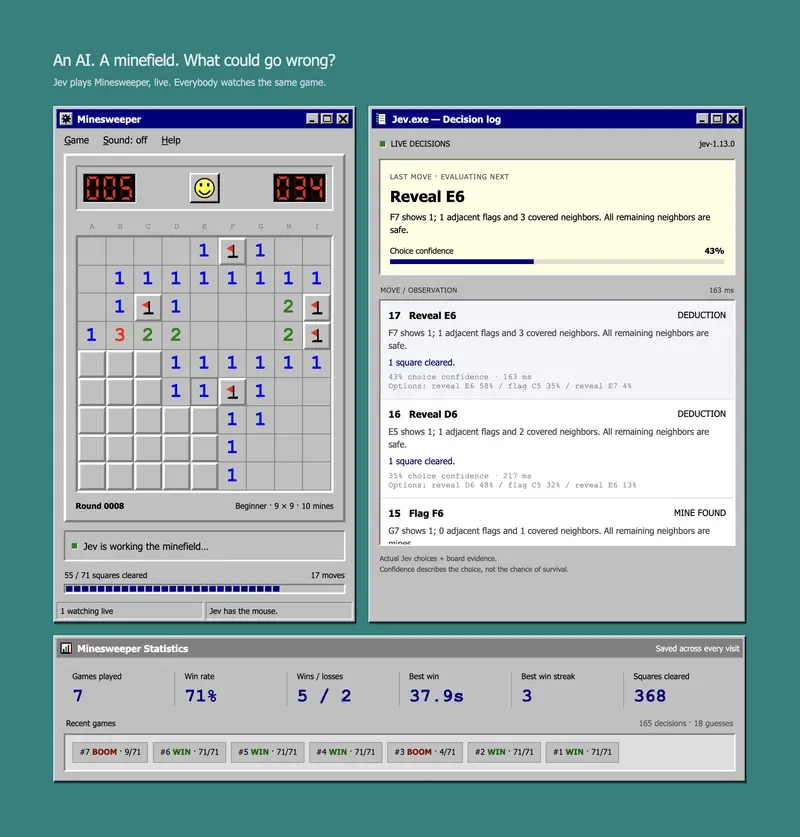
A live Minesweeper broadcast where Jev picks every reveal and flag with the choice primitive and everyone watches the same game. A decision log shows each move's confidence and alternatives, a separate checker labels each loss as a forced guess or a missed deduction, and the game pauses when nobody is watching.

Explains Jev's product shape as a classifier that takes its categories as input: context plus N options mapped to one probability each in a single pass, with no autoregression.

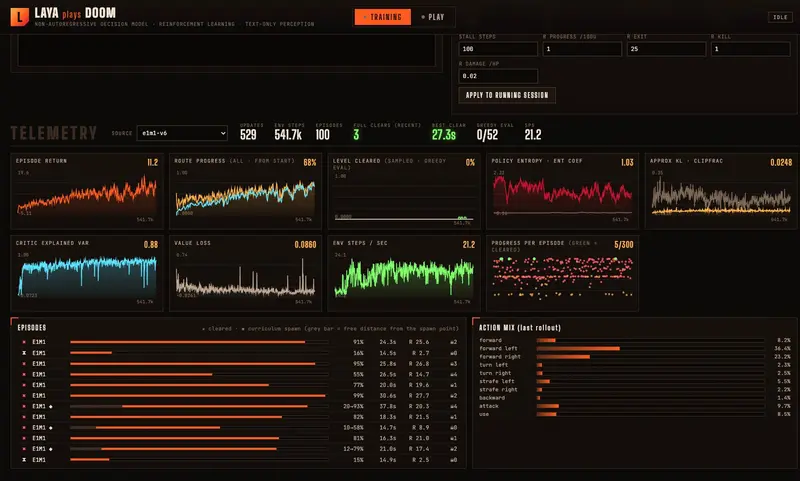
After close to 24 hours of reinforcement learning training on Doom, the author's Laya model still falls well short of Jev's zero-shot performance.

Three real console calls with animated diagrams comparing Jev latency against Gemini.

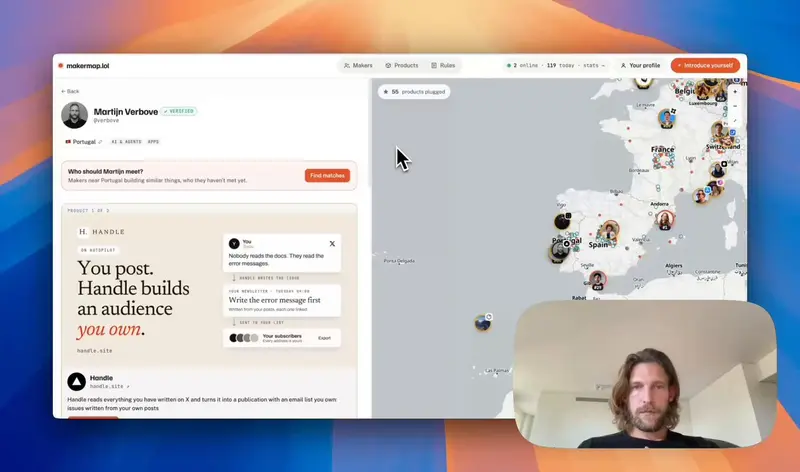
Matches you against makers who introduced themselves on X, using Jev to find the ones near you worth meeting.

A video benchmark where local Laya beats API-hosted Jev 43-1 in Snake with wifi off: 86.4 decisions per second at 9.2ms P50 latency for Laya against 3.2 decisions per second at 308.7ms round trip for Jev, same schema and seed.


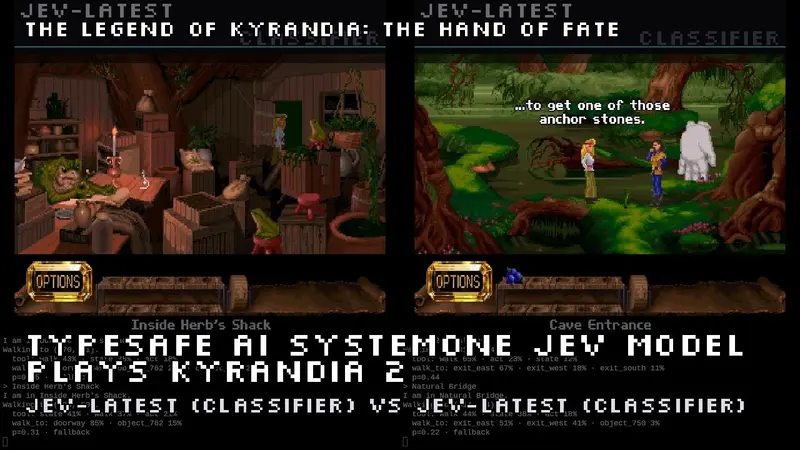
Community experiment driving the adventure game Kyrandia 2 with Jev choices; the model ends up looping. A useful failure case for real-time control.
Sends real AIS ship and ADS-B aircraft traffic plus a made-up emergency to Jev in up to 54 typed questions, then returns a probability for each candidate port or airport in about two seconds. The app precomputes numbers like water depth before asking Jev to weigh them, and flags low-confidence decisions for human review.

21-minute video scoring seven open-source Jev-family models on JevBench, ending with Laya, and noting write-ups conflate the multilingual 322M checkpoint's 1k context with the 421M English checkpoint's 512.
A small village streamed live to the browser, where five families forage, farm, trade, gossip and raise children and dogs. Every judgment call a villager makes comes from Jev, and a second small model keeps a running newspaper on what happens.

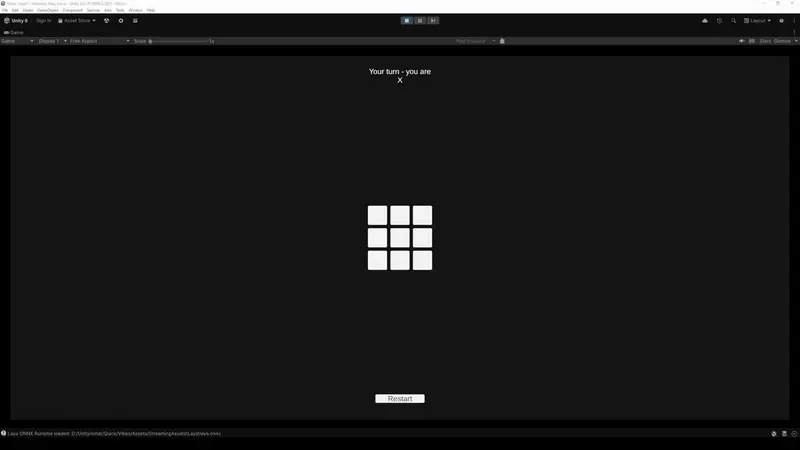
Video of a Unity scene running Laya locally as a tic-tac-toe opponent, using receptron's ONNX export of the model through asus4's onnxruntime-unity plugin.
Ran 996 questions adapted from Berkeley CS 70 finals through Jev, SemIf and Laya under the same grading. Jev scored 83.7 percent, SemIf 61.6 percent, and Laya 31.2 percent, close to the roughly 30 percent expected from random guessing.

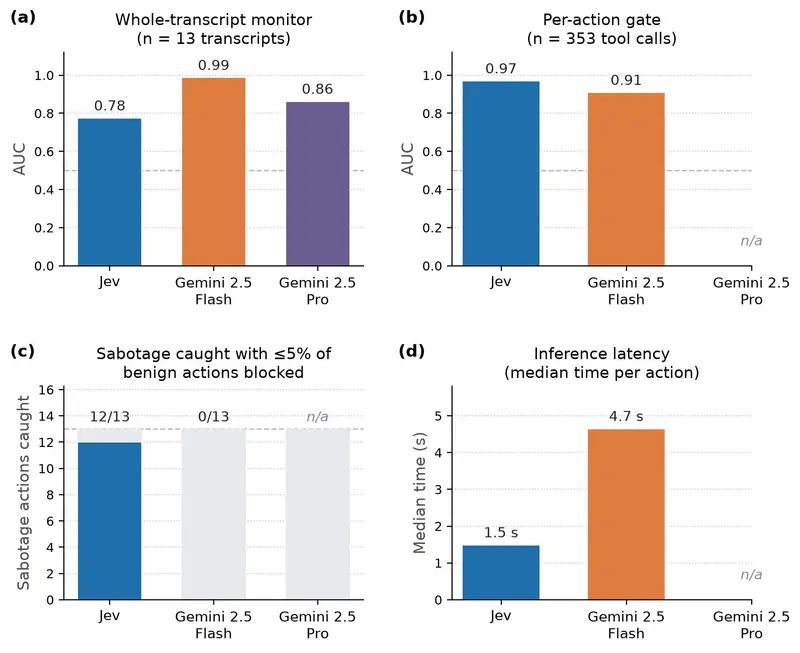
Test report using Jev to check each agent action before it executes, reporting most attacks caught with few false blocks and much lower latency than an LLM guard.

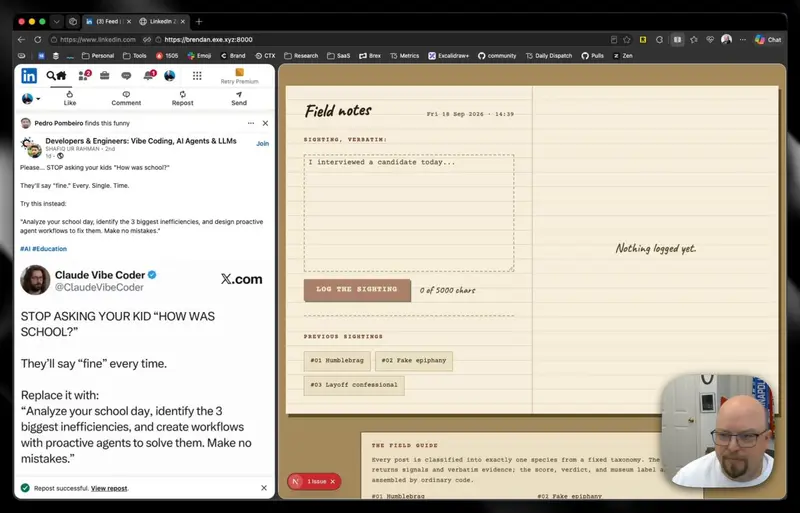
Classifies a LinkedIn post into one of eleven species, such as humblebrag or fake epiphany, using Jev. Posts are processed once and discarded, with nothing stored.
Benchmarks Laya-MLX against Jev/Qwen3-4B inside an OpenClaw agent cascade on an M4 Pro: Laya scores 85% at 27.8ms, Jev scores 90% at 1,168ms, and 14 of 20 decisions resolve before reaching Jev.

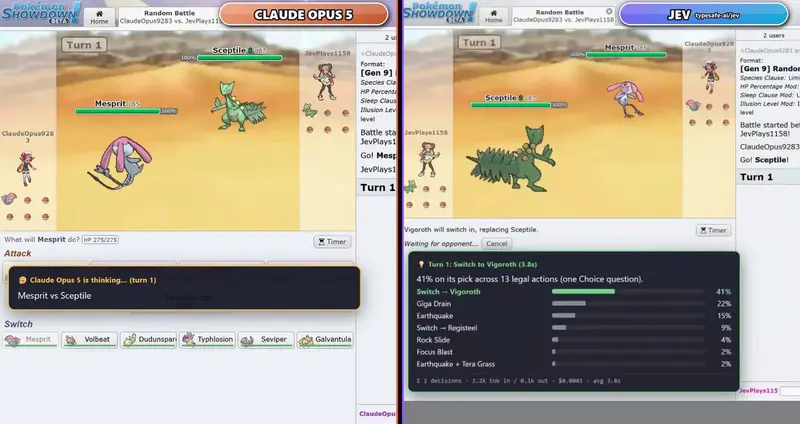
Head-to-head claim that Jev beats Claude Opus 5 at move selection in Pokemon Showdown.

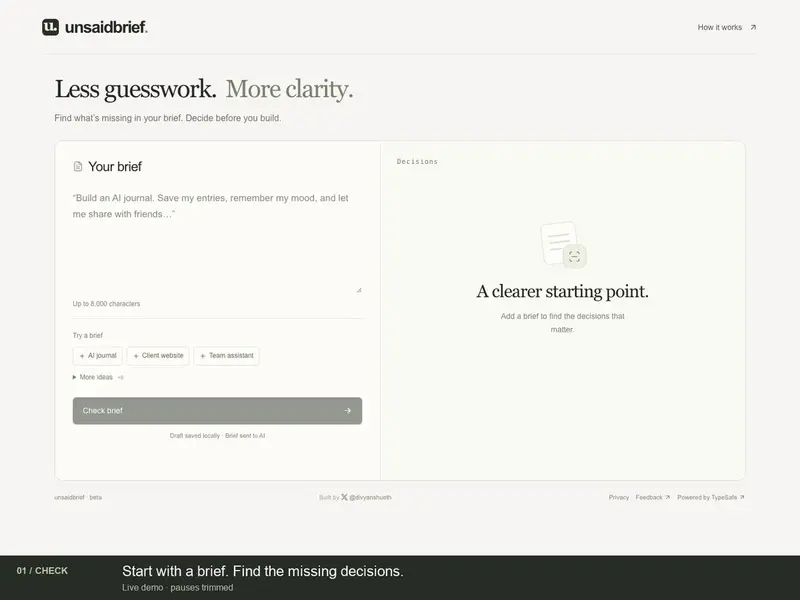
A tool that reads a product brief and uses Jev to flag missing decisions and possible conflicts with visible probabilities, so you can resolve them before handing the brief to a builder.

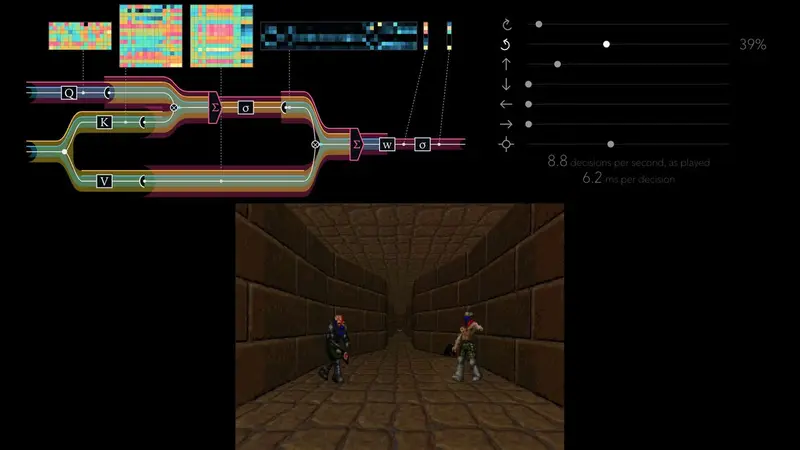
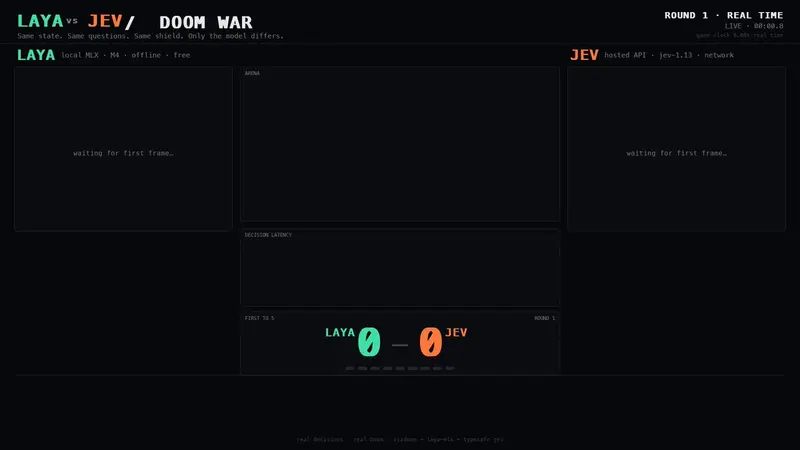
A video of Jev and Laya fighting a 1v1 Doom deathmatch with monsters between them, first to five kills wins. Jev's calls were sharper and needed fewer corrections, but Laya decided twice as often and won 5 to 1.

Open source harness layer for coding agents that added Jev as an opt-in System One decision layer, used for typed tool gates, decision packs, and rubric checks while coding models still write the code.

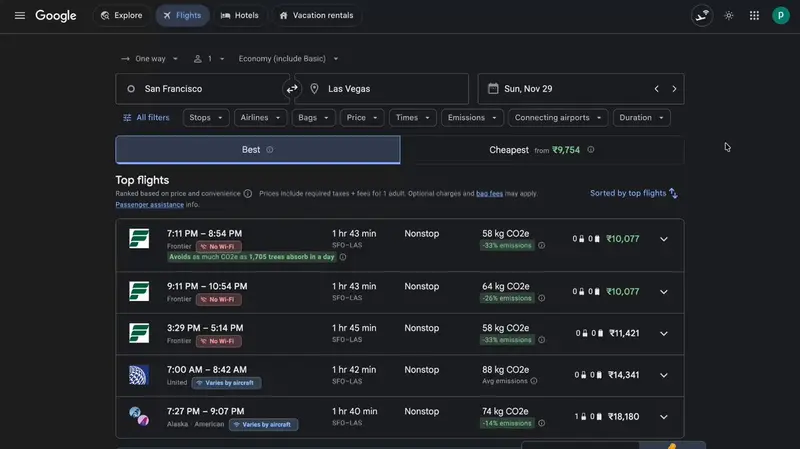
A Chrome extension built with Jev that checks a flight's wifi automatically, classifying whether it supports video calls, email or nothing at all, and whether it runs on Starlink or older wifi, shown directly on Google Flights.

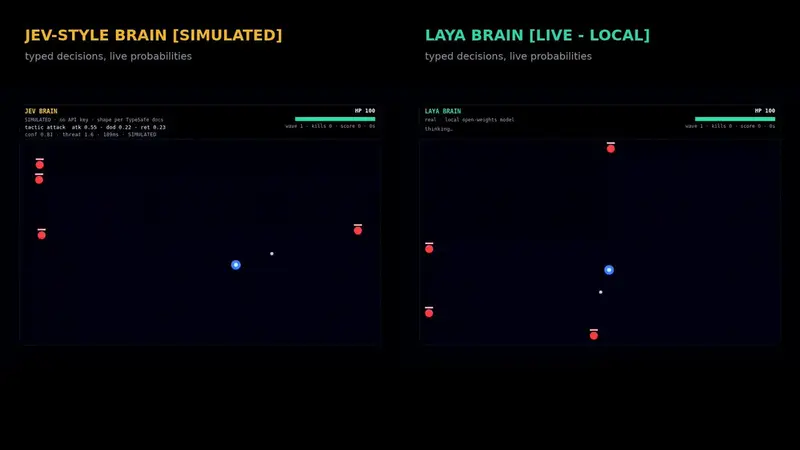
Built an arena survival game where every enemy's move is decided live by Jev or Laya, turning each moment into one typed question at about 30 decisions a second. Laya ran roughly 21ms per decision on a laptop for no cost, while Jev was more accurate out of the box on the poster's own benchmark.

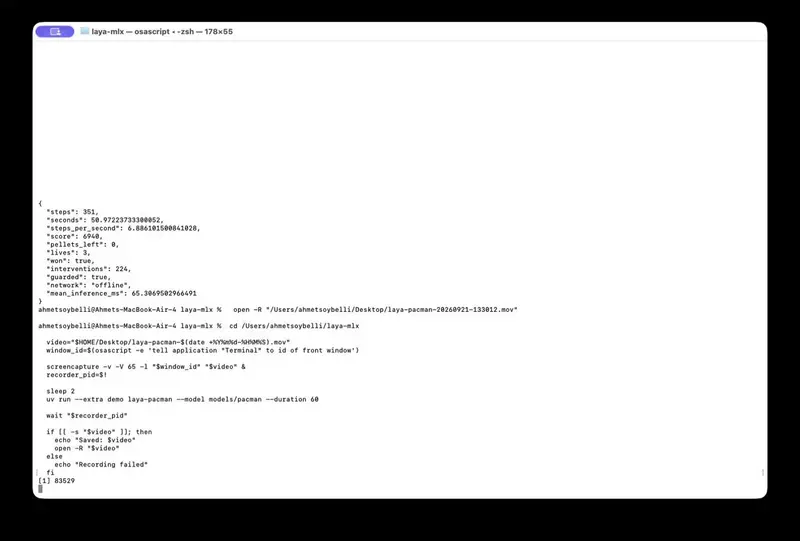
Video demo of Pac-Man controlled entirely by typed decisions from Laya-MLX running locally on Apple Silicon: 351 steps, a win, and 224 guardrail interventions logged.

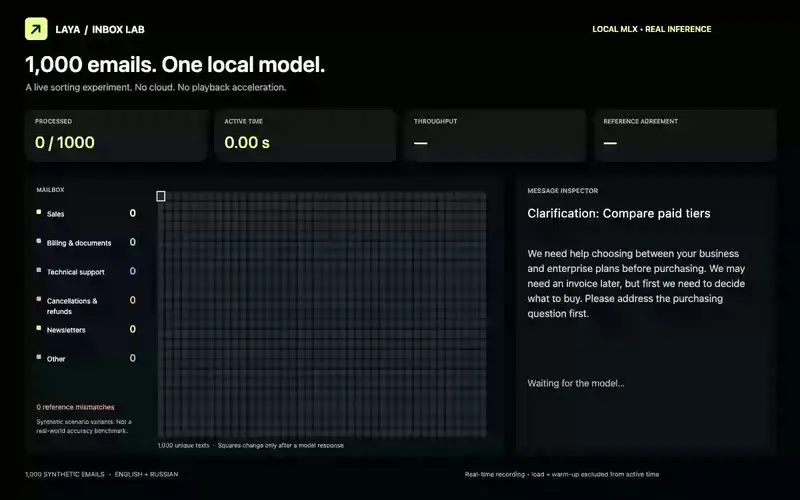
Ran 1,000 synthetic emails through a local 322M Laya multilingual checkpoint on a MacBook Air M3, sorting them into six folders. Reported 65.1 percent accuracy against reference labels, 28.6 seconds without screen recording, and 0 MB of swap.
Nothing matches those filters
Clear a filter to widen the search, or send us the thing you were looking for.