What the Decisions API is
The Decisions API is OpenAI’s hosted API for typed decisions. It does the job of a System One model, though OpenAI does not use that term. OpenAI announced it at DevDay on 29 September 2026, opened a public beta on 6 October and made it generally available on 22 October. You send input as text or as user messages with text, images and JSON, plus a list of named questions. The API returns one typed answer per question. It runs on GPT-6 Luna, the cheapest model in the GPT-6 family, and gpt-6-luna is the only model it accepts.
What it returns
The request is POST https://api.openai.com/v1/decisions. OpenAI’s guide documents three question types. A predicate returns the probability that a condition is true, which is what this site calls a Noul. A Choice returns one of your values, a probability for every option and a confidence field. A Score takes ordered levels and returns a probability-weighted average of the level indices, with per-level probabilities and a confidence. Answers come back in an answers array keyed by each question’s name, and a question can also come back as a refusal.
OpenAI does not say whether the probabilities are calibrated. Its guide tells you to set thresholds from labeled examples of your own.
What it is good at
OpenAI names three jobs: classify content, route requests, and choose an agent’s next action. Its X thread gives a support request and the teams it could go to as the example. Those map to support inbox triage, intent and model routing and agent routing and skill selection.
How it compares with Jev
Both are hosted APIs that answer typed questions with probabilities, and both bill input tokens only. The Decisions API costs $0.10 per million input tokens against $0.042 for Jev. It accepts images by default, where Jev reads text unless you send an opt-in header that TypeSafe says is not ready for production. Its context window on OpenRouter is 1,050,000 tokens against Jev’s 64,000, or 262,000 with Jev’s opt-in long context. TypeSafe says Jev’s probabilities are calibrated; OpenAI makes no such claim.
Every, which had preview access, ran early tests. On a text replay of computer tasks, the Decisions API picked the right control in 76 of 78 steps against 73 for Jev. On a thread-classification test the two tied on accuracy and Jev was faster. Every says the Decisions API beat Jev on a few early tests but trailed on its broader evals. These are the testers’ own results.
The Artificial Analysis Decision Index v1.0, published on 13 October 2026, is the first independent board to score it, under the name GPT-6 Luna (Decisions). It ranked ninth of the 11 decision models it listed at launch, at 48.5 against 57.5 for Jev. On version 2.1, checked on 14 November 2026, it scores 60.2, 20th of 22 decision models, against 66.2 for Jev 1.14; it was 17th of 19 on 12 November. Its accuracy on AA’s private knowledge questions, 42.6%, is second best of the 22, but its score on AA-Symmetry, which checks that an answer holds when the options are moved or reworded, is the lowest, 54.9. It cost $339 per million tasks against Jev 1.14’s $156 and took 206 ms per task against 92 ms. Its calibration error, which this site computed from AA’s published bins, is 0.110 against Jev 1.14’s 0.054. The same GPT-6 Luna called as a language model with low reasoning scores 68.8 on the same tests, at $485 per million tasks and about 4,400 ms per task. The Decisions API has no row on the Jev Decision Index.
The request shape is not Jev’s. OpenAI uses input instead of state, a questions array with a name on each item instead of a keyed map, and predicate instead of noul. A client written for /v1/systemone needs changes to call it directly.
What is not known yet
As of 12 November 2026, OpenAI has published no benchmark, latency figure in milliseconds, calibration data or cap on options per choice. It now documents 400 questions per request and 2 to 10 score levels. The New Stack also lists whether developers can tune it on their own data as unclear.
Access
The Decisions API has been generally available since 22 October 2026, after a week of limited preview for selected customers and a public beta from 6 October. You call it with an OpenAI API key, and the official SDKs support it from Python 3.26.0 and JavaScript 7.30.0, as well as Go, Ruby and Java. OpenAI also offers it in the Playground. It supports Zero Data Retention and HIPAA use for eligible customers. Data residency is available in all supported API regions, and regional processing in the United States and Europe.
OpenRouter has listed it since 6 October 2026 as openai/gpt-6-luna-decisions, at the same $0.10 per million input tokens, served by OpenAI with moderation on. It was second on OpenRouter’s decision leaderboard for the week to 8 October, with 6.75 million requests, checked on 2026-10-09. By 12 November 2026 OpenRouter also served it through Azure, at the same price.
Specifications
| System One Score | 84.6 from 2 of 3 boardsArtificial Analysis Decision Index 82.9, JevBench 86.3. How the score works |
| Inputs | Text, imagesImages as base64 data URLs or public URLs. File ids, files and audio are not supported. |
| Question types | ChoiceScoreNoul |
| Max Choice options | Not documented |
| Score levels | Up to 10 |
| Questions per call | 400 |
| Total context | Not documented |
| State budget | Not documented |
| Rate limit | Not documented |
| Endpoint | POST https://api.openai.com/v1/decisions |
| Licence | Not published as of 12 Nov 2026 |
| SDKs | Python: openaiJavaScript: openai |
OpenAI's Decisions guide allows 1 to 400 questions per request, up from 200 in public beta, and 2 to 10 levels per score question. It publishes no cap on choices. OpenRouter lists openai/gpt-6-luna-decisions with a 1,050,000-token context and a 945,000-token maximum completion, the same window as GPT-6 Luna. OpenAI's own docs do not state a separate window for the Decisions API. Images can be inline base64 data URLs or public HTTP or HTTPS URLs, in input or in a question's instructions, and share one set of request image limits; file_id inputs are not supported. Structured data can go in an input_json content part. Prompt caching needs a shared input prefix of at least 1,024 tokens. Checked on 2026-11-12.
Versions
- Limited preview, 29 Sep 2026, OpenAI names no version or model id. It describes the API as built on GPT-6 Luna, and The Decoder describes a version of Luna made for it. Preview access is limited to selected API customers. Release notes
- Public beta (gpt-6-luna), 6 Oct 2026, OpenAI's changelog lists the Decisions API as released in beta with gpt-6-luna on 6 October. The guide then said it was in public beta, that gpt-6-luna was the only model, and that OpenAI expected general availability in the coming weeks. A request took up to 200 questions. OpenRouter lists it as openai/gpt-6-luna-decisions, snapshot openai/gpt-6-luna-decisions-20261006. Release notes
- General availability (gpt-6-luna), 22 Oct 2026, OpenAI's changelog lists the Decisions API as generally available with gpt-6-luna on 22 October. It added prompt caching for shared input, images inside individual question instructions, structured data through an input_json content part, and up to 400 questions per request. The guide also lists public image URLs, conversation history with tool calls, organisation usage reporting, Private Link and a native GPT-Live integration, which the changelog dates to 15 October. gpt-6-luna is still the only model, and the input price is unchanged at $0.10 per million tokens. Release notes
Use cases
What people use OpenAI Decisions API for, one page per pattern.
Support inbox triage with System One models
Send a support ticket to Jev once with every question attached. Category comes back as a selected label, severity and frustration as numbers on scales you wrote, refund intent as a probability. Your code reads those values and decides what happens to the ticket.
Intent and model routing with System One models
One Jev call reads an incoming request and returns its intent as a label plus a difficulty rating on a scale you wrote. Your router reads both numbers and picks the handler: deterministic code, a cheap model, an expensive one, or a human queue.
Agent routing and skill selection with System One models
An agent choosing from a long skill roster reads one truncated line per entry and often loads the wrong thing. Jev ranks every entry in one request and separately answers whether any skill applies at all, so the agent gets a short hint instead of a guess.
Examples built with OpenAI Decisions API
The most-starred and most-viewed entries in the directory. All OpenAI Decisions API examples.
Microsoft-Decision-1: Our model for fast decision-making
Microsoft's launch post for Microsoft-Decision-1, a Qwen3.5-9B decision model on Foundry at $0.042 per million input tokens. Its vendor-run charts, run on an undisclosed 36-benchmark suite, now include Jev: 82.3% accuracy and 93.7 calibration against 83.5% and 92.2 for Microsoft-Decision-1.
 Satya Nadella (@satyanadella)454k viewsOpenMicrosoft-Decision-1: Our model for fast decision-making on commandline.microsoft.com
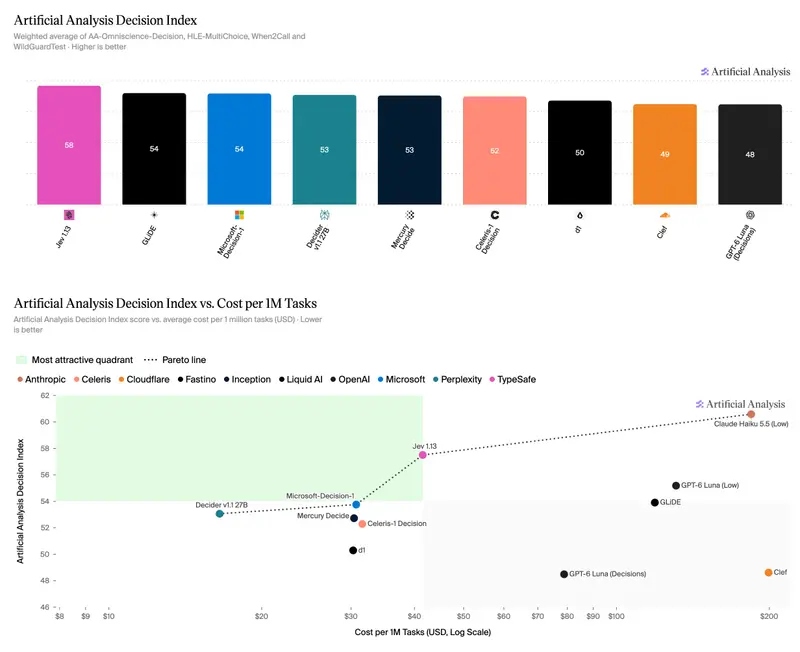
Artificial Analysis Decision Index: 11 hosted decision models against language models
Artificial Analysis scores 11 hosted decision models on knowledge, reasoning, tool-calling and safety tests, with cost and time per task, and runs language models on the same tests. Jev 1.13 led the decision models at launch at 58, and on version 2.1, checked 12 November, Nace.AI's Drex Max v1.1 leads at 72.6; at launch Claude Haiku 5.5 (Low) scores 61 but takes 1.4 seconds per task against 0.13.
 Artificial Analysis (@ArtificialAnlys)45k viewsOpenArtificial Analysis Decision Index: 11 hosted decision models against language models on artificialanalysis.ai
Benchmarks
Published scores, each linked to its source. A row marked vendor-run was measured by the vendor itself, so read it as one side's result. The compare hub sets these beside the other models.
| Benchmark | Metric | Score | Run by | Date |
|---|---|---|---|---|
| Artificial Analysis Decision Index 2.1 | Index score | 60.2 score | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Expected calibration error | 0.1103 ECE | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Cost per 1M tasks | 339 USD | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Time per task | 206 ms | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 1.0 | Index score | 48.5 score | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Expected calibration error | 0.1547 ECE | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Cost per 1M tasks | 79 USD | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Time per task | 168 ms | Independent | 13 Oct 2026 |
| JevBench 1.8.10 | Capability Score | 73.5 score | Independent | 6 Oct 2026 |
- Artificial Analysis Decision Index, Index score: Row: GPT-6 Luna (Decisions), host OpenAI. Raw value 60.246. 17th of 19 decision models on version 2.1 on 2026-11-12, and 20th of 22 on 2026-11-14. Sub-scores: When2Call accuracy 74.4, Omniscience accuracy 42.6, HLE-MultiChoice accuracy 7.9. Version 2.1 figures do not compare with version 1.0 figures.
- Artificial Analysis Decision Index, Expected calibration error: Row: GPT-6 Luna (Decisions). Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: GPT-6 Luna (Decisions). AA's measured cost per million tasks on its version 2.1 evals.
- Artificial Analysis Decision Index, Time per task: Row: GPT-6 Luna (Decisions). Time per task.
- Artificial Analysis Decision Index, Index score: Row: GPT-6 Luna (Decisions). Sub-scores: Omniscience accuracy 40.6, non-hallucination 10.1, HLE-MultiChoice 11.7, When2Call 74.1, WildGuardTest F1 82.8.
- Artificial Analysis Decision Index, Expected calibration error: Row: GPT-6 Luna (Decisions). Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: GPT-6 Luna (Decisions). AA's measured cost at list prices on its four evals.
- Artificial Analysis Decision Index, Time per task: Row: GPT-6 Luna (Decisions). Median time per task.
- JevBench, Capability Score: Row: OpenAI Decisions (gpt-6-luna). Intelligence 56.9, Calibration 90.1. 21st by Capability Score on the hosted API board. Board release v1.8.10, read 2026-11-15.
Comparisons
Head-to-head pages that put OpenAI Decisions API against other models. Every model sits in one table on the compare hub.
Jev vs OpenAI Decisions API: price, API and what's known
OpenAI's Decisions API is generally available on GPT-6 Luna at $0.10 per million input tokens. How it compares with Jev on price, request format, images and evidence.
Updated
Microsoft-Decision-1 vs OpenAI Decisions API: two hosted decision models
Microsoft-Decision-1 and OpenAI's Decisions API (GPT-6 Luna) side by side: price, input, context, request format and Microsoft's own benchmark claims.
Updated