What Jev is
Jev is TypeSafe AI’s System One model, a classification model that reads a block of text and answers typed questions about it. You supply the state, which is the text you want judged, and the questions, which you define in your own code. It answers each one and stops. It does not write a reply, produce code, or explain itself.
Questions come in three shapes, Choice, Score and Noul, each walked through in Choice, Score and Noul. Several questions in one request are evaluated against the same state in parallel.
TypeSafe says it trained the model with Reinforcement Learning for Calibrated Decisions, so the probabilities are meant to match real outcome rates rather than match what a human rater prefers to read. No paper, dataset or training recipe has been published, which RLCD explained goes through. TechCrunch reported on 18 September 2026 that “Almeida says Jev is trained exclusively on synthetic data using a technique he calls ‘reinforcement learning from calibrated decisions.’” That is the only public statement about the training data, and TechCrunch renders the acronym as “from calibrated decisions” where TypeSafe’s own docs say “for calibrated decisions.”
Jev guides and comparisons
- New to Jev: What is Jev AI? is the plain-English explainer.
- Latest release: Jev 1.14 covers the new version, the alias switch and the danger zone features.
- Getting started: how to get Jev access and using Jev with Hermes.
- Cost and speed: Jev speed and pricing and Jev benchmarks.
- Internals: how Jev is built and RLCD explained.
- What people build: Jev game demos.
- Other options: Jev alternatives, plus Jev vs Microsoft-Decision-1, Jev vs Clef, Jev vs pplx-decider, Jev vs Claude, Jev vs GPT, Jev vs BERT and Jev vs GLiNER.
Jev versions and aliases
Two versions are published. jev-1.13.0 is the stable release, and jev-1.14.0, released on 14 October 2026, is the newest. The docs define jev-latest as “the most recent stable, official release” and jev-preview as “the most recent release, official or not.” On 15 October 2026 jev-latest still pointed at 1.13.0 and jev-preview at 1.14.0. TypeSafe’s release post says jev-latest moves to 1.14.0 in one week, so around 21 October. Jev 1.14 covers what changed and the opt-in danger zone features that shipped with it.
Pinning a versioned id rather than an alias keeps the published weakness list matched to the model you are actually calling, and the response’s model field names the version that answered. TypeSafe promises 60 days’ notice before 1.13.0 is deprecated and 30 days for 1.14.0.
What Jev 1.13 does badly
TypeSafe publishes a jaggedness page per version. The one for 1.13 was last reviewed on 17 September 2026 and lists nine failure modes.
- Literal reading: the model “answers the question you wrote, not the one you meant.”
- Math and numbers: counting, numeric representations, and arithmetic attempted through a Score are all weak. The page ships a runnable Python sample that counts by asking one Noul per item instead.
- Date and time comparison: Jev “reads dates as text, not as ordered quantities.”
- Indirection: “instructions carrying double negatives or complex indirection are answered less reliably.”
- Large state full of irrelevant detail: accuracy falls as the state grows with content unrelated to the decision. TypeSafe’s own name for the cause is context rot.
- Adversarial content: “state is data, and
jev-1.13does not treat it as hostile by default.” Screening user-supplied text is your job, which is what the prompt injection screen recipe is for. - Contradictory instructions and criteria: answers degrade when the
instructionsand thecriteriapull in different directions. - Common-sense structural invariants: the page works two numbers through, an idea that scores 0.22 as a Noul but comes back at 0.99 when asked as a Choice, and a Noul plus its negation summing to 1.19 instead of 1. TypeSafe’s line is that “there are many reasons that
P(noul)and1 - P(not noul)may not be directly comparable.” - Generation: “
jev-1.13is not trained to generate text.”
The page closes by telling you to avoid System Two tasks, which it describes as work with “more layers of indirection.”
How independent boards score Jev
The Artificial Analysis Decision Index v1.0, published on 13 October 2026, ranked Jev 1.13 first of the 11 decision models it listed at launch, at 57.5. As of 23 October 2026 it lists 17. Liquid’s d1-ultra leads at 65.2, ahead of SubQ Snap 1.1 at 65.0 and Baseten’s Elephant 9B at 64.7. Jev 1.13 is fourth at 57.5 and Jev 1.14 fifth at 57.1. It averages four tests: private knowledge questions that also reward answering “I don’t know” over a wrong answer, multiple-choice reasoning questions from Humanity’s Last Exam, NVIDIA’s When2Call tool-calling test, and WildGuardTest safety classification. Jev 1.13’s best result is 93.6 F1 on WildGuardTest. Its weakest is 20.9% on the reasoning questions, which is still the top score of the 17 on that test. It cost $42 per million tasks and took a median 127 ms per task. Jev 1.14 cost the same $42 and took 78 ms, and its calibration error, computed by this site from AA’s bins, is 0.095 against 0.117 for 1.13. On the Jev Decision Index (multimodalart’s community board on Hugging Face), Jev 1.14 has a Full score of 60.24 in edition 0.4.1, 41st of 229 rows, and Fastino’s GLiDE 1.2 ranks first at 71.52, so the two boards disagree on which model leads. Jev benchmarks covers both.
How to call Jev
One POST to https://api.typesafe.ai/v1/systemone with an Authorization: Bearer header. Both SDKs read the key from TYPESAFE_API_KEY when you construct the default client.
The quickstart’s curl example, unchanged:
curl -X POST https://api.typesafe.ai/v1/systemone \
  -H "Authorization: Bearer $TYPESAFE_API_KEY" \
  -H "Content-Type: application/json" \
  -d @- <<'EOF'
  {
    "state": "Hi, I've been trying to connect my Stripe account for 3 days and the integration keeps failing. I'm losing sales. Please help ASAP.",
    "model": "jev-latest",
    "questions": {
      "urgency": {
        "type": "noul",
        "instructions": "Does this message express urgency?"
      }
    }
  }
EOF
The Python SDK, typesafe-sdk, installs with uv add typesafe-sdk or pip install typesafe-sdk and needs Python 3.10 or newer.
from typesafe_sdk import Choice, TypeSafeClient

with TypeSafeClient() as client:
    response = client.system_one(
        state={"document": "I was charged twice. Please fix this ASAP."},
        questions={
            "category": Choice(
                instructions="What is this ticket about?",
                criteria={"billing": None, "technical": None, "other": None},
            ),
        },
    )

print(response.choices["category"].choice)
Check that last line against the SDK you installed. TypeSafe’s quickstart page reads answers back as response.answers["department"].choice while the Python SDK’s own page uses response.choices["category"].choice. Both are TypeSafe’s text, and the two disagree.
Python is on 0.7.0, released 18 September 2026. That release swapped serialisation from msgspec to pydantic, which the release notes flag as a breaking change, and gave system_one() a response_model argument that takes a Pydantic model.
The JavaScript SDK, @typesafe-ai/sdk, installs with npm install @typesafe-ai/sdk and needs Node.js 20 or newer. It was still on 0.6.0 on 20 September 2026, with no 0.7.0 release published.
import { choice, TypeSafeClient } from "@typesafe-ai/sdk";

const client = new TypeSafeClient();
const response = await client.systemOne({
  state: { document: "I was charged twice. Please fix this ASAP." },
  questions: {
    category: choice("What is this ticket about?", {
      billing: null,
      technical: null,
      other: null,
    }),
  },
});

console.log(response.answers.category.choice);
The API reference documents four error codes. A bad key returns 401 Unauthorized, and a validation failure returns 422 Unprocessable Entity with the offending field named in the body. Cross either rate limit and you get 429 Too Many Requests. A 529 Overloaded means TypeSafe itself is saturated, and the docs say to “retry after a short delay.” Both SDKs “retry with backoff by default and honor the retry-after header,” which leaves the retry loop to you only when you call the endpoint directly.
Jev on OpenRouter
OpenRouter has listed Jev since 18 September 2026 as typesafe/jev-1.13, plus ~typesafe/jev-latest, an alias that OpenRouter says always redirects to the latest model in the Jev family. TypeSafe is the only provider. The price matches TypeSafe’s: $0.042 per million input tokens, with free output. Both ids list a 64,000-token context as of 9 October 2026.
It is not a chat model there. OpenRouter serves it through its Decisions API, POST https://openrouter.ai/api/alpha/decisions, and warns that chat completions SDKs will not work with it. The request takes the same state and questions as TypeSafe’s API, and an OpenRouter key replaces the TypeSafe key. OpenRouter’s own SDK calls it through openrouter.alpha.decisions.create(). The alpha path means OpenRouter still treats the endpoint as unfinished. The OpenRouter integration page has more.
Languages and data handling
English first. The docs say “English is the primary training language and where accuracy is currently best. Other languages, including CJK scripts, are handled but not equally well.” They add that you should test on your own content before putting a non-English workload through the model. Input is text by default, as a string, a JSON object, or an array of text values. Since 14 October 2026, PNG and JPEG images are accepted on 1.13 and 1.14 behind an opt-in header that TypeSafe says is not ready for production.
On data, TypeSafe states that “Jev is not trained on customer requests or responses” and that the model is “not fine-tuned or LoRA-adapted with customer data,” because “the same weights serve every account.” Zero data retention is offered to enterprise customers under a data processing agreement. None of that has been independently audited.
Access today: open sign-up, console and API key
There is no waitlist. TypeSafe removed it on 20 September 2026, five days after launch, posting on X that “Jev is now available to everyone. No waitlist.” Sign in at console.typesafe.ai with Google or an email code, create a key, and call the API. Getting access and making your first call covers the steps.
The weights are not released, so there is no self-hosted option and no local build.
What it is not for
Anything that ends in prose. Drafting, summarising and code generation sit outside what the model was trained to do, and TypeSafe says so plainly.
Arithmetic, counting and date comparison belong in your code rather than in a question. So does anything that needs two facts chained together, because indirection is one of the nine documented weak spots.
Unscreened user input is the other thing you handle yourself. The model reads the state as data and has no defence against instructions hidden in it, so a separate screen sits in front. The vendor speed and cost claims are unpacked in Jev speed and pricing, and what is known about the internals is in Jev architecture.
Specifications
| System One Score | 86.6 from 3 of 3 boardsArtificial Analysis Decision Index 87.6, Jev Decision Index 84.2, JevBench 88. How the score works |
| Question types | ChoiceScoreNoul |
| Max Choice options | 255 |
| Score levels | Up to 10 |
| Questions per call | Not documented |
| Total context | 64,000 tokens |
| State budget | 32,000 tokens |
| Rate limit | 100,000 tokens/sec and 40 requests/sec as of 2026-09-30, adjusting dynamically |
| Endpoint | POST https://api.typesafe.ai/v1/systemone |
| Licence | Not published as of 23 Oct 2026 |
| SDKs | Python: typesafe-sdkTypeScript: @typesafe-ai/sdk |
64k tokens across the whole request. The state plus the longest single question must fit in 32k of that. OpenRouter lists typesafe/jev-1.13 with a 64,000-token context and a 57,600-token maximum completion, checked on 2026-10-09, which matches the whole-request limit. It listed 32,000 earlier. A Score needs at least 2 levels. The maximum number of questions in one call is not documented. On rate limits the docs warn that the published numbers can change without notice while TypeSafe serves launch demand, and that higher limits come with custom and enterprise plans. Since 14 October 2026 a TypeSafe-Danger-Zone-Long-Context: true header raises both limits to 262k tokens on 1.13 and 1.14 at the same per-token price; it is an opt-in danger zone feature, and the docs say it is slower and less accurate.
Versions
- jev-1.14.0, 14 Oct 2026, Released as a preview under the jev-preview alias, with what TypeSafe calls small improvements to everything and the largest gain expected in multilingual support. Same price and context limits as 1.13. TypeSafe's release post says jev-latest will point to it in one week, around 21 October 2026; on 15 October the docs still pointed jev-latest at jev-1.13.0. It is the only version that answers the new box question type, which returns one bounding box in an image. Box rides on the opt-in danger zone features TypeSafe released alongside it and says are still too jagged for production: image input (TypeSafe-Danger-Zone-Images header), long context up to 262k tokens (TypeSafe-Danger-Zone-Long-Context header) and opt-in data sharing. TypeSafe promises 30 days' notice before jev-1.14.0 is deprecated. TypeSafe had published no jaggedness page for 1.14 on 15 October 2026. Release notes
- jev-1.13.0, 15 Sep 2026, The stable release and the version jev-latest still resolved to on 15 October 2026, while jev-preview now points at jev-1.14.0. It accepts the opt-in image and long-context headers but not the box question type. TypeSafe promises 60 days' notice before it is formally deprecated, with a formal deprecation policy still to come. OpenRouter lists it as typesafe/jev-1.13, snapshot typesafe/jev-1.13-20260917, plus the alias ~typesafe/jev-latest, which OpenRouter says always redirects to the latest model in the Jev family. TypeSafe ships a per-version jaggedness page listing what this version does badly. Release notes
Use cases
What people use Jev for, one page per pattern.
Support inbox triage with System One models
Send a support ticket to Jev once with every question attached. Category comes back as a selected label, severity and frustration as numbers on scales you wrote, refund intent as a probability. Your code reads those values and decides what happens to the ticket.
Intent and model routing with System One models
One Jev call reads an incoming request and returns its intent as a label plus a difficulty rating on a scale you wrote. Your router reads both numbers and picks the handler: deterministic code, a cheap model, an expensive one, or a human queue.
Confidence-gated actions with System One models
Jev returns a confidence value from 0 to 1 alongside every Choice and Score answer. Your code treats it as a separate axis: act automatically when it's high, confirm or flag when it's middling, hand the decision to a person when it's low. Riskier actions get higher bars.
Typed tool dispatch with System One models
Ask Jev one Choice question over your tool names and one per closed-set argument, so every value that comes back is a value the function already accepts. Nouls decide whether an optional argument was mentioned at all. Your code assembles the call and runs it.
RAG passage filtering with System One models
Retrieval returns whatever looks similar, including noise and hostile text. Put a Jev call between retrieval and generation: four yes/no questions per passage return probabilities, and your code decides which passages become evidence, which get flagged as conflicts, and which never reach the prompt.
Semantic reranking with System One models
Keyword or vector search narrows thousands of documents to a shortlist but rarely puts the right one first. Ask Jev one yes/no question about each query and candidate pair, take the probability it returns as the score, and sort the shortlist by it, highest first.
Citation verification with System One models
An answer with citations is only as good as the citations. Match each quote against the source in code to catch fabrications, then ask Jev one Choice question about how the surrounding section relates to the claim. Confidence decides which verdicts a human reviews.
Entity alignment with System One models
Two catalogues describe overlapping sets of the same products, and a rough first pass hands you candidate pairs. One Jev Score question with a level per outcome decides each pair, and yes/no questions about individual fields tell a curator where the two sources disagree.
LLM guardrails with System One models
Put one Jev request in front of an LLM and one behind it. Yes/no questions return the probability that each hazard holds, a Score rates how much harm complying would do, and your thresholds turn those numbers into pass, review, block, or a crisis path.
Semantic code linting with System One models
A semantic lint is a rule you can state in a sentence but cannot express in a regular linter. Jev turns each rule into a yes/no question over one diff hunk and returns a probability, so CI can comment on the likely violations and stay quiet about everything else.
Compliance verification with System One models
A compliance review is a fixed checklist run against a changing document. Jev answers the whole checklist in one request, returning a probability, a label or a rated level per item, so code can clear the clear-cut findings and send the borderline ones to a person.
Self-consistency checks with System One models
Run a rubric over the same document several times and compare the answers. The spread tells you which items sit safely away from a threshold and which ones wobble across it. TypeSafe documents that Jev does not guarantee structural identities between related questions, so code has to enforce those.
Structured extraction with System One models
There are two routes. Clairic, Cloudflare's extraction model, takes named fields and returns typed values, each with the probability that it is missing. Jev cannot write values, so code finds candidate spans, a choice question picks one, and code copies it unchanged.
Composite scoring with System One models
Asking for one overall rating hides the reasoning inside a single number. Score each dimension as its own question instead, normalise each answer to a 0 to 1 range, and combine them with weights your code owns, so a ranking can be explained and retuned without new model calls.
Feature extraction for machine learning with System One models
A tabular model needs numbers, and a written note is not one. Ask Jev a set of questions about each row, keep the probability distribution rather than the winning answer, and you get numeric columns that a gradient-boosting model can train on alongside your existing features.
Hierarchical classification with System One models
A taxonomy with thousands of leaves will not fit in one question. Ask one choice question per node instead, walking down the tree, and use the probability on each edge to decide whether to follow the single best path or keep several candidates alive.
Real-time control with System One models
A model inside a control loop has to answer before the next frame. Jev returns a typed decision rather than text, and TypeSafe reports end to end latency of 70ms to 500ms, which puts a semantic judgment inside the budget of a game tick or an interface response.
Agent routing and skill selection with System One models
An agent choosing from a long skill roster reads one truncated line per entry and often loads the wrong thing. Jev ranks every entry in one request and separately answers whether any skill applies at all, so the agent gets a short hint instead of a guess.
Examples built with Jev
The most-starred and most-viewed entries in the directory. All 638 Jev examples.
Jev Ultrafast (Browser Use)
Browser Use's fast browser agent where Jev picks the operation and the DOM element in a single request; a small LLM is only invoked to write text when typing is required. Demoed on a Google Flights search.

19k starsFlight search 7.1 s
openjev
Attempt to run a Jev-style System One decision model locally on a single RTX 3090. Companion site at openjev.com. The repository was renamed to TheoLeeCJ/SemIf on GitHub, and the old openjev URL now redirects to it.
 TheoLeeCJOpenopenjev on github.com
4.1k starsJSON vs direct 5.21x slowerPeak throughput 20.03 dec/s
jev-trader
Makes one AI trade decision every Monad block on the Kuru MON-USDC market using Jev. The public deployment runs in dry-run mode with a mock model.
 jarrodwattsOpenjev-trader on github.com
2.2k starsLoop, mock model p50 100 msDecision window ~300 ms/block
typesafe-ai/skills (official TypeSafe agent skill)
Official agent skill for Claude Code, Codex and other agent environments; installs via claude plugin marketplace add typesafe-ai/skills or npx skills add typesafe-ai/skills. MIT licensed.

jevlike
Open reimplementation that trains a small model to choose among a changing list of text options, emitting one probability per option in a single forward pass. Ships Doom, chess and Wikispeedia demos.

Anil-matcha/awesome-jev-by-typesafe
Independent community collection of use cases, patterns, prompts and starter code for Jev, explicitly not official. It also links sibling collections by the same author and two related projects that report their own cost figures.

jkudish/jev-mcp
MCP server that gives Claude Code, Codex, Amp, OpenCode and other agents ten Jev judgment tools, each returning typed probabilities they can branch on. The author calls it early software.

320 starsPer call 150-500 ms
JEV Breakdown: The First AI Model Built For Code
Walks through the Choice, Score and Noul primitives live in the TypeSafe playground, with speed and cost numbers and their caveats.
Jev Explained: Demos and Use Cases
CJ from Syntax explains what Jev is, how it works, and walks through several use cases and demos. 17 minutes.
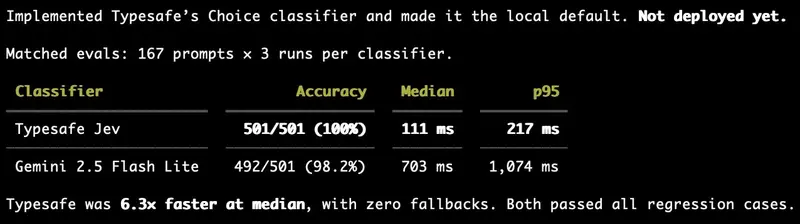
Ran Jev against an existing classifier eval that previously used Gemini 2.5 Flash Lite
Vercel CTO reports Jev saturated an existing classifier eval that had used Gemini 2.5 Flash Lite and ran about 6x faster. Original post; TypeSafe's quote-tweet is a separate item.
 Malte Ubl (@cramforce)OpenRan Jev against an existing classifier eval that previously used Gemini 2.5 Flash Lite on x.com
220k viewsSpeed vs Gemini 6x faster
Introducing Clef: our open-source decision models, and new RL fine-tuning platform
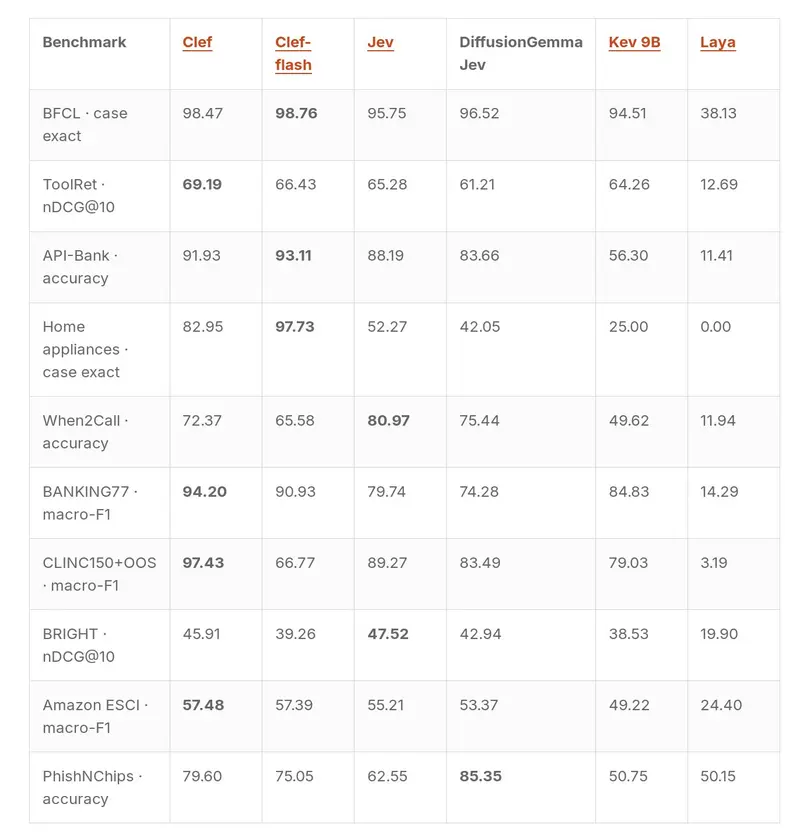
Cloudflare's launch post for Clef and Clef-flash, two decision models on Workers AI that accept the Jev request format and open weights under Apache 2.0. It covers the architecture, Cloudflare's own benchmark tables against Jev, Kev and Laya, and a new reinforcement learning service.
 Michelle Chen (@michellechen)140k viewsOpenIntroducing Clef: our open-source decision models, and new RL fine-tuning platform on blog.cloudflare.com
Decision Model Leaderboard
Cloudflare's live leaderboard for decision models on the Jev Decision Index suite, with Clef, Clef-flash, Jev, Kev-9B and Laya plotted by score and latency. Cloudflare built and ran it, so treat the ranking as vendor-run.
 Cloudflare (@ritakozlov)41k viewsOpenDecision Model Leaderboard on clef-evals.workers-ai-mle.workers.dev
Benchmarks
Published scores, each linked to its source. A row marked vendor-run was measured by the vendor itself, so read it as one side's result. The compare hub sets these beside the other models.
| Benchmark | Metric | Score | Run by | Date |
|---|---|---|---|---|
| Jev Decision Index 0.4.1 | Full score | 60.24 score | Independent | 22 Oct 2026 |
| Jev Decision Index 0.4.1 | Public score | 60.7 score | Independent | 22 Oct 2026 |
| Jev Decision Index 0.4.1 | Expected calibration error | 0.0799 ECE | Independent | 22 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Index score | 57.1 score | Independent | 16 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Expected calibration error | 0.0952 ECE | Independent | 16 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Cost per 1M tasks | 42 USD | Independent | 16 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Time per task | 78 ms | Independent | 16 Oct 2026 |
| JevBench 1.7.47 | Capability Score | 75 score | Independent | 16 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Index score | 57.5 score | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Expected calibration error | 0.1174 ECE | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Cost per 1M tasks | 42 USD | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Time per task | 127 ms | Independent | 13 Oct 2026 |
| JevBench 1.7.46 | Capability Score | 77.1 score | Independent | 12 Oct 2026 |
| Jev Decision Index 0.3.1 | Full score | 60.11 score | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Public score | 57.96 score | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Expected calibration error | 0.074 ECE | Independent | 10 Oct 2026 |
| Microsoft 36-benchmark comparison | Average accuracy | 82.3 % | vendor-run | 9 Oct 2026 |
| Microsoft 36-benchmark comparison | Calibration score | 93.7 score | vendor-run | 9 Oct 2026 |
- Jev Decision Index, Full score: Row: Jev 1.14, 41st of 229 rows by this score. Counts 60% private same-skill tests and 40% private new-domain tests; public benchmarks no longer count. 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: Jev 1.14.
- Jev Decision Index, Expected calibration error: Row: Jev 1.14. Lower is better.
- Artificial Analysis Decision Index, Index score: Row: Jev 1.14. Sub-scores: Omniscience accuracy 33.8, non-hallucination 37.2, HLE-MultiChoice 18.9, When2Call 80.8, WildGuardTest F1 93.1. Fifth of the 17 decision models AA lists as of 2026-10-23, behind d1-ultra, SubQ Snap 1.1, Elephant 9B and Jev 1.13. AA does not date its rows; this is the date it was first checked.
- Artificial Analysis Decision Index, Expected calibration error: Row: Jev 1.14. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Jev 1.14. AA's measured cost at list prices on its four evals.
- Artificial Analysis Decision Index, Time per task: Row: Jev 1.14. Median time per task.
- JevBench, Capability Score: Row: Jev 1.14.0, measured 2026-10-16. Intelligence 59.9, Calibration 90.1. Ranked on the hosted API board; on the open board it is a reference row, not ranked. Jev 1.13.0 keeps its own row at 77.1.
- Artificial Analysis Decision Index, Index score: Row: Jev 1.13. Sub-scores: Omniscience accuracy 34.6, non-hallucination 35.2, HLE-MultiChoice 20.9, When2Call 80.7, WildGuardTest F1 93.6.
- Artificial Analysis Decision Index, Expected calibration error: Row: Jev 1.13. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Jev 1.13. AA's measured cost at list prices on its four evals.
- Artificial Analysis Decision Index, Time per task: Row: Jev 1.13. Median time per task.
- JevBench, Capability Score: Row: Jev 1.13.0. Intelligence 63.6, Calibration 90.6. Reference row, not ranked. The board re-measures rows, so this can differ from earlier editions.
- Jev Decision Index, Full score: Row: Jev. Counts 20% public benchmarks and 80% private tests; 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: Jev.
- Jev Decision Index, Expected calibration error: Row: Jev. Lower is better.
- Microsoft 36-benchmark comparison, Average accuracy: Run by Microsoft on an undisclosed suite of 36 public and private benchmarks, 147,137 questions; added to the post after launch. Jev was first of seven on calibration and second of eight on accuracy.
- Microsoft 36-benchmark comparison, Calibration score: Run by Microsoft on an undisclosed suite of 36 public and private benchmarks, 147,137 questions; added to the post after launch. Jev was first of seven on calibration and second of eight on accuracy.
Comparisons
Head-to-head pages that put Jev against other models. Every model sits in one table on the compare hub. Looking for a different model? Read the Jev alternatives guide.
Jev vs BERT: which is better for text classification?
BERT is a classifier you train and own; Jev takes labels in each request. BERT wins on stable, high-volume label sets, Jev when categories change. Cost and speed.
Updated
Jev vs Clairic: a decision model and an extraction model
Jev picks from options you list. Clairic, from Cloudflare, returns values pulled from the input. How they differ on API, price and access, and how to use them together.
Updated
Jev vs Claude: when a decision model beats an LLM
Jev decides and Claude writes. Prices, context windows, what confidence means in each, and what the public head-to-head benchmarks actually measured.
Updated
Jev vs Clef: TypeSafe's decision model against Cloudflare's
Clef and Clef-flash are Cloudflare's decision models, hosted on Workers AI with open weights. How they compare with Jev on price, speed and Cloudflare's own benchmarks.
Updated
Jev vs GLiNER: typed decisions against span extraction
Classic GLiNER extracts entity spans. Fastino's GLiNER2.5-Decide, released 2026-09-24, answers typed decisions instead. Both differ from Jev in weights and benchmarks.
Updated
Jev vs GPT: OpenAI against a decision model
OpenAI's GPT models generate text. Jev returns a typed decision with a probability. Live prices, the public benchmarks, and why Jev is no ChatGPT alternative.
Updated
Jev vs Laya: hosted decision model or open weights?
Jev is TypeSafe's hosted decision model at $0.042 per million input tokens. Laya is open weights you run yourself. Price, context, latency and Jev Decision Index scores.
Updated
Jev vs Microsoft-Decision-1: same price, different evidence
Microsoft-Decision-1 costs the same as Jev per input token. How the two compare on context, API access, latency claims and independent results.
Updated
Jev vs OpenAI Decisions API: price, API and what's known
OpenAI's Decisions API is in public beta on GPT-6 Luna at $0.10 per million input tokens. How it compares with Jev on price, request format, images, context and evidence.
Updated
Jev vs pplx-decider: TypeSafe's decision model against Perplexity's
pplx-decider is Perplexity's decision model with open weights and image input. How it compares with Jev on price, limits, API format and published results.
Updated
Guides
What is Jev AI? TypeSafe's decision model explained
Jev is TypeSafe AI's decision model. It answers typed questions about text with calibrated probabilities, and it is not an LLM, because it writes nothing.
Updated
Jev 1.14: what changed, when jev-latest moves, and the danger zone
Jev 1.14 shipped on 14 October 2026 as jev-preview. What changed, when jev-latest switches, the opt-in image, box and long-context features, and deprecation.
Updated
Jev speed and pricing
Jev costs $0.042 per million input tokens with free output. TypeSafe claims 70ms to 500ms and 40x to 200x. What those numbers cover.
Updated
How to get Jev API access
How to get Jev API access: open sign-up at the TypeSafe console, the key page, the TYPESAFE_API_KEY env var, SDK installs, and a first working call.
Updated
Jev architecture: parameters, encoder or decoder, and no paper yet
TypeSafe has not published Jev's parameter count, base architecture or weights. Here is the public record and what the community has guessed from it.
Updated
Jev benchmarks: every public evaluation in one place
Every public Jev benchmark we could verify: TypeSafe's own evals, independent tests against Opus, Haiku, GPT and Laya, and what they do and don't show.
Updated
Jev alternatives: hosted, open-source and local options compared
The realistic Jev alternatives in October 2026: other hosted APIs, open models you host, community clones and plain classifiers, with the benchmarks behind each.
Updated