What Microsoft-Decision-1 is
Microsoft-Decision-1 is Microsoft’s decision model, and a System One model. Achint Srivastava, a VP of Software Engineering in Microsoft’s Office of the CTO, announced it on 9 October 2026. The Foundry model card gives 8 October as the release date. Microsoft post-trained Alibaba’s open-weight Qwen3.5-9B to score decisions in a single pass. It says it will later rebase the model on other models, including MAI and OpenAI’s. The weights are not distributed. It runs only as a hosted API in Microsoft Foundry.
What it returns
You send a context or state, a question and a fixed set of answer options. It returns a calibrated probability for each option and writes no text, not even an explanation. Microsoft lists yes/no, multiple-choice and rating questions, which match Noul, Choice and Score. It also grades AI responses and agent actions against a rubric. Input is text only, up to 32,768 tokens.
Microsoft published the request format on 9 October 2026, and it is Jev’s. You POST to <your-foundry-resource-endpoint>/providers/microsoft/v1/systemone with a model (your deployment name), a state as text or JSON, and questions keyed by name. Each question has a type, instructions and criteria. A noul question takes optional true and false descriptions. A choice question takes each option with its description. A score question takes an ordered list of level labels, and the returned score is the probability-weighted average of the level indexes, so four levels give a value from 0 to 3. The docs call the pattern “similar to a system-one API”. The response has an answers object keyed by question name, with the choice and a probability per option. Microsoft has not published rate limits, option limits or question limits as of 12 October 2026. Through OpenRouter, it takes OpenRouter’s Decisions API request, the same one OpenRouter serves Jev on.
What it is good at
Microsoft aims it at routing, classification, prioritization, verification and workflow control. That covers intent and model routing, confidence-gated actions, LLM guardrails and agent routing and skill selection. Input costs $0.042 per million tokens, the same as Jev, and output is free.
The launch post’s accuracy and calibration figures are vendor-run: Microsoft ran the tests. Across 36 public and private benchmarks and 147,137 questions, it averages 83.5% accuracy, against 82.3% for Jev 1.13.0, 81.9% for Quyet-1.0-Large, 79.4% for GPT-6 Luna Decisions and 77.2% for H2O-Lightning-4B. Its calibration score is 92.2 out of 100, third of seven behind Jev’s 93.7 and Quyet’s 93.1. Microsoft added the Jev accuracy and calibration figures to the post after launch. It does not name the 36 benchmarks and says they were kept blind from training, so nobody can reproduce the figures.
Microsoft measured a median of 85 ms per request through Foundry. It compares that with JevBench medians from a different harness, such as 240 ms for Jev 1.13.0. On requests altered in eight ways, it changes its answer 1.3% of the time on average, and never when options are paraphrased, reversed or shuffled. Xbox Research sorted more than 10,000 pieces of feedback and reviews with it and found it competitive with GPT-6 Sol at over 14 times the speed.
It has been on Benchmark Heaven’s JevBench hosted API board since 10 October 2026 (v1.7.31), which measured it natively through Azure Foundry on 1,200 sealed and 300 public observations. JevBench gives it a Capability Score of 70.78 and a Calibration of 84.40, and a native median latency of 459 ms against Microsoft’s own 85 ms. Its 21 context-limit failures stay in the scored denominator. JevBench’s independent Capability Score for Jev 1.13.0 is 77.1 on the current board, above Microsoft-Decision-1’s 70.78. That is the opposite order from Microsoft’s own chart, which puts Microsoft-Decision-1 ahead on accuracy. The Jev Decision Index, multimodalart’s community board on Hugging Face, has no row for it as of 12 October 2026.
The Artificial Analysis Decision Index v1.0, published on 13 October 2026, is the second independent board to score it. AA ran it through OpenRouter and ranked it third of the 11 decision models it listed at launch, at 53.8, behind Jev at 57.5 and GLiDE at 53.9. On version 2.1, checked on 12 November 2026, it scores 62.1, 11th of 19 decision models, against 66.2 for Jev 1.14. Its non-hallucination rate on AA’s private knowledge questions, a measure that rewards answering “I don’t know” over a wrong answer, is 21.7, 12th of the 19. Its accuracy there is 31.0%. It cost $143 per million tasks and took 274 ms per task. Its calibration error, which this site computed from AA’s published bins, is 0.124, third worst of the 19. Like JevBench, AA puts Jev ahead of it.
What it is not for
The model card rules out text generation, open-ended questions, conversation, translation and summarization, and any task without a closed question and fixed options. It reads no images, audio or video. Microsoft says it is tuned for English and may do worse in other languages and in medical, legal and financial work. It should not be the only basis for decisions about people, such as credit, hiring or housing. You cannot self-host it.
Access
It is generally available in Microsoft Foundry as a Direct from Azure model. Deploy it as DataZoneStandard in selected regions or as GlobalStandard, and authenticate with an Entra ID bearer token or an api-key header. OpenRouter also lists it as microsoft/microsoft-decision-1, served by Azure at the same price with a 32,768-token context, since 9 October 2026. Microsoft names no SDK for it, and its quickstart is Python with urllib. The docs list a 400 for an invalid question type or shape, a 422 for an unsupported deployment name or question definition, and a 429 when the deployment rate limit is exceeded.
For side-by-side detail, see Jev vs Microsoft-Decision-1, Microsoft-Decision-1 vs Clef, Microsoft-Decision-1 vs pplx-decider and Microsoft-Decision-1 vs the OpenAI Decisions API.
Specifications
| System One Score | 84.3 from 2 of 3 boardsArtificial Analysis Decision Index 85.5, JevBench 83.1. How the score works |
| Question types | ChoiceScoreNoul |
| Max Choice options | Not documented |
| Score levels | Not documented |
| Questions per call | Not documented |
| Total context | 32,768 tokens |
| State budget | Not documented |
| Rate limit | Not published as of 12 October 2026. |
| Endpoint | POST <foundry-resource-endpoint>/providers/microsoft/v1/systemone |
| Licence | Not published as of 12 Nov 2026 |
| SDKs |
The Foundry model card gives up to 32,768 input tokens, text only. A request holds a context or state, a question and a fixed set of answer options. The Learn deployment page publishes the request format, which matches Jev's: a `model`, a `state` and named `questions` of type noul, choice or score. Microsoft has not published rate limits, option limits, question limits or a maximum number of score levels, as of 12 October 2026.
Versions
- Microsoft-Decision-1, 8 Oct 2026, Version 1 in the Foundry catalog. The model card gives 8 October 2026 as the release date and September to October 2026 as the training time. It is a dense decoder-only model built on Qwen3.5-9B, in the 5B to 15B parameter range. Microsoft says it will rebase the model on other models, including MAI and OpenAI's. Release notes
Use cases
What people use Microsoft-Decision-1 for, one page per pattern.
Intent and model routing with System One models
One Jev call reads an incoming request and returns its intent as a label plus a difficulty rating on a scale you wrote. Your router reads both numbers and picks the handler: deterministic code, a cheap model, an expensive one, or a human queue.
Confidence-gated actions with System One models
Jev returns a confidence value from 0 to 1 alongside every Choice and Score answer. Your code treats it as a separate axis: act automatically when it's high, confirm or flag when it's middling, hand the decision to a person when it's low. Riskier actions get higher bars.
LLM guardrails with System One models
Put one Jev request in front of an LLM and one behind it. Yes/no questions return the probability that each hazard holds, a Score rates how much harm complying would do, and your thresholds turn those numbers into pass, review, block, or a crisis path.
Agent routing and skill selection with System One models
An agent choosing from a long skill roster reads one truncated line per entry and often loads the wrong thing. Jev ranks every entry in one request and separately answers whether any skill applies at all, so the agent gets a short hint instead of a guess.
Examples built with Microsoft-Decision-1
The most-starred and most-viewed entries in the directory. All Microsoft-Decision-1 examples.
Microsoft-Decision-1: Our model for fast decision-making
Microsoft's launch post for Microsoft-Decision-1, a Qwen3.5-9B decision model on Foundry at $0.042 per million input tokens. Its vendor-run charts, run on an undisclosed 36-benchmark suite, now include Jev: 82.3% accuracy and 93.7 calibration against 83.5% and 92.2 for Microsoft-Decision-1.
 Satya Nadella (@satyanadella)454k viewsOpenMicrosoft-Decision-1: Our model for fast decision-making on commandline.microsoft.com
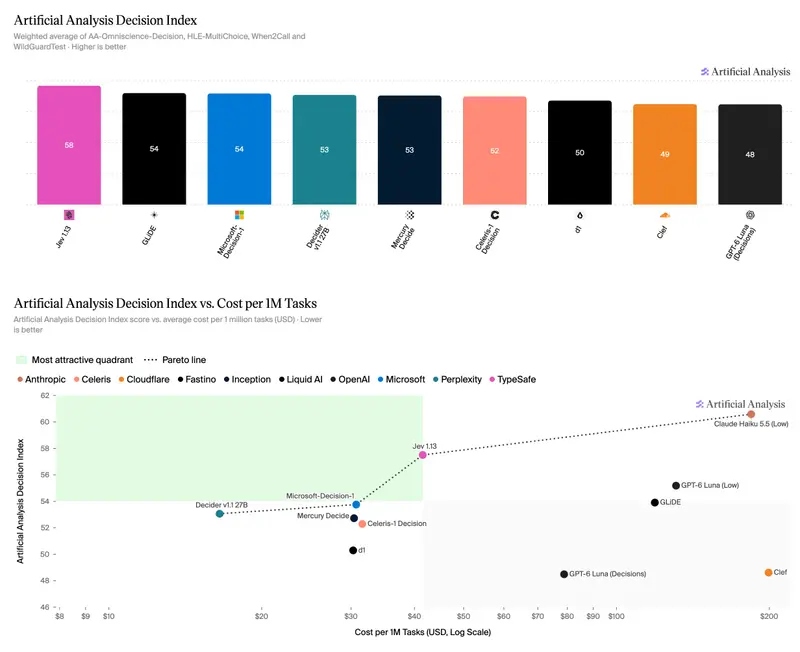
Artificial Analysis Decision Index: 11 hosted decision models against language models
Artificial Analysis scores 11 hosted decision models on knowledge, reasoning, tool-calling and safety tests, with cost and time per task, and runs language models on the same tests. Jev 1.13 led the decision models at launch at 58, and on version 2.1, checked 12 November, Nace.AI's Drex Max v1.1 leads at 72.6; at launch Claude Haiku 5.5 (Low) scores 61 but takes 1.4 seconds per task against 0.13.
 Artificial Analysis (@ArtificialAnlys)45k viewsOpenArtificial Analysis Decision Index: 11 hosted decision models against language models on artificialanalysis.ai
Benchmarks
Published scores, each linked to its source. A row marked vendor-run was measured by the vendor itself, so read it as one side's result. The compare hub sets these beside the other models.
| Benchmark | Metric | Score | Run by | Date |
|---|---|---|---|---|
| Artificial Analysis Decision Index 2.1 | Index score | 62.1 score | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Expected calibration error | 0.1243 ECE | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Cost per 1M tasks | 143 USD | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Time per task | 274 ms | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 1.0 | Index score | 53.8 score | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Expected calibration error | 0.158 ECE | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Cost per 1M tasks | 31 USD | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Time per task | 207 ms | Independent | 13 Oct 2026 |
| JevBench 1.7.31 | Capability Score | 70.78 score | Independent | 10 Oct 2026 |
| JevBench 1.7.31 | Calibration | 84.4 score | Independent | 10 Oct 2026 |
| Microsoft 36-benchmark comparison | Average accuracy | 83.5 % | vendor-run | 9 Oct 2026 |
| Microsoft 36-benchmark comparison | Calibration score | 92.2 score | vendor-run | 9 Oct 2026 |
- Artificial Analysis Decision Index, Index score: Row: Microsoft-Decision-1, host OpenRouter. Raw value 62.072. 11th of 19 decision models on version 2.1. AA ran it through OpenRouter. Sub-scores: When2Call accuracy 86.4, Omniscience accuracy 31.0, HLE-MultiChoice accuracy 8.6. Version 2.1 figures do not compare with version 1.0 figures.
- Artificial Analysis Decision Index, Expected calibration error: Row: Microsoft-Decision-1. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Microsoft-Decision-1. AA's measured cost per million tasks on its version 2.1 evals.
- Artificial Analysis Decision Index, Time per task: Row: Microsoft-Decision-1. Time per task.
- Artificial Analysis Decision Index, Index score: Row: Microsoft-Decision-1. Sub-scores: Omniscience accuracy 28.2, non-hallucination 39.8, HLE-MultiChoice 10.9, When2Call 81.9, WildGuardTest F1 88.2. AA ran it through OpenRouter.
- Artificial Analysis Decision Index, Expected calibration error: Row: Microsoft-Decision-1. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Microsoft-Decision-1. AA's measured cost at list prices on its four evals.
- Artificial Analysis Decision Index, Time per task: Row: Microsoft-Decision-1. Median time per task. AA ran it through OpenRouter.
- JevBench, Capability Score: Hosted API board, added in v1.7.31. Measurement: native Azure Foundry run on 1,200 sealed plus 300 public observations; its 21 context-limit failures stay in the scored denominator. JevBench's native median latency is 459 ms on a 124-request speed subset, against Microsoft's own 85 ms.
- JevBench, Calibration: Hosted API board, added in v1.7.31. Measurement: native Azure Foundry run on 1,200 sealed plus 300 public observations; its 21 context-limit failures stay in the scored denominator. JevBench's native median latency is 459 ms on a 124-request speed subset, against Microsoft's own 85 ms.
- Microsoft 36-benchmark comparison, Average accuracy: Run by Microsoft on an undisclosed suite of 36 public and private benchmarks, 147,137 questions, which it says were kept blind from training. Jev 1.13.0 scored 82.3% and Quyet-1.0-Large 81.9%. The benchmark names are not given, so the figures cannot be reproduced.
- Microsoft 36-benchmark comparison, Calibration score: Run by Microsoft; 100 is perfect. Third of seven: Jev 1.13.0 scored 93.7 and Quyet-1.0-Large 93.1. Added to the post after launch.
Comparisons
Head-to-head pages that put Microsoft-Decision-1 against other models. Every model sits in one table on the compare hub.
Jev vs Microsoft-Decision-1: same price, different evidence
Microsoft-Decision-1 costs the same as Jev per input token. How the two compare on context, API access, latency claims and independent results.
Updated
Microsoft-Decision-1 vs Clef: Microsoft's decision model against Cloudflare's
Microsoft-Decision-1 and Clef-flash are both built on Qwen3.5-9B. How Microsoft's closed model and Cloudflare's open one differ on price, input and outside results.
Updated
Microsoft-Decision-1 vs OpenAI Decisions API: two hosted decision models
Microsoft-Decision-1 and OpenAI's Decisions API (GPT-6 Luna) side by side: price, input, context, request format and Microsoft's own benchmark claims.
Updated
Microsoft-Decision-1 vs pplx-decider: Microsoft's decision model against Perplexity's
Microsoft-Decision-1 is closed and text only. pplx-decider is cheaper, reads images and has open weights. How the two compare on price, limits and published results.
Updated