Specifications side by side
Read from each model's page, so a change there updates this table. A blank field is dated to the day that model's page was last checked.
| Specification | Jev | GLiNER2.5-Decide |
|---|---|---|
| Vendor | TypeSafe AI | Fastino Labs |
| Status | Generally available | Generally available |
| Access | Hosted API | Open weights, self-hosted |
| Question types | Choice, Score, Noul | Choice, Score, Noul |
| Input price | $0.042 per 1M tokens | No hosted API |
| Output price | Free | No hosted API |
| Total context | 64,000 tokens | Not published as of 23 Oct 2026 |
| State budget | 32,000 tokens | Not published as of 23 Oct 2026 |
| Latency | 70 to 500 ms1 | 38 to 167 ms2 |
| Max Choice options | 255 | Not published as of 23 Oct 2026 |
| Score levels | Up to 10 | Not published as of 23 Oct 2026 |
| Rate limit | 100,000 tokens/sec and 40 requests/sec as of 2026-09-30, adjusting dynamically | None for self-hosted use. Fastino's hosted inference and fine-tuning API at http://agent.fastino.ai did not have published rate limits in the sources checked. |
| SDKs | Python, TypeScript | Python |
| Licence | Not published as of 23 Oct 2026 | Apache-2.0 |
| Jev Decision Index, Full score | 60.24 scorev0.4.1, 22 Oct 2026 | 10.14 scorev0.4.1, 22 Oct 2026 |
| Jev Decision Index, Public score | 60.7 scorev0.4.1, 22 Oct 2026 | 11.48 scorev0.4.1, 22 Oct 2026 |
| Jev Decision Index, Expected calibration error | 0.0799 ECEv0.4.1, 22 Oct 2026 | 0.0884 ECEv0.4.1, 22 Oct 2026 |
| JevBench, Capability Score | 75 scorev1.7.47, 16 Oct 2026 | 34.6 scorev1.7.47, 5 Oct 2026 |
| Microsoft 36-benchmark comparison, Average accuracy | 82.3 %vendor-run9 Oct 2026 | Not published as of 23 Oct 2026 |
| Microsoft 36-benchmark comparison, Calibration score | 93.7 scorevendor-run9 Oct 2026 | Not published as of 23 Oct 2026 |
| Artificial Analysis Decision Index, Index score | 57.1 scorev1.0, 16 Oct 2026 | Not published as of 23 Oct 2026 |
| Artificial Analysis Decision Index, Expected calibration error | 0.0952 ECEv1.0, 16 Oct 2026 | Not published as of 23 Oct 2026 |
| Artificial Analysis Decision Index, Cost per 1M tasks | 42 USDv1.0, 16 Oct 2026 | Not published as of 23 Oct 2026 |
| Artificial Analysis Decision Index, Time per task | 78 msv1.0, 16 Oct 2026 | Not published as of 23 Oct 2026 |
| Fast Decisions, Average accuracy | Not published as of 23 Oct 2026 | 60.1 %vendor-run24 Sep 2026 |
| Docs and console | docs.typesafe.ai, Console | github.com |
- 1 Jev: 70ms to 500ms end-to-end is TypeSafe's own figure from the launch post, as is the 3 to 329 seconds it compares frontier LLMs against and the resulting 40x to 200x multiple.
- 2 GLiNER2.5-Decide: Founder George Maloney's launch post gives p50 latency for short, single-document requests: 167ms on a 48-vCPU Intel Xeon Platinum 8581C CPU, and 38 to 47ms on GPU (T4, L4, V100, A100).
Examples in the directory
638 Jev examples
The top 3 by stars and views. All Jev examples.
Jev Ultrafast (Browser Use)
Browser Use's fast browser agent where Jev picks the operation and the DOM element in a single request; a small LLM is only invoked to write text when typing is required. Demoed on a Google Flights search.

19k starsFlight search 7.1 s
openjev
Attempt to run a Jev-style System One decision model locally on a single RTX 3090. Companion site at openjev.com. The repository was renamed to TheoLeeCJ/SemIf on GitHub, and the old openjev URL now redirects to it.
 TheoLeeCJOpenopenjev on github.com
4.1k starsJSON vs direct 5.21x slowerPeak throughput 20.03 dec/s
jev-trader
Makes one AI trade decision every Monad block on the Kuru MON-USDC market using Jev. The public deployment runs in dry-run mode with a mock model.
 jarrodwattsOpenjev-trader on github.com
2.2k starsLoop, mock model p50 100 msDecision window ~300 ms/block
2 GLiNER2.5-Decide examples
The top 2 by stars and views. All GLiNER2.5-Decide examples.
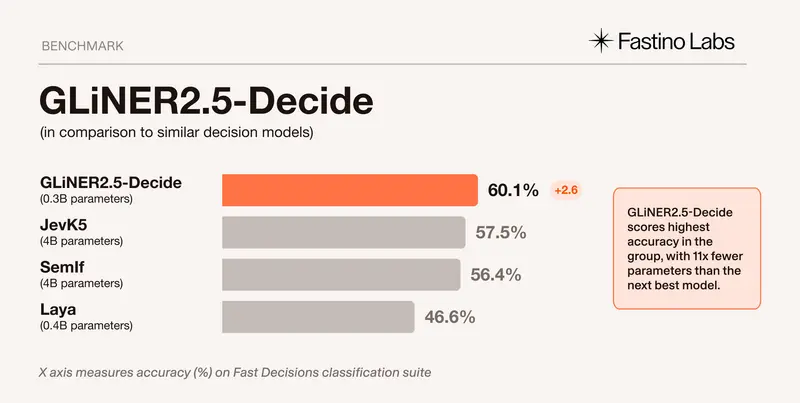
GLiNER2.5-Decide
Open-weights 340M-parameter decision model from Fastino Labs. It jointly decodes typed classification questions and, per Fastino's own internal benchmark, leads 9 of 17 datasets against JevK5, SemIf and Laya.
 Fastino Labs (@fastinoAI)OpenGLiNER2.5-Decide on huggingface.co
2.2k starsCPU latency 167 msGPU latency 38-47 ms
Jev Decision Index: Jev against 50+ open decision models
A leaderboard that runs Jev and 54 open System One models and clones through the same 120,000-question suite on one RTX PRO 6000, scoring accuracy and calibration. Jev leads the 0.2 edition at 51.67 on a chance-corrected scale, with AutoJev-27B close behind at 50.94.
 apolinario (poli) (@multimodalart)43k viewsOpenJev Decision Index: Jev against 50+ open decision models on huggingface.co
Shared use cases
Patterns both Jev and GLiNER2.5-Decide list on their pages.
The short answer
GLiNER is no longer one model with one job. The original GLiNER tells you where something is in the text: ask for PERSON, DRUG and DOSAGE and it returns spans with start and end offsets. GLiNER2.5-Decide, which Fastino Labs released on 24 September 2026, is a separate model in the same family that instead answers typed questions about the whole passage and returns a probability, without pointing at any span. That second model is the closer comparison to Jev. Jev stays a closed, hosted API. Both GLiNER models are Apache 2.0 weights you download and run yourself.
Jev vs the GLiNER family at a glance
| Jev | GLiNER (span extraction) | GLiNER2.5-Decide | |
|---|---|---|---|
| Task | A decision over an option set you define | Zero-shot named entity recognition | Typed classification questions, plus spans, relations and structured records |
| Labels | Supplied per request | Supplied per request | Supplied per request |
| Output | Choice, Score or Noul with a probability per option | Typed spans with start and end offsets | Structured decisions with probability distributions and confidence scores; no fixed Choice/Score/Noul naming |
| Model size | Undisclosed, closed model | Small, medium and large variants; parameter counts are not stated on the README | 340M per the model card and blog; Hugging Face’s own safetensors metadata reports 486,444,053 parameters, an unresolved discrepancy |
| Licence and weights | Closed, managed API only | Apache 2.0, weights on Hugging Face | Apache 2.0, weights on Hugging Face |
| Runs locally | No | Yes, including on CPU | Yes; Fastino says it runs on consumer-grade CPUs or air-gapped |
| Latency | 70ms to 500ms end to end (TypeSafe’s own figure) | No absolute figures published; the README gives up to about 1.5x from torch.compile and up to about 1.9x with FP16 plus compilation |
Fastino’s own figures: p50 167ms on a 48-vCPU CPU, 38 to 47ms on GPU (T4, L4, V100, A100) for short requests |
| Cost | $0.042 per million input tokens, output free | Your own hardware | Your own hardware; Fastino also runs hosted inference and fine-tuning at agent.fastino.ai with no published price |
| Benchmark | 57.5% average on Fastino’s own “Fast Decisions” suite, as JevK5, reported by Fastino | Not evaluated on that suite | 60.1% average on the same Fastino-run suite, leading on 9 of 17 datasets |
| Calibration | Trained with RLCD, unaudited outside TypeSafe | Span scores with no calibration claim | Returns confidence scores per the model card; no independent calibration audit found |
| Languages | English first; docs say other languages including CJK scripts are handled, and recommend testing your own content | 100+ languages claimed, with multilingual variants | English, per the sources checked; no multilingual claim found for this model |
Sources: the GLiNER GitHub README and arXiv:2311.08526, docs.typesafe.ai/models, the TypeSafe launch post, Fastino’s GLiNER2.5-Decide blog post, the Hugging Face model card and the fastino-ai/GLiNER2 GitHub repo, checked 2026-09-25.
What classic GLiNER does
GLiNER is a bidirectional transformer encoder that performs named entity recognition against label types given at inference time, from the paper “GLiNER: Generalist Model for Named Entity Recognition using Bidirectional Transformer” (Zaratiana, Tomeh, Holat and Charnois, arXiv:2311.08526, submitted 2023-11-14). Ask it for PERSON, DRUG and DOSAGE and it finds those spans in a clinical note without having been trained on your schema.
The paper’s headline claim is that GLiNER outperforms both ChatGPT and fine-tuned LLMs in zero-shot NER evaluations, and that it extracts entities in parallel rather than through sequential token generation. The F1 figures behind that live in the full paper and are not restated here.
The family has grown past a single checkpoint: a uni-encoder original aimed at around 50 entity types, a bi-encoder that scales to far larger type counts, a RelEx variant doing joint entity and relation extraction, a decoder variant for generative entity types, and StreamingSpan for incremental extraction. Separately named siblings cover multi-task extraction (GLiNER2), zero-shot text classification (GLiClass), schema-conditioned safeguarding (GLiGuard) and multilingual PII (GLiNER2-PII). All Apache 2.0. The directory entry has the repository details.
What GLiNER2.5-Decide does
GLiNER2.5-Decide is a separate, newer release from Fastino Labs: a 340M-parameter encoder (per the blog post and model card; Hugging Face’s own weight metadata reports 486,444,053 parameters, and nothing in either source explains the gap), fine-tuned from Fastino’s gliner2-large-v1, itself a DeBERTa-v3-large base. It evaluates a set of user-defined typed questions and rules against a piece of text in one pass and jointly decodes the answers, returning probability distributions and confidence scores rather than spans. Fastino also describes it returning character-level spans, relations and structured records, and applying cross-decision rules such as implications, exclusions and cardinality limits, in the same call. The model card is explicit that “this release is not a general-purpose model. It does not reason, explain, or answer open questions.”
That output shape, a typed answer with a probability and no requirement to point at a span, is what makes GLiNER2.5-Decide the GLiNER-family model worth comparing to Jev, rather than the original span extractor. Fastino’s own vocabulary for the question types differs from TypeSafe’s; nothing in the sources checked maps GLiNER2.5-Decide’s typed questions one-to-one onto Jev’s Choice, Score and Noul, beyond both returning a typed answer with a probability.
What Jev does
Jev answers questions about a state you send it. The three primitives are a Choice picking one of up to 255 options, a Score placing the state on 2 to 10 ordered levels, and a Noul answering yes or no as a single number between 0 and 1. Each answer carries a probability.
Nothing in that output points at the text. The API has one documented endpoint, POST /v1/systemone, and no span, offset or entity type appears in it.
Can Jev do named entity recognition?
Not as NER is normally defined, because Jev never returns a span. If your downstream code highlights text, redacts a range or stores a character offset, Jev cannot supply it.
Two shapes get you part of the way. Extract candidates some other way and send them as a Choice over the candidate list, so the model picks the right one. Or send one Noul per candidate, asking whether this string is the drug name in this note. Both use Jev for the judgment and something else for the locating.
Can GLiNER classify text?
Classic GLiNER returns spans, so classifying a whole document is not what it is built for. The sibling model GLiClass exists for zero-shot text classification, and GLiGuard does schema-conditioned classification aimed at LLM safeguarding.
GLiNER2.5-Decide changes this for the family: it is built specifically to answer typed classification questions about a whole passage, per its blog post and model card, and Fastino positions it for support and banking intent, sentiment, document type and routing decisions, the same territory Jev targets. The gap that made span models a poor fit for judgments written nowhere in the text, such as severity, intent or tone, is the gap GLiNER2.5-Decide is built to close.
Speed, cost and hosting
Classic GLiNER is free to run and you pay for the hardware. The README publishes no absolute millisecond figures, only relative speedups: up to about 1.5x from torch.compile, and up to about 1.9x for GPU inference with FP16 quantization plus compilation. GLiNER2.5-Decide is also Apache 2.0 with no waitlist, and Fastino publishes absolute figures: a p50 of 167ms on a 48-vCPU Intel Xeon Platinum 8581C CPU, and 38 to 47ms on GPU (T4, L4, V100, A100) for short, single-document requests. Because both GLiNER models are open weights, the text never leaves your network, which settles the question for regulated data on its own.
Fastino also runs hosted inference and fine-tuning for GLiNER2.5-Decide at http://agent.fastino.ai, aimed at calling from inside a coding agent. No pricing for that service appeared in the sources checked.
Jev is a managed API at $0.042 per million input tokens with free output, and TypeSafe publishes 70ms to 500ms end to end from its own evaluation. No independent latency benchmark for Jev had been published as of 2026-09-25, and no controlled head-to-head of Jev against either GLiNER model exists that this site could verify, so treat any single comparison you find as one author’s setup until you reproduce it.
The cost shapes differ more than the numbers suggest. GLiNER’s bill is fixed, so your per-document cost falls as volume rises. Jev’s bill scales with the tokens you send, which makes small and spiky workloads cheap and very large corpora expensive.
What Fastino’s own benchmark shows
Fastino evaluated GLiNER2.5-Decide on “Fast Decisions,” an internal suite of 17 datasets covering intent routing, triage, sentiment and content understanding, and compared it against JevK5, SemIf and Laya. This is Fastino’s own benchmark, not an independently run one, and it is not the same test TypeSafe uses to publish Jev’s own figures elsewhere on this site. The blog post and Fastino’s X post give GLiNER2.5-Decide 60.1% average accuracy against JevK5 at 57.5%, leading on 9 of 17 datasets; the Hugging Face model card’s results table gives 60.2% and 57.6% for the same run. Fastino highlights support intent classification at 75.3%, 18.6 points ahead of the next model, and banking intent at 64.3%, 8.6 points ahead. Treat “JevK5” as Fastino’s label for whichever Jev configuration it tested, since no other source on this site uses that name.
Using GLiNER and Jev together
The sequence that still makes sense for the original GLiNER is extract, then decide. GLiNER finds the candidate spans, and Jev answers the questions that have no span to point at.
Structured extraction is the obvious case. Pull the entities out of a contract with GLiNER, then send each one to Jev as a Noul asking whether the clause it sits in is an obligation on your side. Entity alignment is the other. Extraction gives you a surface string, and deciding which record that string refers to is a Choice over your candidate matches, with a probability you can threshold before writing to the graph. The alternatives directory lists the other open-weights models people put in the extraction slot. Cloudflare’s Clairic now fills that slot as a hosted extraction model that returns typed values, not only spans; Clairic vs GLiNER compares the two.
Where GLiNER2.5-Decide fits is different: it competes for the same slot as Jev, rather than feeding it. A pipeline that already runs GLiNER for extraction could reasonably route the decision step to GLiNER2.5-Decide instead of Jev, since it is running the same family of encoder on the same hardware.
When to use which
Use classic GLiNER when you need offsets, when the data cannot leave your network, when volume is high enough that per-token pricing adds up, or when you need a multilingual extractor. Use GLiNER2.5-Decide when you want a typed classification decision on your own hardware under Apache 2.0, and Fastino’s benchmark or your own tests hold up for your task. Use Jev when you want a managed API with no hosting to run, a calibrated probability trained with a published method name (RLCD, even if the method itself is unpublished), or several judgments about one document in a single call with TypeSafe’s documented Choice, Score and Noul shapes. Many pipelines still want an extractor and a decision model together, in that order.
FAQ
Is GLiNER an alternative to Jev?
For extraction work, classic GLiNER is the tool you should have been using anyway. For decisions about a whole document, GLiNER2.5-Decide is now a real alternative on paper: Fastino’s own benchmark puts it ahead of what it calls JevK5 on 9 of 17 datasets. Confirm it on your own data before switching.
Can Jev extract entities?
No. Jev returns a Choice, Score or Noul about the state you send, never a span or an offset. You can send candidate entities found elsewhere as Choice options, or ask one Noul per candidate, but the locating has to happen before the call. The API documents a single endpoint with no extraction shape.
Is GLiNER free?
Yes, for both models. Classic GLiNER and GLiNER2.5-Decide are Apache 2.0 with weights published on Hugging Face, so you can download either, run it locally and use it commercially. The cost is the hardware and the engineering time to deploy it, or Fastino’s unpriced hosted inference for GLiNER2.5-Decide. Jev has no equivalent free tier, since it is a closed model behind a metered API.
Which is faster, Jev or GLiNER?
There is no verified head-to-head benchmark for either GLiNER model against Jev. Classic GLiNER’s README publishes only relative speedups, not absolute figures. GLiNER2.5-Decide’s absolute figures come from Fastino itself: p50 167ms on CPU and 38 to 47ms on GPU for short requests, not independently reproduced. TypeSafe publishes 70ms to 500ms for Jev from its own evaluation, also unconfirmed by an independent test as of 2026-09-25.
Can I run GLiNER locally?
Yes, for both models. The weights are on Hugging Face under Apache 2.0, both are small enough to run on CPU, and classic GLiNER’s repository documents torch.compile and FP16 quantization for faster GPU inference. Nothing leaves your network, which matters when the documents cannot be sent to a vendor.
Is GLiNER2.5-Decide the same thing as Jev, just open source?
No. It answers Fastino’s own typed classification questions and, per its own sources, also returns spans, relations and structured records and can enforce cross-decision rules; none of that is confirmed to map directly onto Jev’s Choice, Score and Noul primitives. It is a separate model, and the model card says outright that it does not reason, explain or answer open questions.
Examples
GLiNER: generalist lightweight NER
Compact encoder model that takes the label set as input at inference time and extracts arbitrary entity types zero-shot on CPU. Same classifier-that-takes-its-categories-as-input shape, for extraction rather than decisions. Star count is GitHub's rounded display figure.

GLiNER2.5-Decide
Open-weights 340M-parameter decision model from Fastino Labs. It jointly decodes typed classification questions and, per Fastino's own internal benchmark, leads 9 of 17 datasets against JevK5, SemIf and Laya.
Fastino Labs (@fastinoAI)OpenGLiNER2.5-Decide on huggingface.co2.2k starsCPU latency 167 msGPU latency 38-47 ms