The problem
You have invoices, emails or receipts, and you want typed fields out of them: a total, a due date, an invoice number. System One models come in two classes, and each takes a different route to the same fields.
The direct route is an extraction model. Cloudflare’s Clairic, in preview on Workers AI, takes a map of named fields, each with a type, and returns a value per field. It can also compute values the text never states, such as a due date from an issue date and payment terms.
The other route uses a decision model. Jev is not trained to generate text. TypeSafe says so plainly in the jaggedness list for jev-1.13: you can force generation by chaining choices, but it works badly and runs slowly. So “read this invoice and return the total” is not something Jev can do. Turn the problem around and it gets easier.
A regex can find every money-shaped string in an invoice. What it cannot do is tell you which one is the total the customer owes and which one is a credit already applied. That is a reading comprehension question with a small fixed answer set, which is the shape a choice question fits.
The side effect is worth stating. Because the options are spans that code already found, the answer is a copy of one of them. There is no digit to transpose and nothing to invent, which removes an entire class of hallucination from the pipeline. Projects like commit-miner use this shape to pull structured fields out of unstructured history.
What the state looks like
State is the content the fields or questions get judged against. Both models take the document as it is. With Jev, send the candidate list as part of the question rather than the state, since the candidates are the options. Clairic needs no candidates, and a request can carry up to four images, so a receipt photo can go in beside the text.
{
  "document_id": "INV-2087",
  "text": "Invoice INV-2087.\nSubtotal: $1,200.00\nSales tax: $115.50\nTotal due: $1,315.50\nA $50.00 courtesy credit from last month has already been applied."
}
Four money strings in there and a regex finds all four. Nothing in the digits says which is which. The words around them do, and that is the part worth a model.
The questions you ask
With Clairic: name the fields
Each field gets a type and, when the name is not enough, plain-language instructions. This runs from a Worker:
const { answers } = await env.AI.run("@cf/cloudflare/clairic", {
  model: "clairic",
  state: INVOICE.text,
  fields: {
    invoice_number: { type: "text" },
    total: { type: "number", decimals: 2, unit: "USD", instructions: "Total the customer must pay" },
    credit_applied: { type: "number", decimals: 2, unit: "USD", instructions: "Credit or refund already applied" },
  },
});
Each answer carries value, p_null (the probability the value is not in the input), confidence and guess. A text answer is a span of the input with its offsets, so you can trace it back to the source. There is no cap on the number of fields, and Cloudflare says thirty fields cost about the same as three. The field definitions do bill as input tokens: in the invoice example on the Workers AI model page they took 472 of 655.
With Jev: find, then pick
Find in code, pick with a choice, copy the pick.
import re
from decimal import Decimal

from typesafe_sdk import Choice, Noul, TypeSafeClient

MONEY_RE = re.compile(r"[$€£¥]\s?\d[\d,]*(?:\.\d{2})?")
NONE = "none"

client = TypeSafeClient()
candidates = list(dict.fromkeys(MONEY_RE.findall(INVOICE["text"])))

response = client.system_one(
    INVOICE,
    {
        "total": Choice(
            instructions="Which amount is the total the customer must pay?",
            criteria={c: None for c in candidates} | {NONE: "None of these is the requested value."},
        ),
        "is_credit": Noul(
            instructions="Does this invoice show a credit or refund applied to the customer?"
        ),
    },
)

picked = response.choices["total"].choice
amount = Decimal(re.sub(r"[^\d.]", "", picked)) if picked != NONE else None
Tune the regex to over-find. Recall is what matters, because anything it misses cannot be picked. The none option does real work: without it the model must pick something even when the document never states the value, and a wrong pick is harder to catch than an abstention.
A noul, a yes/no question returning one probability from 0 to 1, handles the attributes that go with the value. Is this amount a credit or a charge? Which decimal convention does the document use? In TypeSafe’s cookbook run the credit question came back at 0.01 on the invoice total and 0.99 on the courtesy credit, so the code knew the sign of each number it parsed.
Dates get the same treatment, in parts. The month, the day and the year are each a small closed set, so each becomes its own choice with an explicit “not stated” option, and code assembles the parts into a real date. Never ask Jev to compare two dates or work out a duration.
Decision policy
With Clairic, the first gate is p_null. Each field can set a null_threshold, the p_null above which its value comes back null; the default is 0.5. A null answer still carries a guess, which helps a reviewer and should never reach a ledger. Cloudflare says calibration “is measured, not guaranteed”, so put a floor on confidence too and check both against documents you have already labelled.
const total = answers.total;
if (total.value === null) {
  queueForReview(INVOICE, { reason: "total not found", guess: total.guess });
} else if (total.confidence < REVIEW_BELOW) {
  queueForReview(INVOICE, { reason: "low confidence", value: total.value });
} else {
  postToLedger(total.value);
}
With Jev, code owns the copy, the normalisation and everything downstream. The model only ever selects.
REVIEW_BELOW = 0.60

answer = response.choices["total"]
if answer.choice == NONE:
    queue_for_review(INVOICE, reason="no candidate matched")
elif answer.confidence < REVIEW_BELOW:
    queue_for_review(INVOICE, reason="low confidence", value=answer.choice)
else:
    post_to_ledger(amount)
A choice answer carries a confidence value from 0 to 1 alongside the full probability distribution over the options, so you can gate on it. TypeSafe’s date cookbook flags anything under 0.60 for a person and reports the lowest confidence among the parts it used, which means one weak answer on the year sends the whole date to review. That is the behaviour you want on a field that becomes a payment.
Set the floor where the review volume is bearable and the escapes are rare. Two candidates that both look plausible will split the probability mass between them, which shows up as low confidence rather than as a silent coin flip. TypeSafe is explicit that the right threshold depends on your domain, so measure yours on documents you have already labelled. The confidence-gated action recipe covers the routing.
When not to use this
Neither model writes prose. Summaries and rewritten clauses belong to an LLM. Jev also cannot produce a field value it was not offered, and chaining choices to fake it is slow and unreliable. When no pattern or roster can supply the candidates, use Clairic.
Clairic has limits of its own, which Cloudflare lists for the preview. Long chains of dependent steps and totals across many table rows are not reliable, so “have Clairic predict the value and let code do the math.” It does not pick from options either, so a decision about the values goes to a decision model such as Clef or Jev. Clef vs Clairic covers that chain.
With Jev, counting the candidates or summing them is out too. Counting is a documented weak spot, arithmetic belongs in code, and the decimal parsing in the snippet above is deliberately code-side for exactly that reason.
Date comparison is the same trap. Extract the parts and do the calendar work yourself, since “is this deadline before that one” is arithmetic wearing a text costume.
Two practical ceilings. A choice takes at most 255 options, so a document with more candidates than that needs narrowing in two stages: pick the section first, then the span inside it, which is the same idea as hierarchical classification. And some values have no regex at all. A person’s name is not a pattern, so its candidates have to come from a roster you already hold or a named entity recogniser.
FAQ
Should I use Clairic or Jev for extraction?
Use Clairic when you want the value read or computed directly, with no candidate step, and Workers AI fits your stack. Use Jev when your code can already find the candidates and you want the answer to be a verbatim copy of one of them, or when Jev already runs in that pipeline. Jev vs Clairic goes into the differences.
What if the regex misses the value entirely?
Then Jev cannot return it, and with a none option in the criteria it will usually say so rather than pick a wrong candidate. That failure is visible, which is the point of building it this way. Tune the pattern for recall and let the model discard the extra matches, since over-finding costs you nothing but a few more options.
How do I extract a value with no obvious pattern?
Produce the candidates some other way and keep the same second step. A roster of customer names, a named entity recogniser, or a generative model proposing spans all work. Jev then picks which one the question asks for, so the selection stays typed and the returned value is a verbatim copy of something that was in the document.
Can one request extract several fields at once?
Yes, and it should. Each question is scored independently against the same state, and TypeSafe’s fan-out pattern notes there is no speed cost for additional questions. Send the total, the credit, the currency and the invoice number together, with each field’s own candidate list as its own criteria, and read them off one response object.
Why not just use an LLM with structured outputs?
An LLM writes the value, so it can write one the document does not contain. With Jev the answer space is the set of spans your code found, so a wrong answer is a wrong selection rather than an invented string. Clairic returns text fields as spans with offsets and gives every field a p_null, so a missing value comes back null.
Examples in the wild
Introducing System One Models and Jev (Hacker News launch thread)
The 1,978-point, 513-comment launch thread. The top comment calls the speed comparison misleading, since Jev only returns structured output, and disputes the cannot-hallucinate claim because a valid type can still hold a wrong value. Others note ordinary LLMs can already be forced into structured output.
DSPy: programming, not prompting, language models
Declares typed input/output Signatures for LLM modules and optimizes the underlying prompts and weights against a metric. Its Signature abstraction is the closest widely-used open equivalent of Jev's typed-question interface. Star count is GitHub's rounded display figure.

Outlines: structured outputs for LLMs
Guarantees valid structured output during generation by constraining decoding to a grammar or schema. The mechanism HN commenters repeatedly cited as already covering Jev's cannot-produce-a-type-error guarantee on ordinary LLMs. Star count is GitHub's rounded display figure.

Instructor: reliable JSON from any LLM
Pydantic-based library that extracts typed, validated structured data from LLMs across providers with automatic retries. The established way teams get Jev-style typed answers today, at LLM latency and cost. Star count is GitHub's rounded display figure.

GLiNER: generalist lightweight NER
Compact encoder model that takes the label set as input at inference time and extracts arbitrary entity types zero-shot on CPU. Same classifier-that-takes-its-categories-as-input shape, for extraction rather than decisions. Star count is GitHub's rounded display figure.

vercel-labs/ai-cli
Vercel Labs CLI for generating from the terminal. Its evaluate command takes a state plus typed questions and defaults its evaluation model to typesafe-ai/jev on the AI Gateway, with -m jev as the shorthand and an --input flag for text or JSON state.

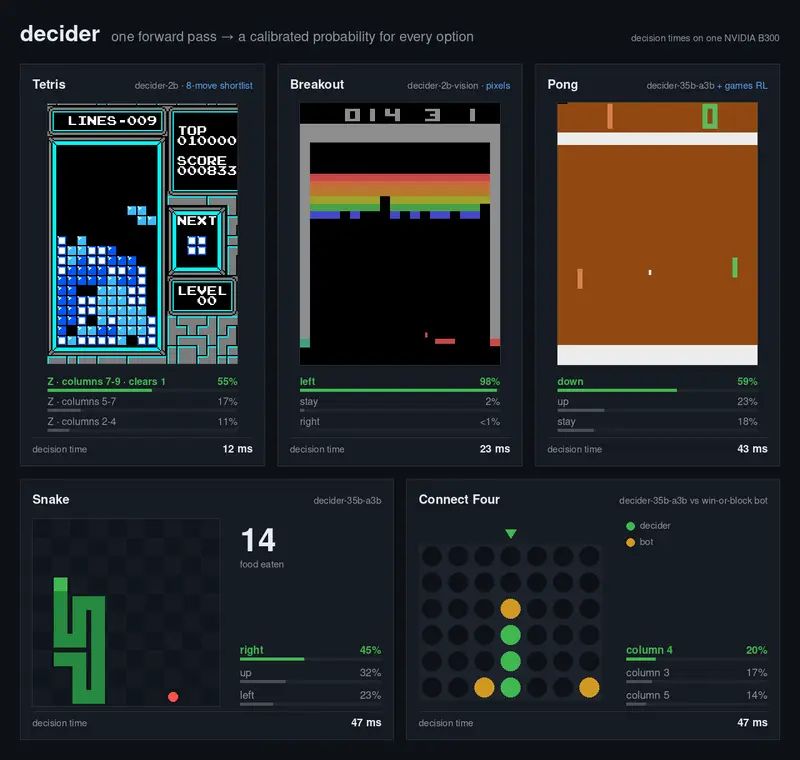
decider: one-pass typed decisions with calibrated probabilities (Qwen3.5-2B)
Open reproduction of the System One model class, fine-tuned from Qwen3.5-2B-Base, returning a probability distribution per typed question in a single forward pass. Serves TypeSafe's POST /v1/systemone wire format so TypeSafe SDKs work unchanged by repointing TYPESAFE_BASE_URL.

Advocaat
Small type-safe client for asking questions about your data, powered by Jev. Returns probabilities, choices and scores in a single request, and ships an agent skill that teaches coding agents how to design the questions.

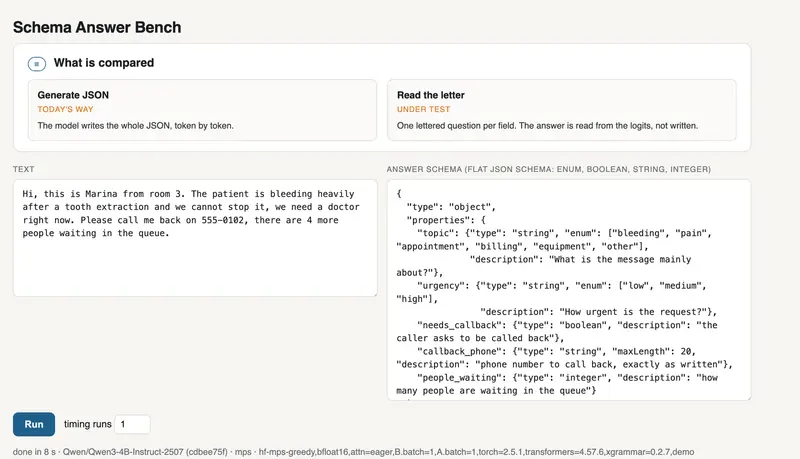
mini-jev: Jev's interface from a frozen LLM's next-token logits
Measures whether an untrained frozen Qwen3-4B can classify against a schema by reading next-token logits for option letters, compared against grammar-constrained JSON generation. Implements analogues of Choice and Noul only; explicitly not a reproduction.

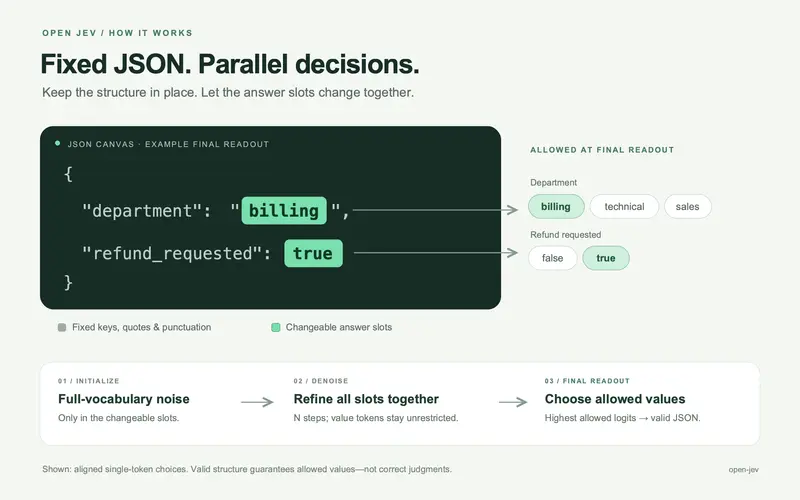
open-jev (JoshuaSP): typed JSON inference with DiffusionGemma
Experimental inference harness for typed JSON decisions with DiffusionGemma: denoise freely, then pick the most likely allowed tokens from the final logits, with no training or fine-tuning. Reports results against Jev benchmarks, measured on an H100.

commit-miner
Rust CLI that classifies Git commit diffs and messages with Jev, labelling bug fixes, security fixes with CWEs, and change types. Scans a local repo or remote URL and exports HTML or CSV reports.

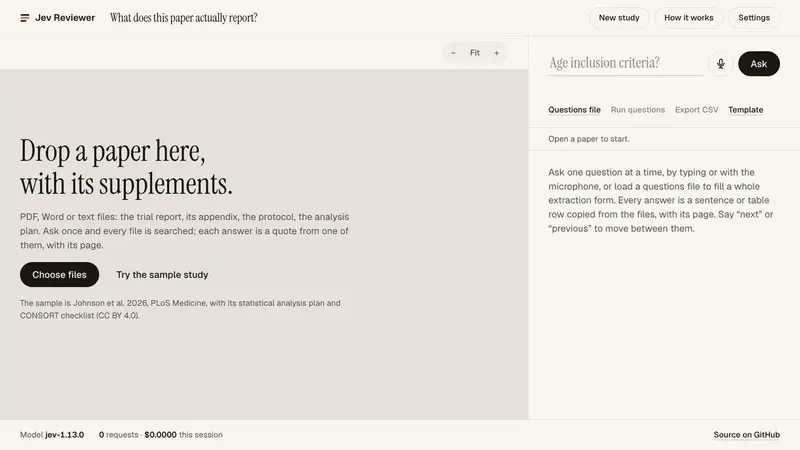
Jev Reviewer
Data extraction for systematic reviewers, built on Jev. It answers extraction forms and risk-of-bias templates like RoB 2, ROBINS-I, QUADAS-2 and TIDieR against a trial report and its supplements, with every answer a verbatim quote and page number to check against the source. Files stay in the browser.
 Ahmad Sofi-Mahmudi (@ASofiMahmudi)OpenJev Reviewer on github.com
33 starsInput price $0.042/M tok