Asking for one overall rating hides the reasoning inside a single number. Score each dimension as its own question instead, normalise each answer to a 0 to 1 range, and combine them with weights your code owns, so a ranking can be explained and retuned without new model calls.
A tabular model needs numbers, and a written note is not one. Ask Jev a set of questions about each row, keep the probability distribution rather than the winning answer, and you get numeric columns that a gradient-boosting model can train on alongside your existing features.
A taxonomy with thousands of leaves will not fit in one question. Ask one choice question per node instead, walking down the tree, and use the probability on each edge to decide whether to follow the single best path or keep several candidates alive.
There are two routes. Clairic, Cloudflare's extraction model, takes named fields and returns typed values, each with the probability that it is missing. Jev cannot write values, so code finds candidate spans, a choice question picks one, and code copies it unchanged.
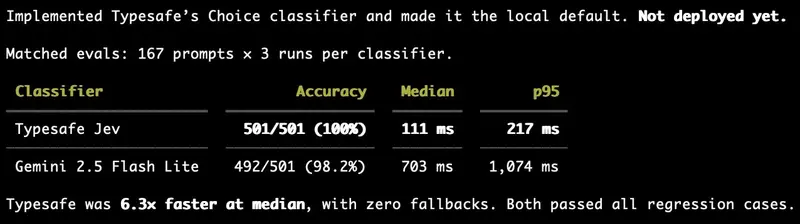
Vercel CTO reports Jev saturated an existing classifier eval that had used Gemini 2.5 Flash Lite and ran about 6x faster. Original post; TypeSafe's quote-tweet is a separate item.
The 1,978-point, 513-comment launch thread. The top comment calls the speed comparison misleading, since Jev only returns structured output, and disputes the cannot-hallucinate claim because a valid type can still hold a wrong value. Others note ordinary LLMs can already be forced into structured output.
Declares typed input/output Signatures for LLM modules and optimizes the underlying prompts and weights against a metric. Its Signature abstraction is the closest widely-used open equivalent of Jev's typed-question interface. Star count is GitHub's rounded display figure.
Guarantees valid structured output during generation by constraining decoding to a grammar or schema. The mechanism HN commenters repeatedly cited as already covering Jev's cannot-produce-a-type-error guarantee on ordinary LLMs. Star count is GitHub's rounded display figure.
Pydantic-based library that extracts typed, validated structured data from LLMs across providers with automatic retries. The established way teams get Jev-style typed answers today, at LLM latency and cost. Star count is GitHub's rounded display figure.
Compact encoder model that takes the label set as input at inference time and extracts arbitrary entity types zero-shot on CPU. Same classifier-that-takes-its-categories-as-input shape, for extraction rather than decisions. Star count is GitHub's rounded display figure.
Fine-tunes Sentence Transformer embeddings plus a lightweight head for high-accuracy classification from a handful of labeled examples, with no prompting. The standard cheap alternative to an LLM classification call when the label set is fixed. Star count is GitHub's rounded display figure.
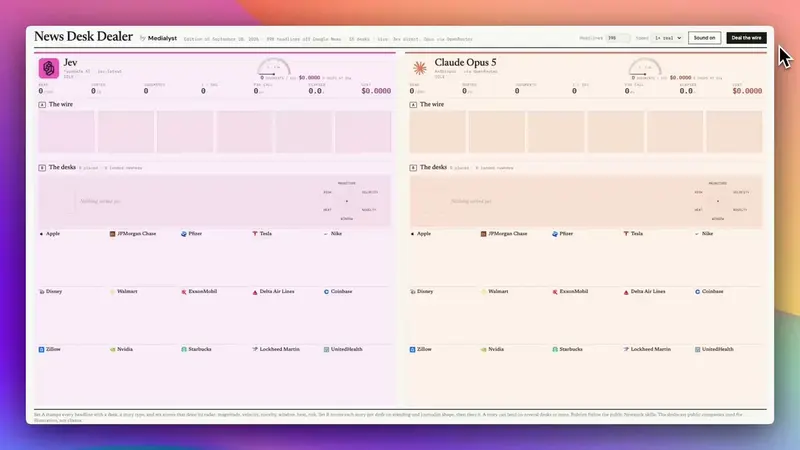
Open source skills that read a morning's news feed with Jev and tell a list of brands which stories to act on. In a demo run it read 384 headlines and matched them to 15 brands in 24.9 seconds for $0.19, against 4 of 384 for $0.77 on Claude Opus 5 over the same feed.
Vercel Labs CLI for generating from the terminal. Its evaluate command takes a state plus typed questions and defaults its evaluation model to typesafe-ai/jev on the AI Gateway, with -m jev as the shorthand and an --input flag for text or JSON state.
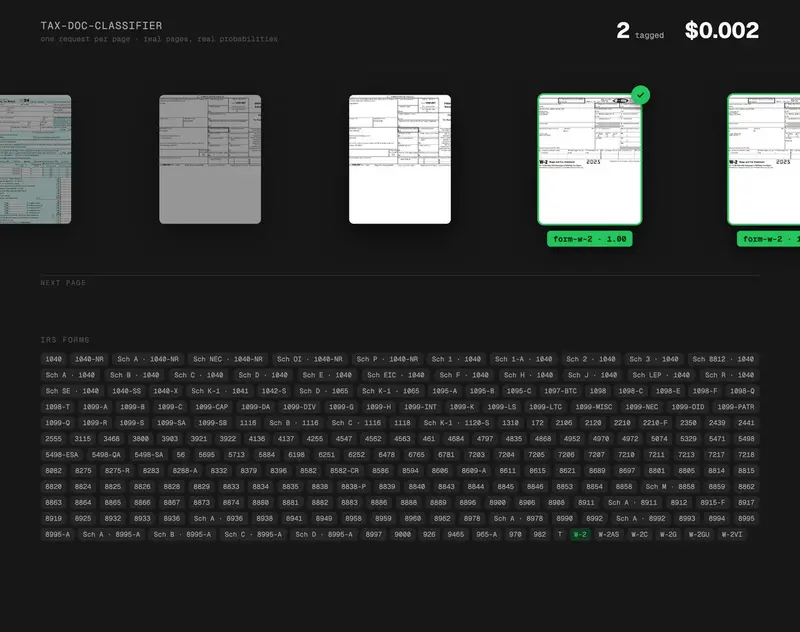
A TypeScript classifier that sends each PDF page's text to Jev as a choice over 261 IRS forms and 7 page kinds, with a second call only for five corporate forms and their schedules. Its eval reports 0 wrong pages on 314 filled TaxCalcBench forms at about $0.001 per page, 34x cheaper and 6x faster than the Sonnet pipeline it replaced.
Open reproduction of the System One model class, fine-tuned from Qwen3.5-2B-Base, returning a probability distribution per typed question in a single forward pass. Serves TypeSafe's POST /v1/systemone wire format so TypeSafe SDKs work unchanged by repointing TYPESAFE_BASE_URL.