What Clef is
Clef is a System One model trained by Cloudflare. You send a state and a set of typed questions, and it returns a probability for every allowed option of every question, with no generated text. It comes in two sizes. Clef is 27B parameters and Clef-flash is 9B. Both run on Cloudflare Workers AI as @cf/cloudflare/clef and @cf/cloudflare/clef-flash. On 9 October 2026 Cloudflare added a third model, Clef-omni, a mixture-of-experts model that also reads audio and video. It has its own page.
Cloudflare calls the request format “fully Jev-API compatible”. It uses the same state and questions fields and the same Noul, Choice and Score question types as Jev, so the request body moves between the two with the model field changed.
What it adds to the Jev request
Two differences are Cloudflare’s own list. Clef reads images, where Cloudflare’s post says Jev reads text only. TypeSafe has since added PNG and JPEG input to Jev, but only behind an opt-in header. The docs add an optional images array of up to four images, which they call a Clef extension to the System One API. Clef’s context window is 65,536 tokens on Workers AI, against 32,000 for Jev per Cloudflare’s post. Clef-flash’s is 24,576. TypeSafe gives Jev 64,000 tokens for the whole request, of which the state plus the longest question must fit in 32,000. The docs also say the state can be text, JSON, images or video.
How it was built
Cloudflare says each model keeps a frozen Qwen backbone, Qwen3.8-27B for Clef and Qwen3.5-9B for Clef-flash. A routing head and rank-256 adapters are trained on top. Inference runs one forward pass over the input, then scores every valid answer in parallel, so no text is generated token by token. Training used label-smoothed cross-entropy with a Brier loss for calibration, synthetic data, and a second stage Cloudflare calls Reinforcement Learning for Calibrated Decisions. It builds on Cloudflare’s earlier DiffusionGemma experiment, which drew on Matt Mastracci’s djev. See how Jev is built for the comparison.
What Cloudflare reports
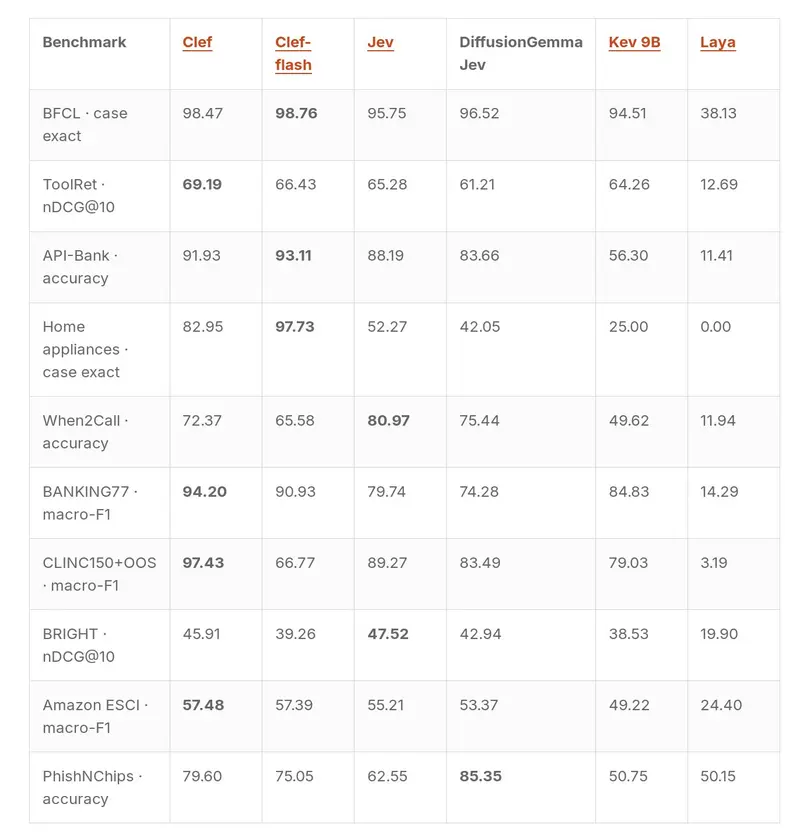
Every figure here is vendor-run: Cloudflare ran the evals and published the tables. On 10 tasks it picked from the Jev Decision Index (multimodalart’s community board on Hugging Face), Clef scores higher than Jev on eight and lower on two: When2Call, 72.37 against 80.97, and BRIGHT, 45.91 against 47.52. Clef-flash scores 66.77 on CLINC150+OOS against Jev’s 89.27. On TypeSafe’s workflow evals Clef beats Jev on invoice processing (64.7 against 61.8), customer service (76.3 against 76.0) and security incidents (62.9 against 61.7), and trails it on agent trace observability (68.5 against 71.6). Cloudflare also says Clef is currently the leader when evaluated against the Jev Decision Index.
What the Jev Decision Index shows
The public Jev Decision Index, a third-party board, added both models in edition 0.3 on 7 October 2026. The figures here are from edition 0.4.1, in the file generated on 12 November 2026. On its public benchmarks Clef scores 61.71 and Clef-flash 56.15, against 60.7 for Jev 1.14. Since edition 0.4 the headline Full score counts only private tests: 60% tests of the same skills and 40% tasks in new domains. There Clef scores 54.92, 104th of 301 rows, and Clef-flash 44.43, 154th, against Jev 1.14’s 60.24, because both score lower on the private tests. Their calibration errors are 0.040 and 0.025, lower than Jev 1.14’s 0.080. So the outside run backs Cloudflare on the public tasks, but not its claim that Clef leads. In the 0.3.1 file of 10 October 2026, Clef scored 53.08 and Clef-flash 47.61 on the Full score.
What the Artificial Analysis Decision Index shows
On version 2.1 of the Artificial Analysis Decision Index, checked on 14 November 2026, Clef scores 60.3, 19th of 22 decision models, against 66.2 for Jev 1.14. It was 16th of 19 on 12 November, before AA added three rows. Version 2.1 has no Clef-flash row. Clef trails Jev 1.14 on every one of AA’s sub-scores except accuracy on the private knowledge questions, 37.8% against 31.6%. Its weakest results are When2Call tool calling, 71.0% against Jev 1.14’s 80.8%, and a non-hallucination rate of 6.8, so it rarely answers “I don’t know” when it is wrong. It cost $863 per million tasks, the most of the 22, and took 354 ms per task, the slowest. On version 1.0, Clef scored 48.6 and Clef-flash 45.8, 14th and 16th of 17 as of 23 October 2026. The Jev Decision Index rates Clef better calibrated than Jev. On the calibration error this site computed from AA’s version 2.1 bins, Jev 1.14 is better: 0.054 against 0.071 for Clef.
What it’s good at
Short typed calls where you want a probability to act on: routing a support request, picking a team, scoring severity, or sending a call to a human when confidence is low. Cloudflare’s example classifies a website’s category from a fetched page. Because it reads images, it can also classify a screenshot or photo.
What it’s not for
It writes no text. Clef-flash scores well below Clef on some tasks, such as CLINC150+OOS (66.77 against 97.43, Cloudflare’s numbers). The latency figures are Cloudflare’s own and do not say how they were measured.
How fast it is
Cloudflare’s 1 October launch post gave a median of 209.3ms for Clef across its 43 evals. On 9 October it said it had made the hosted Clef faster, with changes to the serving layer rather than the weights, including a move to SGLang. Its new table splits latency by input size. The median at about 800 tokens fell from 262ms to 152ms, at about 3,400 tokens from 616ms to 305ms, and at about 16,000 tokens from 2,721ms to 1,635ms. The 95th percentile at about 800 tokens fell from 438ms to 351ms. The two sets of figures use different test inputs, so do not subtract one from the other. Both are Cloudflare’s own runs, and the post does not give hardware, region or network path. The post gave no new Clef-flash figure.
Access today
Both models are live on Workers AI, billed per input token with output free: $0.24 per million input tokens for Clef and $0.038 for Clef-flash on 10 October 2026. Clef-flash cost $0.09 at launch. OpenRouter lists both as cloudflare/clef and cloudflare/clef-flash, served by Cloudflare and by PrimeIntellect at the same prices, and now also by DeepInfra in fp8 for less: $0.192 for Clef and $0.019 for Clef-flash on 12 November 2026. All three providers there give Clef-flash 24,576 tokens of context and Clef about 65,536. The weights are on Hugging Face under Apache 2.0, and Cloudflare also announced a fine-tuning service, hands-on at first and self-serve later. Cloudflare says it does not read, store or train on requests or responses unless you opt into fine-tuning.
Specifications
| System One Score | 82.1 from 3 of 3 boardsArtificial Analysis Decision Index 83.1, Jev Decision Index 74.9, JevBench 88.4. How the score works |
| Inputs | Text, imagesUp to 4 PNG, JPEG or WebP images per request, 4 MiB each. Clef-flash takes the same inputs. |
| Question types | ChoiceScoreNoul |
| Max Choice options | Not documented |
| Score levels | Not documented |
| Questions per call | 64 |
| Total context | 65,536 tokens |
| State budget | Not documented |
| Rate limit | Not published on the Workers AI model pages as of 2026-10-02. |
| Endpoint | POST https://api.cloudflare.com/client/v4/accounts/{account_id}/ai/run/@cf/cloudflare/clef, or env.AI.run("@cf/cloudflare/clef", {...}) from a Worker |
| Licence | Apache-2.0 |
| SDKs |
Workers AI lists a 65,536-token context window for Clef and 24,576 tokens for Clef-flash, checked 2026-11-12; this site recorded 65,536 for both on 2026-10-02. Long text state is truncated to fit; images count toward the window, and a request whose images and questions exceed it fails. A request takes 1 to 64 questions. The optional images array holds up to 4 PNG, JPEG or WebP images, each up to 4 MiB and 16 megapixels, 8 MiB in total, inside a 13 MiB request body. Remote image URLs are not accepted. The docs publish no cap on options per Choice or levels per Score. On OpenRouter, checked 2026-11-12, the Cloudflare and PrimeIntellect endpoints list 65,536 tokens for Clef and 24,576 for Clef-flash, and DeepInfra lists 65,537 and 24,576. On 2026-10-10 the Cloudflare endpoints listed 65,536 for both models and the PrimeIntellect endpoints 16,384.
Versions
- @cf/cloudflare/clef, 1 Oct 2026, The 27B model, built on a frozen Qwen3.8-27B backbone. About 27.4B parameters per Hugging Face. Apache 2.0 weights as Cloudflare/clef. Release notes
- @cf/cloudflare/clef-flash, 1 Oct 2026, The 9B model for latency-sensitive calls, built on a frozen Qwen3.5-9B backbone. About 9.4B parameters per Hugging Face. Apache 2.0 weights as Cloudflare/clef-flash. Release notes
Use cases
What people use Clef for, one page per pattern.
Support inbox triage with System One models
Send a support ticket to Jev once with every question attached. Category comes back as a selected label, severity and frustration as numbers on scales you wrote, refund intent as a probability. Your code reads those values and decides what happens to the ticket.
Intent and model routing with System One models
One Jev call reads an incoming request and returns its intent as a label plus a difficulty rating on a scale you wrote. Your router reads both numbers and picks the handler: deterministic code, a cheap model, an expensive one, or a human queue.
Confidence-gated actions with System One models
Jev returns a confidence value from 0 to 1 alongside every Choice and Score answer. Your code treats it as a separate axis: act automatically when it's high, confirm or flag when it's middling, hand the decision to a person when it's low. Riskier actions get higher bars.
Agent routing and skill selection with System One models
An agent choosing from a long skill roster reads one truncated line per entry and often loads the wrong thing. Jev ranks every entry in one request and separately answers whether any skill applies at all, so the agent gets a short hint instead of a guess.
Examples built with Clef
The most-starred and most-viewed entries in the directory. All Clef examples.
Introducing Clef: our open-source decision models, and new RL fine-tuning platform
Cloudflare's launch post for Clef and Clef-flash, two decision models on Workers AI that accept the Jev request format and open weights under Apache 2.0. It covers the architecture, Cloudflare's own benchmark tables against Jev, Kev and Laya, and a new reinforcement learning service.
 Michelle Chen (@michellechen)140k viewsOpenIntroducing Clef: our open-source decision models, and new RL fine-tuning platform on blog.cloudflare.com
Decision Model Leaderboard
Cloudflare's live leaderboard for decision models on the Jev Decision Index suite, with Clef, Clef-flash, Jev, Kev-9B and Laya plotted by score and latency. Cloudflare built and ran it, so treat the ranking as vendor-run.
 Cloudflare (@ritakozlov)41k viewsOpenDecision Model Leaderboard on clef-evals.workers-ai-mle.workers.dev
Cloudflare/clef: open weights on Hugging Face
Apache 2.0 weights for Cloudflare's 27B Clef decision model, post-trained from Qwen3.8-27B, that reads text and images. The smaller 9B Clef-flash is published next to it as Cloudflare/clef-flash.
Introducing Clairic, a new System One class of extraction models
Cloudflare's launch post for Clairic, a preview extraction model on Workers AI that returns typed values such as spans, numbers, dates, estimates and forecasts with probabilities. It sets out extraction as a second System One class beside decision models and gives Cloudflare's own forecast and claims-pipeline results.
 Cloudflare122k viewsOpenIntroducing Clairic, a new System One class of extraction models on blog.cloudflare.com
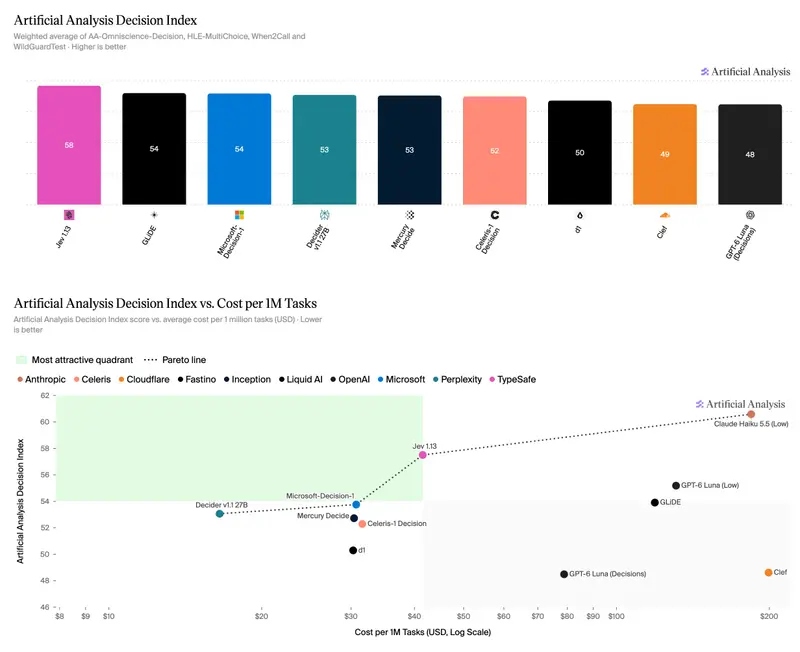
Artificial Analysis Decision Index: 11 hosted decision models against language models
Artificial Analysis scores 11 hosted decision models on knowledge, reasoning, tool-calling and safety tests, with cost and time per task, and runs language models on the same tests. Jev 1.13 led the decision models at launch at 58, and on version 2.1, checked 12 November, Nace.AI's Drex Max v1.1 leads at 72.6; at launch Claude Haiku 5.5 (Low) scores 61 but takes 1.4 seconds per task against 0.13.
 Artificial Analysis (@ArtificialAnlys)45k viewsOpenArtificial Analysis Decision Index: 11 hosted decision models against language models on artificialanalysis.ai
Introducing Clef-omni with full multimodality, plus a faster Clef and a cheaper Clef-flash
Cloudflare's launch post for Clef-omni, a 30B-A3B mixture-of-experts decision model that reads audio, video, images and text, at $0.15 per million input tokens. It also cuts Clef-flash to $0.038 with a 24K hosted context, and gives Cloudflare's own benchmark and latency tables.
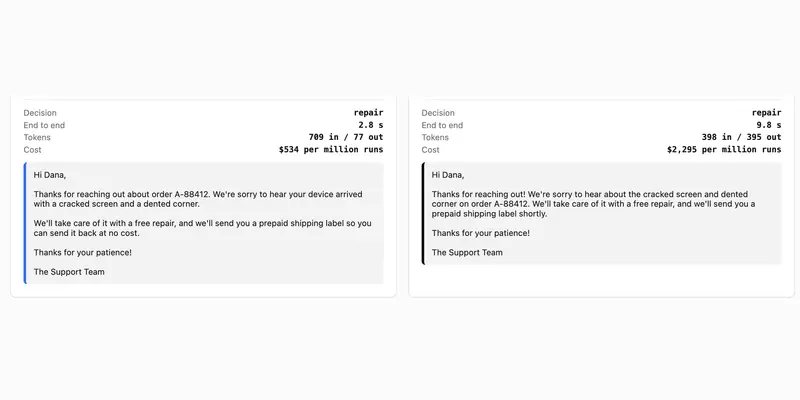
Cascade vs. one LLM: Clairic, Clef and an LLM on Workers AI
Cloudflare's live demo, linked from the Clairic launch post, that sets a cascade of Clairic, Clef and an LLM on Workers AI against a single LLM. Co-author Michelle Chen's X thread says it shows the cascade 3.5x faster and 77% cheaper; the blog's own table gives about 3.2x and 49%. The demo lets you pick the LLM and its reasoning level. All figures are vendor-run.
Benchmarks
Published scores, each linked to its source. A row marked vendor-run was measured by the vendor itself, so read it as one side's result. The compare hub sets these beside the other models.
| Benchmark | Metric | Score | Run by | Date |
|---|---|---|---|---|
| Artificial Analysis Decision Index 2.1 | Index score | 60.3 score | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Expected calibration error | 0.0709 ECE | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Cost per 1M tasks | 863 USD | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Time per task | 354 ms | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Full score | 54.92 score | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Public score | 61.71 score | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Expected calibration error | 0.0395 ECE | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Full score | 44.43 score | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Public score | 56.15 score | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Expected calibration error | 0.0249 ECE | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 1.0 | Index score | 48.6 score | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Expected calibration error | 0.1224 ECE | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Cost per 1M tasks | 199 USD | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Time per task | 309 ms | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Index score | 45.8 score | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Expected calibration error | 0.1205 ECE | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Cost per 1M tasks | 32 USD | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Time per task | 298 ms | Independent | 13 Oct 2026 |
| JevBench 1.8.10 | Capability Score | 75.3 score | Independent | 12 Oct 2026 |
| JevBench 1.8.10 | Capability Score | 63.8 score | Independent | 12 Oct 2026 |
| Jev Decision Index 0.3.1 | Full score | 53.08 score | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Public score | 61.71 score | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Expected calibration error | 0.0395 ECE | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Full score | 47.61 score | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Public score | 56.15 score | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Expected calibration error | 0.0249 ECE | Independent | 10 Oct 2026 |
| BANKING77 | macro-F1 | 94.2 score | vendor-run | 1 Oct 2026 |
| BANKING77 | macro-F1 | 90.93 score | vendor-run | 1 Oct 2026 |
| CLINC150+OOS | macro-F1 | 97.43 score | vendor-run | 1 Oct 2026 |
| CLINC150+OOS | macro-F1 | 66.77 score | vendor-run | 1 Oct 2026 |
- Artificial Analysis Decision Index, Index score: Row: Clef, host Cloudflare. Raw value 60.333. 16th of 19 decision models on version 2.1 on 2026-11-12, and 19th of 22 on 2026-11-14. Sub-scores: When2Call accuracy 71.0, Omniscience accuracy 37.8, HLE-MultiChoice accuracy 10.6. Version 2.1 figures do not compare with version 1.0 figures.
- Artificial Analysis Decision Index, Expected calibration error: Row: Clef. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Clef. AA's measured cost per million tasks on its version 2.1 evals.
- Artificial Analysis Decision Index, Time per task: Row: Clef. Time per task.
- Jev Decision Index, Full score: Row: Cloudflare clef, 104th of 301 rows by this score. Counts 60% private same-skill tests and 40% private new-domain tests; public benchmarks no longer count. 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: Cloudflare clef.
- Jev Decision Index, Expected calibration error: Row: Cloudflare clef. Lower is better.
- Jev Decision Index, Full score: Row: Cloudflare clef-flash, 154th of 301 rows by this score. Counts 60% private same-skill tests and 40% private new-domain tests; public benchmarks no longer count. 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: Cloudflare clef-flash.
- Jev Decision Index, Expected calibration error: Row: Cloudflare clef-flash. Lower is better.
- Artificial Analysis Decision Index, Index score: Row: Clef. Sub-scores: Omniscience accuracy 39.0, non-hallucination 4.3, HLE-MultiChoice 11.1, When2Call 71.0, WildGuardTest F1 90.7.
- Artificial Analysis Decision Index, Expected calibration error: Row: Clef. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Clef. AA's measured cost at list prices on its four evals.
- Artificial Analysis Decision Index, Time per task: Row: Clef. Median time per task.
- Artificial Analysis Decision Index, Index score: Row: Clef-Flash. Sub-scores: Omniscience accuracy 32.6, non-hallucination 2.7, HLE-MultiChoice 10.3, When2Call 64.4, WildGuardTest F1 90.9.
- Artificial Analysis Decision Index, Expected calibration error: Row: Clef-Flash. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Clef-Flash. AA's measured cost at list prices on its four evals.
- Artificial Analysis Decision Index, Time per task: Row: Clef-Flash. Median time per task.
- JevBench, Capability Score: Row: Clef (Cloudflare, Qwen3.8-27B post-train with a joint schema head, multimodal, measured on text). Intelligence 59.1, Calibration 91.6. 48th among open-weights systems by Capability Score. Board release v1.8.10, read 2026-11-15.
- JevBench, Capability Score: Row: Clef-Flash (Cloudflare, Qwen3.5-9B post-train with a joint schema head, multimodal, measured on text). Intelligence 42.2, Calibration 85.5. 110th among open-weights systems by Capability Score. Board release v1.8.10, read 2026-11-15.
- Jev Decision Index, Full score: Row: Cloudflare clef. Counts 20% public benchmarks and 80% private tests; 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: Cloudflare clef.
- Jev Decision Index, Expected calibration error: Row: Cloudflare clef. Lower is better.
- Jev Decision Index, Full score: Row: Cloudflare clef-flash. Counts 20% public benchmarks and 80% private tests; 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: Cloudflare clef-flash.
- Jev Decision Index, Expected calibration error: Row: Cloudflare clef-flash. Lower is better.
- BANKING77, macro-F1: Clef (27B), from Cloudflare's launch post table; Jev scored 79.74.
- BANKING77, macro-F1: Clef-flash (9B), from the same table; Jev scored 79.74.
- CLINC150+OOS, macro-F1: Clef (27B), from Cloudflare's launch post table; Jev scored 89.27.
- CLINC150+OOS, macro-F1: Clef-flash (9B), from the same table; Jev scored 89.27.
Comparisons
Head-to-head pages that put Clef against other models. Every model sits in one table on the compare hub.
Clef vs Clairic: Cloudflare's decision model and its extraction model
Clef picks from options you list. Clairic pulls values out of the input. How Cloudflare's two System One models differ, what they cost, and how to chain them.
Updated
Jev vs Clef: TypeSafe's decision model against Cloudflare's
Clef and Clef-flash are Cloudflare's decision models, hosted on Workers AI with open weights. How they compare with Jev on price, speed and Cloudflare's own benchmarks.
Updated
Microsoft-Decision-1 vs Clef: Microsoft's decision model against Cloudflare's
Microsoft-Decision-1 and Clef-flash are both built on Qwen3.5-9B. How Microsoft's closed model and Cloudflare's open one differ on price, input and outside results.
Updated