Specifications side by side
Read from each model's page, so a change there updates this table. A blank field is dated to the day that model's page was last checked.
| Specification | Jev | pplx-decider |
|---|---|---|
| Vendor | TypeSafe AI | Perplexity |
| Status | Generally available | Generally available |
| Access | Hosted API | Hosted API |
| Question types | Choice, Score, Noul | Choice, Score, Noul |
| Input price | $0.042 per 1M tokens | $0.02 per 1M tokens |
| Output price | Free | Free |
| Total context | 64,000 tokens | 262,144 tokens |
| State budget | 32,000 tokens | Not published as of 14 Nov 2026 |
| Latency | 70 to 500 ms1 | Not published as of 14 Nov 2026 |
| Max Choice options | 255 | 255 |
| Score levels | Up to 10 | Up to 10 |
| Rate limit | Set per organization and shown in the TypeSafe developer console. TypeSafe publishes no fixed figures, checked on 2026-11-14. Going over the token or request limit returns HTTP 429, and higher limits are available on custom and enterprise plans. | 10 requests per second per organization by default, shared by all four models. Token limits are per model: 15,000,000 a minute and 900,000,000 an hour for pplx-decider-v1.3 and pplx-decider-v1.2, and 4,000,000 a minute and 240,000,000 an hour for each Flash model. Going over returns HTTP 429 with a Retry-After header. Checked 2026-11-14. |
| SDKs | Python, TypeScript | Python, TypeScript |
| Licence | Not published as of 14 Nov 2026 | Apache-2.0 |
| Jev Decision Index, Full score | 60.24 scorev0.4.1, 12 Nov 2026 | 67.67 scorev0.4.1, 12 Nov 2026 |
| Jev Decision Index, Public score | 60.7 scorev0.4.1, 12 Nov 2026 | 67.74 scorevendor-runv0.4.1, 12 Nov 2026 |
| Jev Decision Index, Expected calibration error | 0.0799 ECEv0.4.1, 12 Nov 2026 | 0.0421 ECEv0.4.1, 12 Nov 2026 |
| JevBench, Capability Score | 75 scorev1.8.10, 16 Oct 2026 | 80.8 scorev1.8.10, 20 Oct 2026 |
| Microsoft 36-benchmark comparison, Average accuracy | 82.3 %vendor-run9 Oct 2026 | Not published as of 14 Nov 2026 |
| Microsoft 36-benchmark comparison, Calibration score | 93.7 scorevendor-run9 Oct 2026 | Not published as of 14 Nov 2026 |
| Artificial Analysis Decision Index, Index score | 66.2 scorev2.1, 12 Nov 2026 | 70.4 scorev2.1, 14 Nov 2026 |
| Artificial Analysis Decision Index, Expected calibration error | 0.0536 ECEv2.1, 12 Nov 2026 | 0.0643 ECEv2.1, 14 Nov 2026 |
| Artificial Analysis Decision Index, Cost per 1M tasks | 156 USDv2.1, 12 Nov 2026 | 68 USDv2.1, 14 Nov 2026 |
| Artificial Analysis Decision Index, Time per task | 92 msv2.1, 12 Nov 2026 | 289 msv2.1, 14 Nov 2026 |
| Jev Decision Index, Overall Decision Index | Not published as of 14 Nov 2026 | 68.09 scorevendor-runv0.3, 16 Oct 2026 |
| Docs and console | docs.typesafe.ai, Console | docs.perplexity.ai |
- 1 Jev: 70ms to 500ms end-to-end is TypeSafe's own figure from the launch post, as is the 3 to 329 seconds it compares frontier LLMs against and the resulting 40x to 200x multiple.
Examples in the directory
638 Jev examples
The top 3 by stars and views. All Jev examples.
Jev Ultrafast (Browser Use)
Browser Use's fast browser agent where Jev picks the operation and the DOM element in a single request; a small LLM is only invoked to write text when typing is required. Demoed on a Google Flights search.

19k starsFlight search 7.1 s
openjev
Attempt to run a Jev-style System One decision model locally on a single RTX 3090. Companion site at openjev.com. The repository was renamed to TheoLeeCJ/SemIf on GitHub, and the old openjev URL now redirects to it.
 TheoLeeCJOpenopenjev on github.com
4.1k starsJSON vs direct 5.21x slowerPeak throughput 20.03 dec/s
jev-trader
Makes one AI trade decision every Monad block on the Kuru MON-USDC market using Jev. The public deployment runs in dry-run mode with a mock model.
 jarrodwattsOpenjev-trader on github.com
2.2k starsLoop, mock model p50 100 msDecision window ~300 ms/block
1 pplx-decider example
The top 1 by stars and views. All pplx-decider examples.
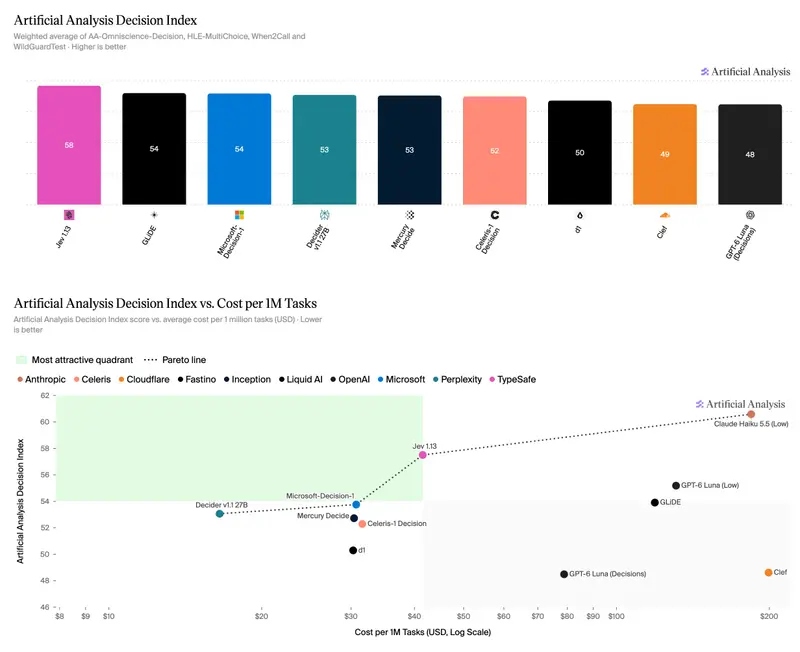
Artificial Analysis Decision Index: 11 hosted decision models against language models
Artificial Analysis scores 11 hosted decision models on knowledge, reasoning, tool-calling and safety tests, with cost and time per task, and runs language models on the same tests. Jev 1.13 led the decision models at launch at 58, and on version 2.1, checked 12 November, Nace.AI's Drex Max v1.1 leads at 72.6; at launch Claude Haiku 5.5 (Low) scores 61 but takes 1.4 seconds per task against 0.13.
 Artificial Analysis (@ArtificialAnlys)45k viewsOpenArtificial Analysis Decision Index: 11 hosted decision models against language models on artificialanalysis.ai
Shared use cases
Patterns both Jev and pplx-decider list on their pages.
The short answer
pplx-decider is a decision model from Perplexity. Like Jev, it reads one state and answers typed Noul, Choice and Score questions with probabilities. It differs in four ways. It reads images in the normal request body, while Jev reads them only behind an opt-in header. It accepts 262,144 input tokens per request, it allows 255 options on a Choice and sets no general cap on questions per call, and its weights are open under Apache 2.0. It is also cheaper, at $0.02 per million input tokens against $0.042 for Jev, and Perplexity’s smaller Flash model costs $0.01.
It is not a drop-in swap. It has its own endpoint and request format, so code written for Jev needs changes and TypeSafe’s SDKs do not work with it. Jev has the longer record, the SDKs and a wire format that several other vendors accept. The best outside comparison so far is the Jev Decision Index, multimodalart’s community board on Hugging Face. On edition 0.2.1, checked 2 October 2026, Jev scored 57.91 and pplx-decider v1 56.40. The 0.3.1 file, generated 10 October 2026, put v1.1 first at 62.75 against Jev’s 60.11, on a new Full score that added private tests. Edition 0.4.1, generated 22 October 2026, lists v1.2 instead, at 67.98 against Jev 1.14’s 60.24, on a Full score built only from private tests. The file generated on 12 November 2026 adds the current v1.3, at 67.67.
Jev vs pplx-decider at a glance
| Jev | pplx-decider | |
|---|---|---|
| Maker | TypeSafe AI | Perplexity |
| Model and base | jev-1.14.0, with jev-1.13.0 still served; base not published |
pplx-decider-v1.3, fine-tuned from Qwen3.8-27B; pplx-decider-flash-v1.3 (4B, from Qwen3.5-4B) also offered; v1.2 and Flash v1.2 still served by name; v1.1 and v1 names answered by v1.2 |
| Weights | Closed, API only | Apache 2.0 on Hugging Face, not gated |
| Endpoint | POST /v1/systemone |
POST /v1/decisions |
| Question types | Choice, Score, Noul | Choice, Score, Noul; locate text spans on v1.3 |
| Input | Text; PNG and JPEG images behind the opt-in TypeSafe-Danger-Zone-Images header |
Text, JSON and base64 images |
| Context | 64,000 tokens per request, 32,000 for state plus the longest question; both 262k with the opt-in long-context header | Under 256K (262,144) input tokens for the state plus each question, 32 MiB body |
| Options per Choice | 255 | 255 |
| Levels per Score | 10 | 10 |
| Questions per call | Not documented | No general cap; at most 100 with web grounding and 128 with a locate question |
| Input price per million tokens | $0.042, output free | $0.02, output free; $0.01 for Flash |
| Rate limit | Set per organization and shown in the developer console, as of 14 November 2026 | 10 requests per second per organization, shared by all four models, plus per-model token limits |
| SDKs | Python and TypeScript | Python (perplexityai 0.44.0 or later) and TypeScript, with a decisions.create method |
| Latency as published | 70ms to 500ms end to end, TypeSafe’s claim | 16 seconds for about 243,000 input tokens on v1.3 and 5 seconds on Flash v1.3, Perplexity’s figures |
| Status | Generally available since 15 September 2026 | Generally available since 1 October 2026 |
Sources: TypeSafe’s models page and SDK docs, Perplexity’s quickstart and the model card, checked 2 October 2026. The pplx-decider model, question type, context, questions, price, rate-limit, SDK and latency rows were rechecked against Perplexity’s quickstart, API reference and changelog on 14 November 2026.
What each model does
Both models take a state and a set of named questions and return a probability for each answer. Neither writes text. Choice, Score and Noul covers the three question types, and pplx-decider uses the same three. In pplx-decider a Noul returns the probability of yes, a Choice returns one probability per option, and a Score returns a probability-weighted average level.
The request differs. Perplexity’s body has model, state and questions, as Jev’s does, but it goes to https://api.perplexity.ai/v1/decisions, the answers come back under an answers object, and the key goes in an Authorization: Bearer header. Images go in the state array as base64 PNG, JPEG or WebP data URLs, up to 2,048 tiles of 32 by 32 pixels each. The API never fetches image URLs.
Jev’s /v1/systemone format is also used by Solar Decide, d1, Decider 1 and several open projects, and Clef takes the same fields, as Jev alternatives lists. pplx-decider is not on that list. Moving code means changing the endpoint, the response parsing and the model name, and dropping the TypeSafe client.
What the benchmarks show
Perplexity did not publish a head-to-head test against Jev under shared conditions. Three sources give numbers, and they are not directly comparable with each other.
Perplexity’s model cards. The v1 card reports 85.71% across 11 benchmarks for pplx-decider against 74.76% for the base Qwen3.8-27B, and says it measured pplx-decider through its own API. Its table also has a Jev column, at 84.51% overall, and does not say how those Jev figures were obtained. Jev is higher on six of the 11 rows, among them WinoGrande (90.70% against 83.30%) and BBH (94.27% against 82.80%). pplx-decider is higher on the other five, among them RAGTruth (88.80% against 77.27%) and Circa (89.20% against 84.60%). This is a vendor-run table. The v1.1 card reports a Jev Decision Index score of 61.56 for v1.1, against 56.4 for v1 and 57.9 for Jev, with v1.1 ahead of Jev in every area but Knowledge (48.18 against 51.4). That is also vendor-run.
The Jev Decision Index. The Jev Decision Index is a third-party board with one suite and one set of rules for every entry. Edition 0.2.1, checked on 2 October 2026, listed pplx-decider-v1-27b with a headline score of 56.40 against 57.91 for Jev 1.13, fourth of the 71 rows. Its calibration error, the average gap between stated confidence and how often the model is right, was 0.018 against Jev’s 0.074, and lower is better.
Edition 0.3, on 7 October 2026, dropped v1 and scored v1.1; the figures here are from the 0.3.1 file generated on 10 October 2026, which left the text scores unchanged. It also changed the headline. The 0.2.1 score used the public benchmarks only. The 0.3 Full score takes 20% from public benchmarks, 50% from private tests of the same skills and 30% from private tasks in new domains, so the two editions’ numbers do not compare. On 0.3, v1.1 was first of 117 rows in the 10 October 2026 file (edition 0.3.1), at 62.75, and Jev shared second place at 60.11. On the public benchmarks alone, v1.1 scored 62.25 and Jev 57.96. Calibration error is measured the same way in every edition, and v1.1’s was 0.071 against Jev’s 0.074, so its edge over Jev on calibration was much smaller than v1’s.
Edition 0.4, on 19 October 2026, rebuilt the Full score from private tests alone: 60% on the same skills and 40% in new domains. In edition 0.4.1, generated on 22 October 2026, the board has replaced v1.1 with Perplexity Decider v1.2 (27B). v1.2 scores 67.98, fourth of 229 rows, against 60.24 for Jev 1.14, which is 41st. In the 12 November file, with 301 rows, the same scores are 26th and 67th. On the public benchmarks alone v1.2 scores 67.74 and Jev 1.14 60.7, and their calibration errors are 0.055 and 0.080. Perplexity declared that v1.2 trained on the official training splits of several Index benchmarks. The file generated on 12 November 2026, checked on 14 November, adds the current v1.3 at 67.67, 29th of 301 rows and a little below v1.2’s 67.98. Its calibration error is 0.042, against 0.080 for Jev 1.14. The Index is one person’s suite, and its note says the board’s Jev latency is a hosted-API round trip that is not comparable with the on-card figures of the open models.
The same task, two setups. RAGTruth is on the v1 card and on the Index, and the two give different numbers for the same model. The card has pplx-decider v1 at 88.80% and Jev at 77.27%. The Index 0.2.1 has them at 80.34 and 76.53, and Index 0.3 has v1.1 at 83.14 against the same 76.53 for Jev. The setups, metrics and who ran them differ, so do not read one gap against the other.
Perplexity’s own calibration figures cover v1.2 only. Its v1.2 card gives an error of 0.014 on a 1,497-question development set, and about 0.05 on decision data held out from all training, where it says the model is still somewhat over-confident. Those are vendor-run. The v1.3 and Flash v1.3 cards, checked on 14 November 2026, give no error figure and tell you to calibrate on a sample of your own traffic. The 0.018, 0.071, 0.055 and 0.042 above come from the Index. Neither vendor’s numbers have been reproduced on your data, so run both on a sample of it.
Speed, cost and hosting
Perplexity gives times by input size, from its own tests on 30 September 2026: under 2 seconds for a few hundred input tokens, about 5 seconds at roughly 90,000, about 14 at roughly 190,000 and about 23 just under the limit. Its tests on 12 November 2026 put v1.3 at 16 seconds and Flash v1.3 at 5 seconds for about 243,000 input tokens. It publishes no median or percentile. TypeSafe’s own figure for Jev is 70ms to 500ms end to end, also unverified by a third party. The two sets of numbers use different measures, so they cannot be set against each other. Time both from your own region with your own state sizes.
pplx-decider is cheaper: $0.02 against $0.042 per million input tokens, with output free on both. Perplexity cut the price from $0.04 when v1.1 shipped, and requests that still name v1 bill at the new rate. v1.3 kept those prices. OpenRouter lists perplexity/pplx-decider-v1.2 at $0.02 and perplexity/pplx-decider-flash-v1.2 at $0.01, as of 14 November 2026. Its v1.3 listings showed no active endpoint that day. Perplexity publishes a rate limit of 10 requests per second per organization. TypeSafe sets Jev’s limits per organization and shows them only in its developer console.
Because the pplx-decider weights are Apache 2.0, you can run the model yourself. The v1.3 model card says that takes Python 3.12 or newer and a CUDA GPU with room for about 49 GiB of weights plus working memory, or about 8.5 GiB for Flash v1.3. Jev has no downloadable weights.
When to use which
- You send very long states. pplx-decider takes 262,144 input tokens. Jev’s state limit is 32,000 by default, or 262k with an opt-in header that TypeSafe says makes answers slower and less accurate.
- You classify images. pplx-decider reads them with no opt-in. Jev reads PNG and JPEG only behind an opt-in header, and TypeSafe says that feature is not yet ready for production.
- You ask many questions about one state. pplx-decider sets no general cap per call as of 14 November 2026, and the 27B v1.3 bills the state once per request. Jev does not document a limit, so check it before you rely on a large batch.
- You want weights you control. Only pplx-decider offers them, under Apache 2.0.
- You want the lowest price. pplx-decider costs less than half of Jev’s rate per input token.
- You need independent results. On Jev Decision Index 0.4.1, v1.3 scores above Jev 1.14, 67.67 against 60.24. The Artificial Analysis Decision Index agrees on version 2.1: v1.3 scores 70.4, sixth of 22, against Jev 1.14’s 66.2, as of 14 November 2026. Jev has the longer public record.
- You already use TypeSafe’s SDKs or the
/v1/systemoneformat. Stay on Jev. Several other vendors accept that format, so you keep a way out. - You need a known request rate before you sign up. Perplexity publishes 10 requests per second per organization. TypeSafe shows each organization’s limits only in its console, and offers higher limits on custom and enterprise plans.
See Jev alternatives for the other options.
FAQ
Is pplx-decider a Jev alternative?
Yes, for the job. Both answer typed Noul, Choice and Score questions with probabilities about one state. It is not a drop-in swap, because it uses Perplexity’s /v1/decisions endpoint and its own response shape. Moving means changing the endpoint, the model name and the parsing, and rerunning your own evals.
Is pplx-decider better than Jev?
The two outside boards agree. Jev Decision Index 0.4.1 gives the current v1.3 a Full score of 67.67 against Jev 1.14’s 60.24, with calibration errors of 0.042 and 0.080. The Artificial Analysis Decision Index version 2.1 also has v1.3 ahead, 70.4 against 66.2 for Jev 1.14, as of 14 November 2026. pplx-decider also has the larger default context, standard image input and open weights. Test both on your own data.
Does pplx-decider read images?
Yes. You put base64 PNG, JPEG or WebP data URLs in the state array, up to 2,048 tiles of 32 by 32 pixels each. Jev takes PNG and JPEG only behind an opt-in header, which TypeSafe says is not production-ready. Perplexity’s own v1.2 card reports 77.43 on the public vision Index. The Jev Decision Index’s vision board (edition 0.3.1, 9 October 2026) placed v1.1 first of 21 rows at 70.58.
Is pplx-decider free or open source?
The weights are free under Apache 2.0 on Hugging Face and are not gated. Perplexity’s hosted Decisions API is not free. It costs $0.02 per million input tokens for v1.3 and $0.01 for Flash v1.3 as of 14 November 2026, with output free. Running the v1.3 weights yourself needs a CUDA GPU with about 49 GiB for the weights plus working memory.
Can I use TypeSafe’s SDKs with pplx-decider?
No. TypeSafe’s Python and TypeScript SDKs call /v1/systemone, and pplx-decider answers at /v1/decisions with a different response shape. Perplexity’s own Python and TypeScript SDKs now have a decisions.create method, but they call Perplexity’s endpoint. Changing the base URL alone will not work.
Examples
Jev Decision Index: Jev against 50+ open decision models
A leaderboard that runs Jev and 54 open System One models and clones through the same 120,000-question suite on one RTX PRO 6000, scoring accuracy and calibration. Jev leads the 0.2 edition at 51.67 on a chance-corrected scale, with AutoJev-27B close behind at 50.94.
 apolinario (poli) (@multimodalart)43k viewsOpenJev Decision Index: Jev against 50+ open decision models on huggingface.co