Skip to content
System One

Jev for documents, OCR and data extraction: 8 projects

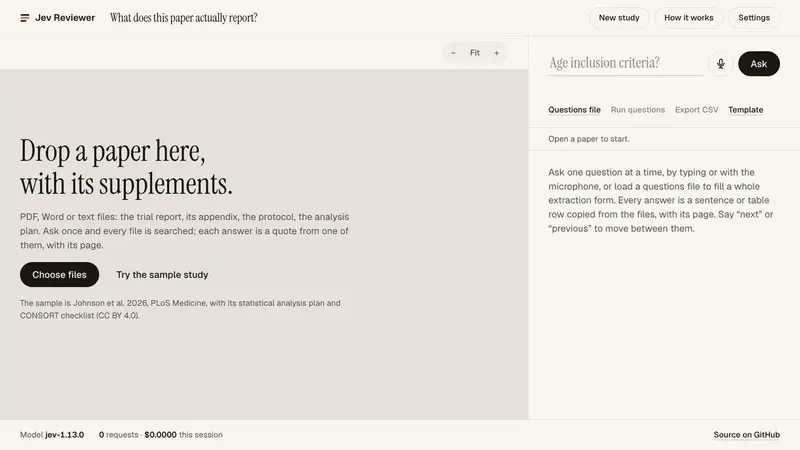
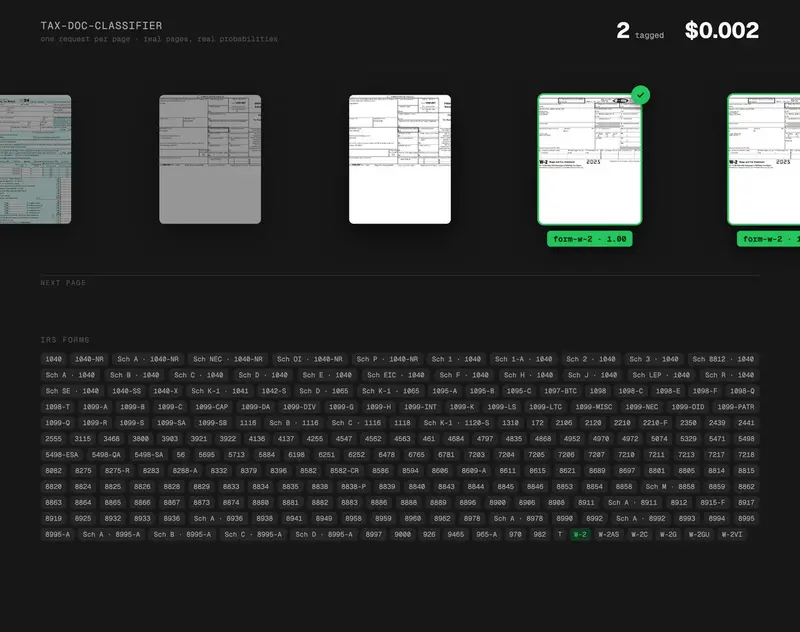
Documents arrive as PDFs, scans, notes and messy text. The job is to turn them into fields your code can use: a form type, a date, a yes or no for each question in a template. A decision model does this by answering typed questions about the document, one field at a time, instead of writing JSON that may or may not parse. Every answer has a type and a confidence value. The examples in this hub run on Jev and other decision models, and Laya appears in some. Examples include kyotofin/tax-doc-classifier, which picks an IRS form for each PDF page, Jev Reviewer by Ahmad Sofi-Mahmudi, which answers extraction forms for systematic reviews, and gtaras7/typesafe-jev, a local CV screening workbench. Before you copy one, check what happens to the document text, how long a document can be, how dates and numbers are handled, and whether a person reviews the low-confidence fields. Most entries are small, so you can read the whole flow before you adopt it.

8 entries

All entries

Showing 8 of 8

How decision models are used for documents and extraction

The loop is: split the document into pages or sections, ask a fixed set of typed questions for each, and let code assemble the record. gtaras7/typesafe-jev asks a small fixed set of questions about each CV and scores the answers with arithmetic you can read. kyotofin/tax-doc-classifier sends each PDF page's text as one choice over 261 IRS forms and 7 page kinds.

Choice fits picking a type from a list. Noul fits yes or no template questions. Score is rare here. The TypeSafe AI cookbooks on structure recovery from plain text and on date extraction show the pattern, and the date entry notes it pre-parses the text to work around the model's weakness at date arithmetic. Run your own sample before you trust a pattern.

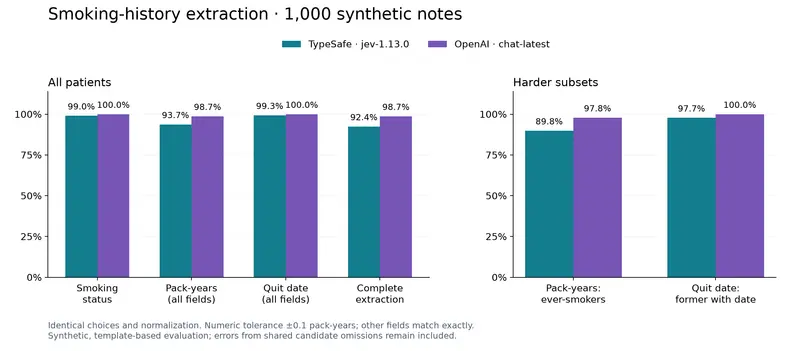
Free text is the limit. A decision model picks among options you supply, so it does not copy a long passage out on its own. vclic/smoking-extraction-benchmark compares Jev with OpenAI structured outputs on synthetic outpatient notes, with both given the same candidate values and questions. Plan to supply the candidates. Candidates can come from a form template, a list of known values or an earlier extraction step.

FAQ

Can Jev extract data from PDFs and invoices?

It can classify pages and answer typed questions about a document's text, as kyotofin/tax-doc-classifier and Jev Reviewer do. It picks from options you supply, so you give it the candidate values or fields. OCR and layout reading happen before it.

Is a decision model better than structured outputs from an LLM?

It returns typed answers with a confidence value, which makes review easy. An LLM can copy free text out of a document, which a decision model does not. vclic/smoking-extraction-benchmark compares the two on one task.

Can Jev decide which pages need OCR?

Yes. The page-by-page OCR router by Misbah Syed uses Jev to decide which PDF pages need OCR and extracts the rest locally.