Skip to content
System One

Jev evals, benchmarks and LLM judging: 64 entries

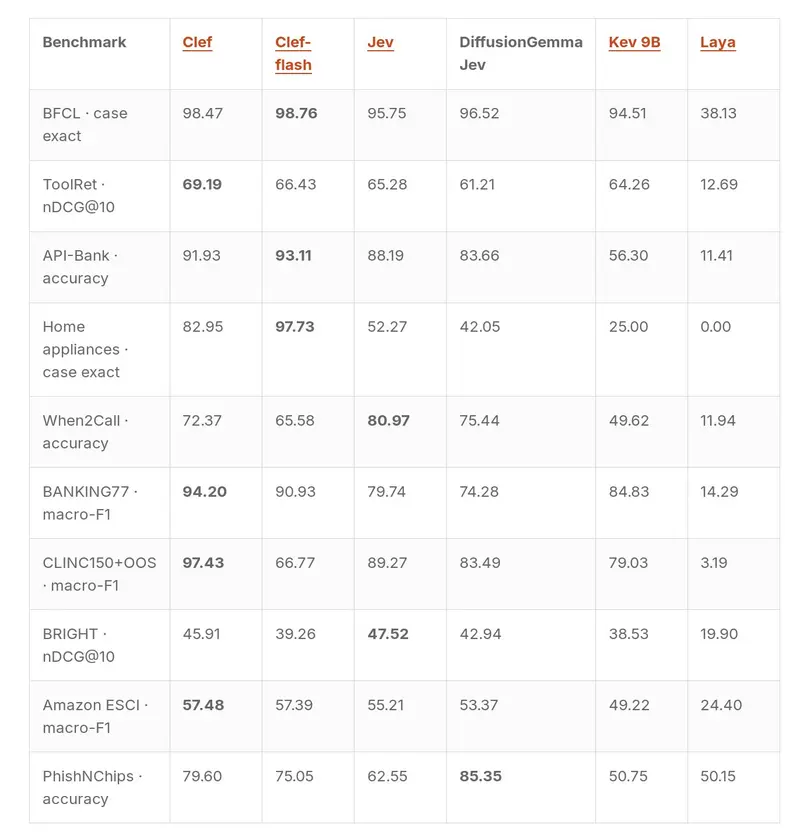
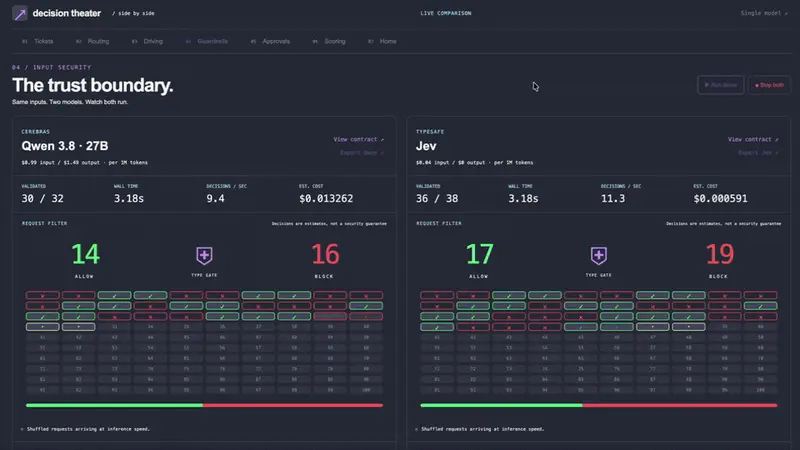
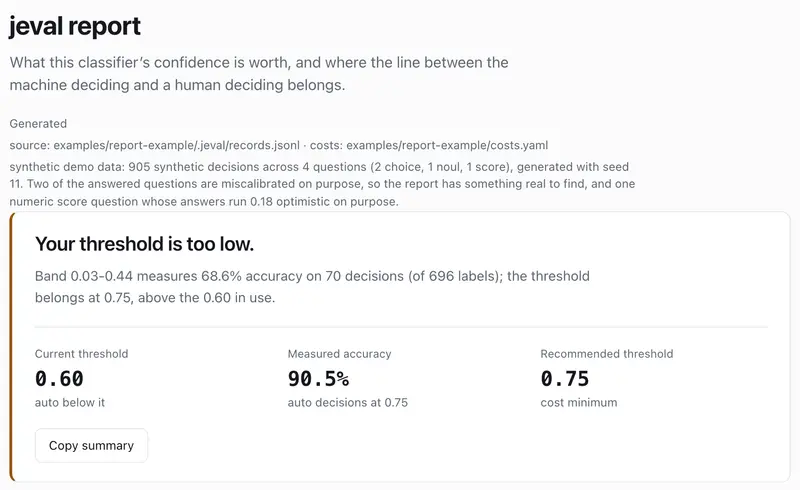
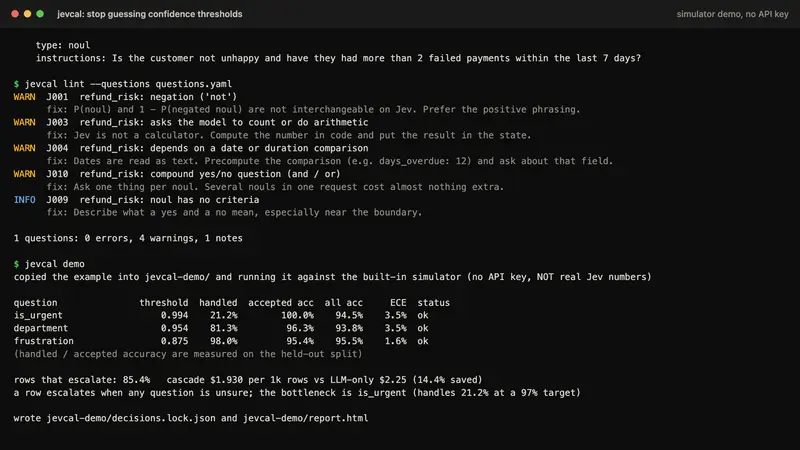
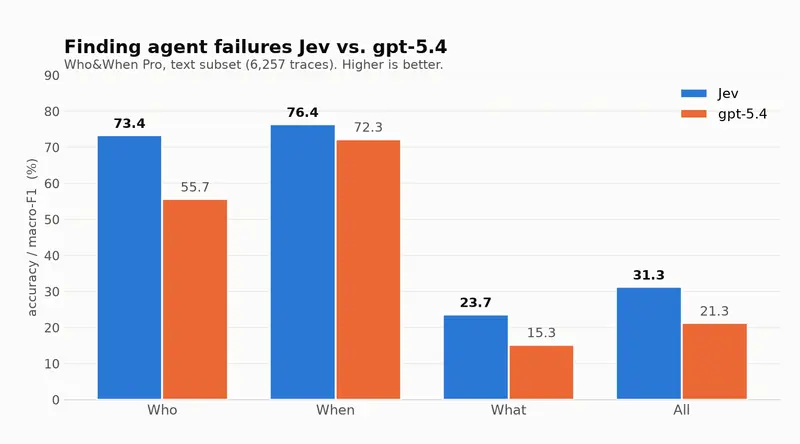
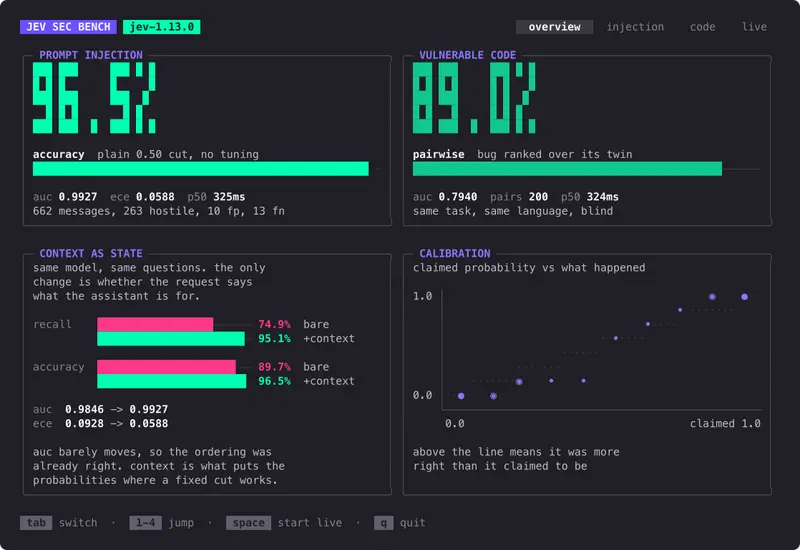
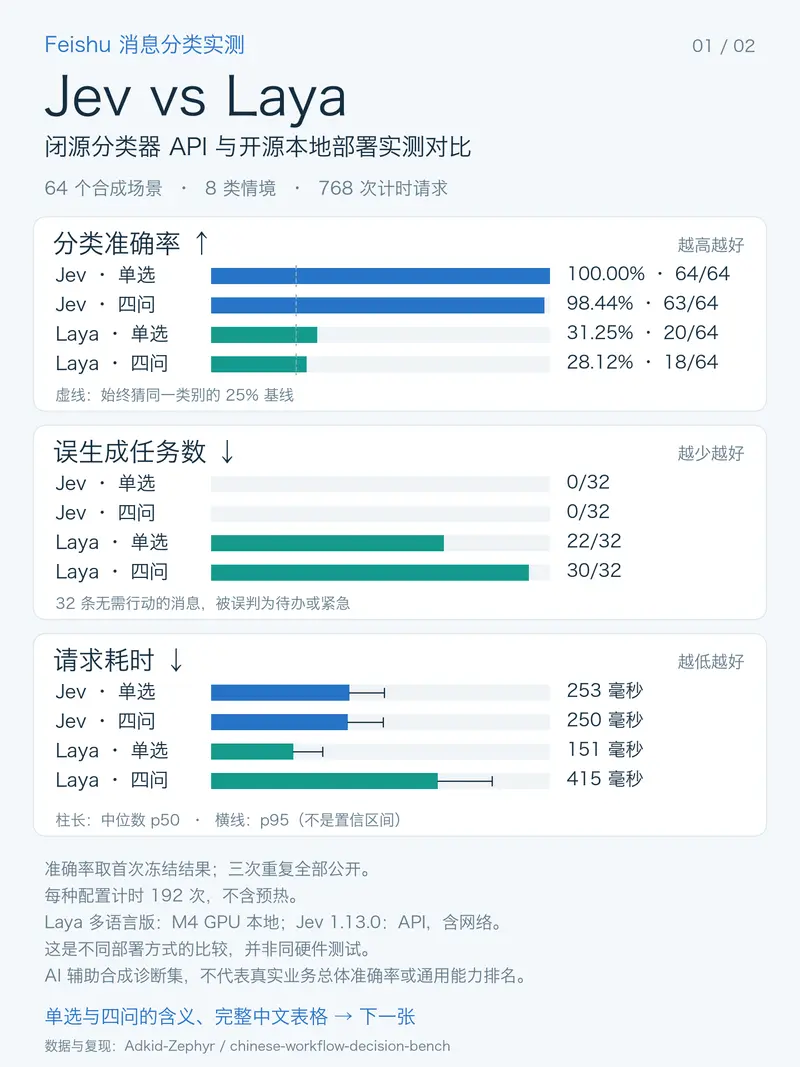
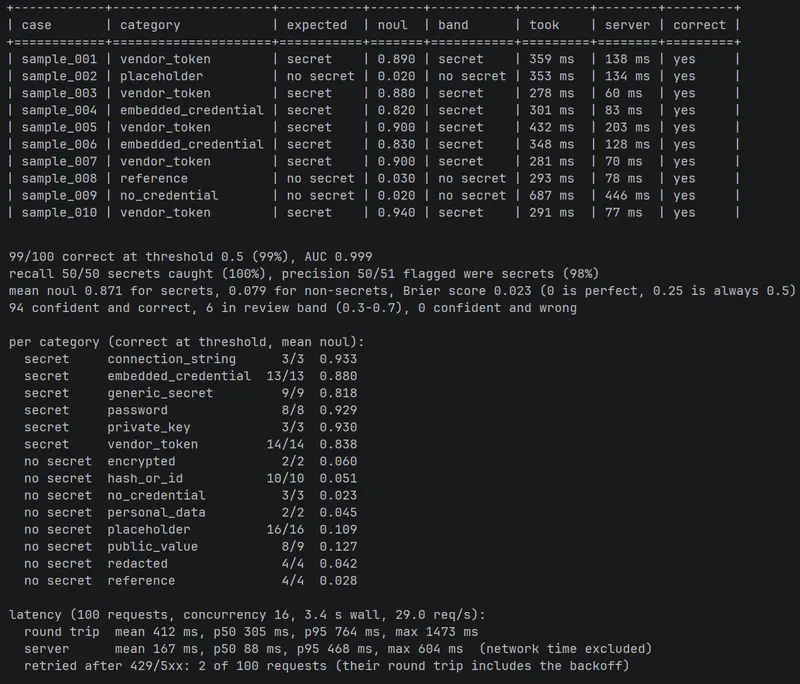
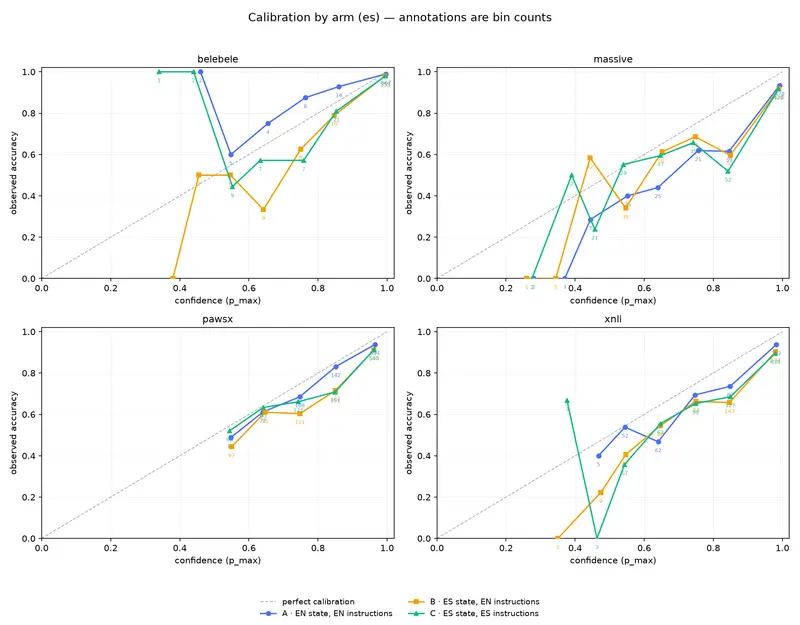
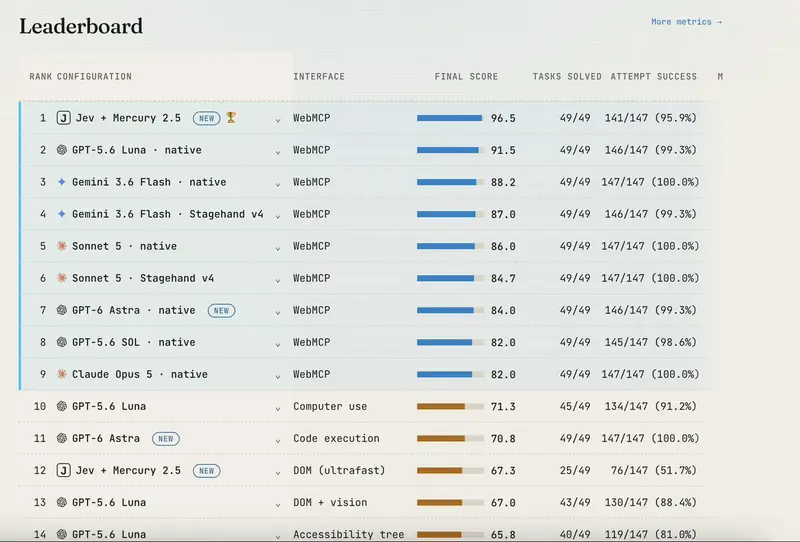
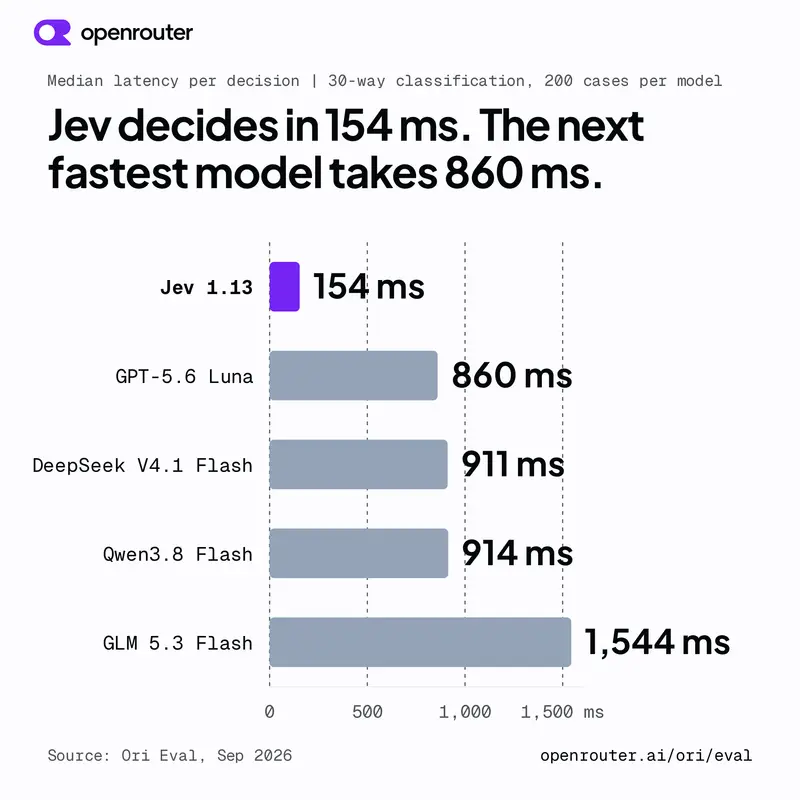
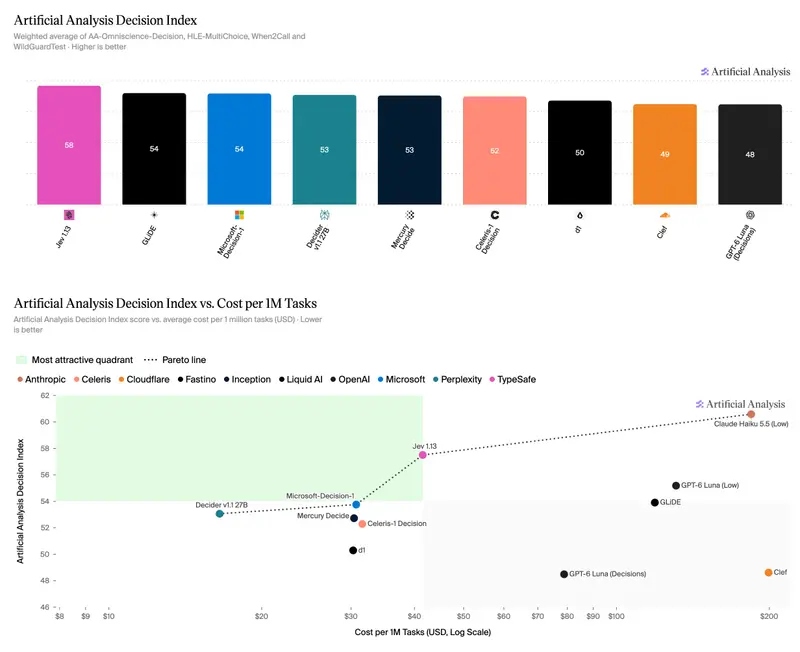
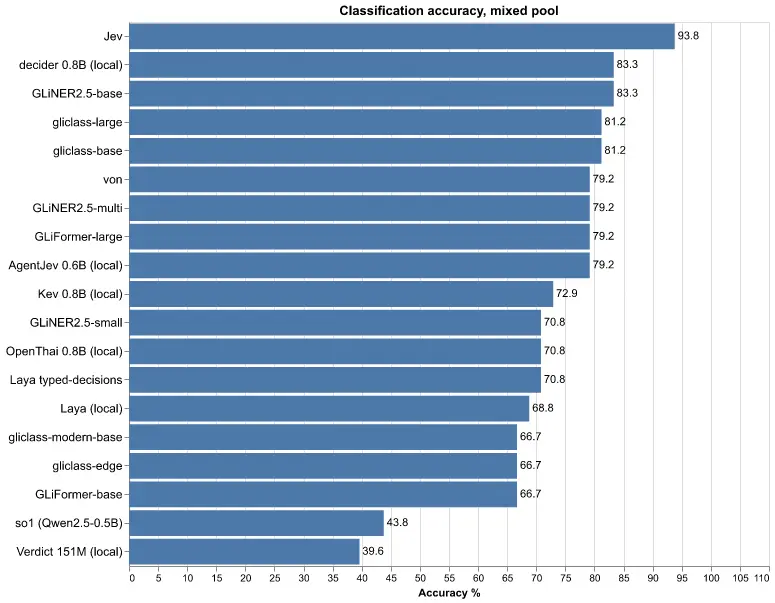
Two kinds of work sit here. One tests decision models, with benchmarks that measure accuracy and calibration, meaning whether a stated confidence matches how often the answer is right. The other uses a decision model as a judge that grades text, agent actions or other model output. A judge built on a decision model returns a typed score or choice, so a test suite can compare numbers instead of reading verdicts. The entries in this hub run on Jev and other decision models, and Laya appears in several. Examples include the Jev Decision Index leaderboard, which runs many open decision models through one question suite, abhixhek/jevcal, which fits a confidence threshold to your own labeled data, and DanRWilloughby/snifftest, a prose linter. Before you trust a benchmark, check who ran it, what data it used, whether the raw outputs are published, and whether the author sells one of the models. Treat any leaderboard as one view, and look for the method before the ranking.

64 entries

All entries

Showing 1 to 48 of 64

How decision models are used for evals and judging

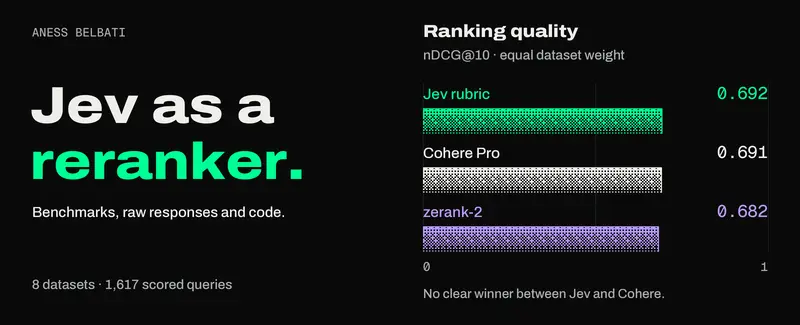
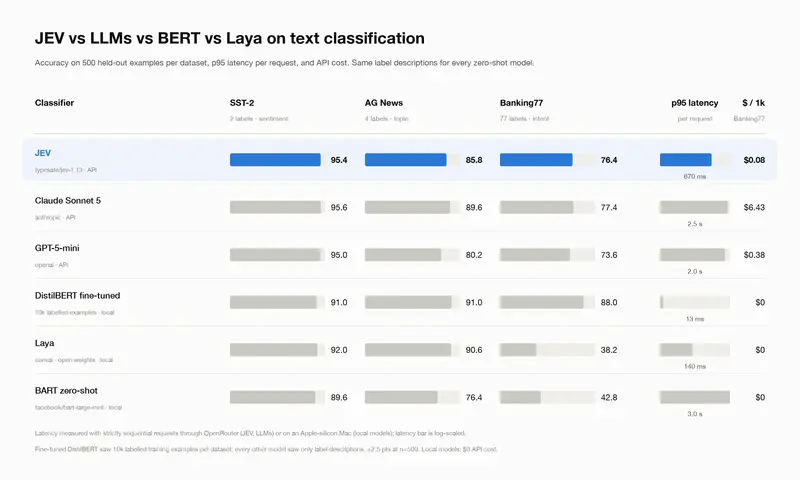
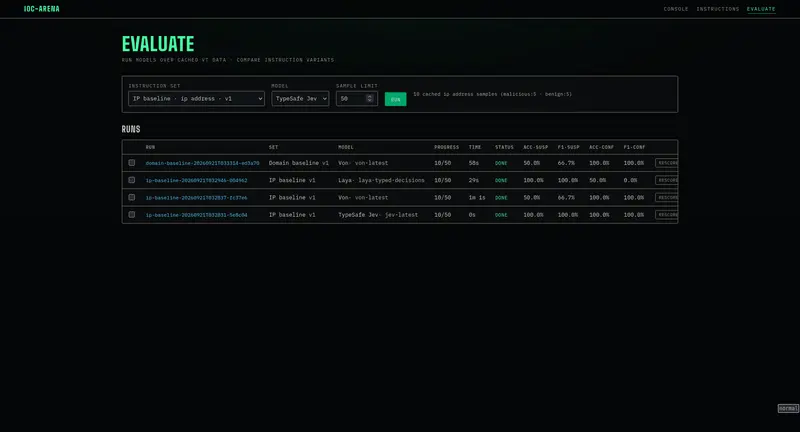
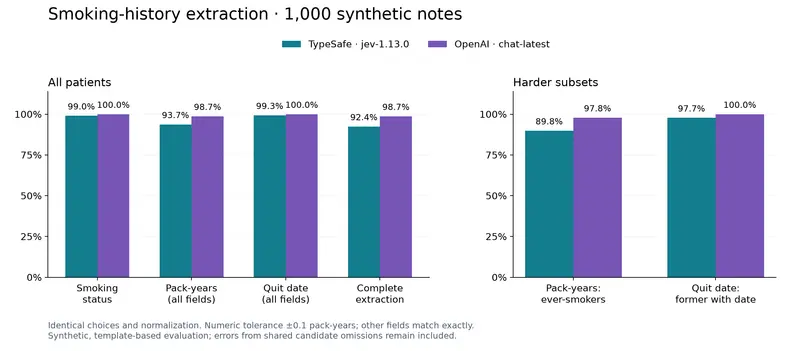
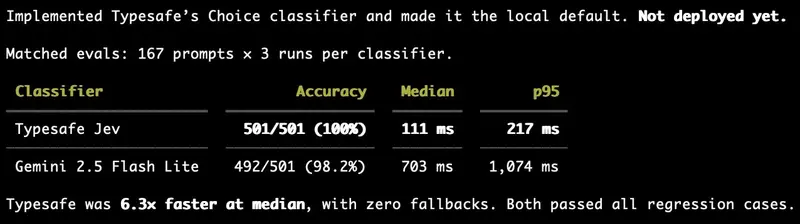
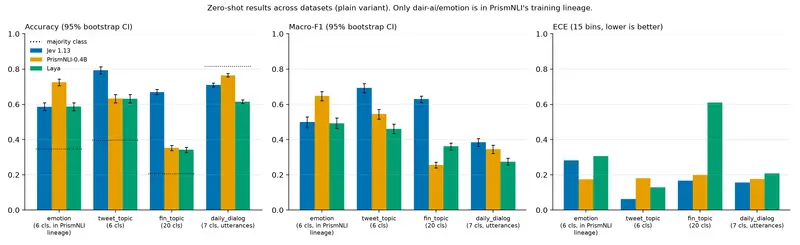
Benchmark entries follow one pattern. Pick a labeled set, ask every model the same questions, and report accuracy and calibration. anisselbd/jev-phishing-bench compares Jev with Claude Haiku 4.5 on phishing emails, and bitnovus/jev-spam-eval asks how far written category definitions get you before you need training data. Some entries publish the raw responses so you can rerun them. Compare their questions before you compare their results.

Judging entries use score for quality, choice for pairwise picks and noul for pass or fail checks. AI Elo Ranker by opaielsheikh uses pairwise Jev judgments with Elo ratings and Swiss matchmaking to rank texts. hobbs/jev-turn-analysis scores finished Claude Code and Codex sessions and suggests changes to agent instructions. In both cases the output is a typed value, so a test suite can compare it against a threshold or a baseline run.

Watch the limits. Small test sets and synthetic data can flatter a model, and a model that leads on one task can trail on another. The ikkun article compares one direct Jev call per row with many separately scored dimensions on three tasks. Question design matters as much as model choice. Vendor-run numbers should be read as the vendor's own.
FAQ

Can a decision model act as an LLM judge?

Yes. Entries such as openlayer-ai/jevals and AI Elo Ranker use a decision model to grade output and rank texts. The judgment comes back as a typed score or choice with a confidence value, so tests can compare it directly.
How do I check that a decision model is calibrated?

Run it on labeled data of your own and compare stated confidence with how often it is right. abhixhek/jevcal fits a confidence threshold to your accuracy target and checks it on a held-out split.

Where can I compare decision models?

The Jev Decision Index and the Cloudflare Decision Model Leaderboard both run several decision models through shared question suites. Check who built each suite and read the method before relying on a ranking.