What pplx-decider is
pplx-decider is Perplexity’s System One model. The first version, pplx-decider-v1-27b, launched on 1 October 2026 with the Decisions API, and v1.1 replaced it in the first week of October. On 16 October Perplexity released v1.2 in two sizes, 27B and a 4B Flash model. On 12 November it released v1.3 in the same two sizes: pplx-decider-v1.3, the 27B default, and pplx-decider-flash-v1.3, a 4B model distilled from it. Perplexity describes them as decision models that return probabilities over a fixed set of answers instead of text. You send a state and any number of named questions in one call.
v1.3 changes how questions share a request. v1.2 reads the state and every question in one sequence, so each question sees the others and the grouping can change the answers. v1.3 still answers every question in one pass, but each question sees only the state and itself. Perplexity says this keeps results more stable, though questions can still affect each other a little through the shared state. v1.3 also adds locate questions, which find matching text in the state and return each span with its character offsets and a score. That is extraction, not a choice from listed options.
It is listed as commercial because Perplexity’s own generally available API is the main way to use it. The weights of every version are also on Hugging Face under Apache 2.0, ungated. v1.3 is on a Qwen3.8-27B base with 26.1 billion parameters per Hugging Face, and Flash v1.3 on Qwen3.5-4B with 4.5 billion.
What it returns
The request is POST https://api.perplexity.ai/v1/decisions with model set to pplx-decider-v1.3 or pplx-decider-flash-v1.3, or to the aliases pplx-decider-latest and pplx-decider-flash-latest, which select them. pplx-decider-v1.2 and pplx-decider-flash-v1.2 are still served by name, and requests that name v1.1 or v1 are answered by v1.2. A Noul returns a yes probability from 0 to 1. A Choice takes 1 to 255 options and returns a probability for each. A Score takes up to 10 ordered levels and returns a probability-weighted average. A locate question, on v1.3 only, returns a list of spans and needs a plain-text state. The state can be text, JSON, or a list that includes base64 images. The response is JSON, and output tokens are not billed.
What it is good at
Perplexity’s docs include a support-ticket triage example, which maps to support inbox triage. Routing a request to a model or tool fits intent and model routing. The v1.2 model card reports 88.80 on RAGTruth, a test of whether an answer is supported by its sources, which is closest to citation verification. The context window is 256K tokens, much larger than most hosted rivals, and it accepts images.
Perplexity’s blog post of 12 November reports its own tests of v1.3. On one million real Decisions API requests, scored against answers from frontier LLM judges, v1.3 agreed with the judges on 93.98% of questions, against 93.68% for v1.2 and 93.35% for Jev 1.14. On 17 extraction tasks, locate averaged 69.0 for v1.3 and 63.6 for Flash v1.3, against 41.5 for Cloudflare’s Clairic and 43.3 for Liquid’s d1. Perplexity ran all of these itself, so they are vendor-run.
The v1 card reports 85.71% across 11 benchmarks, against 84.51% for Jev and 74.76% for the base Qwen3.8-27B. Jev scores higher on 6 of the 11. Perplexity measured its own model through its API and does not say how it ran Jev, so these are vendor-run.
The v1.1 card reports a Jev Decision Index score of 61.56, up from 56.4 for v1 and against 57.9 for Jev. It leads Jev on Language (69.45 against 62.0), Retrieval (61.26 against 55.4), Tools (78.88 against 75.1) and Arts (44.66 against 37.7), and trails on Knowledge (48.18 against 51.4). Perplexity credits the gains to removing the causal mask and training on more data, including tasksource. These figures are also vendor-run.
The v1.2 card reports 68.09 on the public Decision Index 0.3 with all of a request’s questions in one sequence, and 67.75 with one question per request, against 62.30 for v1.1. On the public vision board it gives 77.43 against 73.22. The Flash card gives Flash 60.05 with one question per request, 58.88 when they are grouped, and 72.53 on vision. Perplexity says v1.2 trained on the official training splits of several Index benchmarks, decontaminated against the test sets. These are vendor-run too.
Edition 0.2.1 of the independent Jev Decision Index, multimodalart’s community board on Hugging Face, listed v1, checked on 2 October 2026, under the engine id autojev-27b, which the site’s guides earlier called AutoJev-27B. It scored 56.40 against Jev’s 57.91 on the 0 to 100 headline score, with a calibration error of 0.018 against Jev’s 0.074.
Jev Decision Index 0.3, on 7 October 2026, replaced v1 with v1.1. It also changed the headline to a Full score that adds private tests to the public benchmarks, so its numbers do not compare with 0.2.1’s. In the 0.3.1 file of 10 October 2026, v1.1 ranked first of 117 entries with a Full score of 62.75, against 60.11 for Jev. On the public benchmarks alone it scored 62.25 against Jev’s 57.96. Its calibration error was 0.071 against Jev’s 0.074, much higher than the 0.018 that v1 had on the same measure. On RAGTruth the Index gave v1.1 an F1 of 83.14 against Jev’s 76.53.
The board then replaced v1.1 with Perplexity Decider v1.2 (27B). Perplexity submitted the public run as a results dataset, and the Index ran the private tests. Since edition 0.4 the Full score counts only those private tests. In edition 0.4.1, in the file generated on 22 October 2026, v1.2 scored 67.98, fourth of 229 rows, against 60.24 for Jev 1.14; in the 12 November file the same score is 26th of 301. Perplexity told the board that v1.2 trained on the official training splits of several Index benchmarks, and that it chose the checkpoint partly on Index results. Flash v1.2 scored 54.29, 71st of 229, and is 107th of 301 in the 12 November file.
The file generated on 12 November 2026, checked on 14 November, adds v1.3 and Flash v1.3. v1.3 has a Full score of 67.67, 29th of 301 rows, a little below v1.2’s unchanged 67.98, which is now 26th. Its calibration error is lower, 0.042 against 0.055. Flash v1.3 scores 55.14, 103rd, against 54.29 for Flash v1.2, with a calibration error of 0.072 against 0.052. Jev 1.14 is unchanged at 60.24.
On Benchmark Heaven’s JevBench, which ran the open weights itself, v1.2 has a Capability Score of 80.8 in release v1.8.10, measured on 20 October 2026, against 82.7 for v1.1. Flash v1.2 scores 61.7, measured on 19 October, 127th among open-weights systems. JevBench had no v1.3 row on 15 November 2026. Since release v1.8.0 JevBench estimates the cost of self-hosting from GPU time, about $0.026 per 1,000 decisions for v1.2, so v1.2 now counts in its ranking; before, the estimate put it outside the cost cap. That is JevBench’s hardware estimate, not Perplexity’s API price.
The Artificial Analysis Decision Index v1.0, published on 13 October 2026, ran v1.2, Flash v1.2 and v1.1. On version 2.1, checked on 14 November 2026, Decider v1.3 is sixth of 22 decision models at 70.4, just ahead of v1.2 at 69.8 and ahead of Jev 1.14 at 66.2. Flash v1.3 is 13th at 64.1, well above Flash v1.2 at 60.1, which is 21st. On version 1.0, as of 23 October 2026, v1.2 was sixth of 17 at 56.2, just behind Jev 1.14 at 57.1.
On version 2.1, v1.3 has the best score of the 22 on the Humanity’s Last Exam reasoning questions, 15.3%, and its When2Call tool-calling accuracy rose to 94.0% from v1.2’s 88.1%. Its non-hallucination rate on AA’s knowledge questions fell to 6.7 from 17.2, so it almost never answers “I don’t know” when it is wrong. Its calibration error, which this site computed from AA’s published bins, is 0.064, against 0.061 for v1.2 and 0.054 for Jev 1.14. It cost $68 per million tasks and took 289 ms per task. Flash v1.3 cost $34 per million tasks, the second lowest of the 22 after Celeris Decision, and took 178 ms. Its calibration error is 0.112.
What it is not for
It writes no text, so it cannot explain an answer or draft a reply. Perplexity’s own calibration figures are vendor-run: the v1.2 card gives an error of 0.014 on its development set and about 0.05 on decision data held out from all training, where it says the model is still somewhat over-confident. There is no response-time guarantee, and latency grows with input size. The rate limit of 10 requests per second per organization, shared by all four models, caps high-volume use. Flash is the weaker model: on the 0.4.1 Full score Flash v1.3 trails v1.3 by more than 12 points. locate does not read images or work with web grounding, and Perplexity says it has measured span quality only on inputs up to 32K tokens.
Access
The Decisions API is generally available now with a Perplexity API key. It costs $0.02 per million input tokens for v1.3 and v1.2, and $0.01 for both Flash models. The 27B price fell from $0.04 when v1.1 shipped. The 27B models bill the state once per request, unless the questions have to be split into groups to fit the input limit. Flash v1.2 bills the state again for every question. For Flash v1.3 the docs disagree: the first quickstart example says it bills the state once per question, and the section on grouping says once per request. Perplexity’s Python library, perplexityai 0.44.0 or later, and its TypeScript SDK now have a decisions.create method.
In November 2026 Perplexity added an optional mode: "web_grounding" to the Decisions API. The API runs one web search per question, up to 100 questions, and adds the results to the state as evidence before the model answers. The state can also be a page URL, which the API fetches first. Each search and each fetched page costs $0.001, on top of input tokens for the added text. Requests without mode work as before.
Self-hosting v1.3 needs Python 3.12 or newer and a CUDA GPU with about 49 GiB for the weights plus working memory. Flash v1.3 needs about 8.5 GiB. Perplexity’s Decider for Mac app runs Flash v1.2 on an Apple silicon Mac with 16 GB of memory and serves the same API at 127.0.0.1 with no key or bill. It downloads a 5.8 GB model on first launch.
OpenRouter lists perplexity/pplx-decider-v1.2 at $0.02 and perplexity/pplx-decider-flash-v1.2 at $0.01 per million input tokens, both served by Perplexity, as of 14 November 2026. It added listings for v1.3 and Flash v1.3 on 12 November, but they showed no active endpoint on 14 November. In the week to 8 October v1.1 handled 2.1 million requests there, against 1.95 million for v1.
Specifications
| System One Score | 94.7 from 3 of 3 boardsArtificial Analysis Decision Index 97, Jev Decision Index 92.2, JevBench 94.8. How the score works |
| Inputs | Text, imagesPNG, JPEG or WebP images as data URLs, up to 8 per question. Flash and the v1.2 models take the same inputs. Locate questions on v1.3 read a text state only. |
| Question types | ChoiceScoreNoul |
| Max Choice options | 255 |
| Score levels | Up to 10 |
| Questions per call | Not documented |
| Total context | 262,144 tokens |
| State budget | Not documented |
| Rate limit | 10 requests per second per organization by default, shared by all four models. Token limits are per model: 15,000,000 a minute and 900,000,000 an hour for pplx-decider-v1.3 and pplx-decider-v1.2, and 4,000,000 a minute and 240,000,000 an hour for each Flash model. Going over returns HTTP 429 with a Retry-After header. Checked 2026-11-14. |
| Endpoint | POST https://api.perplexity.ai/v1/decisions |
| Licence | Apache-2.0 |
| SDKs | Python: perplexityaiTypeScript: @perplexity-ai/perplexity_ai |
Perplexity's models table gives v1.3 and Flash v1.3 a 256K-token context window, and v1.2 and Flash v1.2 the same; OpenRouter lists 262,144 tokens for v1.2. The state, its images and each question must stay under 256K input tokens. On v1.3, Flash v1.3 and v1.2, questions that do not fit together are answered in consecutive groups, and each group bills the state again; Flash v1.2 answers every question on its own. As of 14 November 2026 the docs set no general cap on questions per request: at least 1, at most 100 with web grounding, and at most 128 when the request has a locate question. When this site checked them on 23 October 2026, the docs capped every request at 128 questions. A Choice takes 1 to 255 options and a Score up to 10 levels. The body must stay under 32 MiB. State can be a string, an object or an array. Images go in the state as base64 PNG, JPEG or WebP data URLs, up to 8 per question and 2,048 tiles of 32 by 32 pixels each, for example 1440 by 1440. Locate needs a string state with no images. The v1.3 model cards say training used sequences up to 30,720 tokens.
Versions
- Decisions API: web grounding and URL fetching, Not a new model. Perplexity's changelog, dated only November 2026, adds mode: "web_grounding" to POST /v1/decisions. Before the model answers, the API runs a Fast Search for each question, up to 100 questions, adds the results to the state as evidence and lists them in search_results. Each search costs $0.001 on top of input tokens for the added results. A second entry lets you pass a page URL as the state in the same mode: the API fetches the page text before searching, returns it in fetched_results, and charges $0.001 per successful fetch. max_staleness sets the oldest stored copy of the page to accept, in seconds. Requests without mode are unchanged. Perplexity's Python and TypeScript SDKs have no mode parameter yet, so it goes in the request body. Release notes
- pplx-decider-v1.3, 12 Nov 2026, The current 27B model and the default: pplx-decider-latest selects it. Same Qwen3.8-27B backbone as v1.2, 26.1B parameters per Hugging Face, at the same $0.02 per million input tokens. It answers all questions in one pass, but each question sees only the state and itself, not the other questions, so answers shift less with grouping than on v1.2. It adds locate questions, which return matching spans of a text state with character offsets and a score. Open weights on Hugging Face under Apache 2.0, ungated. The date is Perplexity's blog post; the changelog dates it only to November 2026. Release notes
- pplx-decider-flash-v1.3, 12 Nov 2026, The current 4B model: pplx-decider-flash-latest selects it. Built on Qwen3.5-4B, 4.5B parameters per Hugging Face, and distilled from v1.3. Same request, response, limits, image support and locate questions as v1.3, at $0.01 per million input tokens. Open weights on Hugging Face under Apache 2.0, ungated. Release notes
- pplx-decider-v1.2, 16 Oct 2026, Replaced as the default by v1.3 on 12 November 2026 and still served by name at $0.02. Perplexity says to keep it only while you revalidate thresholds tuned on it. It replaced v1.1 on the same Qwen3.8-27B backbone, 26.1B parameters per Hugging Face. It reads all of a request's questions in one sequence, so they can affect each other's answers. It does not answer locate questions. Open weights on Hugging Face under Apache 2.0, ungated. The date is Perplexity's launch post; OpenRouter lists it as perplexity/pplx-decider-v1.2, snapshot -20261016. Release notes
- pplx-decider-flash-v1.2, 16 Oct 2026, Replaced as the default 4B model by Flash v1.3 on 12 November 2026 and still served by name at $0.01. Built on Qwen3.5-4B, 4.5B parameters per Hugging Face, and distilled from the 27B decision models. It answers each question on its own and bills the state again for each, so Perplexity built it for one question per request. Open weights on Hugging Face under Apache 2.0, ungated. Perplexity's Decider for Mac app runs it locally on Apple silicon. Release notes
- pplx-decider-v1.1-27b, 7 Oct 2026, Replaced by v1.2. Requests that name it are now answered by v1.2. It replaced v1 on the same Qwen3.8-27B backbone. Open weights on Hugging Face under Apache 2.0. Perplexity's changelog dates it only to October 2026; the date here is when OpenRouter added it as perplexity/pplx-decider-v1.1-27b, snapshot -20261006. That listing showed no active endpoint on 2026-10-23. Release notes
- pplx-decider-v1-27b, 1 Oct 2026, The launch model. Requests that name it are now answered by v1.2 at its rate. Open weights on Hugging Face under Apache 2.0, ungated, on a Qwen3.8-27B base, in BF16 Safetensors. The card says 26 billion parameters while the model id says 27b. Srinivas's launch post calls it pplx-decider-27b. Release notes
Use cases
What people use pplx-decider for, one page per pattern.
Support inbox triage with System One models
Send a support ticket to Jev once with every question attached. Category comes back as a selected label, severity and frustration as numbers on scales you wrote, refund intent as a probability. Your code reads those values and decides what happens to the ticket.
Intent and model routing with System One models
One Jev call reads an incoming request and returns its intent as a label plus a difficulty rating on a scale you wrote. Your router reads both numbers and picks the handler: deterministic code, a cheap model, an expensive one, or a human queue.
Citation verification with System One models
An answer with citations is only as good as the citations. Match each quote against the source in code to catch fabrications, then ask Jev one Choice question about how the surrounding section relates to the claim. Confidence decides which verdicts a human reviews.
Examples built with pplx-decider
The most-starred and most-viewed entries in the directory. All pplx-decider examples.
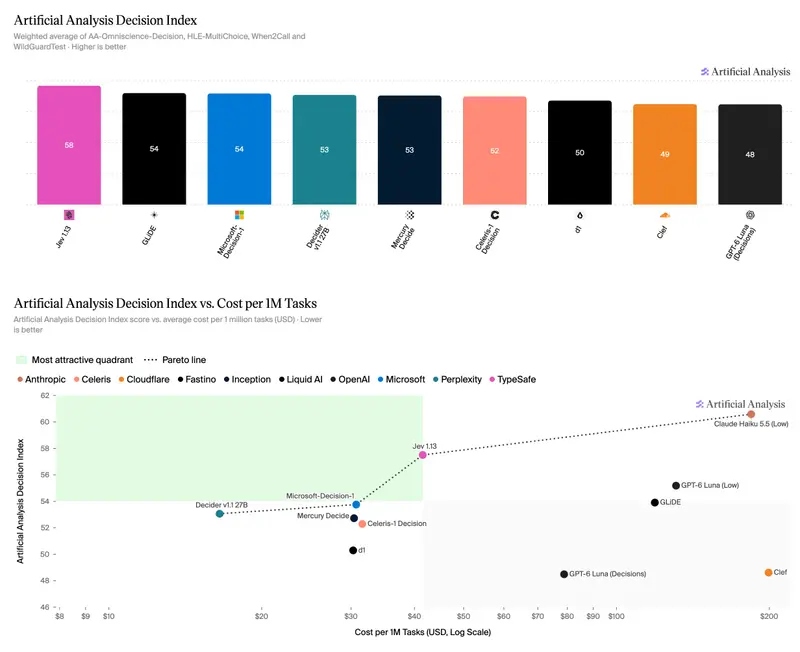
Artificial Analysis Decision Index: 11 hosted decision models against language models
Artificial Analysis scores 11 hosted decision models on knowledge, reasoning, tool-calling and safety tests, with cost and time per task, and runs language models on the same tests. Jev 1.13 led the decision models at launch at 58, and on version 2.1, checked 12 November, Nace.AI's Drex Max v1.1 leads at 72.6; at launch Claude Haiku 5.5 (Low) scores 61 but takes 1.4 seconds per task against 0.13.
 Artificial Analysis (@ArtificialAnlys)45k viewsOpenArtificial Analysis Decision Index: 11 hosted decision models against language models on artificialanalysis.ai
Benchmarks
Published scores, each linked to its source. A row marked vendor-run was measured by the vendor itself, so read it as one side's result. The compare hub sets these beside the other models.
| Benchmark | Metric | Score | Run by | Date |
|---|---|---|---|---|
| Artificial Analysis Decision Index 2.1 | Index score | 70.4 score | Independent | 14 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Expected calibration error | 0.0643 ECE | Independent | 14 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Cost per 1M tasks | 68 USD | Independent | 14 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Time per task | 289 ms | Independent | 14 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Index score | 64.1 score | Independent | 14 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Expected calibration error | 0.1115 ECE | Independent | 14 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Cost per 1M tasks | 34 USD | Independent | 14 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Time per task | 178 ms | Independent | 14 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Cost per 1M tasks | 68 USD | Independent | 14 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Index score | 69.8 score | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Expected calibration error | 0.0609 ECE | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Time per task | 229 ms | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Index score | 60.1 score | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Expected calibration error | 0.15 ECE | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Cost per 1M tasks | 196 USD | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Time per task | 134 ms | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Full score | 67.67 score | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Expected calibration error | 0.0421 ECE | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Full score | 55.14 score | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Expected calibration error | 0.0721 ECE | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Full score | 67.98 score | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Public score | 67.74 score | vendor-run | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Expected calibration error | 0.0551 ECE | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Full score | 54.29 score | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Public score | 60.06 score | vendor-run | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Expected calibration error | 0.0523 ECE | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 1.0 | Index score | 56.2 score | Independent | 23 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Expected calibration error | 0.097 ECE | Independent | 23 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Cost per 1M tasks | 15 USD | Independent | 23 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Time per task | 206 ms | Independent | 23 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Index score | 50.2 score | Independent | 23 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Expected calibration error | 0.1807 ECE | Independent | 23 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Cost per 1M tasks | 8.2 USD | Independent | 23 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Time per task | 110 ms | Independent | 23 Oct 2026 |
| JevBench 1.8.10 | Capability Score | 80.8 score | Independent | 20 Oct 2026 |
| JevBench 1.8.10 | Capability Score | 61.7 score | Independent | 19 Oct 2026 |
| Jev Decision Index 0.3 | Overall Decision Index | 68.09 score | vendor-run | 16 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Index score | 53.1 score | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Expected calibration error | 0.1447 ECE | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Cost per 1M tasks | 17 USD | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Time per task | 170 ms | Independent | 13 Oct 2026 |
| JevBench 1.8.10 | Capability Score | 82.7 score | Independent | 12 Oct 2026 |
| Jev Decision Index 0.3.1 | Full score | 62.75 score | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Public score | 62.25 score | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Expected calibration error | 0.0713 ECE | Independent | 10 Oct 2026 |
| Jev Decision Index | Overall Decision Index | 61.56 score | vendor-run | 7 Oct 2026 |
- Artificial Analysis Decision Index, Index score: Row: Decider v1.3, host Perplexity. Raw value 70.408. 6th of 22 decision models on version 2.1, checked 2026-11-14. Sub-scores: When2Call accuracy 94.0, Omniscience accuracy 40.6, HLE-MultiChoice accuracy 15.3. Version 2.1 figures do not compare with version 1.0 figures.
- Artificial Analysis Decision Index, Expected calibration error: Row: Decider v1.3. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Decider v1.3. AA's measured cost per million tasks on its version 2.1 evals.
- Artificial Analysis Decision Index, Time per task: Row: Decider v1.3. Time per task.
- Artificial Analysis Decision Index, Index score: Row: Decider Flash v1.3, host Perplexity. Raw value 64.072. 13th of 22 decision models on version 2.1, checked 2026-11-14. Sub-scores: When2Call accuracy 88.9, Omniscience accuracy 32.2, HLE-MultiChoice accuracy 9.8.
- Artificial Analysis Decision Index, Expected calibration error: Row: Decider Flash v1.3. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Decider Flash v1.3. AA's measured cost per million tasks on its version 2.1 evals.
- Artificial Analysis Decision Index, Time per task: Row: Decider Flash v1.3. Time per task.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Decider v1.2. AA's measured cost per million tasks on its version 2.1 evals, $68.46 on 2026-11-14.
- Artificial Analysis Decision Index, Index score: Row: Decider v1.2, host Perplexity. Raw value 69.766. 6th of 19 decision models on version 2.1 on 2026-11-12, and 7th of 22 on 2026-11-14, behind v1.3. Sub-scores: When2Call accuracy 88.1, Omniscience accuracy 39.6, HLE-MultiChoice accuracy 13.8. Version 2.1 figures do not compare with version 1.0 figures.
- Artificial Analysis Decision Index, Expected calibration error: Row: Decider v1.2. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Time per task: Row: Decider v1.2. Time per task.
- Artificial Analysis Decision Index, Index score: Row: Decider Flash v1.2, host Perplexity. Raw value 60.084. 18th of 19 decision models on version 2.1 on 2026-11-12, and 21st of 22 on 2026-11-14. Sub-scores: When2Call accuracy 74.1, Omniscience accuracy 35.4, HLE-MultiChoice accuracy 10.2. Version 2.1 figures do not compare with version 1.0 figures.
- Artificial Analysis Decision Index, Expected calibration error: Row: Decider Flash v1.2. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Decider Flash v1.2. AA's measured cost per million tasks on its version 2.1 evals.
- Artificial Analysis Decision Index, Time per task: Row: Decider Flash v1.2. Time per task.
- Jev Decision Index, Full score: Row: Perplexity Decider v1.3 (27B), 29th of 301 rows by this score in the file generated 2026-11-12, checked 2026-11-14. The same file gives v1.2 67.98, 26th, and Jev 1.14 60.24. Counts 60% private same-skill tests and 40% private new-domain tests. 0 is random guessing, 100 is perfect.
- Jev Decision Index, Expected calibration error: Row: Perplexity Decider v1.3 (27B). Lower is better; v1.2 scores 0.0551 in the same file.
- Jev Decision Index, Full score: Row: Perplexity Decider Flash v1.3 (4B), 103rd of 301 rows by this score in the file generated 2026-11-12, checked 2026-11-14. Flash v1.2 scores 54.29 in the same file.
- Jev Decision Index, Expected calibration error: Row: Perplexity Decider Flash v1.3 (4B). Lower is better; Flash v1.2 scores 0.0523 in the same file.
- Jev Decision Index, Full score: Row: Perplexity Decider v1.2 (27B), 26th of 301 rows by this score. Counts 60% private same-skill tests and 40% private new-domain tests; public benchmarks no longer count. 0 is random guessing, 100 is perfect. The board's v1.2 row replaces v1.1, which it no longer lists.
- Jev Decision Index, Public score: Row: Perplexity Decider v1.2 (27B). Public run submitted by Perplexity as a results dataset.
- Jev Decision Index, Expected calibration error: Row: Perplexity Decider v1.2 (27B). Lower is better.
- Jev Decision Index, Full score: Row: Perplexity Decider Flash v1.2 (4B), 107th of 301 rows by this score. Counts 60% private same-skill tests and 40% private new-domain tests; public benchmarks no longer count. 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: Perplexity Decider Flash v1.2 (4B). Public run submitted by Perplexity as a results dataset.
- Jev Decision Index, Expected calibration error: Row: Perplexity Decider Flash v1.2 (4B). Lower is better.
- Artificial Analysis Decision Index, Index score: Row: Decider v1.2, 6th of 17 decision models as of 2026-10-23. Sub-scores: Omniscience accuracy 39.4, non-hallucination 16.5, HLE-MultiChoice 14.6, When2Call 87.7, WildGuardTest F1 94.4. AA does not date its rows; this is the date it was checked.
- Artificial Analysis Decision Index, Expected calibration error: Row: Decider v1.2. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Decider v1.2. AA's measured cost at list prices on its four evals.
- Artificial Analysis Decision Index, Time per task: Row: Decider v1.2. Median time per task.
- Artificial Analysis Decision Index, Index score: Row: Decider Flash v1.2 (4B), 13th of 17 decision models as of 2026-10-23. Sub-scores: Omniscience accuracy 35.2, non-hallucination 6.5, HLE-MultiChoice 12.1, When2Call 74.4, WildGuardTest F1 93.3.
- Artificial Analysis Decision Index, Expected calibration error: Row: Decider Flash v1.2. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Decider Flash v1.2. AA's measured cost at list prices on its four evals, the lowest of the 17.
- Artificial Analysis Decision Index, Time per task: Row: Decider Flash v1.2. Median time per task.
- JevBench, Capability Score: Row: pplx-decider-v1.2 (Perplexity, Qwen3.8-27B full fine-tune, marker readout, self-hosted), measured 2026-10-20. Intelligence 71.7, Calibration 90.0. 24th among open-weights systems by Capability Score. Board release v1.8.10, read 2026-11-15. It was 81.7 in release 1.7.47.
- JevBench, Capability Score: Row: pplx-decider-flash-v1.2 (Perplexity, Qwen3.5-4B full fine-tune, marker readout, self-hosted), measured 2026-10-19. Intelligence 45.5, Calibration 78.0. 127th among open-weights systems by Capability Score. Board release v1.8.10, read 2026-11-15. It was 62.5 in release 1.7.47.
- Jev Decision Index, Overall Decision Index: From the v1.2 model card, Perplexity's own run with all of a request's questions in one sequence; 67.75 with one question per request, against 62.30 for v1.1. The Flash card gives Flash 60.05 with one question per request and 58.88 joint.
- Artificial Analysis Decision Index, Index score: Row: Decider v1.1 27B, kept as history; 9th of 17 decision models as of 2026-10-23. Sub-scores: Omniscience accuracy 39.8, non-hallucination 13.3, HLE-MultiChoice 15.4, When2Call 76.5, WildGuardTest F1 93.8.
- Artificial Analysis Decision Index, Expected calibration error: Row: Decider v1.1 27B. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Decider v1.1 27B. AA's measured cost at list prices on its four evals.
- Artificial Analysis Decision Index, Time per task: Row: Decider v1.1 27B. Median time per task.
- JevBench, Capability Score: Row: Perplexity Decider v1.1 27B, kept on the board after v1.2. Intelligence 75.6, Calibration 89.8. 9th among open-weights systems by Capability Score. Board release v1.8.10, read 2026-11-15. It was 82.8 in release 1.7.46.
- Jev Decision Index, Full score: Row: Perplexity Decider v1.1 (27B). Counts 20% public benchmarks and 80% private tests; 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: Perplexity Decider v1.1 (27B).
- Jev Decision Index, Expected calibration error: Row: Perplexity Decider v1.1 (27B). Lower is better.
- Jev Decision Index, Overall Decision Index: From the v1.1 model card, Perplexity's own run; the same table gives 57.9 for Jev and 56.4 for v1.
Comparisons
Head-to-head pages that put pplx-decider against other models. Every model sits in one table on the compare hub.
Jev vs pplx-decider: TypeSafe's decision model against Perplexity's
pplx-decider is Perplexity's decision model with open weights and image input. How it compares with Jev on price, limits, API format and published results.
Updated
Microsoft-Decision-1 vs pplx-decider: Microsoft's decision model against Perplexity's
Microsoft-Decision-1 is closed and text only. pplx-decider is cheaper, reads images and has open weights. How the two compare on price, limits and published results.
Updated