Inception is winding down the Mercury API. Its docs say the service stays fully available through 28 December 2026, and after that you lose access to the service and to any data sent to it. Plan a move to another model before then.
What Mercury Decide is
Mercury Decide is a decision model from Inception, the company that makes the Mercury family of diffusion language models. A System One model reads a state and answers typed questions about it, and Mercury Decide is Inception’s entry in that class, alongside Jev. OpenRouter describes it as a structured decision model served as a System One endpoint.
You send a state and typed questions. It returns a choice, a score or a yes/no answer, each with a probability. OpenRouter says that probability is taken from the model rather than written out as text, so there is no generated prose to parse.
How you call it
It is not OpenAI-compatible. Inception’s own API takes POST https://api.inceptionlabs.ai/v1/decisions with the model mercury-decide, a state and a map of named questions, and an INCEPTION_API_KEY. Inception’s docs say it does not support chat completions, streaming or tool calling. On OpenRouter, according to AlphaSignal’s report on the launch, you called the /v1/systemone endpoint instead of a chat completions route. OpenRouter served a paid inception/mercury-decide and a free inception/mercury-decide:free, both from the inception/mercury-decide-20260930 snapshot, with Inception as the only provider. On 12 November 2026 both listings returned no endpoints, and the model was no longer on OpenRouter’s decisions list.
Inception makes diffusion LLMs, which generate text in parallel rather than one token at a time. The launch materials we found do not say how Mercury Decide is built beyond that, and no weights are published.
What it returns
The primitives map to the three answer types: a choice picks one option from a list, a score returns a level, and a yes/no answer is what the site calls Noul. Each comes with a probability, and a Choice or Score also returns a confidence value. Inception’s docs allow 1 to 255 options per Choice and 1 to 10 levels per Score. A Score can be fractional, because it is a probability-weighted average of the levels. No cap on questions per call is published as of 2026-10-09.
What Inception claims
Inception’s launch post calls Mercury Decide “the most intelligent decision model on @OpenRouter (JevBench v1.4)” and says it makes “up to 14 decisions per second”. Both numbers are reported by Inception and were not independently run. The model was not on Benchmark Heaven’s public JevBench board on 2026-10-01, and the launch post does not link to the evaluation behind the claim. JevBench’s hosted API board has since measured it, on 7 October 2026, at a Capability Score of 73.6, 19th on that board in release v1.8.10, against 75.0 for Jev 1.14. Treat the ranking as a vendor statement until someone reproduces it.
The first outside score came from the Artificial Analysis Decision Index v1.0, published on 13 October 2026. It ranked Mercury Decide fifth of the 11 decision models it listed at launch, at 52.7 against 57.5 for Jev. On version 2.1, checked on 14 November 2026, it scores 62.1, 15th of 22 decision models, against 66.2 for Jev 1.14; it was 12th of 19 on 12 November. Its calibration error, which this site computed from AA’s published bins, is 0.171, the worst of the 22. Its non-hallucination rate on AA’s private knowledge questions, which rewards answering “I don’t know” over a wrong answer, is 20.2, 14th of the 22. It cost $70 per million tasks, the seventh lowest of the 22, and took 245 ms per task. Mercury Decide has no row on the Jev Decision Index, so there is no second board to check it against.
What it’s good for
OpenRouter says it is built for triage, routing, moderation, agent step selection and evaluation loops. These are calls where the answer comes from a fixed set and you want a probability to gate on, for example sending a ticket to a queue, picking the next step for an agent, or scoring an output against a rubric.
What it’s not for
It does not write text, so anything that needs an explanation or a draft belongs with a language model. Its calibration error on the Artificial Analysis run is the highest of the 22 decision models there, so test the probabilities on your own cases before you act on a threshold.
Access today
Mercury Decide costs $0.02 per million input tokens on Inception’s API, which Inception lists as 50% off a regular $0.04. Output is not charged. OpenRouter sold it at the same price as inception/mercury-decide, with a free inception/mercury-decide:free, but showed no endpoint for either on 12 November 2026, so Inception’s API is the way to call it. Inception’s docs carry no early-access or beta label for it, though its /v1/models API calls it a “Typed-decision preview”. Inception has published no rate-limit figures or SDK as of 2026-10-09.
Specifications
| System One Score | 86 from 2 of 3 boardsArtificial Analysis Decision Index 85.5, JevBench 86.4. How the score works |
| Inputs | Text, imagesUp to 16 PNG, JPEG, WebP or GIF images per request as base64 data URLs, per Inception's docs. Inception's /v1/models lists text input only. |
| Question types | ChoiceScoreNoul |
| Max Choice options | 255 |
| Score levels | Up to 10 |
| Questions per call | Not documented |
| Total context | 65,536 tokens |
| State budget | Not documented |
| Rate limit | Inception documents a 429 rate-limit error but publishes no figures, checked on 2026-10-09. |
| Endpoint | POST https://api.inceptionlabs.ai/v1/decisions |
| Licence | Not published as of 15 Nov 2026 |
| SDKs |
Inception's /v1/models API gives mercury-decide a 65,536-token context, checked 2026-11-12, while its docs models table gives no context window. OpenRouter listed 65,536 tokens with a 58,982-token maximum completion for both its endpoints on 2026-10-09, and 32,768 and 29,491 on 2026-10-01. Inception's docs say a Choice takes 1 to 255 options and a Score 1 to 10 levels. The docs also take base64 PNG, JPEG, WebP or GIF images in the state, up to 16 per request and 10 MiB each, inside a 20 MiB body. No cap on questions per call is published.
Versions
- inception/mercury-decide-20260930:free, 30 Sep 2026, The free launch endpoint on OpenRouter, served by Inception alone, listed as inception/mercury-decide:free. OpenRouter returned no endpoints for it on 2026-11-12. Release notes
- inception/mercury-decide-20260930, The paid endpoint of the same snapshot, not listed when this page was checked on 2026-10-01 and listed by 2026-10-09, at $0.02 per million input tokens, served by Inception, as inception/mercury-decide. OpenRouter returned no endpoints for it on 2026-11-12 and had dropped it from its decisions list. On Inception's own API the model id is mercury-decide, which its /v1/models API describes as a "Typed-decision preview" on 2026-11-12. Release notes
Use cases
What people use Mercury Decide for, one page per pattern.
Support inbox triage with System One models
Send a support ticket to Jev once with every question attached. Category comes back as a selected label, severity and frustration as numbers on scales you wrote, refund intent as a probability. Your code reads those values and decides what happens to the ticket.
Intent and model routing with System One models
One Jev call reads an incoming request and returns its intent as a label plus a difficulty rating on a scale you wrote. Your router reads both numbers and picks the handler: deterministic code, a cheap model, an expensive one, or a human queue.
LLM guardrails with System One models
Put one Jev request in front of an LLM and one behind it. Yes/no questions return the probability that each hazard holds, a Score rates how much harm complying would do, and your thresholds turn those numbers into pass, review, block, or a crisis path.
Agent routing and skill selection with System One models
An agent choosing from a long skill roster reads one truncated line per entry and often loads the wrong thing. Jev ranks every entry in one request and separately answers whether any skill applies at all, so the agent gets a short hint instead of a guess.
Examples built with Mercury Decide
The most-starred and most-viewed entries in the directory. All Mercury Decide examples.
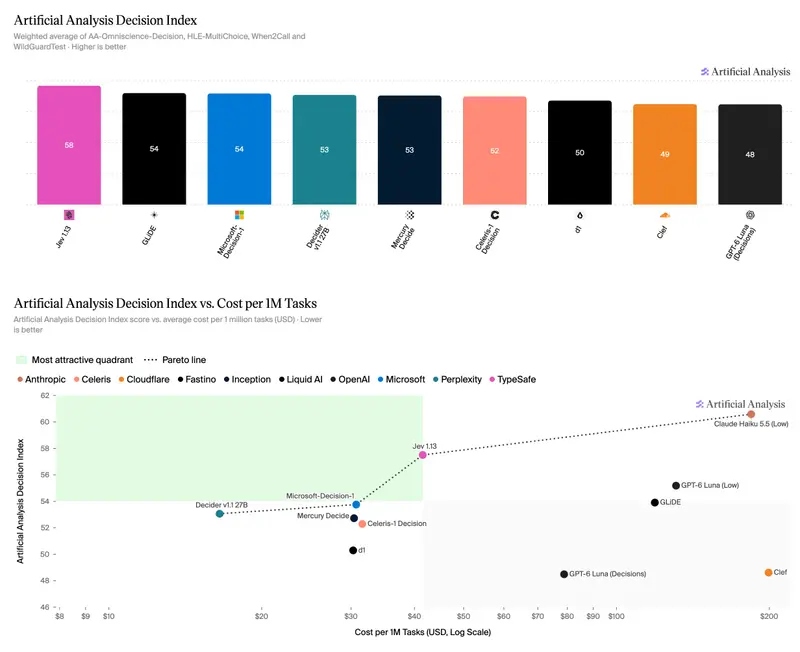
Artificial Analysis Decision Index: 11 hosted decision models against language models
Artificial Analysis scores 11 hosted decision models on knowledge, reasoning, tool-calling and safety tests, with cost and time per task, and runs language models on the same tests. Jev 1.13 led the decision models at launch at 58, and on version 2.1, checked 12 November, Nace.AI's Drex Max v1.1 leads at 72.6; at launch Claude Haiku 5.5 (Low) scores 61 but takes 1.4 seconds per task against 0.13.
 Artificial Analysis (@ArtificialAnlys)45k viewsOpenArtificial Analysis Decision Index: 11 hosted decision models against language models on artificialanalysis.ai
Mercury Decide vs Jev in chess
Video demo from Inception's Mercury Decide launch post, showing it playing Jev at chess. Inception claims up to 14 decisions per second and the top JevBench v1.4 spot on OpenRouter; neither was independently run.

Benchmarks
Published scores, each linked to its source. A row marked vendor-run was measured by the vendor itself, so read it as one side's result. The compare hub sets these beside the other models.
| Benchmark | Metric | Score | Run by | Date |
|---|---|---|---|---|
| Artificial Analysis Decision Index 2.1 | Index score | 62.1 score | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Expected calibration error | 0.1706 ECE | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Cost per 1M tasks | 70 USD | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Time per task | 245 ms | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 1.0 | Cost per 1M tasks | 15 USD | Independent | 16 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Index score | 52.7 score | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Expected calibration error | 0.2111 ECE | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Time per task | 500 ms | Independent | 13 Oct 2026 |
| JevBench 1.8.10 | Capability Score | 73.6 score | Independent | 7 Oct 2026 |
- Artificial Analysis Decision Index, Index score: Row: Mercury Decide, host Inception. Raw value 62.067. 12th of 19 decision models on version 2.1 on 2026-11-12, and 15th of 22 on 2026-11-14. Sub-scores: When2Call accuracy 78.9, Omniscience accuracy 35.8, HLE-MultiChoice accuracy 8.6. Version 2.1 figures do not compare with version 1.0 figures.
- Artificial Analysis Decision Index, Expected calibration error: Row: Mercury Decide. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Mercury Decide. AA's measured cost per million tasks on its version 2.1 evals.
- Artificial Analysis Decision Index, Time per task: Row: Mercury Decide. Time per task.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: Mercury Decide. AA's measured cost at list prices on its four evals. AA showed $30 when checked on 2026-10-14 and $15 on 2026-10-16.
- Artificial Analysis Decision Index, Index score: Row: Mercury Decide. Sub-scores: Omniscience accuracy 35.0, non-hallucination 32.0, HLE-MultiChoice 10.1, When2Call 79.3, WildGuardTest F1 88.0. AA names the host as Inception and does not say whether it used the free or the paid model id.
- Artificial Analysis Decision Index, Expected calibration error: Row: Mercury Decide. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Time per task: Row: Mercury Decide. Median time per task.
- JevBench, Capability Score: Row: Mercury Decide, measured 2026-10-07. Intelligence 65.9, Calibration 81.3. 19th by Capability Score on the hosted API board. Board release v1.8.10, read 2026-11-15.