Post on X
- Views
- 405
- Likes
- 1
- Reposts
- 0
Read from X on . Counts change daily.
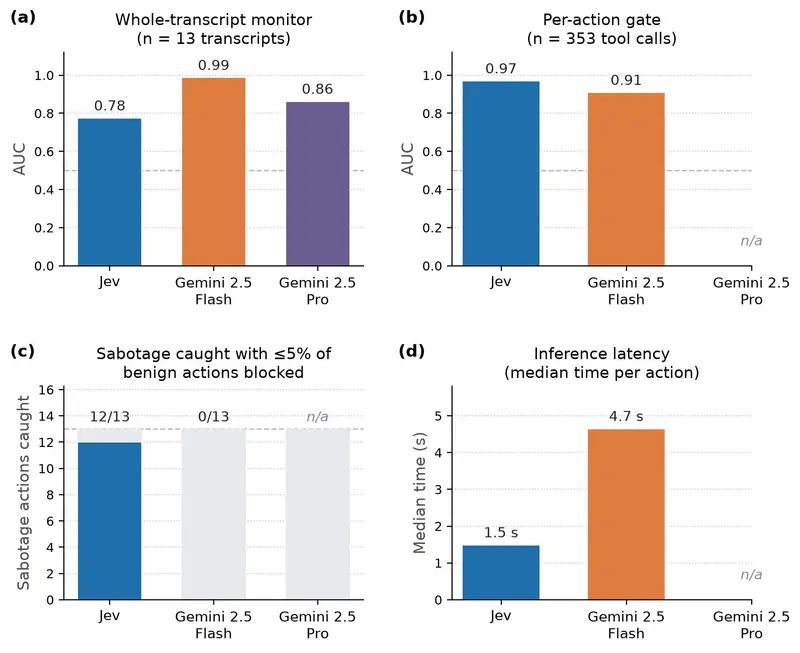
Test report using Jev to check each agent action before it executes, reporting most attacks caught with few false blocks and much lower latency than an LLM guard.
Read from X on . Counts change daily.
Makes one AI trade decision every Monad block on the Kuru MON-USDC market using Jev. The public deployment runs in dry-run mode with a mock model.
 jarrodwattsOpenjev-trader on github.com
2.2k starsLoop, mock model p50 100 msDecision window ~300 ms/block
MCP server that gives Claude Code, Codex, Amp, OpenCode and other agents ten Jev judgment tools, each returning typed probabilities they can branch on. The author calls it early software.
320 starsPer call 150-500 ms
The 1,978-point, 513-comment launch thread. The top comment calls the speed comparison misleading, since Jev only returns structured output, and disputes the cannot-hallucinate claim because a valid type can still hold a wrong value. Others note ordinary LLMs can already be forced into structured output.
Guarantees valid structured output during generation by constraining decoding to a grammar or schema. The mechanism HN commenters repeatedly cited as already covering Jev's cannot-produce-a-type-error guarantee on ordinary LLMs. Star count is GitHub's rounded display figure.
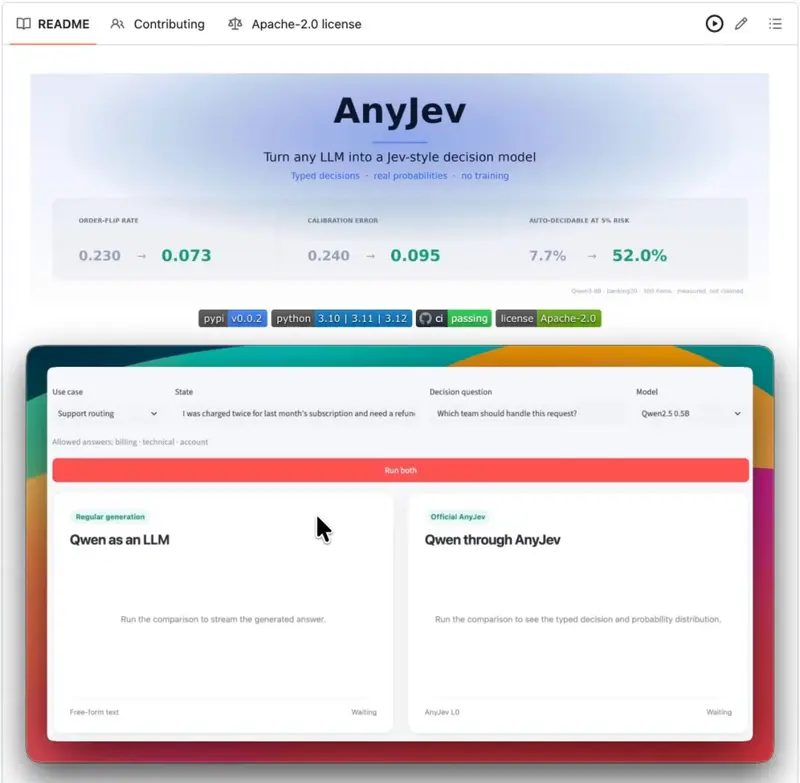
Python library from Nokia researchers that reads typed Choice, Noul and Score answers with probabilities from an open LLM's logits or hidden states, without fine-tuning. Its zero-label level reduces option-order bias, and a head fit on 100 to 300 labels can run behind vLLM.
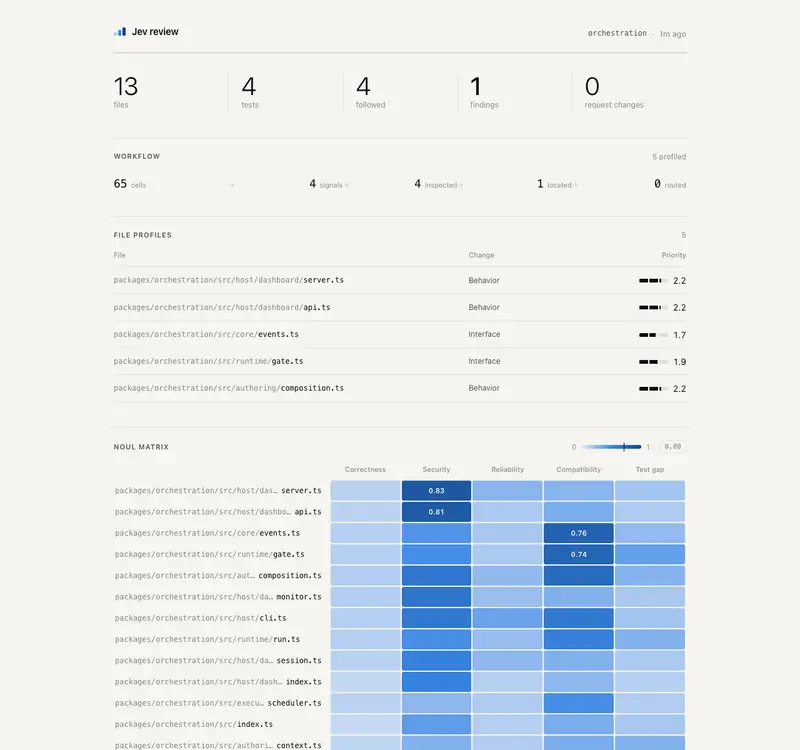
Staged code-review workflow with a local dashboard, where Jev judges code changes or a whole codebase.


