typesafe-ai/skills (official TypeSafe agent skill)
Official agent skill for Claude Code, Codex and other agent environments; installs via claude plugin marketplace add typesafe-ai/skills or npx skills add typesafe-ai/skills. MIT licensed.
The layer between your code and the API: SDKs for the languages the vendor does not ship, MCP servers that put the model inside a coding agent, provider packages for the usual frameworks, CLI wrappers and workflow nodes. Most of these are days old and still moving, so check when each one was last touched before you depend on it in something that matters.
250 tools
Showing 1 to 48 of 250
Official agent skill for Claude Code, Codex and other agent environments; installs via claude plugin marketplace add typesafe-ai/skills or npx skills add typesafe-ai/skills. MIT licensed.
MCP server that gives Claude Code, Codex, Amp, OpenCode and other agents ten Jev judgment tools, each returning typed probabilities they can branch on. The author calls it early software.
320 starsPer call 150-500 ms
Apache 2.0 weights for Cloudflare's 27B Clef decision model, post-trained from Qwen3.8-27B, that reads text and images. The smaller 9B Clef-flash is published next to it as Cloudflare/clef-flash.
Claude Code plugin that replaces the compaction summary with Jev decisions. Every tool call and result is scored in one request against the whole conversation, stale ones are dropped or truncated, and everything kept stays verbatim. Also usable as an npm library.
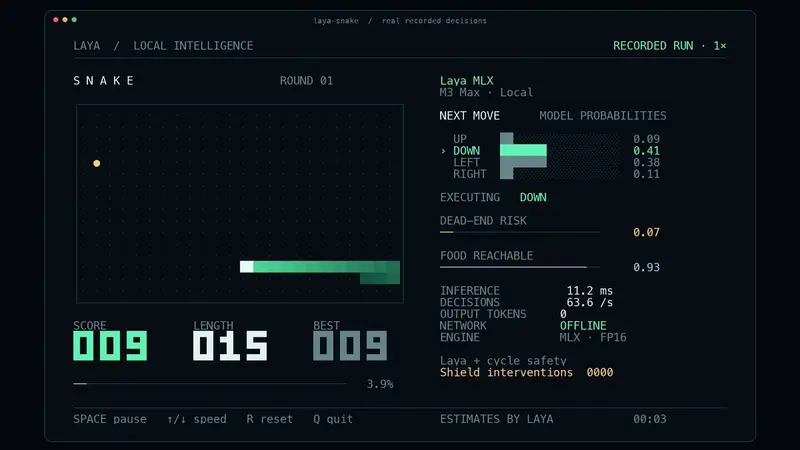
An independent MLX port of Laya for Apple Silicon, 13.4ms median for a short English decision and 7.4ms on the multilingual checkpoint, with a Snake demo that plays at up to 75 moves per second under 1GB of memory.
 mizorewwwOpenLaya-MLX on github.com
6.1k starsShort decision 13.4 ms P50Snake demo 75.4 moves/s
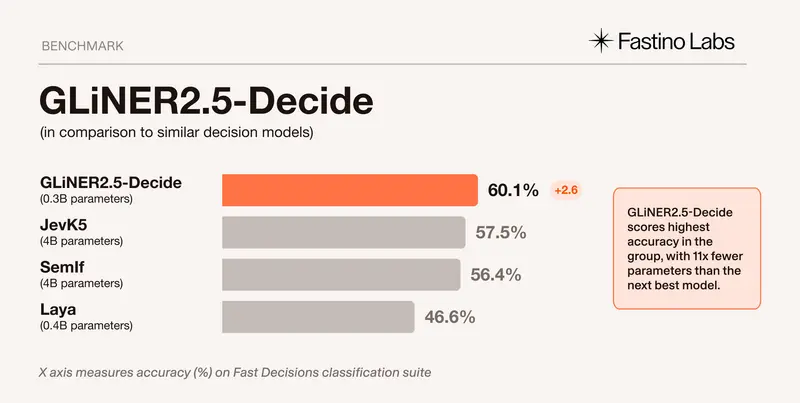
Open-weights 340M-parameter decision model from Fastino Labs. It jointly decodes typed classification questions and, per Fastino's own internal benchmark, leads 9 of 17 datasets against JevK5, SemIf and Laya.
 Fastino Labs (@fastinoAI)OpenGLiNER2.5-Decide on huggingface.co
2.2k starsCPU latency 167 msGPU latency 38-47 ms
Core ML ports of all three Laya checkpoints for Apple Silicon, reaching 4.98ms P50 on the Neural Engine for a short multilingual decision, with a Snake demo sustaining about 50 decisions per second.
 mizorewwwOpenLaya-CoreML on github.com
1.4k starsShort decision 4.98 ms P50Snake demo 49-50 dec/s
Vercel Labs CLI for generating from the terminal. Its evaluate command takes a state plus typed questions and defaults its evaluation model to typesafe-ai/jev on the AI Gateway, with -m jev as the shorthand and an --input flag for text or JSON state.
Places Jev as a fast supervisor above slower Codex coding agents. Codex workers do the engineering while Foreman independently assesses whether the work is complete, requirements are met, tests suffice, or human input is needed.
A browser skill for Codex where Jev handles navigation, clicks, toggles and scrolling while Codex stays in charge of text input, visual judgment and the final check.
447 starsSpeed 5-10x faster
Automatic per-turn model routing for Claude Code and OpenAI Codex. Jev sends simple work to the fast model tier and difficult work to the strong tier while preserving each CLI's native tools, sessions, permissions and authentication.
Node.js and TypeScript package that runs the Laya decision model through ONNX Runtime, so JavaScript projects can call it without Python.
 receptronOpen@receptron/laya on github.com
374 stars3-question call ~140 msModel size ~1.7 GB
MCP server for TypeSafe shipped as a single static Go binary with no Node or Python runtime. Sends usage guidance to the client so the agent writes better questions.
Official drop-in replacement for TypeSafeClient that sends the same typed questions to ordinary LLM APIs, so developers can compare Jev against an LLM on cost, speed and answers.
A CLI from Sutro for building AI functions with Jev: it finds uncertain examples, has you label them, and uses GEPA to improve the function.
Per-call model routing for Codex: Jev answers four choice questions to pick the model tier and thinking depth, so the cheapest sufficient model serves each call. A 7-day replay of 237 real turns measured about 60% savings against always using Astra, under an older policy.
262 starsHistorical replay ~-60% cost
Browser-use tool driving a real headless browser through an MCP server, CLI or library, with Jev choosing the actions. Returns text, markdown, HTML or accessibility-tree output plus traces and screenshots.
256 starsWikipedia nav ~4s, $0.0016
Self-hosted, versioned skills library for AI agents. Serves skills over MCP with scoped clients, and adds optional Jev recommendations for which skill to reach for.
Official TypeScript/JavaScript client published to npm as @typesafe-ai/sdk (v0.6.0), requiring Node.js 20+ and shipping ESM, CommonJS and type declarations.
Official Python client for the TypeSafe System One API, published to PyPI as typesafe-sdk with sync (TypeSafeClient) and async (AsyncTypeSafeClient) clients.
Local-first MCP plugin giving Claude Code, Codex, Cursor and OpenCode structured code-quality scores (correctness, complexity, modularity, security) while they work. Sends focused diffs to Jev and keeps keys and code local.
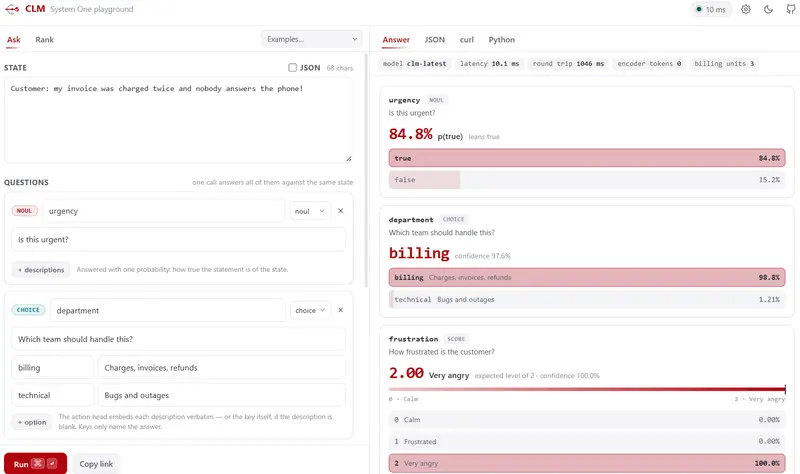
Open System One model that scores states against actions with a contrastive objective, serving CLM-8B behind a TypeSafe-compatible API. The authors report Jev-level results on computer-use, gaming and tool-calling with up to 9x lower latency, plus scaling laws and a fine-tuning guide.
 Jacky Kwok (@jackyk02)OpenCLM: Contrastive Language Models on github.com
215 starsvs Jev latency up to 9x fasterDeepSWE (tuned) 81.6%
Open source tool that scores every turn a coding agent takes against project rules that can't be codified into a linter, using Jev, then tells the agent what to fix.
 Ohans Emmanuel (@OhansEmmanuel)Opencoldteadotai/abide on github.com
211 starsRule breaks 1 in 13 turnsPer check ~300 ms
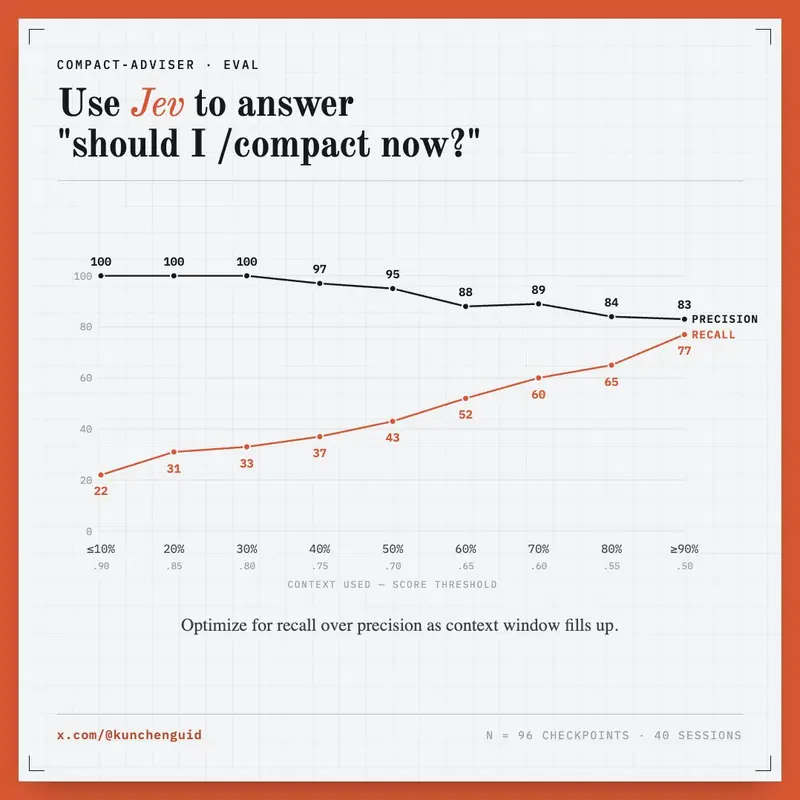
A Claude Code and pi plugin that uses Jev to judge whether a session has reached a safe point to run /compact, in a hint mode or a fully automatic mode.
 Kun Chen (@kunchenguid)Openkunchenguid/compact-adviser on github.com
183 starsEval set 40 sessionsHint floor (empty) 0.90
An AI API server that abstracts multiple models and providers behind one layer, for local use with Ollama or LM Studio or in the cloud via OpenRouter, OpenAI, Anthropic or Google. It now supports Jev.
Extension making Jev the decision layer for the Pi coding agent: a measured tool-call gate plus a jev_ask tool. Judges whether an action is destructive, exfiltrates data or exceeds scope, then blocks or warns on calibrated thresholds.
144 starsGate latency ~300ms
A Claude Code plugin that uses Jev to trim noisy Bash output after a command runs but before the result reaches the main model, once the output passes an estimated token threshold.
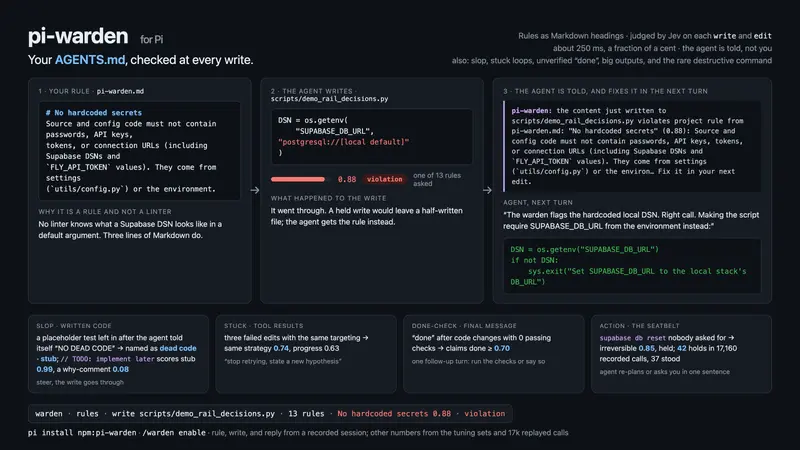
Guardrails for the Pi agent built on pi-typesafe. Jev judges irreversible and off-task tool calls, detects stuck loops, checks unverified completion claims and flags low-quality output, steering the agent rather than interrupting the user.
 DevMortimerOpenpi-warden on github.com
138 starsHolds per 1000 calls 3
A grep that matches lines by meaning instead of regular expressions: Jev scores each line against a plain-language description and the tool applies a threshold, combining meanings with AND, OR and NOT.
134 starsBatch speed <1s/210 lines
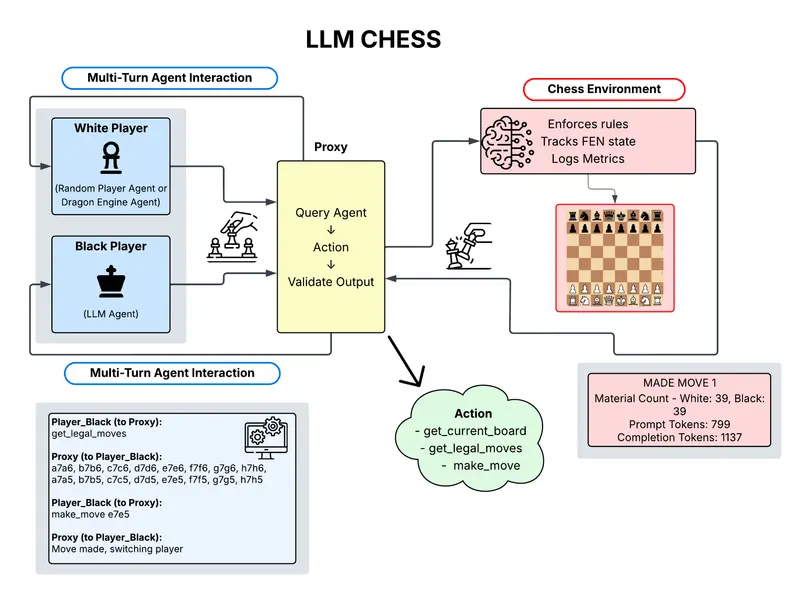
A benchmark that has language models play chess against a random-move player and the Komodo Dragon engine, scoring both chess skill and whether the model keeps making legal moves without hallucinating.
Rust CLI that hands an agent's live session context to Jev, which compares the available skills and estimates which fit the next step. Ships Claude Code hooks, structured JSON, abstention, a terminal display and local feedback.
Command-line toolkit a coding agent can delegate judgment work to: ranking relevant files, checking a diff against its task and project rules, and triaging test failures or review comments. Each request runs one bounded typed workflow and returns a structured report.
Scores source-file quality by asking Jev a set of yes/no questions, runs the test command you already use, and turns uncovered paths into small queries a coding agent can work through. Scoring costs about a cent per megabyte of source; coverage needs no account, config file or hosted service.
 supercorp-aiOpensupercorp-ai/supercov on github.com
109 starsScoring cost ~1c/MB
Fish-style autosuggestions for zsh ranked by Jev. As you type, the plugin sends your last 100 distinct history entries and asks which one you are most likely completing, then shows the best match in grey with its score for you to accept.
Small type-safe client for asking questions about your data, powered by Jev. Returns probabilities, choices and scores in a single request, and ships an agent skill that teaches coding agents how to design the questions.
Standalone C++ inference for Laya's typed decisions using ggml, with CUDA and Vulkan backends, a Jev-compatible /v1/systemone HTTP server, and automatic request batching.
 lkarlslundOpenlaya.cpp on github.com
85 starsCUDA BF16 speedup 1.11-2.71x
Pre-alpha PostgreSQL extension that calls TypeSafe Jev from SQL for Choice, Noul and Score, including a batched function that classifies many distinct rows in one request.
 giuliosmallOpengiuliosmall/pg_typesafe on github.com
82 starsOne-by-one time 23sBatched time 0.86s
Browser automation where an LLM plans and Jev decides each tactical action, executed through Playwright without feeding page snapshots to the LLM. README reports 40/42 tasks passing and roughly 5x less token context.
 Ying-Kai-LiaoOpenYing-Kai-Liao/jev-browser on github.com
82 starsTask accuracy 40/42Checkout time ~14s
A Python evals and guardrails library for agent traces that uses Jev-style decision models instead of an LLM judge, running Jev through TypeSafe or Vercel, or Kev or Laya locally on a Mac. All checks for a trace go out as one request in a few hundred milliseconds.
 openlayer-aiOpenjevals on github.com
81 starsVariance vs LLM 92-913x
A Claude Code hook that splits large tool results into blocks and asks Jev a yes/no relevance question per block, replacing low-relevance blocks with a short recoverable stub before they enter context.
Adds a bounded decision loop to Codex Computer Use: Codex prepares the goal and allowed actions, Jev selects the operation and target in one request, and Computer Use performs the click.
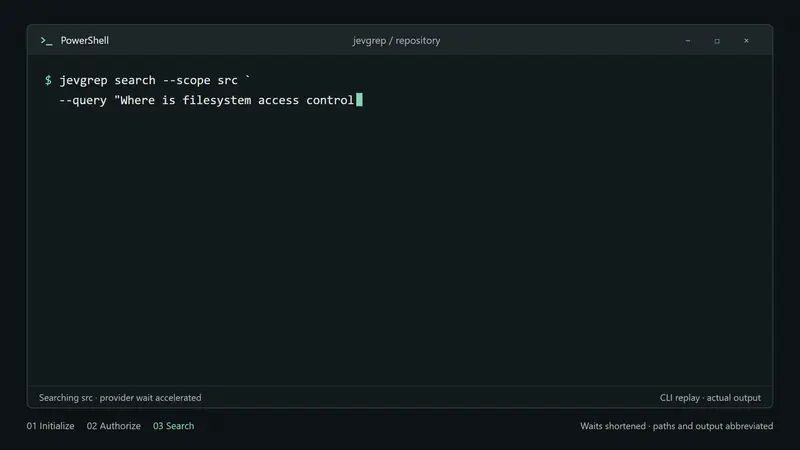
Semantic code search for coding agents: it scans an authorized repository, asks Jev to score all eligible fragments against a plain-English question, and returns the original source excerpts with their paths and line numbers.
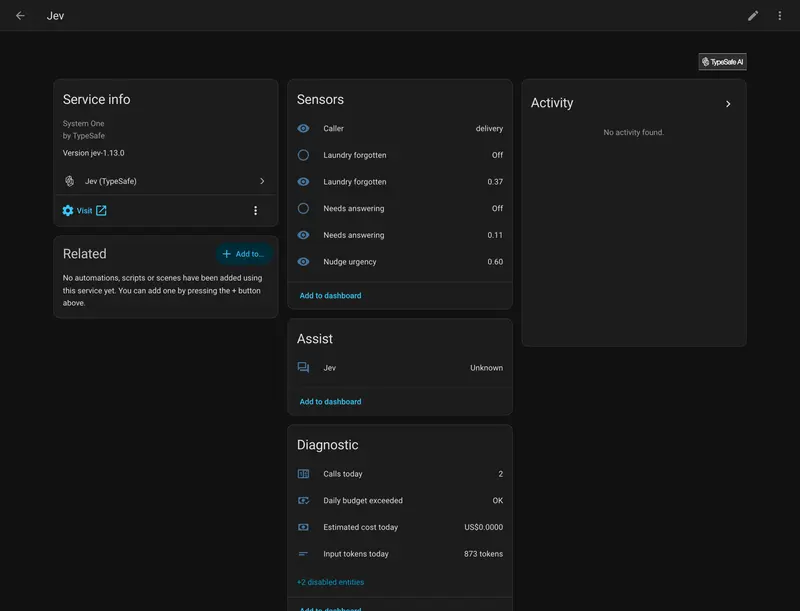
Unofficial Home Assistant integration that asks Jev questions about your house and turns each answer into an entity you can automate on. Questions in configuration.yaml become sensors, and four actions answer inside an automation and return a response variable.
Swift 6 bridge that maps Apple Foundation Models @Generable types onto Jev: Bool to noul, enum to choice, and @Guide range to score.
A Python CLI that turns Jev calls into Unix-pipeline predicates, routing, scoring and JSONL filtering with stable exit codes, plus an agent-safety guard recipe for authorization and destructiveness checks.
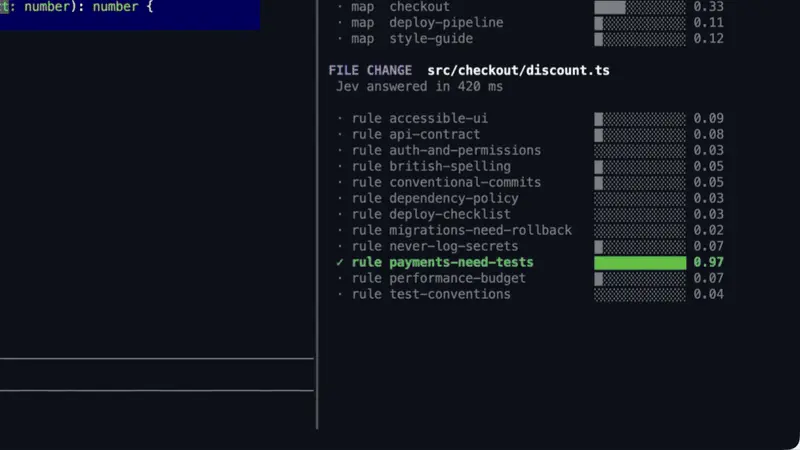
Uses Jev to pick which of your project's rules apply to a given prompt, so Claude only sees the relevant ones.
Rust and Python dataset sifter that streams Parquet and JSONL rows past Jev typed decisions at 1,500+ records per second, writing passed and rejected rows to disk. Uses speculative fan-out and calibrated post-training rubrics.
Adds semantic tool routing, skill discovery and typed Choice, Noul and Score judgments to the Pi coding agent. Opt-in modes pick the model per prompt and use Jev to decide which tool history survives compaction.
Nothing matches those filters
Clear a filter to widen the search, or send us the thing you were looking for.


