supercorp-ai/supercov on GitHub
- Stars
- 109
- Forks
- 5
- Language
- Rust
- License
- MIT
- Last push
- 24 Sep 2026
Read from GitHub on . Counts change daily.
Reported by the author
- Scoring cost
- ~1c/MB
a megabyte of source costs a little over a cent
github.com
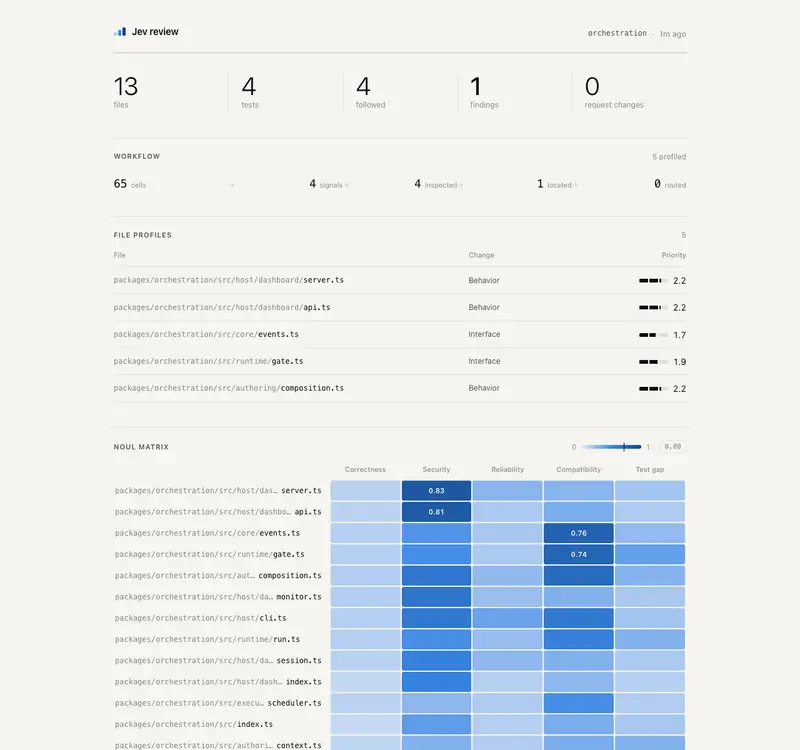
Supercov tells a coding agent what to test and what to fix, without a hosted service or account beyond a TypeSafe API key for the scoring step. It scores source files by asking Jev a set of yes/no questions about each one and doing the arithmetic itself, so every part of a resulting score traces back to a question you can check against the actual file. Separately, it runs whatever test command the project already uses and turns the paths that command doesn’t cover into small, focused queries an agent can work through one at a time.
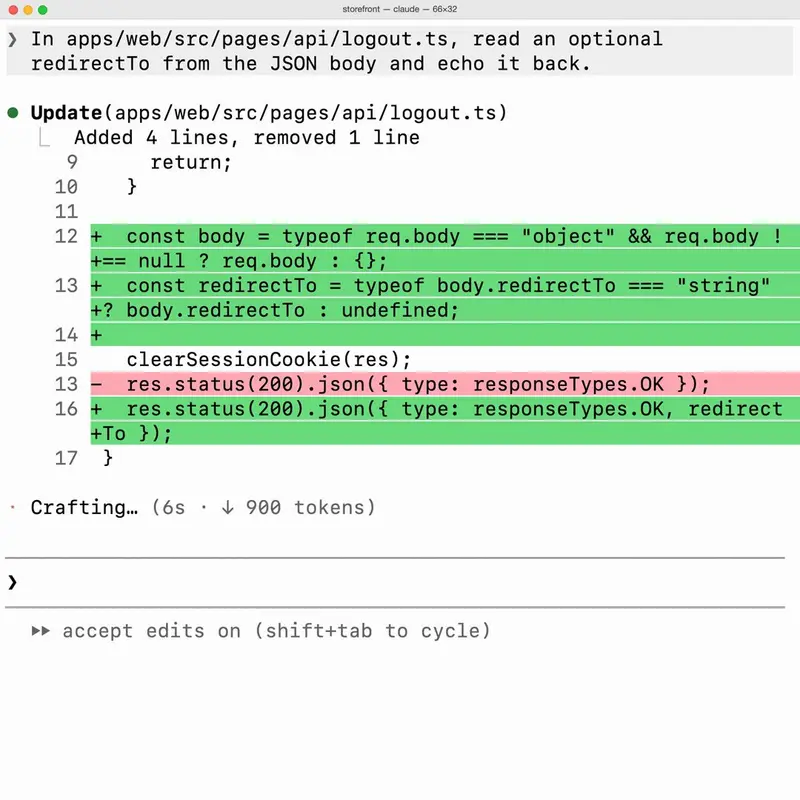
The intended loop hands both outputs to a coding agent: pick a target, write a focused test or refactor, rerun the suite, and prove what improved before moving to the next target. Supercov itself changes nothing in the project’s source, tests or runner configuration.
Jev is billed only for what it reads, not what it writes, so scoring costs a little over a cent per megabyte of source, and answers are cached by content so a second run only pays for what changed. It’s a single local binary, MIT licensed, with support for JavaScript, TypeScript, Rust, Python, Ruby, Go, Java and Kotlin.