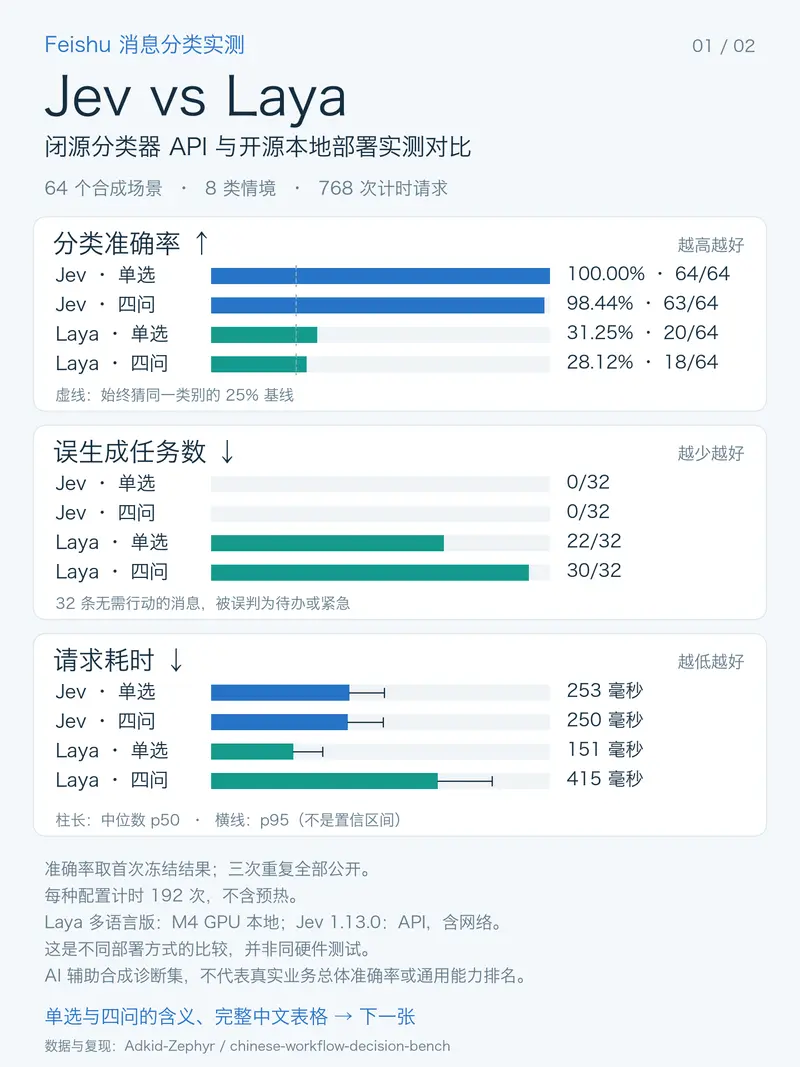
Adkid-Zephyr/chinese-workflow-decision-bench on GitHub
- Stars
- 1
- Forks
- 0
- Language
- Python
- License
- MIT
- Last push
- 21 Sep 2026
Read from GitHub on . Counts change daily.
How it uses Jev
 client=httpx.Client(headers={'Authorization':'Bearer '+key.strip()},timeout=60);key=None
 metadata['model']='jev-1.13.0';metadata['httpx']=httpx.__version__
 def call(req):
  start=time.perf_counter();response=client.post('https://api.typesafe.ai/v1/systemone',json={**req,'model':'jev-1.13.0'})
  if response.status_code!=200:raise RuntimeError('HTTP '+str(response.status_code))
  result=response.json();ms=(time.perf_counter()-start)*1000
  return {k:result[k] for k in ['model','answers','usage'] if k in result},ms,{}
else:
 if not args.checkpoint:raise SystemExit('--checkpoint must point to a locally downloaded multilingual checkpoint')
 os.environ.update(HF_HUB_OFFLINE='1',USE_TF='0',USE_TORCH='1',TOKENIZERS_PARALLELISM='false')
 import torch,transformers,laya
 from laya.common import build_sequence,serialize_state
 torch.set_num_threads(2);start=time.perf_counter();model=laya.load(args.checkpoint,device=args.device)
 metadata.update(model='convaiinnovations/laya/multilingual',checkpoint_revision='1c5edc17a7acd8701df6fc341c0d179f1c62c982',checkpoint_config=model.cfg,load_seconds=time.perf_counter()-start,torch=torch.__version__,transformers=transformers.__version__,device=str(model.device),cpu_threads=2,hardware='Apple M4 MacBook Air, 32 GB unified memory',laya_source_commit='ef7d7d269e2e34c763c228144dc10fe7d421acf9')
def call(req):Use casesSupport inbox triage