Open source, self-hosted. There is no hosted API. You download the weights and run them on your own hardware. How open-source models are listed.
What Laya is
Laya is a System One model from Convai Innovations, an Indian company led by CEO Nandakishor M, who publishes the code. It reads a state, which can be text, an email, a ticket or a JSON document, and answers typed questions about it: Choice, Score and Noul, the same three shapes Jev uses. Every question in a call is answered in one forward pass, and nothing is generated, so there is no output to parse.
Unlike Jev, Laya is not a hosted API. It ships as Apache 2.0 weights on Hugging Face and a Python package, pip install laya, and runs on your own GPU or CPU.
How it is built
Laya is an encoder with a decision head on top. The English checkpoint fully fine-tunes ModernBERT-large (395M parameters) and adds a head trained from scratch: two transformer layers, a scorer that reads one [MASK] token per option, and an act-or-escalate output. That comes to 421M parameters. The multilingual checkpoint uses mmBERT-base and comes to 322M. Options are defined per request, so a new question schema needs no retraining.
Training uses what Convai also calls RLCD. The reward is a strictly proper scoring rule, so reporting honest probabilities earns the most reward, and updates use REINFORCE with a group-mean baseline. TypeSafe has not published its recipe. Convai has, along with a fine-tuning notebook that takes 4 to 5 hours on Kaggle’s free pair of T4 GPUs.
A Router picks between the checkpoints by detecting the script and language before the forward pass. The English checkpoint fails on other scripts without losing confidence: on Khmer it scored 0.000 at 0.952 confidence.
What it is good at
Its strengths are speed and ownership. Convai measures 32.8ms for one question on a T4, and you can keep, inspect and retrain the weights. After fitting a temperature per question type on held-out data, its calibration error falls from 0.466 to 0.081. The package ships ready-made question sets for model routing, prompt guardrails, moderation and ticket triage.
The Jev Decision Index by multimodalart tests Laya zero-shot across a broad suite. Its edition 0.4.1, in the file generated on 22 October 2026, ranks entries by a Full score built only from private tests, 60% on the same skills and 40% in new domains, on a scale where 0 is random guessing and 100 is perfect. Laya scores 9.21 against Jev 1.14’s 60.24, close to random guessing, and 6.19 against Jev 1.14’s 60.7 on the public benchmarks alone. The headline changed in 0.3 and again in 0.4, so these numbers do not compare with the 0.2.1 figures this page gave before, or with the 0.3.1 Full score of 4.43. That fits Convai’s own advice to specialise it on your task rather than use it zero-shot.
What it is not for
The base checkpoints are close to chance on the typed-decisions benchmark without fine-tuning: 0.362 against a 0.318 random baseline. Convai’s own README calls Laya “a fast base to specialise, not a zero-shot decision engine.” Score questions are its weakest type, and large label sets need extra configuration. Probabilities are over-confident until you fit temperatures on your own data.
Convai’s comparisons with Jev set its own numbers against Jev figures published by third parties, not measured in the same run, so treat the head-to-head as indicative.
Specifications
| System One Score | 25.5 from 2 of 3 boardsJev Decision Index 12.9, JevBench 38.1. How the score works |
| Question types | ChoiceScoreNoul |
| Max Choice options | Not documented |
| Score levels | Not documented |
| Questions per call | Not documented |
| Total context | 512 tokens |
| State budget | 320 tokens |
| Rate limit | None. It runs on your own hardware. |
| Licence | Apache-2.0 |
| SDKs | Python: laya |
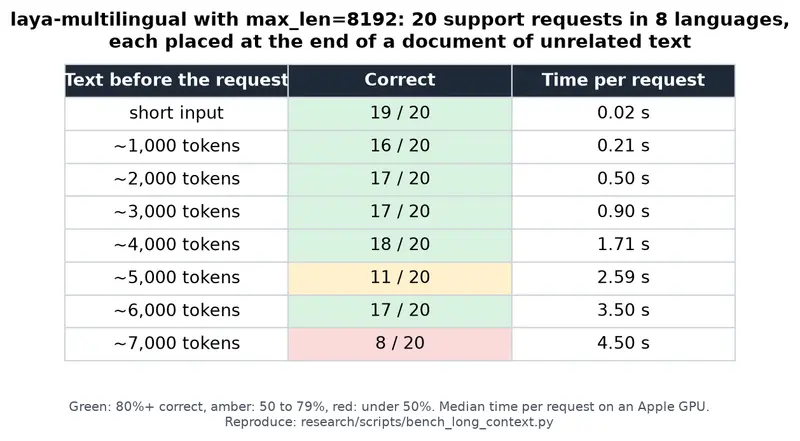
The English checkpoint defaults to 512 tokens, 192 of them reserved for the question and its options, leaving about 320 for the state. laya-multilingual and laya-typed-decisions default to 1,024 tokens with 256 for options. The mmBERT encoder under the multilingual checkpoint accepts up to 8,192 if you raise max_len. There is no hard cap on Choice options, but they share the option budget: 77 labels get about 3 to 4 tokens each, and Banking77 accuracy falls to 0.425. Raise head_max_len or shortlist with predict_shortlist for large label sets.
Versions
- convaiinnovations/laya, 18 Sep 2026, English checkpoint at the repo root. ModernBERT-large encoder, 421M parameters, 512-token context. Release notes
- convaiinnovations/laya-typed-decisions, 18 Sep 2026, The same 421M English model fine-tuned on the typed-decisions benchmark's training split, with a 1,024-token context. Release notes
- convaiinnovations/laya-multilingual, 19 Sep 2026, mmBERT-base encoder, 322M parameters, 1,024-token context, for text outside English. Release notes
Use cases
What people use Laya for, one page per pattern.
Support inbox triage with System One models
Send a support ticket to Jev once with every question attached. Category comes back as a selected label, severity and frustration as numbers on scales you wrote, refund intent as a probability. Your code reads those values and decides what happens to the ticket.
Intent and model routing with System One models
One Jev call reads an incoming request and returns its intent as a label plus a difficulty rating on a scale you wrote. Your router reads both numbers and picks the handler: deterministic code, a cheap model, an expensive one, or a human queue.
LLM guardrails with System One models
Put one Jev request in front of an LLM and one behind it. Yes/no questions return the probability that each hazard holds, a Score rates how much harm complying would do, and your thresholds turn those numbers into pass, review, block, or a crisis path.
Confidence-gated actions with System One models
Jev returns a confidence value from 0 to 1 alongside every Choice and Score answer. Your code treats it as a separate axis: act automatically when it's high, confirm or flag when it's middling, hand the decision to a person when it's low. Riskier actions get higher bars.
Examples built with Laya
The most-starred and most-viewed entries in the directory. All 106 Laya examples.
Introducing Clef: our open-source decision models, and new RL fine-tuning platform
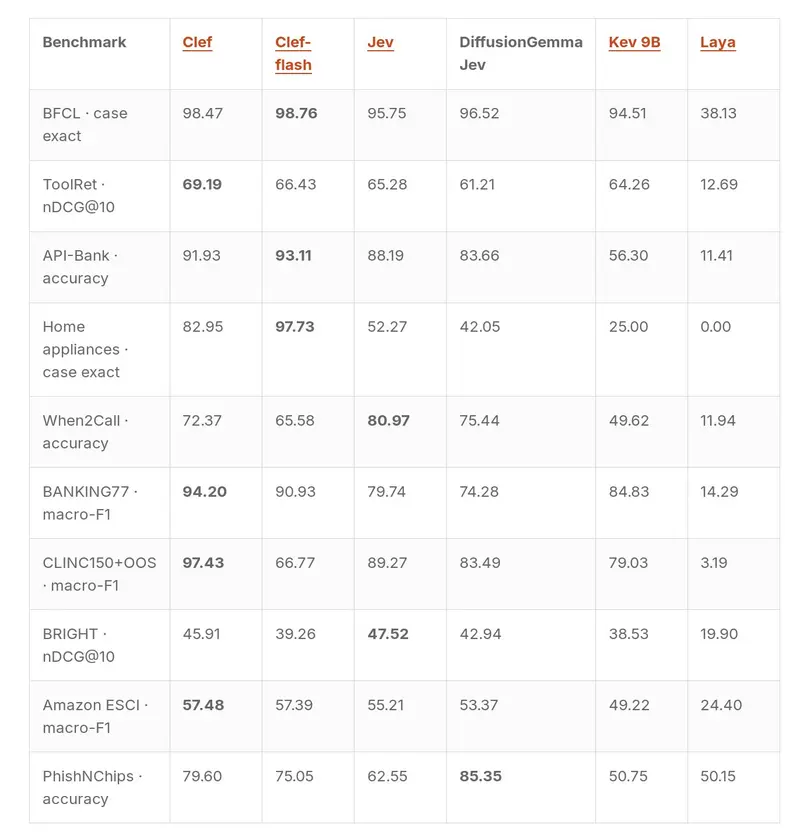
Cloudflare's launch post for Clef and Clef-flash, two decision models on Workers AI that accept the Jev request format and open weights under Apache 2.0. It covers the architecture, Cloudflare's own benchmark tables against Jev, Kev and Laya, and a new reinforcement learning service.
 Michelle Chen (@michellechen)140k viewsOpenIntroducing Clef: our open-source decision models, and new RL fine-tuning platform on blog.cloudflare.com
Decision Model Leaderboard
Cloudflare's live leaderboard for decision models on the Jev Decision Index suite, with Clef, Clef-flash, Jev, Kev-9B and Laya plotted by score and latency. Cloudflare built and ran it, so treat the ranking as vendor-run.
 Cloudflare (@ritakozlov)41k viewsOpenDecision Model Leaderboard on clef-evals.workers-ai-mle.workers.dev
NandhaKishorM/laya
Decision model from Convai Innovations that fully fine-tunes an encoder and adds a typed-decision head: a 421M English checkpoint on ModernBERT-large and a 322M multilingual one on mmBERT-base, with a router picking between them by detected language. Returns choice, score and noul answers, and reports expected calibration error of 0.081 after temperature fitting, down from 0.466 as shipped.

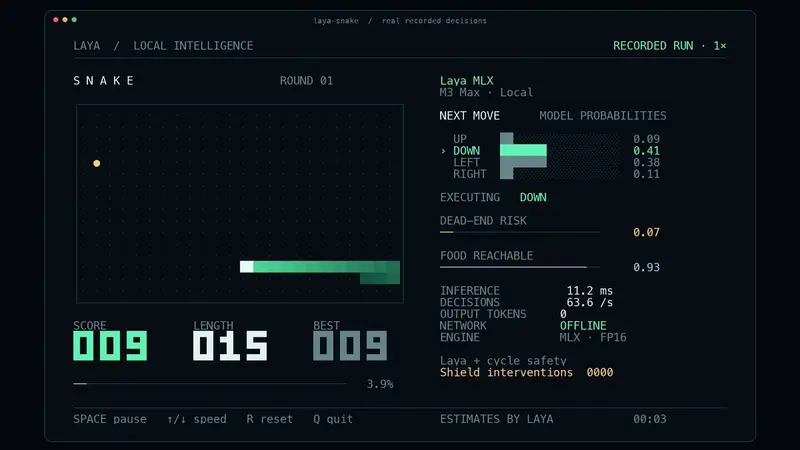
Laya-MLX
An independent MLX port of Laya for Apple Silicon, 13.4ms median for a short English decision and 7.4ms on the multilingual checkpoint, with a Snake demo that plays at up to 75 moves per second under 1GB of memory.
 mizorewwwOpenLaya-MLX on github.com
6.1k starsShort decision 13.4 ms P50Snake demo 75.4 moves/s
Laya-CoreML
Core ML ports of all three Laya checkpoints for Apple Silicon, reaching 4.98ms P50 on the Neural Engine for a short multilingual decision, with a Snake demo sustaining about 50 decisions per second.
 mizorewwwOpenLaya-CoreML on github.com
1.4k starsShort decision 4.98 ms P50Snake demo 49-50 dec/s
@receptron/laya
Node.js and TypeScript package that runs the Laya decision model through ONNX Runtime, so JavaScript projects can call it without Python.
 receptronOpen@receptron/laya on github.com
374 stars3-question call ~140 msModel size ~1.7 GB
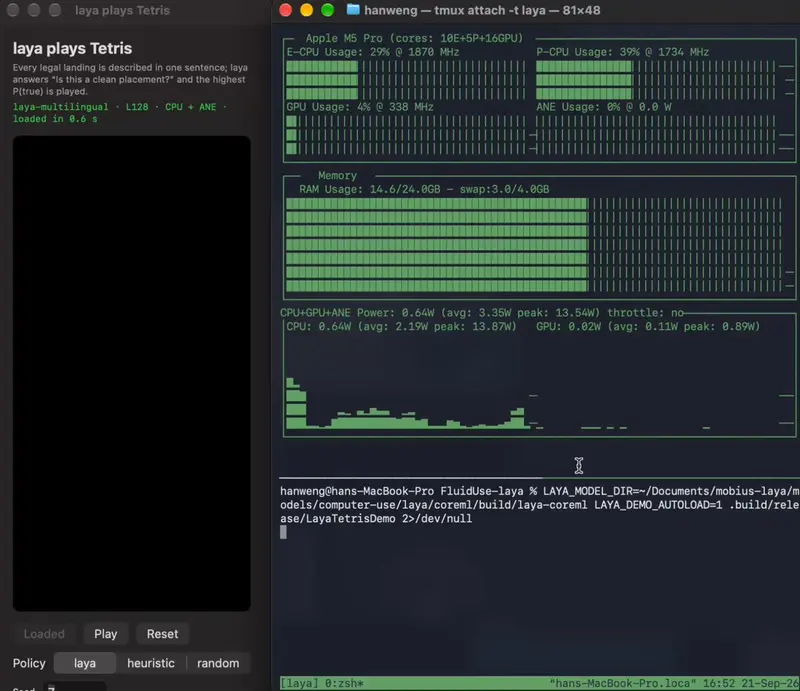
FluidUse
A Swift package for local computer use on Apple Silicon that reads a form through the Accessibility API and asks a small on-device model what belongs in each field. Its Laya integration runs FluidInference's Core ML port of Laya on the Neural Engine at 3.7 ms per decision on an M5 Pro, about seven times faster than the upstream GPU figure.
 FluidInferenceOpenFluidUse on github.com
152 starsPer decision 3.7msSpeedup ~7x faster
Laya Ultrafast
A local, open-weight port of browser-use's jev-ultrafast agent that swaps Jev's hosted decisions for Laya running on Apple Silicon through MLX, while keeping the original hosted Jev policy as a fallback mode.
 ipenywisOpenLaya Ultrafast on github.com
145 starsDecision latency ~33ms
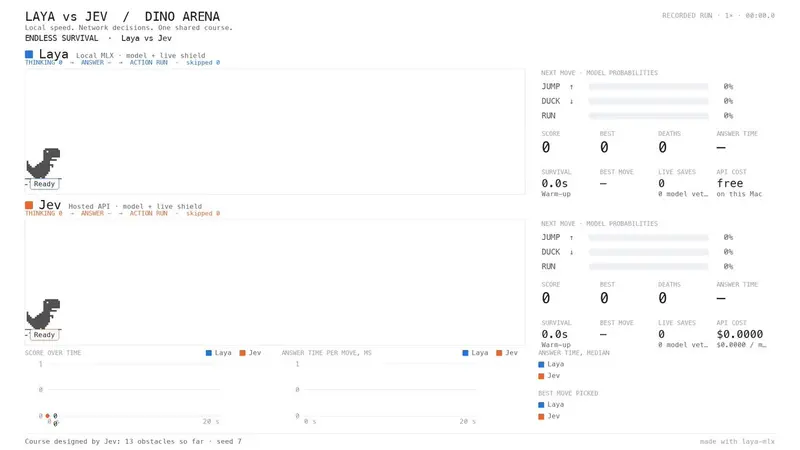
Laya vs Jev: T-Rex Race
Laya, running locally on Apple Silicon via MLX, and Jev, over TypeSafe's hosted API, play Chrome's T-Rex game side by side on a shared obstacle course, with response times, survival streaks and crash replays recorded.

laya.cpp
Standalone C++ inference for Laya's typed decisions using ggml, with CUDA and Vulkan backends, a Jev-compatible /v1/systemone HTTP server, and automatic request batching.
 lkarlslundOpenlaya.cpp on github.com
85 starsCUDA BF16 speedup 1.11-2.71x
jevals
A Python evals and guardrails library for agent traces that uses Jev-style decision models instead of an LLM judge, running Jev through TypeSafe or Vercel, or Kev or Laya locally on a Mac. All checks for a trace go out as one request in a few hundred milliseconds.
 openlayer-aiOpenjevals on github.com
81 starsVariance vs LLM 92-913x
Chat Seek
A VS Code extension that finds past Claude Code, Codex and OpenCode conversations from a plain-language description, using a local Laya model to rerank the keyword search results.

Benchmarks
Published scores, each linked to its source. A row marked vendor-run was measured by the vendor itself, so read it as one side's result. The compare hub sets these beside the other models.
| Benchmark | Metric | Score | Run by | Date |
|---|---|---|---|---|
| Jev Decision Index 0.4.1 | Full score | 9.21 score | Independent | 22 Oct 2026 |
| Jev Decision Index 0.4.1 | Public score | 6.19 score | Independent | 22 Oct 2026 |
| Jev Decision Index 0.4.1 | Expected calibration error | 0.1402 ECE | Independent | 22 Oct 2026 |
| JevBench 1.7.46 | Capability Score | 32.5 score | Independent | 12 Oct 2026 |
| Jev Decision Index 0.3.1 | Full score | 4.43 score | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Public score | 6.19 score | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Expected calibration error | 0.1402 ECE | Independent | 10 Oct 2026 |
| Convai README benchmarks | ECE after temperature fitting | 0.081 ECE | vendor-run | 18 Sep 2026 |
- Jev Decision Index, Full score: Row: Laya. Counts 60% private same-skill tests and 40% private new-domain tests; public benchmarks no longer count. 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: Laya.
- Jev Decision Index, Expected calibration error: Row: Laya. Lower is better.
- JevBench, Capability Score: Row: Laya. Intelligence 1.8, Calibration 63.2. Benchmark Heaven also lists Laya typed-decisions (44.2) and Laya multilingual (17.0). The board re-measures rows, so this can differ from earlier editions.
- Jev Decision Index, Full score: Row: Laya. Counts 20% public benchmarks and 80% private tests; 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: Laya.
- Jev Decision Index, Expected calibration error: Row: Laya. Lower is better.
- Convai README benchmarks, ECE after temperature fitting: Convai measured it; calibration error was 0.466 before fitting a temperature per question type on held-out data.
Comparisons
Head-to-head pages that put Laya against other models. Every model sits in one table on the compare hub.
Jev vs Laya: hosted decision model or open weights?
Jev is TypeSafe's hosted decision model at $0.042 per million input tokens. Laya is open weights you run yourself. Price, context, latency and Jev Decision Index scores.
Updated