 Play the video in the post below
FluidInference/FluidUse on GitHub
- Stars
- 152
- Forks
- 12
- Language
- Swift
- License
- Apache-2.0
- Last push
- 23 Sep 2026
Post on X
- Views
- 113,824
- Likes
- 1,320
- Reposts
- 111
Read from GitHub and X on . Counts change daily.
Reported by the author
- Per decision
- 3.7ms
3.7 ms per decision on an M5 Pro
x.com - Speedup
- ~7x faster
about 7× faster than the ~27 ms upstream reports on an M1 Max GPU
github.com
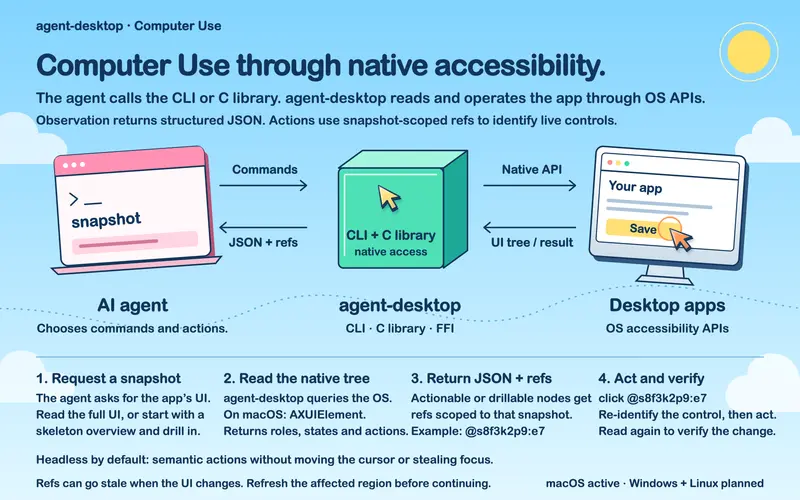
FluidUse is a Swift package for filling in forms in Mac apps and browser pages without sending anything off the machine. It reads a form through macOS’s Accessibility API, the same interface screen readers use, and for each field asks a small on-device model what belongs there, then types the answer into the real app. The first model plugged in is CUA-S1-FORMS, a 706K-parameter form specialist, converted to Core ML.
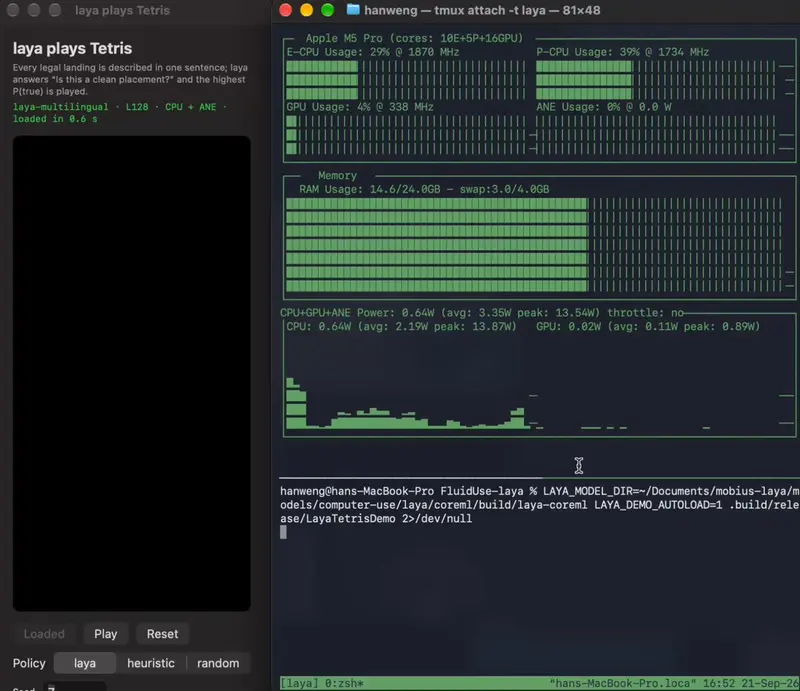
FluidUse also runs Laya, an open Jev-style decision model built by Convai Innovations: a 322M-parameter mmBERT encoder plus a decision head that answers choice, score, and noul questions about a text state with calibrated probabilities in one pass, with no generated tokens. FluidUse’s LayaManager runs Laya’s Core ML buckets, sized at 128, 256, 512, or 1024 tokens with 32 options, on the Neural Engine, and each prompt runs on the smallest loaded bucket that fits. On Laya’s own published suites, rebuilt from the original scripts into 3,899 questions, the Core ML version matches the accuracy of the PyTorch reference on every suite.
In the release post, FluidInference reports 3.7ms per decision on an M5 Pro with 99.5% of the ops on the Neural Engine. The README puts that at about 7 times faster than the roughly 27ms the upstream Laya project reports on an M1 Max GPU. The README also sets limits: the form model matches a field to a value it is given, does not write free text, and never clicks Submit unless that is enabled.