Post on X
- Views
- 59,552
- Likes
- 970
- Reposts
- 62
Read from X on . Counts change daily.
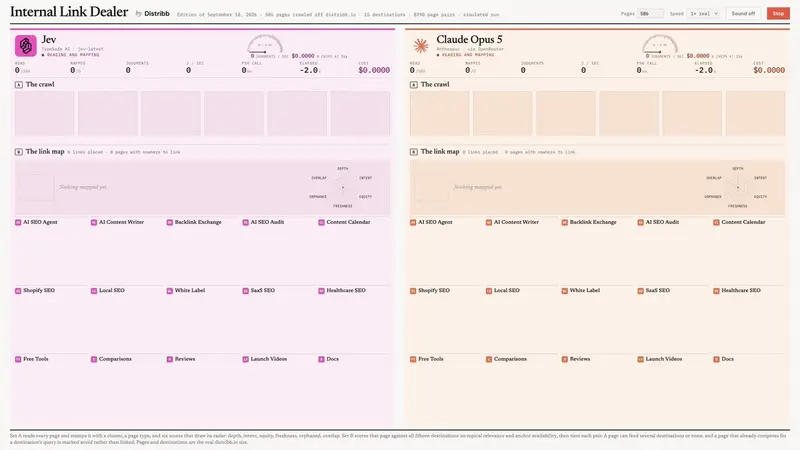
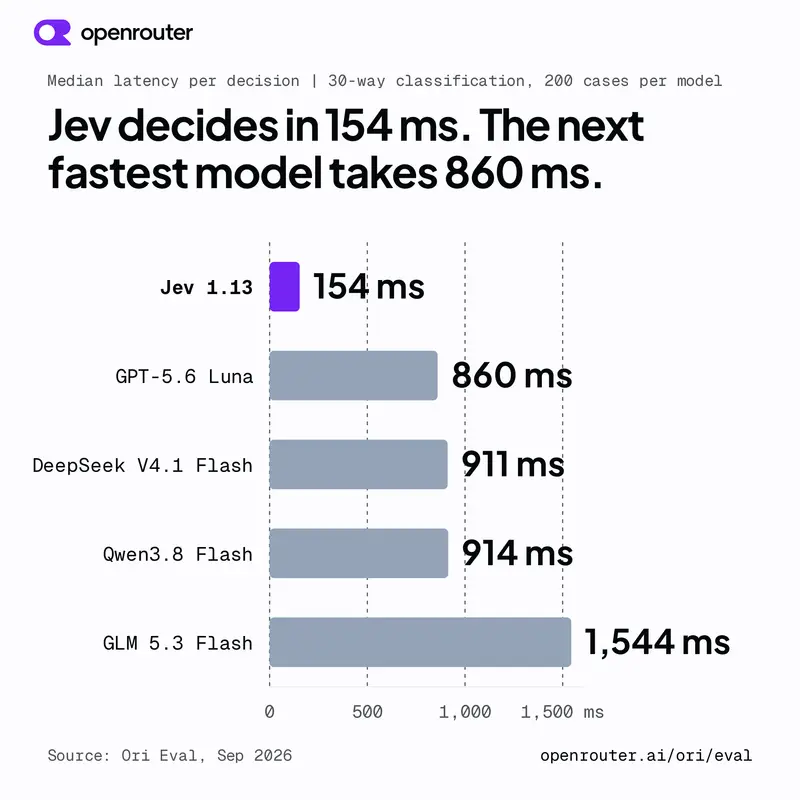
OpenRouter used Ori Eval, its tool for comparing models on a specific use case, to test Jev against four popular LLMs on a judging task. According to the thread, each model read incoming requests and labeled each one as one of 30 task types. All five ran the same 200 synthetic cases, evenly spread across the types, sequentially and without shared state. Reasoning was off for the LLMs except GLM 5.3 Flash, which requires it and ran at low effort.
The chart shows median latency by model: Jev at 154 milliseconds, against 860 for GPT-5.6 Luna, 911 for DeepSeek V4.1 Flash, 914 for Qwen3.8 Flash, and 1,544 for GLM 5.3 Flash. OpenRouter says Jev was over 5 times faster than the next fastest model, and that even its slowest requests beat every other model’s median.
On accuracy, the thread says Jev matched the LLMs, with all five within a handful of cases of each other. On cost, Jev came in second cheapest, just behind Qwen3.8 Flash. DeepSeek and GLM used default provider routing, so their tail latency reflects a mix of providers.