 Play the video in the post below
Post on X
- Views
- 42,569
- Likes
- 312
- Reposts
- 52
multimodalart/jev-decision-index on Hugging Face
- Likes
- 232
Read from X and Hugging Face on . Counts change daily.
A leaderboard that runs Jev and 54 open System One models and clones through the same 120,000-question suite on one RTX PRO 6000, scoring accuracy and calibration. Jev leads the 0.2 edition at 51.67 on a chance-corrected scale, with AutoJev-27B close behind at 50.94.
Play the video in the post belowRead from X and Hugging Face on . Counts change daily.
AI News daily roundup leading with the Jev launch, summarising RLCD and TypeSafe's 20-200x speed and 40-400x cost claims. Its recap of reactions notes posters using Jev as a structured classifier, judge and routing policy where text generation is unnecessary.
Argues Jev's speed comes mainly from constrained single-token generation and aggressive prefill, techniques reproducible with existing LLMs, rather than a new architecture. Still treats very fast structured output as a new primitive, while doubting Jev matches frontier models on raw intelligence.
An independent, evidence-based map of where Jev's calibrated-decision claim holds up and where it breaks down, built from real API-call receipts rather than a leaderboard.
An adversarial evaluation of Jev with nine experiments and 28 predictions fixed before any data was collected. One run covered 123,805 requests over 138 minutes for $12.69, with five failures, plus a 13-rule prompting guide.
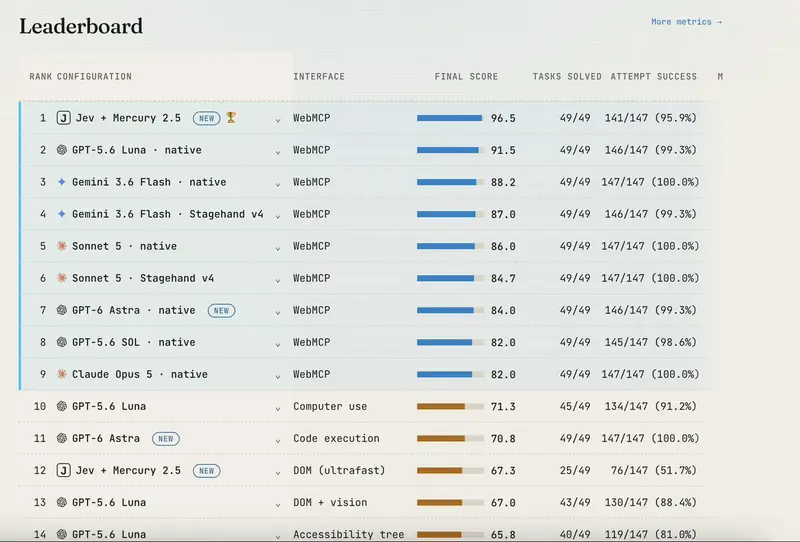
A 49-task, 8-site browser-agent benchmark. Jev paired with a small model for argument generation solved 100% of tasks at far lower cost than screenshot-based computer use, and adding WebMCP tool exposure roughly doubled Jev's own solve rate from 25 to 49 tasks.
 idan levin (@0xidanlevin)OpenWindTunnel: the WebMCP benchmark on webmcp.com
239k viewsSolve rate 25/49 to 49/49Cost vs Astra 112x lower
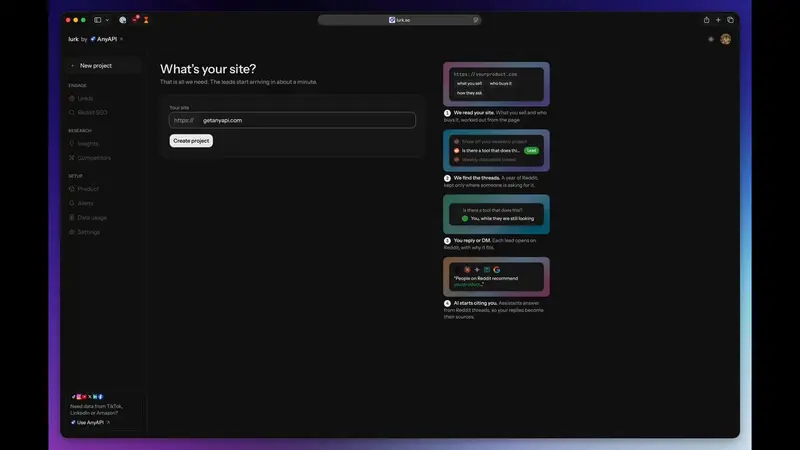
Find Reddit buyer intent and see what every lead's data cost.
 Kevin Wang (@mxfp4)Openlurk by AnyAPI on lurk.so
84k viewsThreads scanned 4,000

