Open source, self-hosted. There is no hosted API. You download the weights and run them on your own hardware. How open-source models are listed.
What Kev is
Kev is a family of open-source System One models published by Jared Palmer. It reads a state and answers typed Choice, Score and Noul questions about it with probabilities, the same three shapes Jev uses. You download the weights from Hugging Face and run them on CUDA, ROCm or Apple Silicon through MLX, or call Kev-4B on OpenRouter. The 27B model needs an 80 GB data-centre GPU and has no Mac path.
The server exposes POST /v1/systemone with the same request and response shape as TypeSafe’s API, so the typesafe-sdk Python client works once you point base_url at your own machine. The repo also ships a Modal script that deploys Kev-4B to an L40S behind a bearer key, and a Hugging Face Space runs Kev-4B and Kev-0.8B in the browser.
OpenRouter added Kev-4B on 25 September 2026, hosted by SiliconFlow in fp8. It costs $0.042 per million input tokens with free output and an 8,192-token context, the same price as Jev. OpenRouter says it takes the same request as Jev, so switching means changing the model field to jaredpalmer/kev-4b. The 0.8B, 9B and 27B models are not hosted there.
How it is built
Each checkpoint is a rank-16 LoRA adapter plus a small pointer head on a Qwen base: Qwen3.5 at 0.8B, 4B and 9B, and Qwen3.8 at 27B. The head scores each option against a decision token at the end of its question, and a softmax turns those scores into probabilities. Questions share the state but cannot see each other.
Training is plain cross-entropy on 10,000 examples from ten public datasets, plus 896 generated policy examples and 1,680 from generated rule structures. The README says no Jev outputs were used. Kev-27B trains for one epoch on Kev-9B’s data, plus 1,400 records where the question sits among 1k to 6k tokens of unrelated text, and it uses soft targets where the right answer is genuinely ambiguous. Each checkpoint ships with a temperature fitted on in-distribution data, which changes the probabilities but never the answer.
The 0.8B, 4B and 9B models got a short second training pass on generated examples on 2026-09-21, with the earlier weights kept at revision v7-base. Kev-4B was updated again on 2026-09-24 after one epoch on consumer-finance complaints.
Kev-27B differs from the others in its base. The smaller models start from Qwen base checkpoints. Kev-27B starts from Qwen3.8-27B, Qwen’s post-trained release, and the README says its training data is unknown. Comparisons with Jev or with the smaller Kevs therefore do not test the method alone.
What its own evals show
These are the author’s numbers from the repo’s own benchmark, which also runs the Jev comparison. On datasets Kev was not trained on, Kev-9B scores 0.822 on the development set against Jev’s 0.857, and 0.852 on a test set Jev has not been run on. Kev-27B scores 0.848 on the development set, within a point of Jev, and 0.896 on the test set. On held-out examples from its training sources Kev-9B scores 0.872 against Jev’s 0.845, and Kev-27B 0.866. The README says this is not a controlled comparison, because Jev’s training data is unknown, and Kev-27B’s post-trained base adds a second unknown.
The first independent test is the Jev Decision Index by multimodalart. Its headline is a Full score. Since edition 0.4, on 19 October 2026, that score counts only private tests: 60% tests of the same skills and 40% tasks in new domains. Its numbers do not compare with the 0.2.1 figures this page gave before. In edition 0.4.1, in the file generated on 22 October 2026, Jev 1.14 scores 60.24 on the Full score and Kev 27B 59.56, 46th of 229 rows. The smaller Kev entries are named Kev 9B v2, Kev 4B r10 and Kev 0.8B r15, link to the same Hugging Face repos, and score 40.91, 34.93 and 16.30. On the public benchmarks alone, Kev 27B scores 56.69 against Jev 1.14’s 60.7. Expected calibration error, the average gap between stated confidence and actual accuracy, is 0.022 for Kev 27B, 0.045 for Kev 9B v2, 0.032 for Kev 4B r10 and 0.040 for Kev 0.8B r15, all below Jev 1.14’s 0.080. In the 0.3.1 file of 10 October 2026, Kev 27B scored 58.78, sixth of 117 rows.
Speed is self-reported too. Kev-4B on an L40S takes 41.5ms to 145ms of model time for a new state, depending on how many questions you ask and how long the state is. Kev-27B takes 46.5ms to 178ms on a B200 and 75ms to 278ms on an H100. The README’s sample request on an Apple M5 in bf16 came back in 495ms.
What it is not for
Knowledge questions are the widest gap: Kev-9B scores 0.74 on MMLU and Kev-27B 0.84, where Jev scores 0.90. Changing the order of options can change an answer. Training covered at most 384 state tokens, so long documents fall outside it even though the server accepts a 65,536-token state. The server handles one request at a time, and the Qwen3.5 models run slowly on a Mac. Kev-27B needs an 80 GB GPU, with 55 GB of weights and about 66 GB in use once the serving buffers are counted, and it has no Mac path.
Specifications
| System One Score | 87.9 from 2 of 3 boardsJev Decision Index 83.3, JevBench 92.6. How the score works |
| Question types | ChoiceScoreNoul |
| Max Choice options | 255 |
| Score levels | Up to 255 |
| Questions per call | Not documented |
| Total context | 8,192 tokens |
| State budget | Not documented |
| Rate limit | None when self-hosted, where the server handles one request at a time. OpenRouter does not publish a rate limit for Kev-4B. |
| Endpoint | POST /v1/systemone on your own server, or Kev-4B through OpenRouter |
| Licence | Apache-2.0 |
| SDKs | Python: typesafe-sdk |
The README says the server accepts a state of up to 65,536 tokens plus 8,192 for each question, but training used at most 384 state tokens and 1,024 for the state plus one question, so longer inputs fall outside what training covered. Kev-27B holds up better on long text: 0.833 on questions buried in 1k to 6k tokens of unrelated text, against 0.556 for Kev-9B. OpenRouter lists an 8,192-token context for Kev-4B. Choice takes 1 to 255 options and Score 1 to 255 levels. A request can carry any number of questions; the server runs them a 16,384-token row at a time, so memory does not grow with the question count.
Versions
- jaredpalmer/kev-0.8b, 21 Sep 2026, LoRA adapter and pointer head on Qwen3.5-0.8B-Base. Weights updated on 2026-09-21 with a second training pass on generated examples; the previous weights are at revision v7-base. Release notes
- jaredpalmer/kev-4b, 24 Sep 2026, The recommended starting point, on Qwen3.5-4B-Base. Updated on 2026-09-21 like the others, then again on 2026-09-24 with one epoch on 5,219 consumer-finance complaint narratives; the previous weights are at revision night2-du-release. OpenRouter serves this build as kev-4b-20260924. Release notes
- jaredpalmer/kev-9b, 21 Sep 2026, The most accurate Kev on a Qwen3.5 base. Updated on 2026-09-21; the previous weights are at revision v7-base. Release notes
- jaredpalmer/kev-27b, 24 Sep 2026, The most accurate Kev, a LoRA adapter and pointer head on Qwen3.8-27B, Qwen's post-trained release rather than a base checkpoint. Apache 2.0. It needs an 80 GB GPU (55 GB of weights in bf16, about 66 GB with serving buffers) and has no Mac path. Release notes
Use cases
What people use Kev for, one page per pattern.
Support inbox triage with System One models
Send a support ticket to Jev once with every question attached. Category comes back as a selected label, severity and frustration as numbers on scales you wrote, refund intent as a probability. Your code reads those values and decides what happens to the ticket.
Confidence-gated actions with System One models
Jev returns a confidence value from 0 to 1 alongside every Choice and Score answer. Your code treats it as a separate axis: act automatically when it's high, confirm or flag when it's middling, hand the decision to a person when it's low. Riskier actions get higher bars.
Examples built with Kev
The most-starred and most-viewed entries in the directory. All Kev examples.
Introducing Clef: our open-source decision models, and new RL fine-tuning platform
Cloudflare's launch post for Clef and Clef-flash, two decision models on Workers AI that accept the Jev request format and open weights under Apache 2.0. It covers the architecture, Cloudflare's own benchmark tables against Jev, Kev and Laya, and a new reinforcement learning service.
 Michelle Chen (@michellechen)140k viewsOpenIntroducing Clef: our open-source decision models, and new RL fine-tuning platform on blog.cloudflare.com
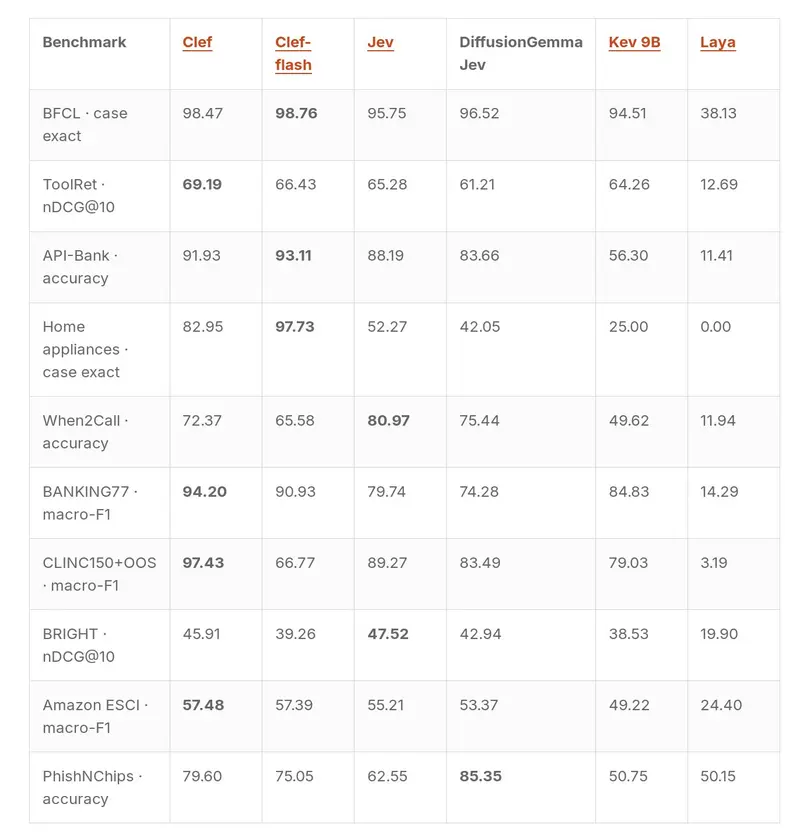
Decision Model Leaderboard
Cloudflare's live leaderboard for decision models on the Jev Decision Index suite, with Clef, Clef-flash, Jev, Kev-9B and Laya plotted by score and latency. Cloudflare built and ran it, so treat the ranking as vendor-run.
 Cloudflare (@ritakozlov)41k viewsOpenDecision Model Leaderboard on clef-evals.workers-ai-mle.workers.dev
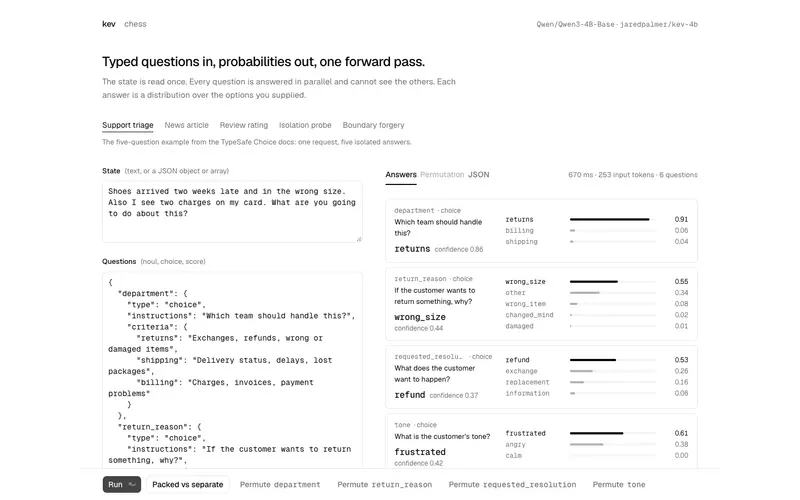
jaredpalmer/kev
A family of small, self-hosted decision models built on Qwen3.5 at 0.8B, 4B and 9B, with training code and an API that matches TypeSafe's System One so TypeSafe's own Python SDK can point at a local server.

jevals
A Python evals and guardrails library for agent traces that uses Jev-style decision models instead of an LLM judge, running Jev through TypeSafe or Vercel, or Kev or Laya locally on a Mac. All checks for a trace go out as one request in a few hundred milliseconds.
 openlayer-aiOpenjevals on github.com
81 starsVariance vs LLM 92-913x
kevala
Runs Laya and Kev decision models inside the browser: a zero-dependency Rust engine compiled to WebAssembly with WebGPU kernels, downloading a pinned int8 model pack and answering choice, score and noul questions with no server or API key.

Jev vs Laya on Moroccan Darija sentiment
A zero-shot benchmark of Jev, self-hosted Kev-9B and self-hosted Laya on 171 Moroccan Darija reviews in Arabic script and Arabizi. Jev scored 79.5 percent accuracy, Kev-9B 71.9 percent, and Laya 53.8 percent, tying an always-positive baseline.

Jev Decision Index: Jev against 50+ open decision models
A leaderboard that runs Jev and 54 open System One models and clones through the same 120,000-question suite on one RTX PRO 6000, scoring accuracy and calibration. Jev leads the 0.2 edition at 51.67 on a chance-corrected scale, with AutoJev-27B close behind at 50.94.
 apolinario (poli) (@multimodalart)43k viewsOpenJev Decision Index: Jev against 50+ open decision models on huggingface.co
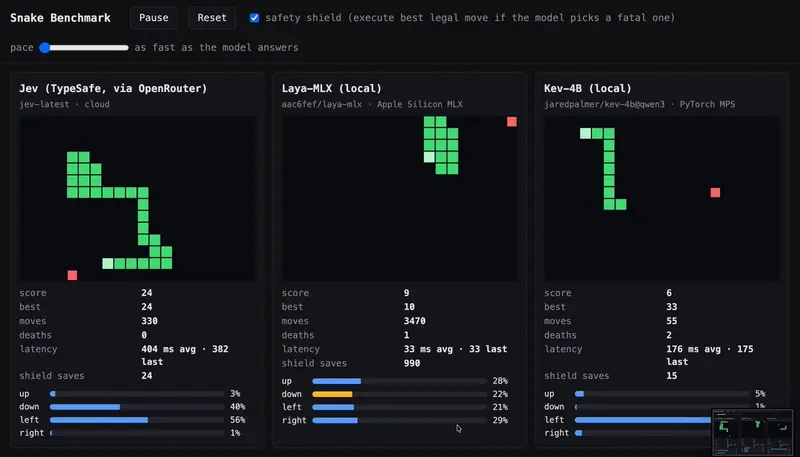
Home-Made Snake Benchmark: Jev vs Laya-MLX vs Kev-4B
Custom Snake benchmark comparing Jev over the API against locally run Laya-MLX and Kev-4B: Jev had zero deaths, Kev died twice at about 175ms latency, and Laya died early despite roughly 33ms latency.
 Tobias Wupperfeld (@tobiaswup)3.1k viewsOpenHome-Made Snake Benchmark: Jev vs Laya-MLX vs Kev-4B on x.com
JevBench by Benchmark Heaven: Jev-class decision model leaderboard
Benchmark Heaven's own leaderboard for Jev-class decision models, unrelated to the dhruvmehra/jevbench repo, ranking 106 of 112 systems on 1,624 choice, score and noul decisions each in release v1.5.4. Jev 1.13.0 leads on capability at 80.0, while on the four-axis composite that adds speed and cost, Cygnet and Winnow-12B Q8 tie first and Jev is third.
Benchmarks
Published scores, each linked to its source. A row marked vendor-run was measured by the vendor itself, so read it as one side's result. The compare hub sets these beside the other models.
| Benchmark | Metric | Score | Run by | Date |
|---|---|---|---|---|
| Jev Decision Index 0.4.1 | Full score | 59.56 score | Independent | 22 Oct 2026 |
| Jev Decision Index 0.4.1 | Public score | 56.69 score | Independent | 22 Oct 2026 |
| Jev Decision Index 0.4.1 | Expected calibration error | 0.0218 ECE | Independent | 22 Oct 2026 |
| JevBench 1.7.46 | Capability Score | 78.9 score | Independent | 12 Oct 2026 |
| Jev Decision Index 0.3.1 | Full score | 58.78 score | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Public score | 56.69 score | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Expected calibration error | 0.0218 ECE | Independent | 10 Oct 2026 |
- Jev Decision Index, Full score: Row: Kev 27B, 46th of 229 rows by this score. Counts 60% private same-skill tests and 40% private new-domain tests; public benchmarks no longer count. 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: Kev 27B.
- Jev Decision Index, Expected calibration error: Row: Kev 27B. Lower is better.
- JevBench, Capability Score: Row: Kev 27B. Intelligence 64.2, Calibration 93.7. The board re-measures rows, so this can differ from earlier editions.
- Jev Decision Index, Full score: Row: Kev 27B. Counts 20% public benchmarks and 80% private tests; 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: Kev 27B.
- Jev Decision Index, Expected calibration error: Row: Kev 27B. Lower is better.