Post on X
- Views
- 338
- Likes
- 2
- Reposts
- 0
Read from X on . Counts change daily.
PrimitivesChoice
Use casesIntent and model routing
Benchmarks Laya-MLX against Jev/Qwen3-4B inside an OpenClaw agent cascade on an M4 Pro: Laya scores 85% at 27.8ms, Jev scores 90% at 1,168ms, and 14 of 20 decisions resolve before reaching Jev.
Read from X on . Counts change daily.
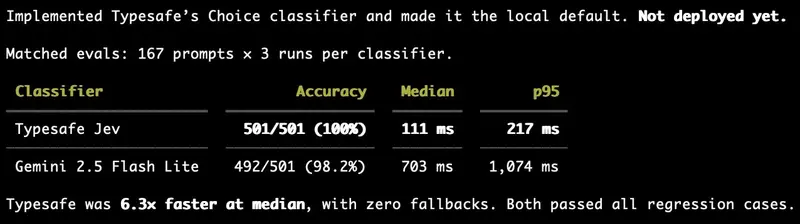
Vercel CTO reports Jev saturated an existing classifier eval that had used Gemini 2.5 Flash Lite and ran about 6x faster. Original post; TypeSafe's quote-tweet is a separate item.
 Malte Ubl (@cramforce)OpenRan Jev against an existing classifier eval that previously used Gemini 2.5 Flash Lite on x.com
220k viewsSpeed vs Gemini 6x faster
AI News daily roundup leading with the Jev launch, summarising RLCD and TypeSafe's 20-200x speed and 40-400x cost claims. Its recap of reactions notes posters using Jev as a structured classifier, judge and routing policy where text generation is unnecessary.
The 1,978-point, 513-comment launch thread. The top comment calls the speed comparison misleading, since Jev only returns structured output, and disputes the cannot-hallucinate claim because a valid type can still hold a wrong value. Others note ordinary LLMs can already be forced into structured output.
Declares typed input/output Signatures for LLM modules and optimizes the underlying prompts and weights against a metric. Its Signature abstraction is the closest widely-used open equivalent of Jev's typed-question interface. Star count is GitHub's rounded display figure.
Guarantees valid structured output during generation by constraining decoding to a grammar or schema. The mechanism HN commenters repeatedly cited as already covering Jev's cannot-produce-a-type-error guarantee on ordinary LLMs. Star count is GitHub's rounded display figure.
Pydantic-based library that extracts typed, validated structured data from LLMs across providers with automatic retries. The established way teams get Jev-style typed answers today, at LLM latency and cost. Star count is GitHub's rounded display figure.


