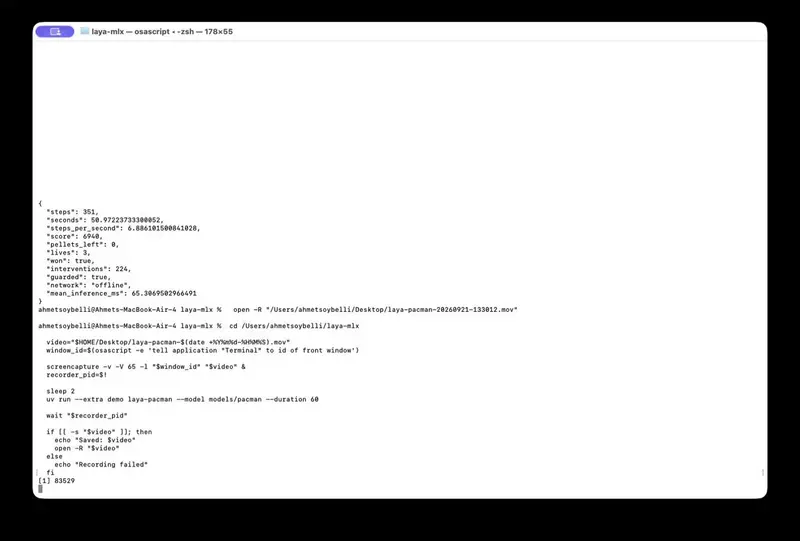
Pac-Man Wired to Laya-MLX
Video demo of Pac-Man controlled entirely by typed decisions from Laya-MLX running locally on Apple Silicon: 351 steps, a win, and 224 guardrail interventions logged.

VideoReal-time control
Entries 625 to 672 of 746, in the hub's default order. The introduction is on page 1.
Showing 625 to 672 of 746
Video demo of Pac-Man controlled entirely by typed decisions from Laya-MLX running locally on Apple Silicon: 351 steps, a win, and 224 guardrail interventions logged.
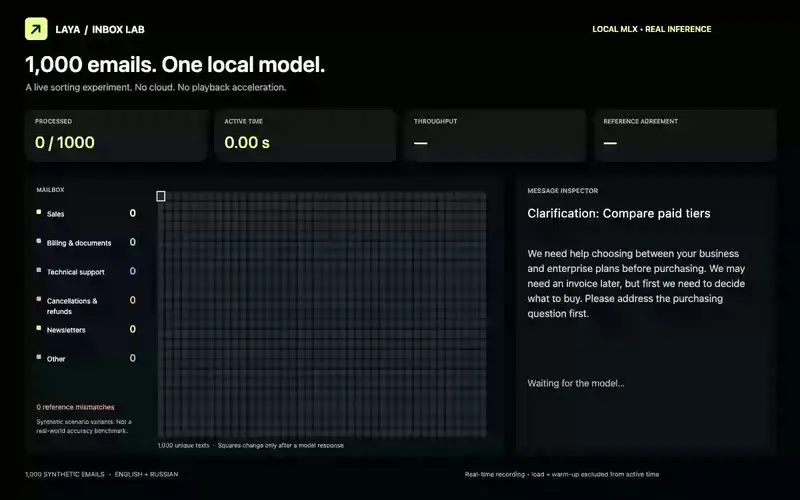
Ran 1,000 synthetic emails through a local 322M Laya multilingual checkpoint on a MacBook Air M3, sorting them into six folders. Reported 65.1 percent accuracy against reference labels, 28.6 seconds without screen recording, and 0 MB of swap.
An Overcooked-style kitchen simulation with four Jev-driven chefs handling expiring orders and competing priorities. In one early test Jev gave firefighting a 66% probability over finishing an order at 33%, then returned its move in about 200ms.
A site where you answer questions about loyalty, money, and relationships, then see whether your pick matches Jev's answer and how other people voted, to find where opinions diverge.
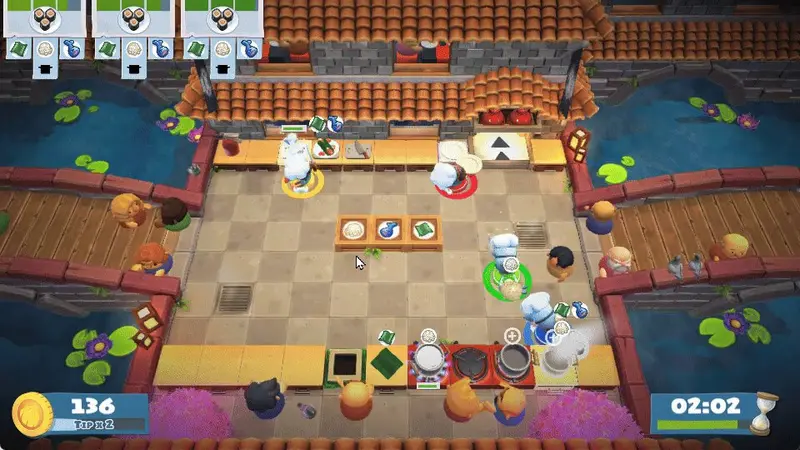
Video demo of a harness for playing Overcooked: a planning model builds a live understanding of the level while Jev agents make decisions in real time.
Built a proof-of-concept Google ADK triage agent on 30 labeled tickets, swapping only the decision engine. Jev took 422ms at 53 percent accuracy, Laya took 152ms at 10 percent accuracy: faster but not more accurate.
Tested Jev against a local MLX build of Laya in zero-shot mode on 40 English and Thai support tickets. Jev scored 90 to 100 percent accuracy, Laya scored 30 to 80 percent, though Laya ran faster.
TypeSafe's release post for jev-1.14.0, shipped under the jev-preview alias with small improvements across the board and the biggest gain expected in multilingual support. It adds opt-in danger zone features (image input, a box question type, longer context, data sharing) and promises 60 days' notice before jev-1.13.0 is deprecated.
Cloudflare's launch post for Clef-omni, a 30B-A3B mixture-of-experts decision model that reads audio, video, images and text, at $0.15 per million input tokens. It also cuts Clef-flash to $0.038 with a 24K hosted context, and gives Cloudflare's own benchmark and latency tables.
NeuroLink's xor provider for decide(): configuration through a proxy, local media checks, and the silent failure where a deployment without image support ignores images and still answers 200. A test scores four Meta Ad Library ads 0 to 3 across five identical runs; the post says it did not confirm which model sits behind its route.
meraGPT's own post, following Elvis Saravia's "Building a Custom Harness with Pi and Jev". A Pi agent harness of about 130 lines of JavaScript calls Decider 1 through TypeSafe's JS SDK to pick the model, block shell commands that delete data or use the network, and send unfinished answers back.
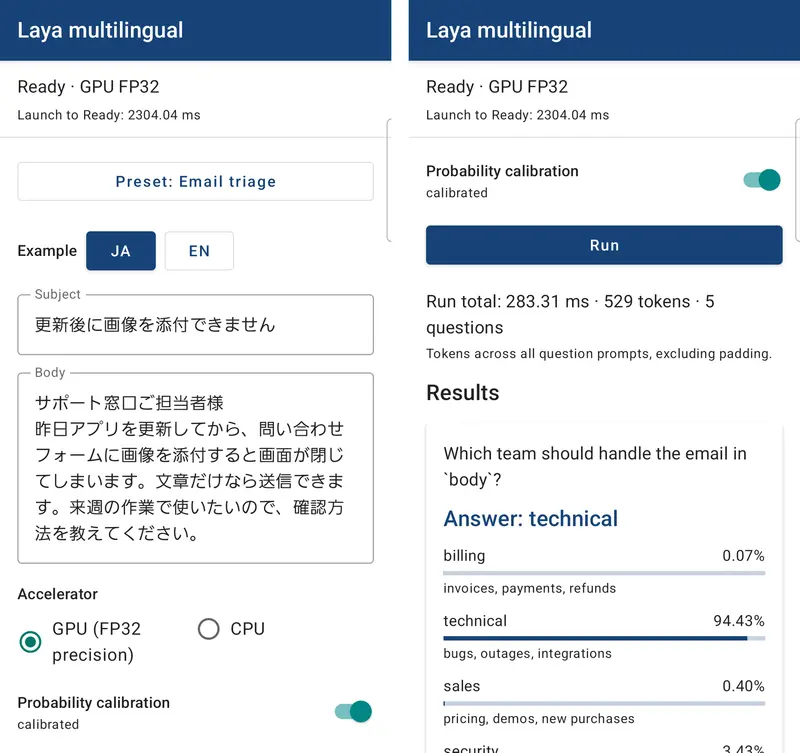
Google's LiteRT conversion of Laya's multilingual checkpoint for on-device Android GPU inference, matching the official CPU implementation on 201 validation rows with a Kotlin sample app answering typed choice, score and noul questions.
A vision variant of Laya, an independent SmolVLM-256M based fork, that answers calibrated choice, score and noul questions about an image plus optional text in one forward pass, with a trained score head.
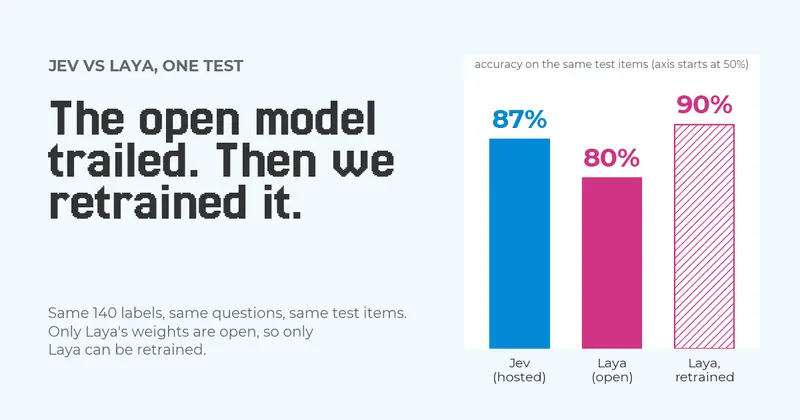
An independent benchmark testing Jev against Laya on the same 140 labels, checking whether each engine's own feedback loop finds a hidden labeling factor, and fine-tuning Laya on the same data to compare results.
Laya's multilingual checkpoint fine-tuned on 701 Burmese SIB-200 examples for seven-way topic classification, reaching 0.716 test accuracy versus a 0.441 zero-shot baseline, with temperature-scaled calibrated probabilities.
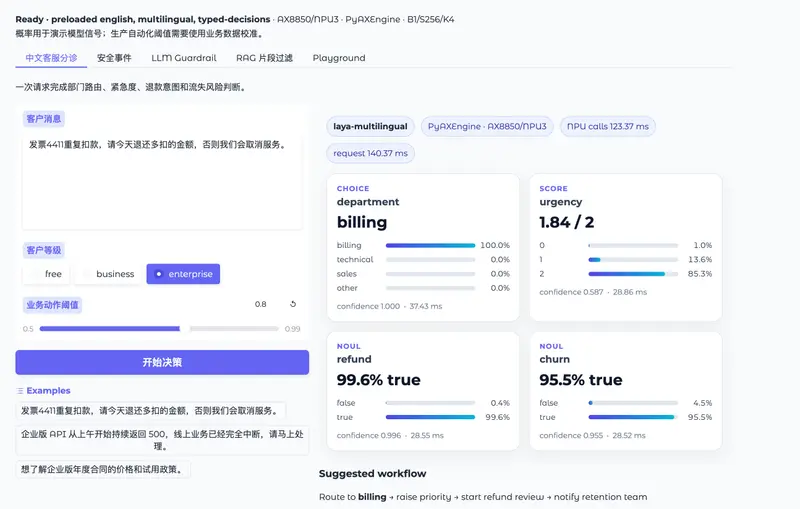
A ready-to-run deployment package for all three Laya checkpoints (English, multilingual, typed-decisions) on Axera AX650/AX8850 edge NPUs, with sample requests, outputs and a demo app via the axllm runtime.
Laya fine-tuned for Arabic NLU on laya-multilingual, covering intent classification, natural language inference and offensive-language detection. On MASSIVE ar-SA intent classification it reached 81.6 percent accuracy against 38.6 percent for stock Laya.
A live site where Laya plays Tetris, Flappy and a three-lane runner in the browser, with a measured Laya-vs-Jev benchmark and a free agent skill for local decision routing.
Laya's English checkpoint compiled to GGUF with ggmlc, scoring choice, score and noul questions in one encoder pass with a CLI that ships an injection-guard preset and a local serve/daemon mode.
Convai's own Gradio Space running Laya live across eight workflow tabs, including support triage, LLM guardrails, RAG passage filtering and multilingual checkpoint routing, each returning typed choice, score and noul probabilities.
Developer article framing Jev as a smart if-statement: pass structured data plus predefined questions, get probabilities over defined options. Covers Noul, Choice and Score, JavaScript, Python and Vercel AI SDK usage, and limits including arithmetic, dates, prose and images.
Runs early-access Jev over 24 Norwegian submissions to the 2022 hearing on resource rent tax for salmon farming, reporting agreement with a frontier model's labels, calibration, cost and latency. Compared against DeepSeek V4.1 Flash with and without reasoning.
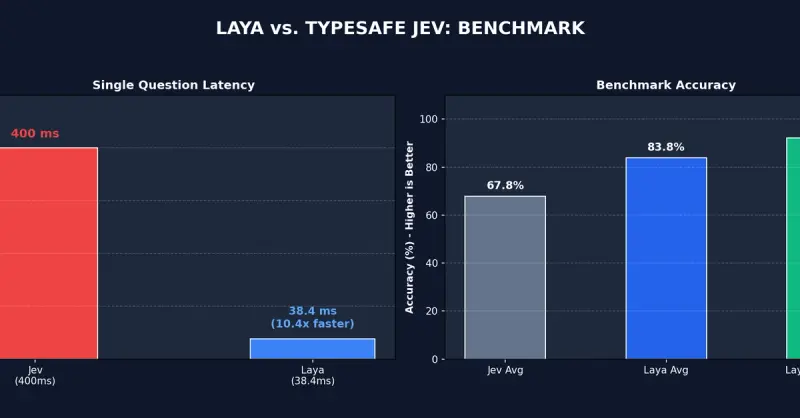
Laya's author argues his March 2025 non-autoregressive decision-model research predates Jev by over a year, and lays out his RLCD training method, calibration approach and sub-40ms latency figures.
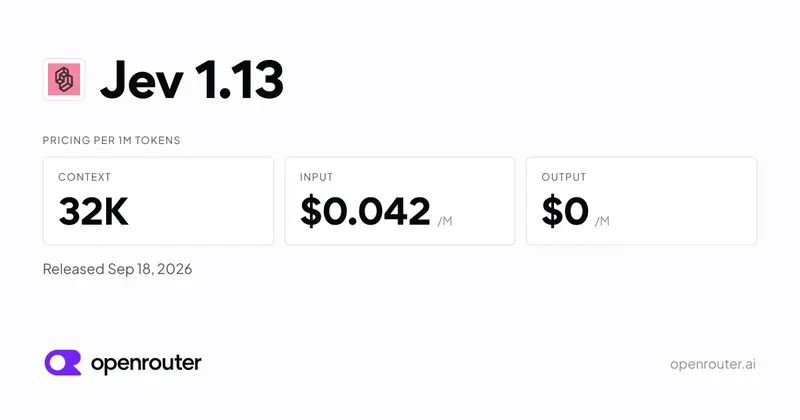
OpenRouter's model page for Jev 1.13, which runs on OpenRouter's Decisions API rather than its OpenAI-compatible chat endpoint. Listed at $0.042/M input and $0/M output with a 64,000-token context on 10 October 2026, up from 32,000 when added in September.
Laya fine-tuned on 671 Mind2Web examples to predict the next browser action, an operation and a target element index, from a page's DOM and a goal, reaching 74.3% validation accuracy.
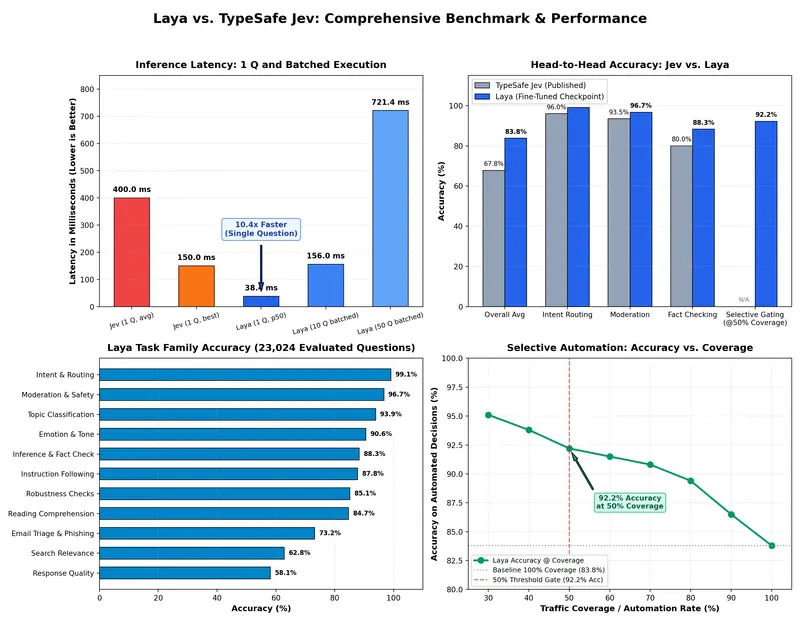
An ONNX export of Convai's Laya decision model, with int8 and fp16 variants and a Python quickstart that builds the marker-token sequence and runs one inference in about 15ms on CPU.
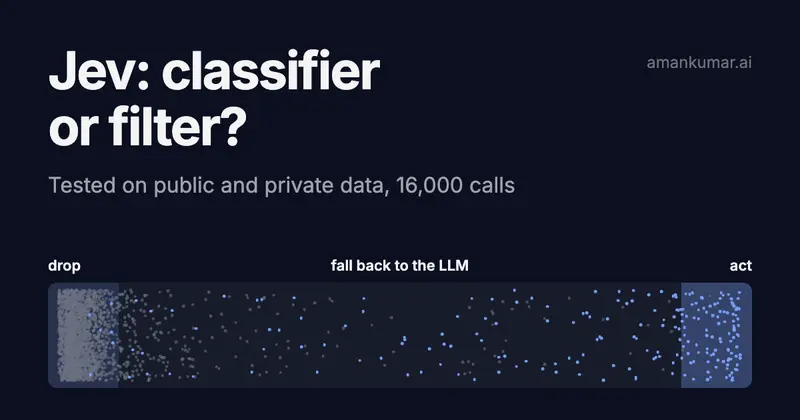
16,000 calls comparing Jev with gpt-5.4-mini and gpt-5.6-luna on four public datasets, then on a few thousand real pipeline decisions. Covers where it wins, where it breaks, and how to use it.
Elixir Forum thread (8 replies, 281 views) announcing an Elixir SDK for Jev with strict noul/choice/score constructors and evaluate/evaluate_many/streaming. Notes five independent Elixir Jev clients appeared in the same launch week.
German outlet heise reports on Jev's 70-500ms latency, $0.042 per million input tokens, and RLCD. Notes the model gives no linguistic explanation for its decisions, which raises transparency questions.
Practical guide covering setup, the three primitives (Choice up to 255 options, Score across 2-10 levels, Noul as a yes/no probability), and five patterns: speculative fan-out, confidence-gated routing, composite scoring, cascading to a larger model, and retrieval before judgment.
A side project that scores a project idea using only Jev Score questions, with no generative model in the loop.
A researcher claims prior open-source work with the same decision-only design and links the model, dataset, and paper. Companion to the Hacker News item 49736660.
Goes claim by claim through TypeSafe's launch material against available evidence. Concludes the cost and latency advantages hold up in independent testing, but the calibration claim is unproven without published reliability data.
Uses poker to probe where a fast decision model helps and where it does not. Given the opponent's exact cards, a made flush against its straight, Jev said it was ahead and shoved 89.5 into a 22.5 pot five runs out of five; the author argues the release shipped without published evals.
86-point, 12-comment thread on browser-use's agent. Commenters dispute the 7.1s Google Flights timing because timing starts after initial page observation, report demo failures, and object to paying per call for a cloud decision model.
Measures one direct Jev call per row against 12 to 14 Jev-scored dimensions fed into a locally trained linear model, across three classification tasks. Decomposition lifted Japanese NLI from 0.837 to 0.908 but was about 25 times worse on false positives against hard benign input, and the whole run cost $1.43 over 5,477 test rows.
Async Python client for Jev, version 1.1.0, requiring Python 3.12+ and aiohttp. Supports Noul, Choice and Score and encourages batching multiple questions into one call.
36-point, 9-comment priority claim: the poster says he published a non-autoregressive, schema-constrained probability model in March 2025 (arXiv 2503.23303) using PPO over sequence embeddings rather than a parallel sampler. Commenters reply that the difference was marketing reach, not the idea.
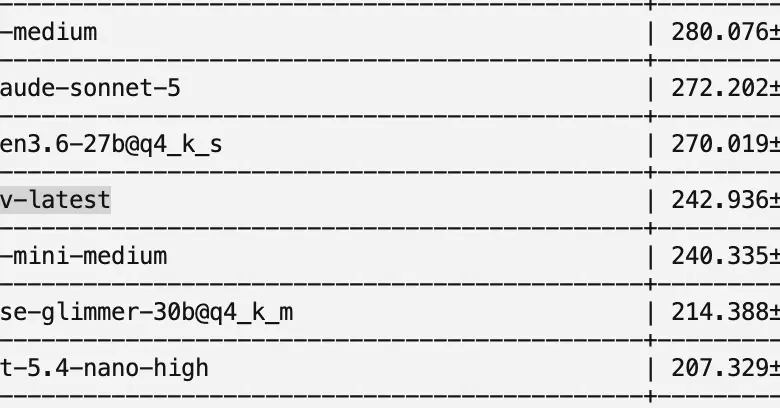
The author ran Jev through his LLM Chess benchmark, where a model repeatedly picks from a list of legal moves rather than generating free text. Jev's win rate against the random-move baseline landed close to several reasoning models, despite Jev not being built to reason.
Argues that Jev changes how products are built and how AI credits are metered, because output tokens are free and every decision carries a confidence number. The case is not that Jev is the best reasoning model, but that it gives you a reason to split one expensive model into two systems.
Reports the launch and describes Jev's parallel sampler in place of sequential token generation, giving 70-500ms responses against 3-329 seconds for LLMs. Covers the Doom demo at about 10 queries per second and the waitlist-gated early access.
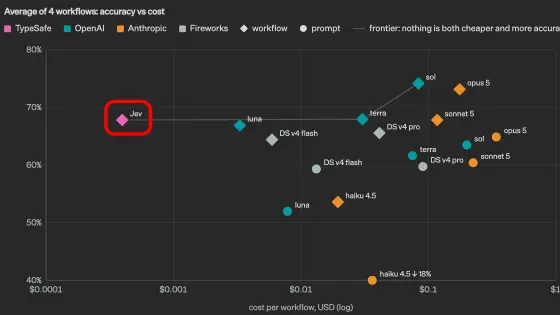
Japanese tech news coverage of the launch, reporting GPT-5.6 Terra-level performance on System One tasks at much lower cost and latency.
Vercel changelog announcing Jev on AI Gateway under model ID typesafe-ai/jev. Evaluation calls appear in Gateway logs, count toward budgets and accept Gateway provider options.
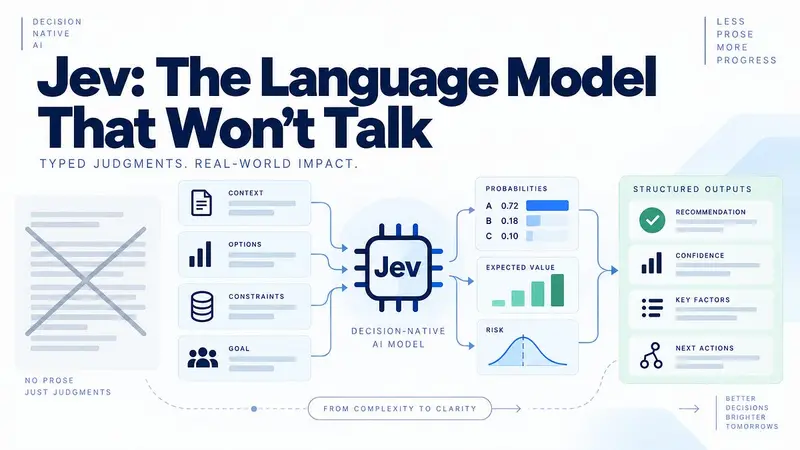
Analysis of RLCD as a training target where stated probabilities should match how often the model is right. Flags calibration breaking under distribution shift, correlated errors compounding across workflows, and the difficulty of appeals without explanations.
Explainer covering how Jev differs from token-by-token LLMs, the three typed primitives, and RLCD. Reports roughly 68% accuracy on TypeSafe's four-workflow benchmark, comparable to GPT-5.6 Terra, and notes Jev is unsuitable for open-ended generation.
HuggingFace Space running a stock Qwen2.5-1.5B-Instruct 4-bit checkpoint that scores multi-field JSON schemas in one pass using KV-cache broadcasting and logit slicing, reporting a 5.6x to 7.0x latency cut on Apple Silicon. The README documents no reinforcement learning or fine-tuning despite the RLCD in the model name.
157-point, 23-comment thread on vinnylarouge/jevlike, an independent one-pass architecture that scores a changing list of text options against context. The submission claims only the same input/output shape as Jev, not equal quality or a reproduction of RLCD.
Near Here compares Jev with Mistral Small 4 and Gemini 3.5 Flash-Lite at rejecting unsuitable local event listings, each with its own tuned prompt. Jev scored 48 of 50 on the main test set at a median 0.58 seconds, and the post includes token counts, cost per decision and a downloadable comparison PDF.
Nothing matches those filters
Clear a filter to widen the search, or send us the thing you were looking for.


