Jev: one judge call, or twelve dimension scores? I measured both on three tasks
Measures one direct Jev call per row against 12 to 14 Jev-scored dimensions fed into a locally trained linear model, across three classification tasks. Decomposition lifted Japanese NLI from 0.837 to 0.908 but was about 25 times worse on false positives against hard benign input, and the whole run cost $1.43 over 5,477 test rows.
More like this
jev-trader
Makes one AI trade decision every Monad block on the Kuru MON-USDC market using Jev. The public deployment runs in dry-run mode with a mock model.
 jarrodwattsOpenjev-trader on github.com
2.2k starsLoop, mock model p50 100 msDecision window ~300 ms/block
Introducing System One Models and Jev (Hacker News launch thread)
The 1,978-point, 513-comment launch thread. The top comment calls the speed comparison misleading, since Jev only returns structured output, and disputes the cannot-hallucinate claim because a valid type can still hold a wrong value. Others note ordinary LLMs can already be forced into structured output.
DSPy: programming, not prompting, language models
Declares typed input/output Signatures for LLM modules and optimizes the underlying prompts and weights against a metric. Its Signature abstraction is the closest widely-used open equivalent of Jev's typed-question interface. Star count is GitHub's rounded display figure.
GLiNER: generalist lightweight NER
Compact encoder model that takes the label set as input at inference time and extracts arbitrary entity types zero-shot on CPU. Same classifier-that-takes-its-categories-as-input shape, for extraction rather than decisions. Star count is GitHub's rounded display figure.
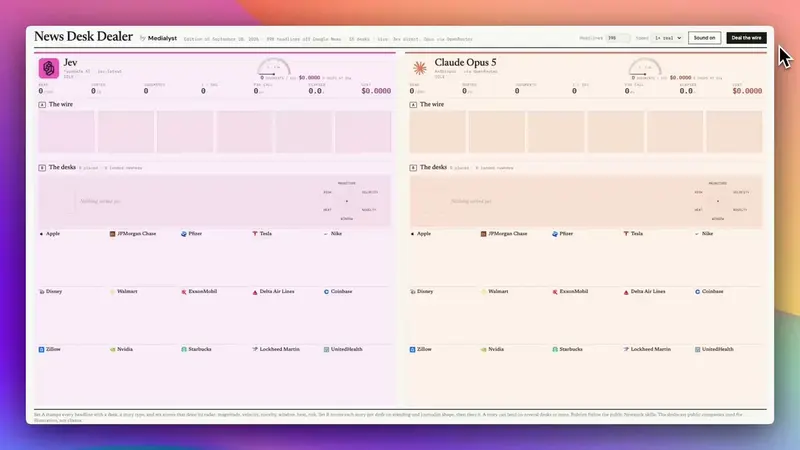
newsjack
Open source skills that read a morning's news feed with Jev and tell a list of brands which stories to act on. In a demo run it read 384 headlines and matched them to 15 brands in 24.9 seconds for $0.19, against 4 of 384 for $0.77 on Claude Opus 5 over the same feed.
 Elvis (@elvissun)Opennewsjack on newsjack.sh
851 starsCost $0.19vs Opus/headline ~390x cheaper
ProjectComposite scoring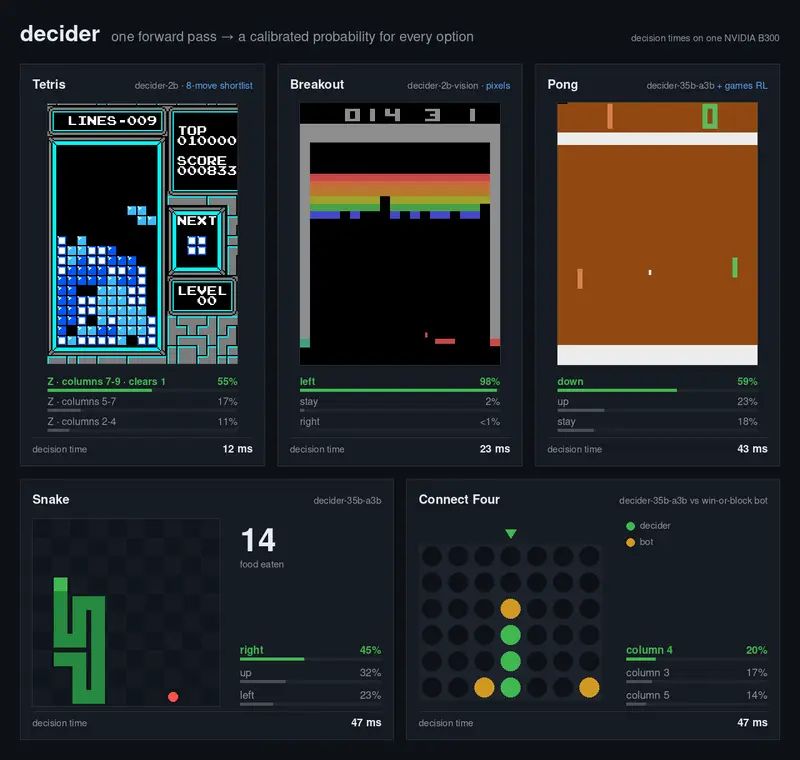
decider: one-pass typed decisions with calibrated probabilities (Qwen3.5-2B)
Open reproduction of the System One model class, fine-tuned from Qwen3.5-2B-Base, returning a probability distribution per typed question in a single forward pass. Serves TypeSafe's POST /v1/systemone wire format so TypeSafe SDKs work unchanged by repointing TYPESAFE_BASE_URL.


