PrimitivesChoice
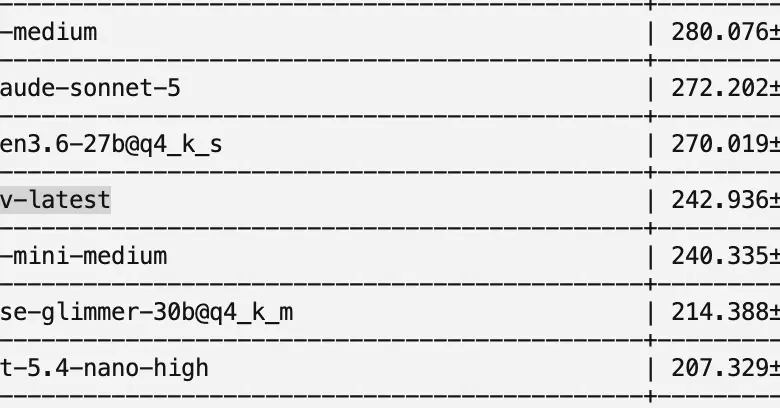
The author ran Jev through his LLM Chess benchmark, where a model repeatedly picks from a list of legal moves rather than generating free text. Jev's win rate against the random-move baseline landed close to several reasoning models, despite Jev not being built to reason.
Cloudflare's launch post for Clef and Clef-flash, two decision models on Workers AI that accept the Jev request format and open weights under Apache 2.0. It covers the architecture, Cloudflare's own benchmark tables against Jev, Kev and Laya, and a new reinforcement learning service.
 Michelle Chen (@michellechen)140k viewsOpenIntroducing Clef: our open-source decision models, and new RL fine-tuning platform on blog.cloudflare.com
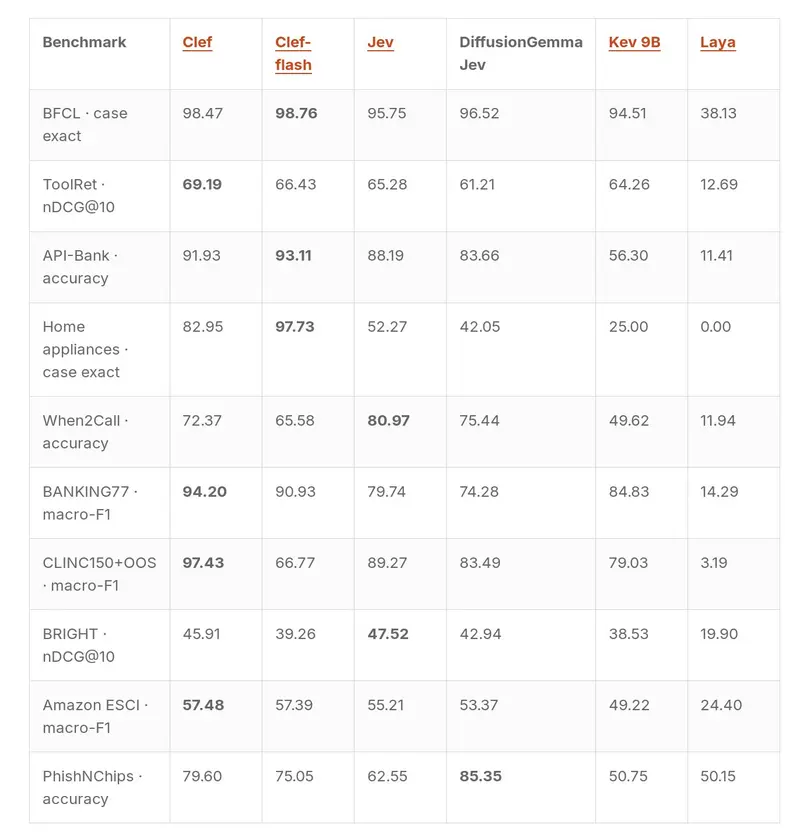
Cloudflare's live leaderboard for decision models on the Decision Index suite, with Clef, Clef-flash, Jev, Kev-9B and Laya plotted by score and latency. Cloudflare built and ran it, so treat the ranking as vendor-run.
 Cloudflare (@ritakozlov)41k viewsOpenDecision Model Leaderboard on clef-evals.workers-ai-mle.workers.dev
AI News daily roundup leading with the Jev launch, summarising RLCD and TypeSafe's 20-200x speed and 40-400x cost claims. Its recap of reactions notes posters using Jev as a structured classifier, judge and routing policy where text generation is unnecessary.
Argues Jev's speed comes mainly from constrained single-token generation and aggressive prefill, techniques reproducible with existing LLMs, rather than a new architecture. Still treats very fast structured output as a new primitive, while doubting Jev matches frontier models on raw intelligence.
An independent, evidence-based map of where Jev's calibrated-decision claim holds up and where it breaks down, built from real API-call receipts rather than a leaderboard.
An adversarial evaluation of Jev with nine experiments and 28 predictions fixed before any data was collected. One run covered 123,805 requests over 138 minutes for $12.69, with five failures, plus a 13-rule prompting guide.

