lomeshdutta/skill-router
A personal skill router for Claude Code that uses Jev to decide which of your installed skills a session needs, built after the author found they only reached for five of about 90 installed skills.
Entries 289 to 336 of 430, in the hub's default order. The introduction is on page 1.
Showing 289 to 336 of 430
A personal skill router for Claude Code that uses Jev to decide which of your installed skills a session needs, built after the author found they only reached for five of about 90 installed skills.
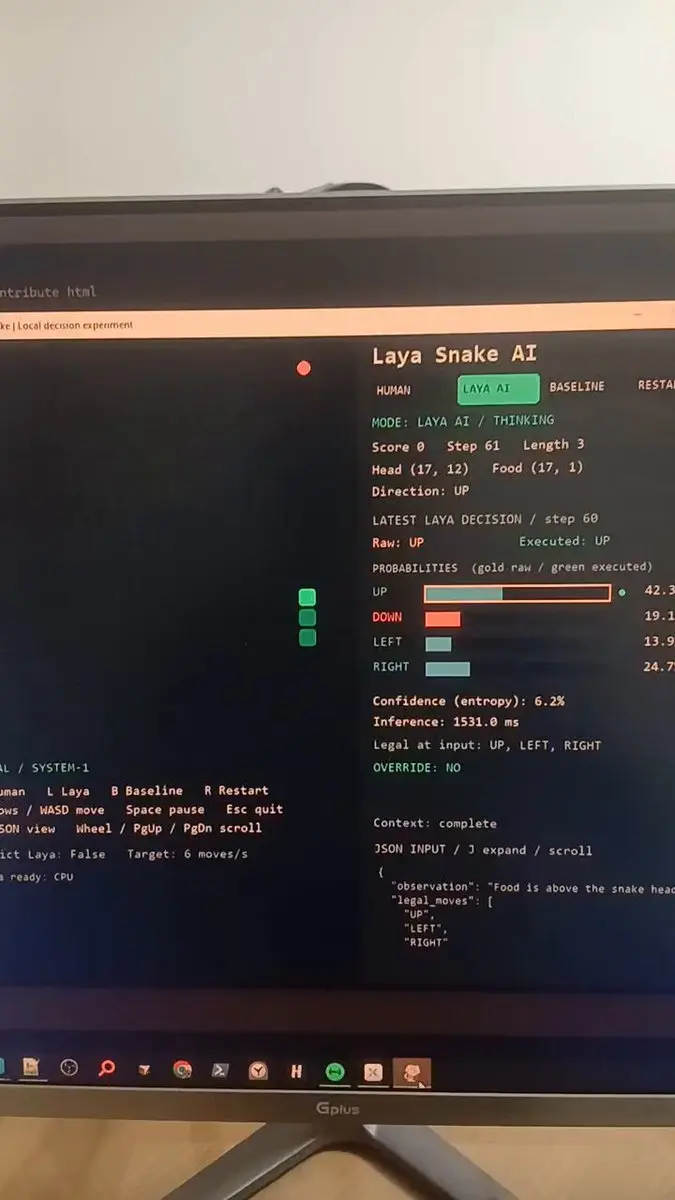
A desktop Pygame Snake game with HUMAN, Laya AI and greedy-baseline modes, showing a live decision dashboard with real SDK probability bars, entropy confidence and per-move inference time.
A live market news desk that takes yfinance headlines and returns ranked trade ideas, running 215 typed judgments through Jev per pass in 2.7 seconds for about a quarter of a cent. Built with Claude Code and TypeSafe's agent skill.
Groups a raw log stream into patterns, asks Jev about each pattern once instead of every line, and routes the result to page, ticket, or log using a paging policy written in plain English. One run processed 22.8 million lines into 11,812 patterns for 64 cents.
Two ComfyUI nodes that free VRAM between models on a single GPU: one unloads cached image models, and a Laya-based router classifies the enhanced prompt's style before an image model loads. Measured on a 12 GB RTX 3080 Ti.
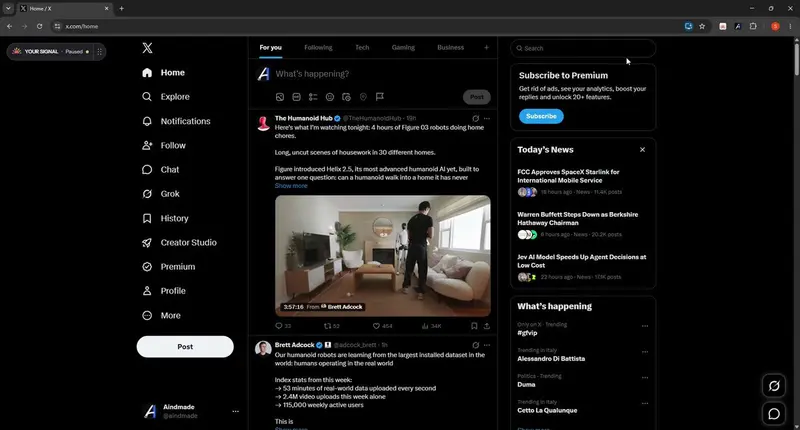
An open source, bring-your-own-key browser extension that scores posts already on your X feed with Jev, then applies your own rules locally. Reversible, with no telemetry.
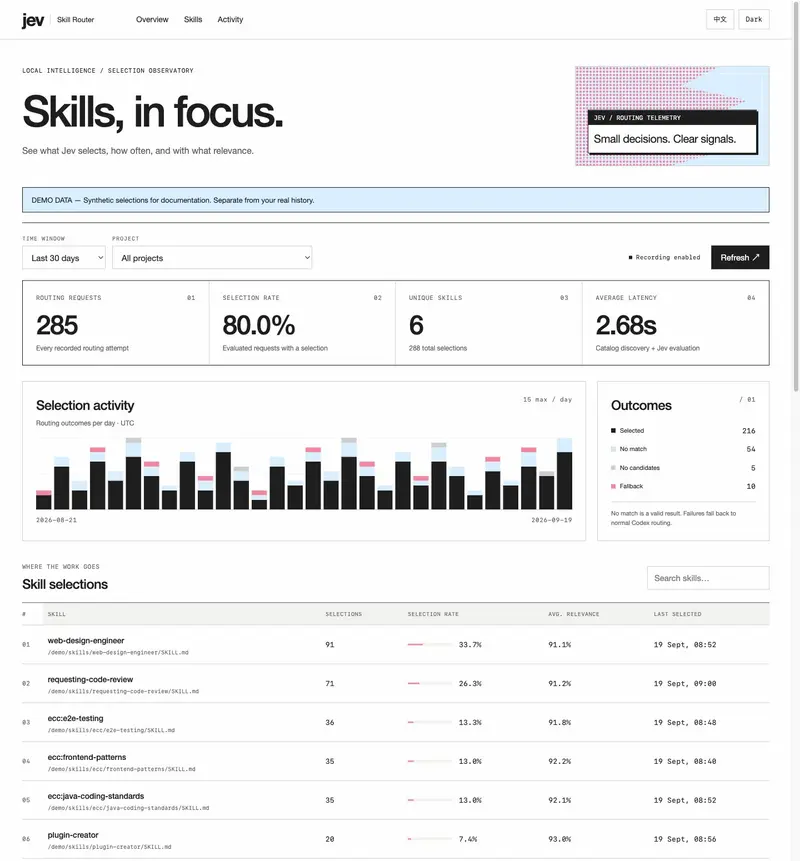
A Codex CLI plugin that uses Jev to score which of a project's skills are relevant to a prompt, passes the matches to Codex, and shows selection history on a local dashboard.
A cross-platform Agent Skill and MCP tool that gives Codex, Claude Code, OpenCode and Pi local Laya decision routing, with explicit invocation verified end to end on Apple Silicon and cross-platform CI.
A voice-driven control layer for macOS with a Rust core and Tauri shell, where Jev is a fallback rather than the main router.
A fully local Home Assistant Assist conversation agent that scores registered intents and exposed entities with Laya in one forward pass, dispatching simple commands directly and escalating compound or low-confidence requests to a fallback LLM.
Runs Jev-style typed decisions directly on images with shared visual encoding, using Qwen3-VL instead of a text description of the image.
A Chrome extension that files bookmarks into folders using semantic rules you write, matched by Jev.
Semantic code search for coding agents built on Jev, packaged as a CLI and MCP server, with results reported on SWE-bench Lite.
Runs Cucumber .feature files with no step definitions: Jev resolves what each Gherkin step means and Playwright executes it.
Measures on your own labelled data where a small model's confidence stops paying off, then routes each decision to Jev or a larger model at the threshold it found rather than a default. On 500 Banking77 examples Jev was 77.8% accurate but 90.7% confident, and threshold 0.67 reached 80.2% accuracy for $0.1033.
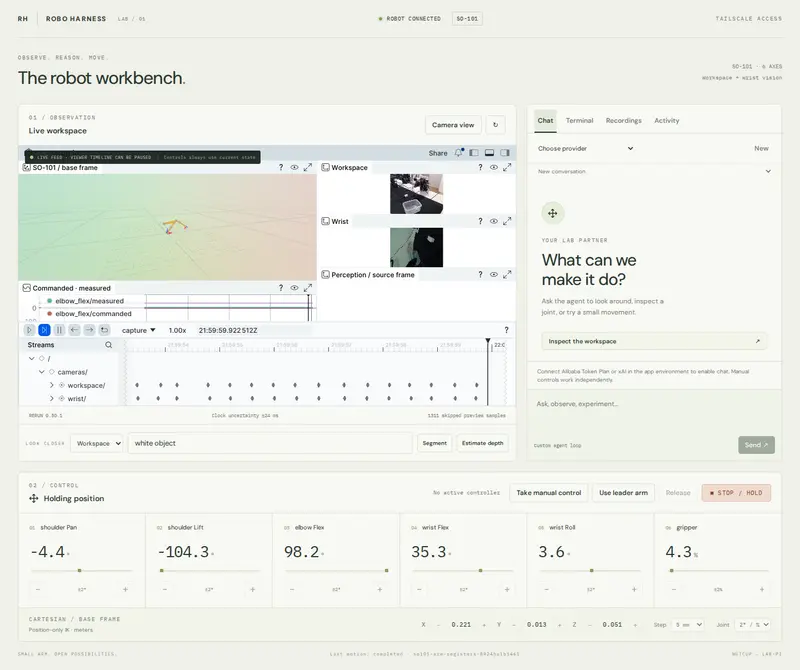
SO-101 robot-arm workbench with a Bun and Effect coordinator, a React workbench around Rerun, and a Python LeRobot hardware boundary. Its decision runner lets Jev, reached through the AI SDK evaluate API on Vercel AI Gateway, pick bounded joint steps under a spend cap, and chat and a decision run never move the arm at the same time.
A TypeScript toolkit of production patterns around the Jev SDK: decision contracts, confidence-threshold routing with fallback and review paths, an offline evaluation harness, and a RAG diagnosis showcase.
A Home Assistant conversation agent where Jev classifies an utterance and either takes a fast-path light action or hands off to the Grok conversation agent, gated by confidence and yes/no thresholds.
Game of Thrones roleplay where a story model writes each scene and Jev reads it back, answering five questions in parallel: where Jon stands, the kind of beat, the danger, what should play under it, and whether the prose stayed inside the fiction. The header, soundtrack, artwork and next prompt are all functions of those answers.
Asks how far written category definitions get you before you need a labeled training set. On a 5,733-email ham, spam and phishing test Jev reached 98.64% against 98.87% for TF-IDF logistic regression. A separate 18,514-email spam run scored 98.3% against 98.4%, and averaging both reached 99.2%.
Emoji autocomplete that makes one Jev call per pause in typing: a Choice over up to 254 emojis, a Choice over eight emotions, three Scores and three booleans, answered in parallel in about 100 ms of model time per the README. TanStack Start on Cloudflare Workers through the AI SDK typesafe-ai provider, hosted on Whop, with a live demo at emoji-jev.whop.site.
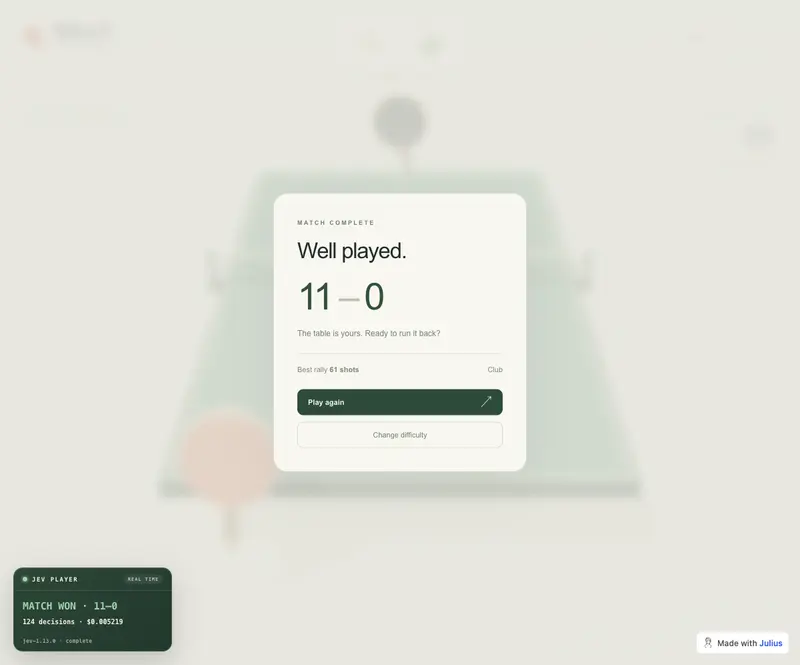
Jev plays a browser table-tennis game in real time from structured telemetry, driving ordinary Chrome inputs and logging auditable decision evidence.
Reproducible eval harness and field note for a Jev Ultrafast research-browser session: 11 baseline cases, human and quant stress suites, QC grades, a suite runner and a report generator. It drives an upstream checkout of browser-use/jev-ultrafast at a pinned commit rather than forking it.
Agent skill that hunts for fuzzy semantic judgment in a system and turns it into small Choice, Score and Noul questions, deciding where the Jev boundary belongs, what state each question sees and which ones can run together. Meant to be installed alongside TypeSafe's official skill.
Proof of concept that identifies Spanish profanity with Jev and replaces the matching word intervals with a beep without changing the audio duration. Word timestamps from an ASR adapter feed parallel Jev evaluations for a Boolean profanity probability and a severity Score, then ffmpeg overlays the beep and writes a JSON audit report.
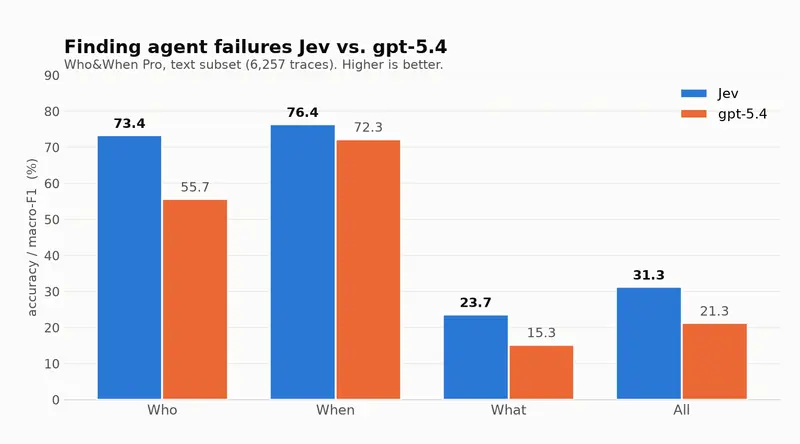
Benchmarks Jev on the 6,257 text traces of the Who and When Pro agent-failure-attribution set, predicting the responsible agent, the decisive step and the error type. Scored with the official whowhen_eval scorer against the paper's LLM baselines, at about $1.28 for the full run.
Spring Boot starter for WebFlux that evaluates each response payload with Jev and turns suspected silent HTTP 200 failures into ordinary exceptions. Evaluation is one non-blocking WebClient call with a 750 ms default timeout, and any API error or timeout is treated as not a failure.
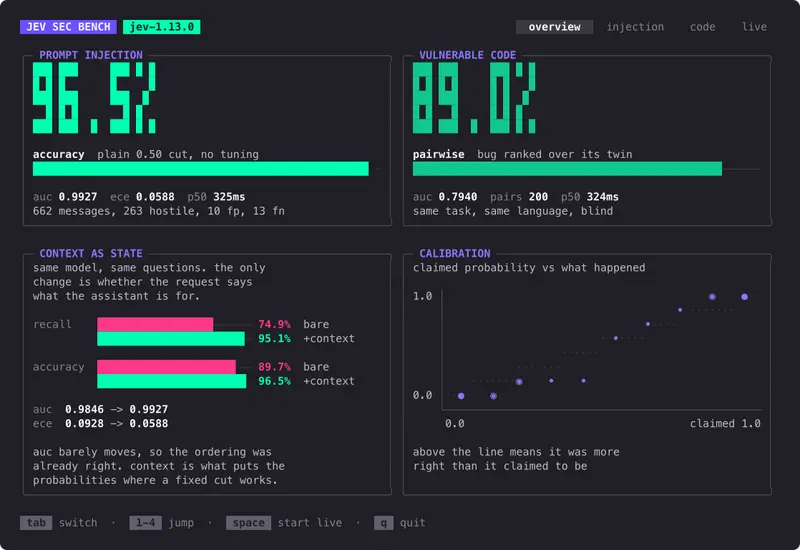
Two blind security benchmarks for Jev on public corpora: 662 labelled prompt-injection messages and 200 matched vulnerable-code pairs, run through jev-go with raw per-sample output committed. At a plain 0.50 cut the injection run reached 96.5% accuracy, ROC-AUC 0.9927 and p50 325 ms.
Experimental full-game harness where Jev plays the original Civilization II in a browser, displaying live action probabilities.
Fish-style zsh history autosuggestions ranked by an AI model instead of prefix matching, with Jev as one of four supported providers.
.NET SDK for the System One API with dependency-injection support, Microsoft.Extensions.AI integration for chat middleware and guardrails, and native AOT compatibility.
A stdio MCP server built on the laya-mlx runtime, exposing preset tools for support triage, prompt-injection guarding, moderation and email classification, plus a generic typed choice, score and noul tool.
Has Jev select a native Codex tool call before the coding model runs, so Codex executes it through its own tool runtime and approvals while the coding model handles reasoning and edits.
Evaluates writing against separate named checks, such as hedging, em dash overuse, clarity and passive voice, using Jev for each check with its own verdict and confidence signal.
An MCP toolkit for agent-driven bug bounty and pentesting work, with scope-gated scanning tools, an evidence graph and a finding lifecycle, gating each step through Jev.
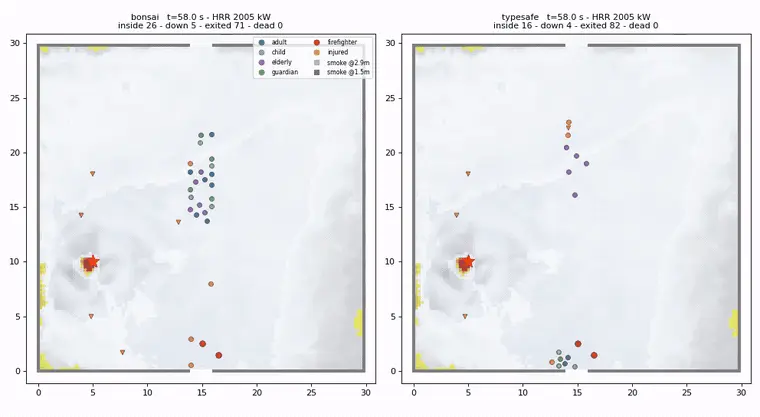
A fire evacuation simulation that rebuilds a Jev-style typed decision engine on local LLMs, then runs a per-person evacuation model on top, comparing it against a chat-model baseline on the same fire scenario.
Unofficial dependency-free Go client for the TypeSafe v1 API covering System One and model discovery, with automatic retries.
A fork of the Needle Chrome extension that finds webpage passages by meaning, swapping its hosted Jev calls for Laya running locally so no API key is needed.
Turns Jev, a decision model, into a character-by-character text generator by repeatedly asking it to pick the next character from the vocabulary.
A Hermes plugin that pre-routes each task to a skill before the main model sees it, classifying against a roughly 300-skill index with SemIf by default or a legacy local Laya model. Measured 67 percent top-1 for SemIf against 56 percent for Laya on the same pools.
Unified Python client for typed decisions with a fallback chain across Jev, OpenRouter, Laya and cross-encoder models.
Agent memory where Jev decides what is worth recalling, with Mnemosyne-compatible storage and a Hermes integration.
Jev plays Minesweeper, picking each move as a typed decision instead of generated text.
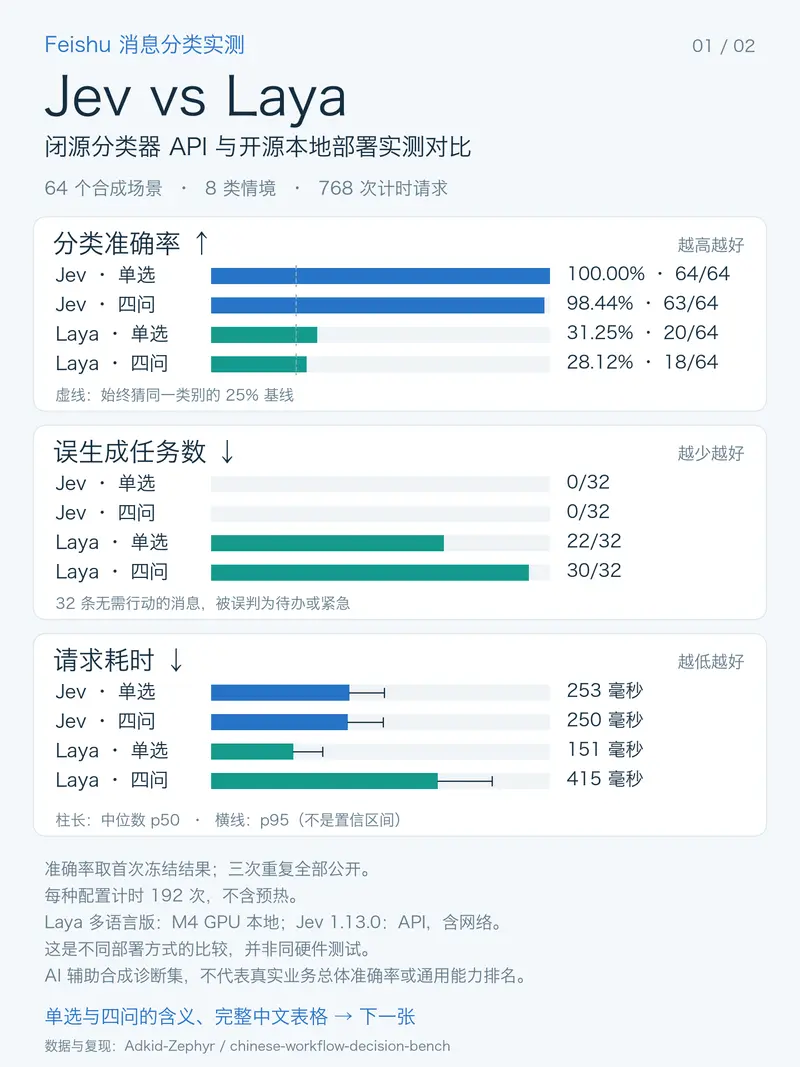
A frozen 64-case benchmark of Feishu-style workplace messages, scoring Jev and Laya on a single choice question and on a four-question workflow. Jev scored 100 and 98.44 percent correct, Laya scored 31.25 and 28.12 percent, on the same requests.
Learns a repository's decision norms from its history, then uses Jev to adversarially judge past decisions against those norms, through five Unix-style primitives: seed, expand, judge, verify, report.
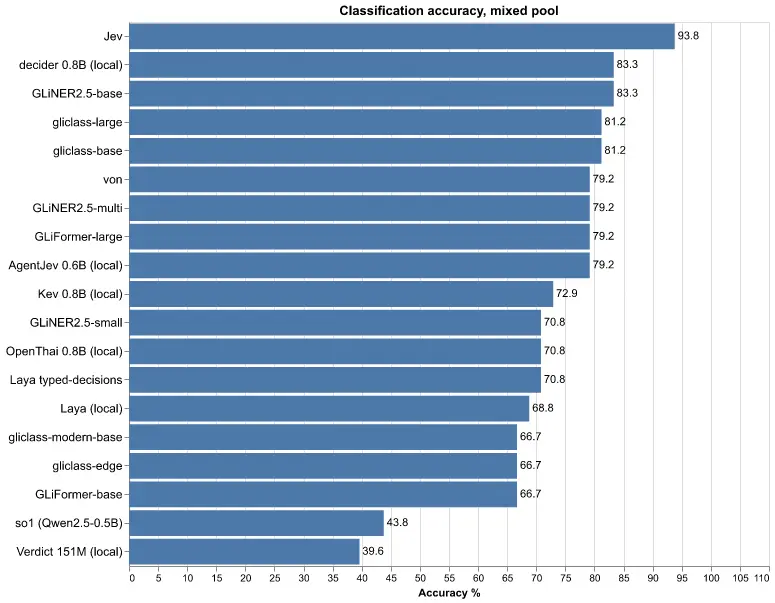
Compares GLiNER 2.5, GLiFormer, GLiClass, Laya, Von and Jev on zero-shot information extraction and classification in one web UI.
A PreToolUse hook for Claude Code that scores every tool call against a YAML policy you own and allows or denies it in about 100ms, with no LLM call in the loop. Runs on Jev today, with local models planned next, and publishes a calibration table.
A dockerized FastAPI service that loads Laya's English, multilingual and typed-decisions checkpoints behind a router, and serves choice, score and noul questions over HTTP with API-key or Basic auth.
Nothing matches those filters
Clear a filter to widen the search, or send us the thing you were looking for.


