jeffrey
A coding-agent CLI that splits work between a decision model, Jev by default or self-hosted Laya, which only picks the next tool and scores progress and risk, and an OpenAI-compatible LLM that fills in the tool arguments.
Entries 337 to 384 of 430, in the hub's default order. The introduction is on page 1.
Showing 337 to 384 of 430
A coding-agent CLI that splits work between a decision model, Jev by default or self-hosted Laya, which only picks the next tool and scores progress and risk, and an OpenAI-compatible LLM that fills in the tool arguments.

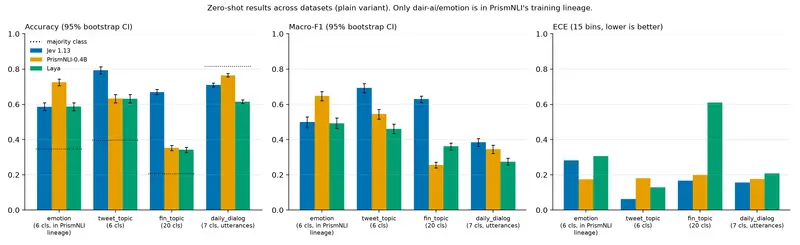
Zero-shot classification benchmark across four datasets: Jev leads decisively on topic tasks, and Laya's advertised edge over Jev does not reproduce, tying on emotion and trailing elsewhere.
A Swift package that runs one Laya typed decision per call on-device via Core ML, ported from laya-coreml, with no Python needed at runtime.
A local MCP server that runs ready-made Jev question packs (Choice, Noul, Score) as tools for Cursor and other MCP-compatible agents.
Turns a set of coding-agent skills into oxlint rules, using Jev to do the classification.

Pong where the ball moves one segment per model decision, so a lane's speed is that model's latency and nothing else. Four lanes replay a recorded run with Jev, Gemini 3.8 Flash, Claude Haiku 4.5 and GPT-5.6 Sol on the right paddle, every player and agent on an Ably channel.
A configurable GitHub Action that reviews directory submissions and classifies pull requests using only Jev: typed yes/no checks plus one category choice, with code applying the policy and posting one PR comment.

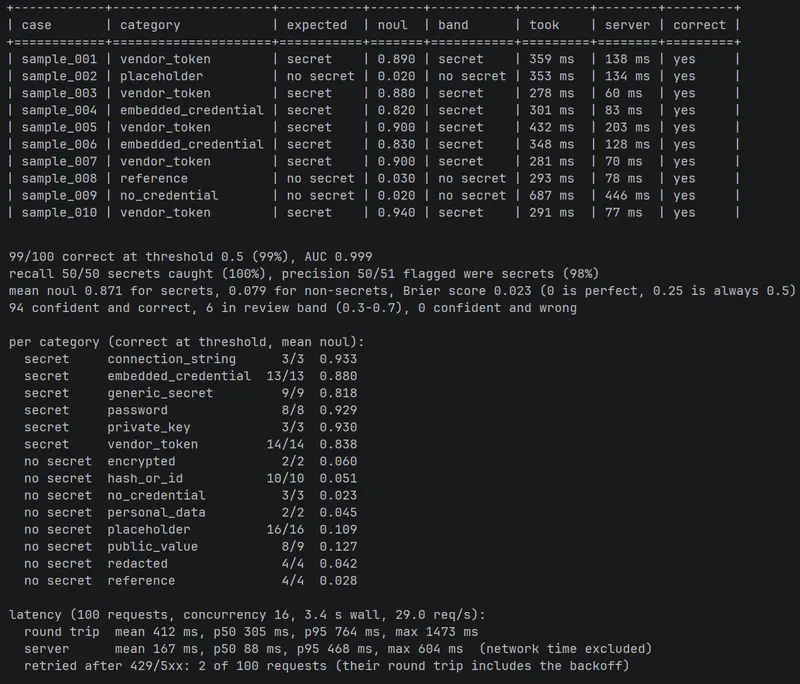
Measures how well Jev spots real secret credentials in file snippets. Each case is one Noul question and the probability is compared with the expected label, with no regex matching or provider verification. Reports accuracy, AUC, recall, precision, Brier score, review-band counts and latency.
Paste an email, Slack message or memo and get rustc-style diagnostics back. A plain lexer finds phrases and their line and column positions, then one request to Jev scores dimensions such as passive aggression, unnecessary urgency and how much actual information the text carries.
PHP and Laravel SDK for TypeSafe AI's Jev model series, distributed on Packagist as binnash/typesafe-sdk.
Multiplayer triage dashboard for public GitHub repositories, where a System One model answers a fixed set of typed questions per issue: what kind, how severe, how urgent, whether it duplicates another, and what a maintainer should do next. People correct the answers, corrections are shown back on later runs, and nothing is written back to GitHub.
Three.js drone simulation with a typed Python and FastAPI backend where jev-latest chooses each navigation action. The Choice distribution, Noul obstruction estimate, confidence, latency and the exact model input and output are visible beside the flight.

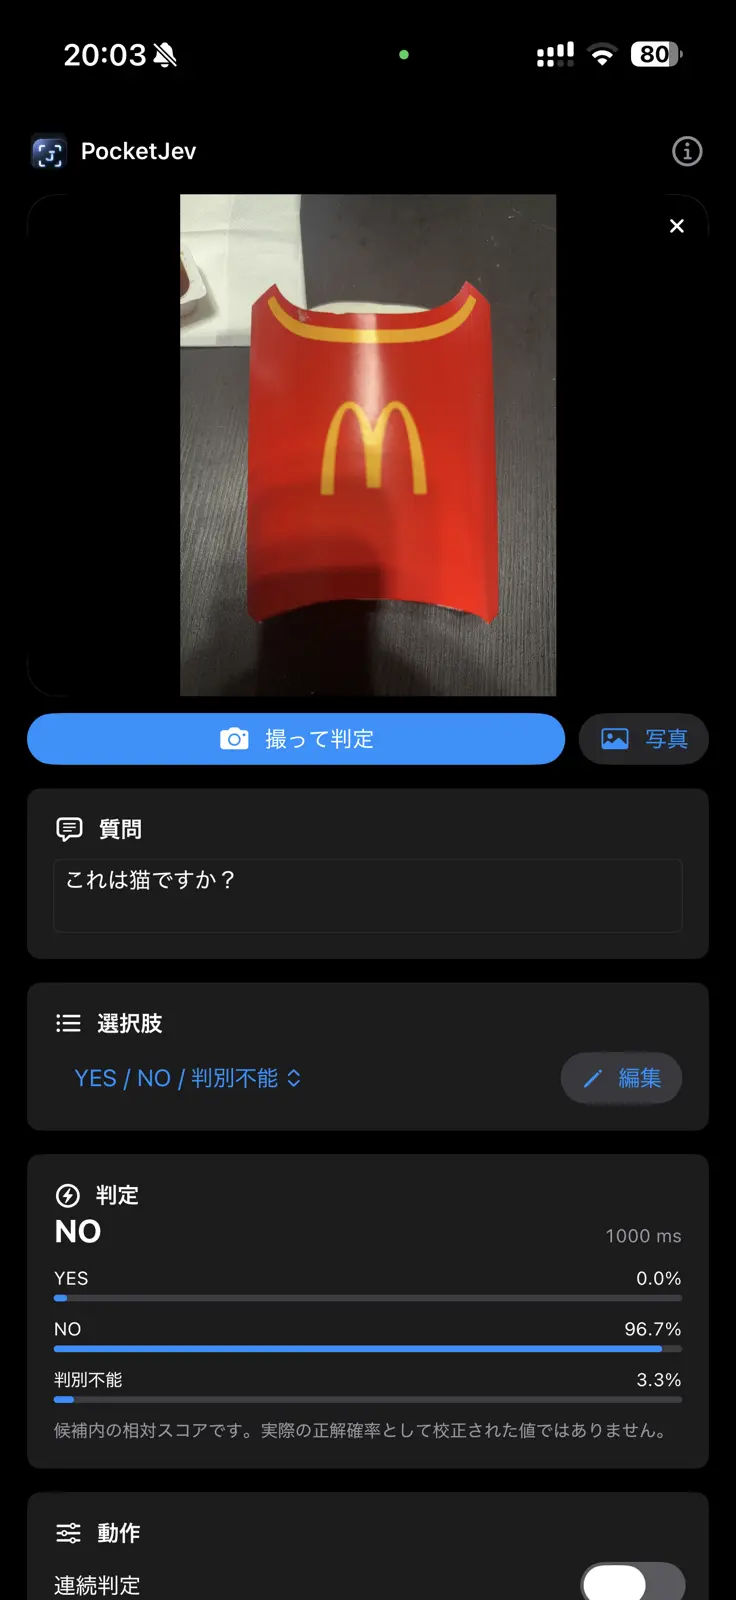
Experimental SwiftUI iPhone app that turns a small vision-language model into an on-device multiple-choice decision tool, reading the next-token logits for A, B, C instead of generating an answer. The displayed percentages are relative scores among the supplied choices, not calibrated probabilities.
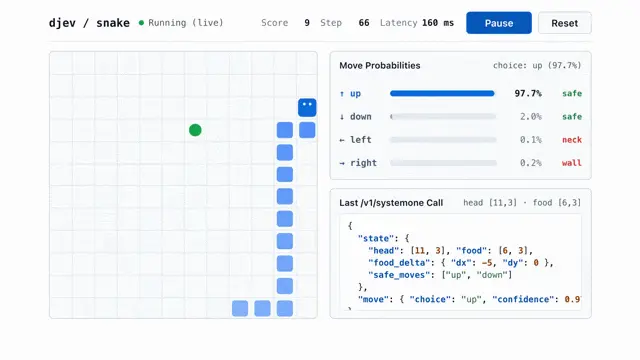
Desktop Snake where Jev assesses the board and Python combines the answers into a move, one API call per game tick. One recorded run reached 29 foods in 461 ticks before trapping itself; the agent spots immediate hazards but does not plan a route.
Rust derive layer that turns ordinary enums and structs into Choice, Score and Noul questions and returns compile-time-checked answers. Results carry confidence, so a policy can gate on it before acting.
Minecraft Java player controlled by Jev, with live decision display, a Canadian flag building task, and a side-by-side dashboard.
Unofficial Rust client mirroring the official Python SDK's environment variables, defaults, retry semantics and error classification. Published as the typesafe-ai-sdk crate.
Unofficial PHP SDK for the System One API supporting yes/no, category and scoring questions, with synchronous calls and asynchronous requests via Guzzle promises.
LLM-agnostic guardrails library using Jev to detect prompt injection, jailbreak attempts, PII exposure and credential leaks in one batched request. Not published to PyPI at time of check.
Unofficial Go SDK for the Jev API with deliberately minimal abstractions over Choice, Noul and Score.
A Jev-based model-routing experiment for Codex tasks that the author now recommends against adopting: in a Pokedex benchmark, the Jev-routed team cost almost as much as running the top model alone and missed the time limit, while the single-model run finished and passed all checks. Code and results are public as a negative benchmark.

Answers four routing questions about an agent turn, model tier, effort, tools and skill, in a single Jev call under 350ms with a hard deadline, and ships a Claude Agent SDK adapter.
A macOS menu bar app that serves Laya over an OpenAI-compatible HTTP endpoint, so n8n's Text Classifier node can run email classification locally with no cloud call and no Dock window.
Idiomatic Elixir client for the TypeSafe AI API with configuration-driven auth, retries, telemetry and test support. Returns judgments as data structures the caller thresholds itself.
An interactive Chicago traffic simulator comparing three signal policies on the same scenario: fixed timing, adaptive queue-based signals, and a citywide policy from Jev.
Tests whether a System One model can steer music: Jev picks the musical plan using fixed options only, and separate code renders the sheet music, audio and MIDI.

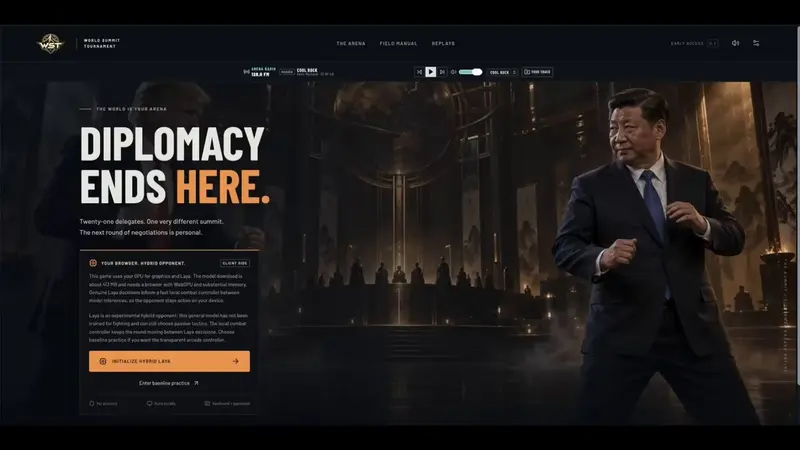
Browser fighting game with 21 satirical world-leader fighters, where the AI opponent's moves run on the Laya decision model client-side via WebGPU.
Machine client that browses HAL hypermedia by choosing the next link from what a page's ALPS profile declares, using Laya-MLX to pick among the server-offered affordances.

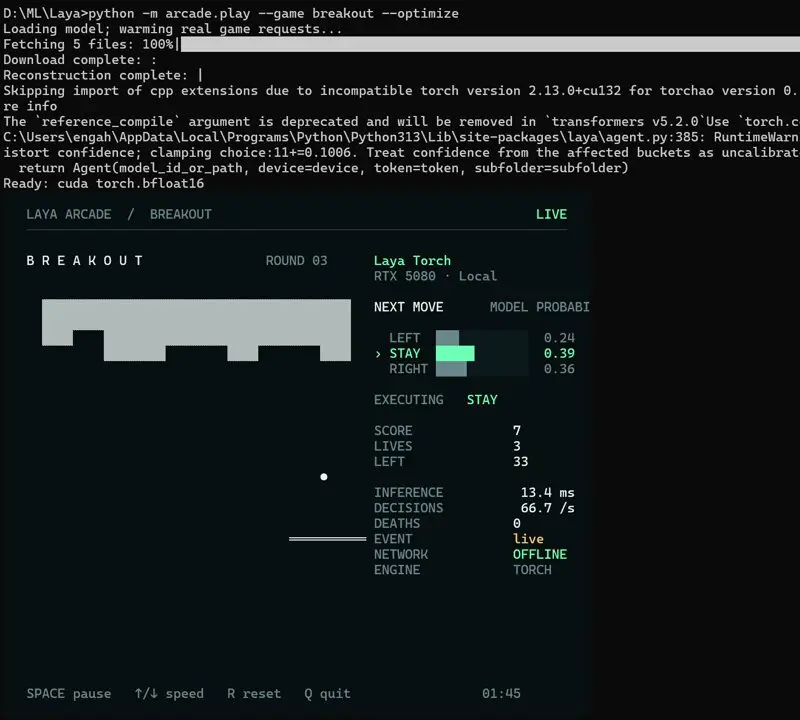
An open-weight Laya model plays Breakout live on Windows, choosing each paddle move as a single choice question at about 70 decisions per second on an RTX 5080, with no planner or safety shield.
PostgreSQL extension that runs Laya decision-model inference natively inside the database, using Rust and Candle.

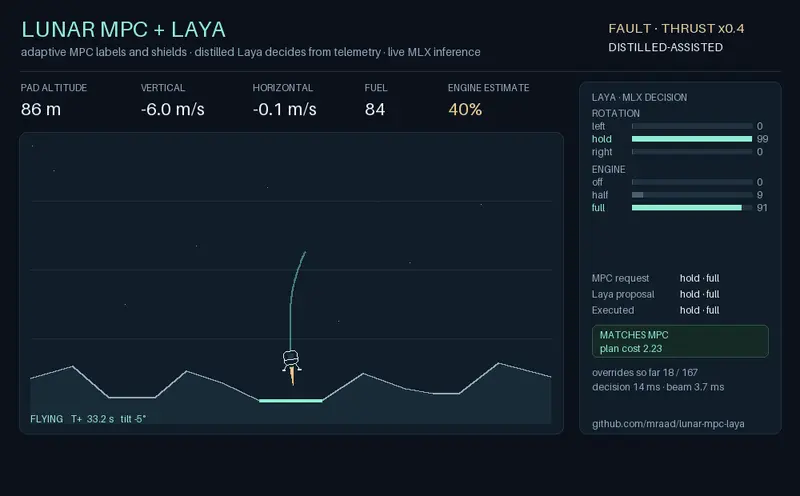
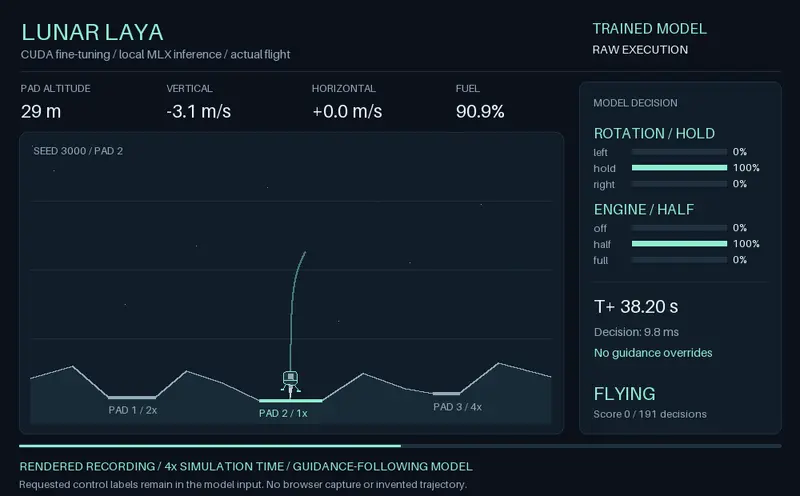
Adaptive model predictive control guides and vetoes a Laya decision model piloting a lunar lander. Laya alone lands 0/90; with MPC's veto it lands 90/90 through a 60% engine power loss.

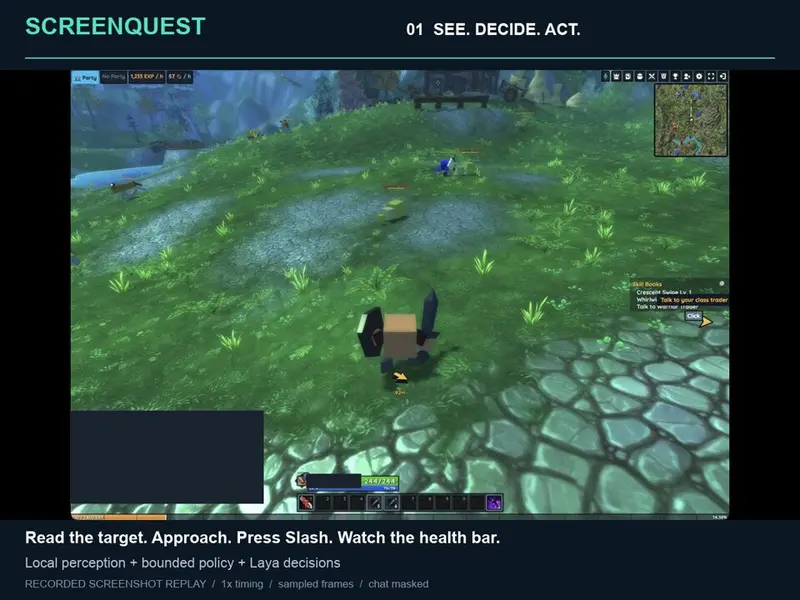
Screenshot-to-action game agent for Hordes.io: Qwen plans from screenshots, Laya makes the typed real-time decision, and Apple Vision OCR reads the screen, all running locally on Apple Silicon.
Runs Laya's English typed-decision checkpoint on a Windows machine with an AMD Radeon RX 6900 XT (gfx1030) GPU through a pinned PyTorch ROCm build, with an optional Jev-compatible HTTP loopback service.

A zero-shot benchmark of Jev, self-hosted Kev-9B and self-hosted Laya on 171 Moroccan Darija reviews in Arabic script and Arabizi. Jev scored 79.5 percent accuracy, Kev-9B 71.9 percent, and Laya 53.8 percent, tying an always-positive baseline.
A community Unity package, installable via the Package Manager git URL, giving a backend-independent C# client for typed Choice/Score/Noul decisions against local Laya servers or TypeSafe-compatible endpoints.

A 322M-parameter Laya checkpoint plays a Pac-Man-inspired game on Windows with CUDA, using typed decisions and live probability output.
A simulated Swedish villa energy system compares Laya's live one-minute decisions against a naive charger, a tariff-aware controller and an optimal plan, cutting the naive controller's bill from 985 to 530 SEK.
A Home Assistant conversation integration that routes spoken or typed commands through Jev for intent classification and device control instead of a general-purpose LLM.
A live tone checker that scores a draft message with Laya as you type: a choice question for tone, a score question for formality, and a noul question for fight risk, answered in 40 to 110 ms per check.
A guide-directed leveling agent for a private World of Warcraft: The Burning Crusade 2.4.3 server, built so it gets cheaper to run the longer it plays.
A local computer-use runtime for Codex and Waku that adds a Jev fast path alongside Cua.

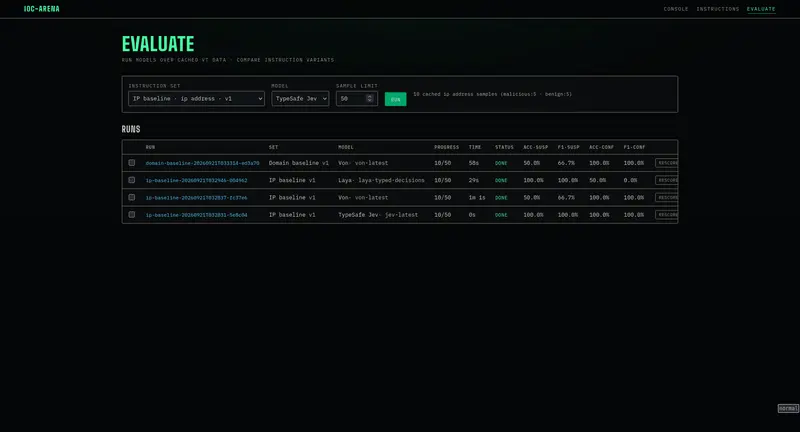
A self-hosted app that runs VirusTotal data on IP addresses, domains and file hashes through Jev, Von and Laya so you can compare the models against each other on the same labelled dataset.
Compares Jev with Laya before and after task-specific fine-tuning across Banking77 and five other public workflows, plus a chat-moderation study. Fine-tuning raised Laya's Banking77 accuracy from 51.3 to 79.4 percent, close to Jev's 80.0 percent.
Benchmarks Jev against Laya on 14 PostgreSQL statements with deliberately planted bugs, scoring which model catches more of the SQL defects.

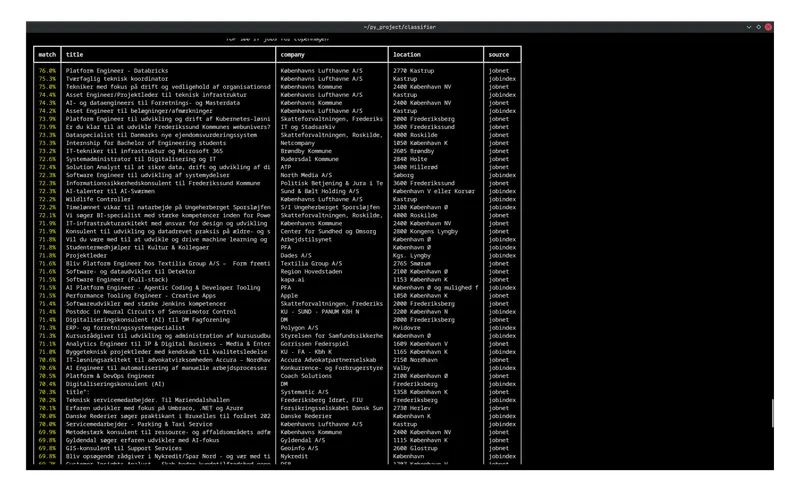
Collects job ads from two Danish job sites, filters them against a candidate profile, and ranks the rest with a multilingual Laya model answering nine typed questions per ad before printing ranked tables.

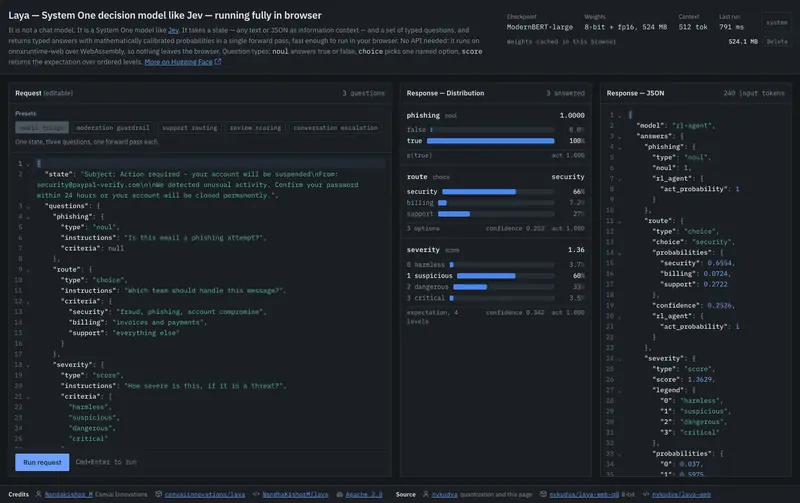
Laya's English checkpoint quantized to 8-bit and run entirely client-side via onnxruntime-web WebAssembly, with an editable JSON playground, three question types, calibrated confidence and weights cached in the browser.

Atari-style lunar lander simulation with a CUDA-trained Laya checkpoint that lands 30/30 held-out flights locally on Apple MLX, plus a browser flight recorder.
A Clay agent skill and Python workflow that scores and ranks B2B leads with Jev for prospect qualification and people search.
Nothing matches those filters
Clear a filter to widen the search, or send us the thing you were looking for.