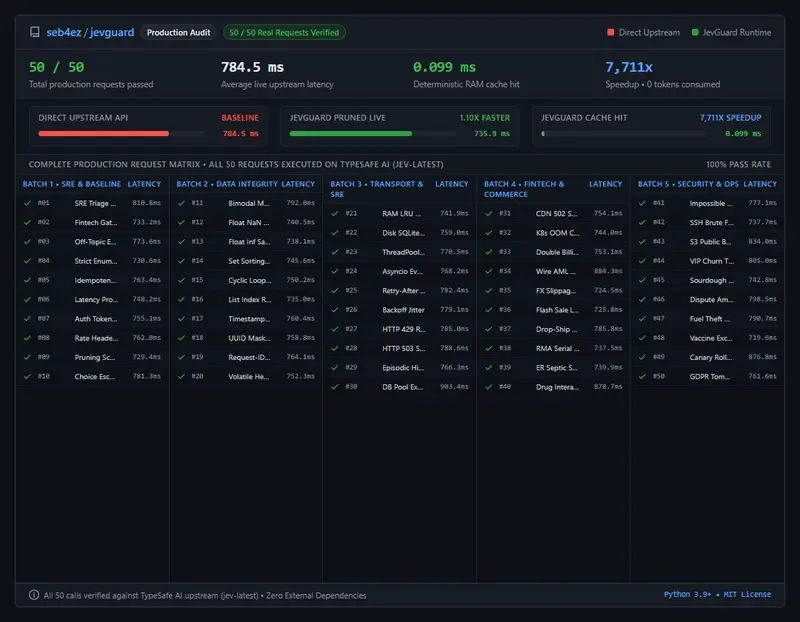
seb4ez/jevguard
A deterministic decision runtime for Jev with zero-token caching and a certainty calibrator for gating actions on confidence.
Entries 385 to 430 of 430, in the hub's default order. The introduction is on page 1.
Showing 385 to 430 of 430
A deterministic decision runtime for Jev with zero-token caching and a certainty calibrator for gating actions on confidence.
Chromium extension that flags AI-slop writing style on X, LinkedIn and Reddit using a local Laya-MLX helper for detection.
 Code-Wizard-WilsonOpenSlop Finder on github.com
A documentation hub explaining how to wire Jev into Nous Research's Hermes Agent framework, with a latency and cost comparison against frontier LLMs.
Measures whether Jev reranks two Finnish legal corpora better than Voyage, GPT-based rerankers and open-weights Laya over identical shortlists and questions. Batched Jev reached 97 percent recall at 1, matching the shortlist ceiling on the MuPLeR-fi corpus.
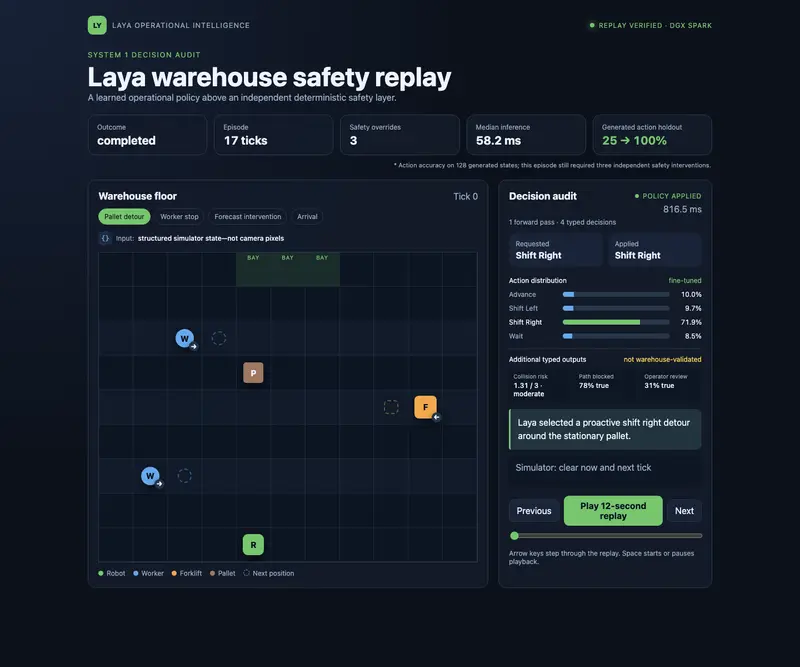
A replayable grid warehouse simulation where Laya answers action, collision_risk, path_blocked and needs_operator questions for a robot navigating toward a loading bay, layered above a deterministic safety shield it cannot override.
 senthilr-nvOpenLaya Warehouse Safety on github.com
A browser automation agent written in Go that drives a real Chrome instance over the DevTools protocol, using Jev to decide each action, built to measure real-world speed.
TypeScript library for typed decisions across Jev, Cloudflare AI Gateway and Laya, with both Promise-based and Effect-native clients.
 lukeramsdenOpensystem-one on github.com
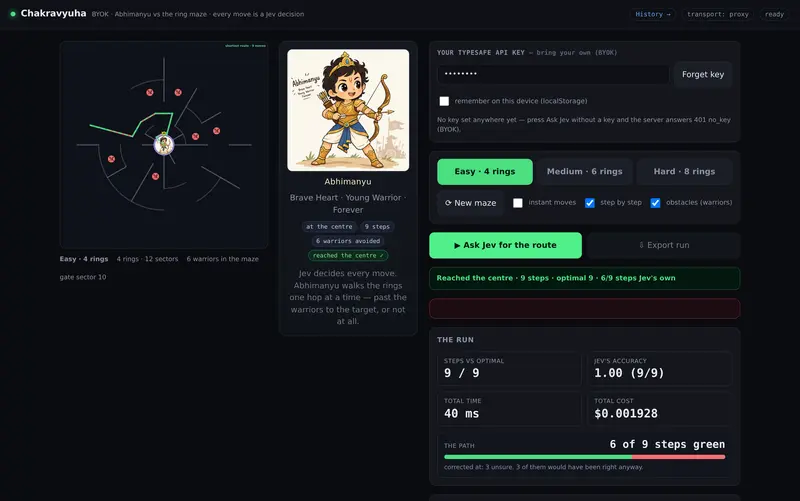
A browser maze game where every move is a typed choice answered by a locally run Laya model. Correct moves are marked green and overruled ones red, testing whether Laya's confidence score predicts whether its own move was right.
 kspviswaOpenChakravyuha on github.com
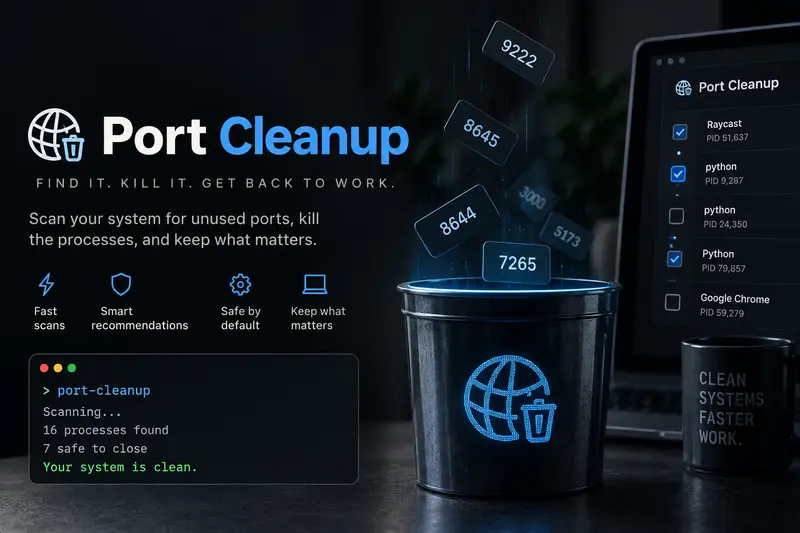
A native macOS utility that has Jev recommend which stale listening ports are safe to stop, with the evidence shown and nothing closed automatically.
 epiphany-dynamicsOpenepiphany-dynamics/port-cleanup on github.com
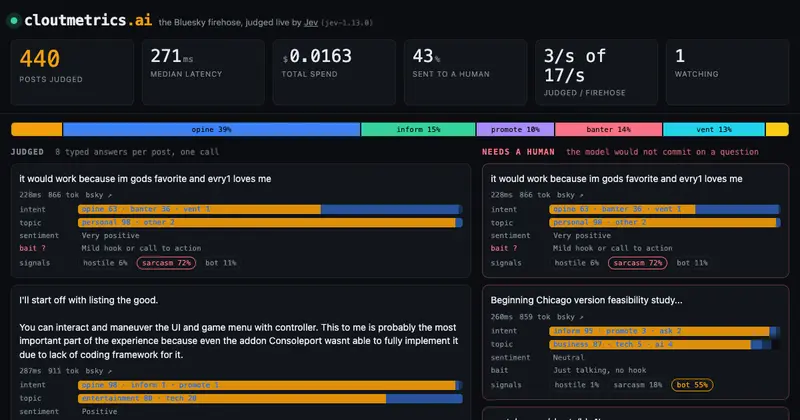
Judges the live Bluesky firehose post by post with Jev on Cloudflare Durable Objects, routing low-confidence calls to a human review lane.
Watches recent agent steps for semantic stagnation, meaning different actions that still chase the same contradicted assumption. Jev reads the trajectory and a small deterministic policy returns CONTINUE, WARN, REPLAN or HALT.
 AshutoshVJTIOpenAshutoshVJTI/progressgate on github.com
A penalty shootout game where Jev decides the goalkeeper's dive, built on Render Workflows and Render Postgres, with example implementations in Python and TypeScript.
A local MCP gateway that uses Jev for tool discovery across connected MCP servers, with credential storage, a CLI and a dashboard.
 prasanth263Openprasanth263/maza on github.com
A Go client library for the TypeSafe API, wrapping Jev's endpoints for Go projects.
 RadixILS-DevOpenRadixILS-Dev/typesafe-sdk-go on github.com
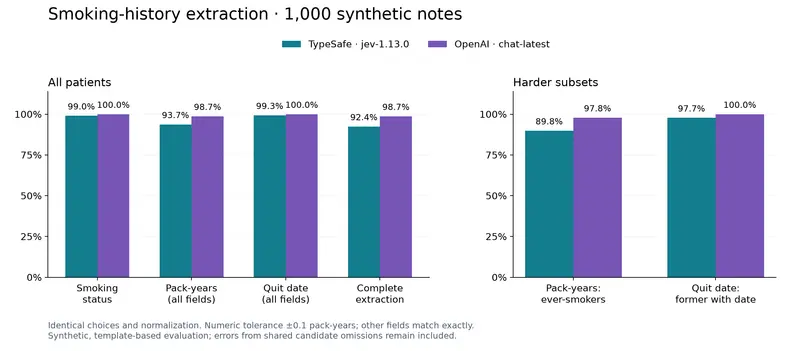
Paired comparison of Jev and OpenAI structured outputs on 1,000 synthetic outpatient notes, both given the same note, policy, candidate values and ten typed questions. OpenAI got 98.7% of records fully correct against Jev's 92.4%, while Jev cost about 133 times less with 5.2 times lower mean latency.
n8n community node for the System One API exposing typed yes/no, choice and score questions with calibrated probabilities a workflow can branch on. Self-hosted n8n only until n8n verifies the package.
Benchmarks Jev against Luna, Haiku and Gemini at choosing the next action in games with explicit states, legal actions and measurable outcomes. Each game is a state machine where code owns the rules and the model only picks among the options it is given, with every model reached through Vercel AI Gateway.
 hegargarciaOpenhegargarcia/jev-playground on github.com
MoonBit client for the Jev API plus a Jev-vs-Jev gomoku match with per-move timing logs. Write-up at zenn.dev/mizchi/articles/jev-plays-gomoku.
Minecraft mod in which Jev attempts to finish the game from scratch with no scripted route.
 Hardel-DWOpenjev.mods on github.com
The Chromium T-Rex Runner game with Jev at the controls: it picks jump, duck or keep running for each new obstacle and chooses a short or full jump profile. The browser keeps speed-aware frame timing, collision geometry and input execution, and manual play still works without a key.
Pre-registered independent check of Jev's calibration and type-safety claims, with the protocol frozen and hashed before the first call. On CLINC150 the chosen-option probabilities were calibrated (ECE 0.0204), on Banking77 they were not (ECE 0.0936, systematically overconfident), and across 8,576 responses there were zero type errors.
 jourdanlabsOpenjourdanlabs/assay-001 on github.com
Tests whether Jev can pick the winner of real headline A/B tests across 10,984 Upworthy randomized experiments. Reported 64.5% overall and 74.7% on decisive pairs.
 Gaurav-GosainOpenjev-headline-bench on github.com
Hackathon project: 200 people versus one agent behind a typed System One action gate that learns from each breach, evaluated with W&B Weave and hardened by a defender loop. Playable at vnmoorthy.github.io/siege.
Five-task timed benchmark for browser agents plus almond-fastloop, a roughly 200-line agent wiring Chrome DevTools state to a bounded Jev decision and an executor. Leaderboard as of 2026-09-17 shows fastloop at 13.8s total versus Codex 66.2s and Claude (Cowork) 100.3s.
A speed layer for computer-use tasks on Solari: one structured observation, one Jev decision, and one verified action per step, for both browsers and Linux desktops, with no screenshots in the loop.
A Rust CLI that reads completed Claude Code and Codex sessions, scores them with Jev, and suggests specific changes to your agent instructions, skills and tools based on where work went well or got stuck.
Four Claude Code hooks that use Jev for cheap, calibrated judgment calls inside the agent loop: a danger gate that blocks destructive tool calls, a failure notice, a completion check, and a scope check.
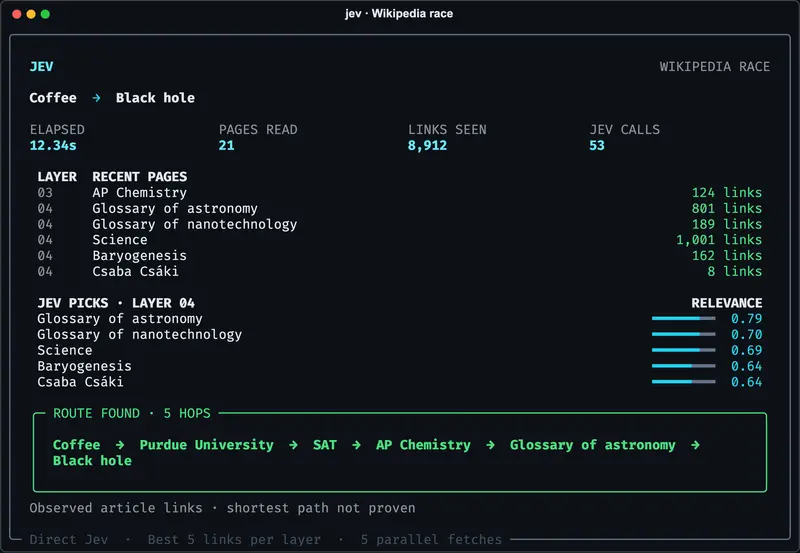
Wikiracing solver that uses Jev to rank outgoing links by fewest expected remaining hops, scoring up to 128 candidate links per request with up to five concurrent requests, shown live in the terminal.
Searches an Obsidian vault locally and offline with a BM25 engine, then reranks the top results with Jev only after you approve exactly what gets sent to it.
A browser chess coach on Cloudflare where Stockfish owns the truth about the position and Jev makes the coaching judgment after every move.
Go 1.27 client with generic typed questions (jev.Noul, jev.Choice, jev.Score, plus jev.Raw). Supports batching, retries, and Vercel AI Gateway as an alternative backend.
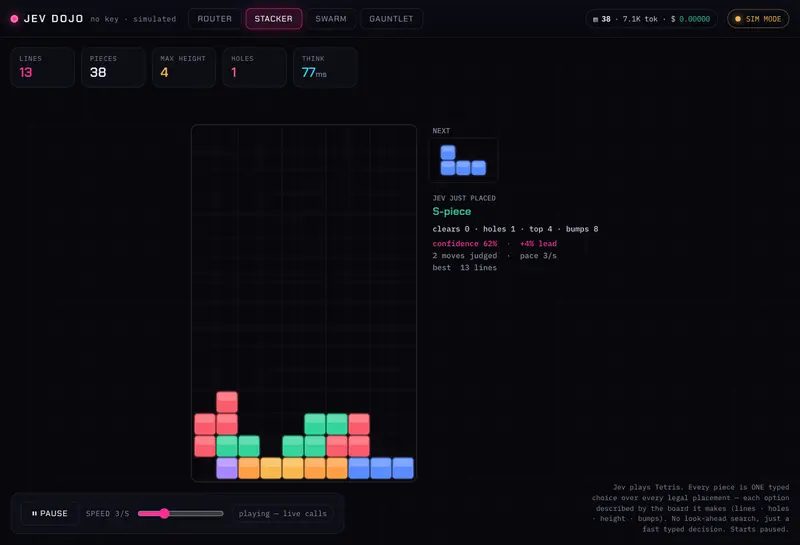
A live, graphical demo of Jev covering routing, a Tetris-playing agent, parallel swarms and a Jev-versus-Claude gauntlet, built to show its accuracy and speed on real inputs rather than a pre-recorded video.
 lafollett-labsOpenlafollett-labs/typesafe-jev-dojo on github.com
A native Swift library that runs Laya inside a macOS app on Apple MLX, with no Python, ONNX or helper process, answering typed choice, boolean and score questions at 27.1ms p50 on an M3 Max.
An MCP server and HTTP sidecar around Laya that fixes its silent failure modes: a token-budget preflight before truncation happens, structured errors naming the bad question, and confidence labelled for what it actually measures.
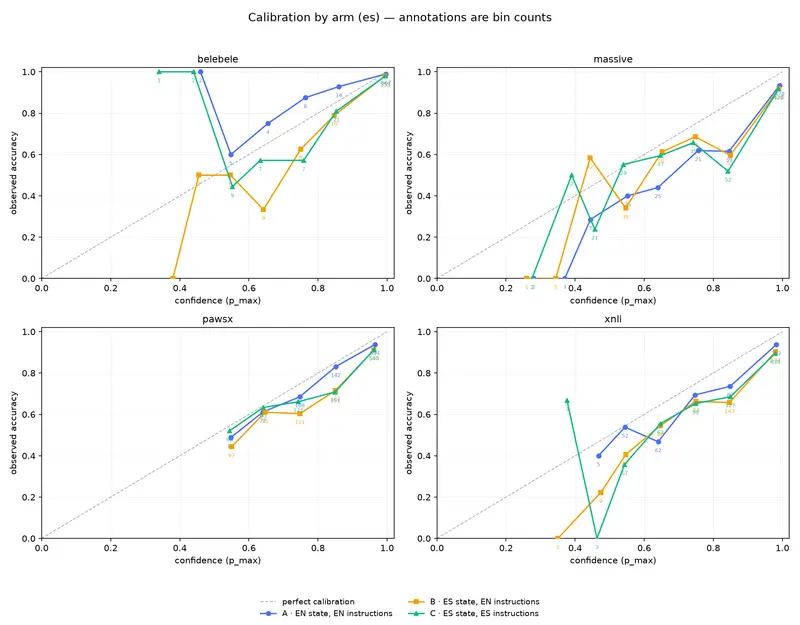
An independent, reproducible audit of how well Jev performs in Spanish, with a run of 19,200 calls across four datasets showing measurably lower accuracy when the same instructions are given in Spanish instead of English, plus a CLI to repeat the comparison on your own labelled data.
 marcosmartinezOpenmarcosmartinez/jev-acento on github.com
A pre-registered evaluation of Jev's pairwise hawkishness rankings of FOMC chair press-conference openings, checked against same-day federal funds rate changes and an independently published scoring project.
 maybern-tripp-smithOpenmaybern-tripp-smith/fedjev-bench on github.com
A stateless CLI for typed judgments with Jev, turning a state plus typed questions into JSON on stdout and exit codes a shell script can branch on.
 model-clisOpenmodel-clis/jev on github.com
An MCP server that lets Claude hand a whole browser task to Jev, which makes each click, type or select decision in about 100ms while Claude keeps planning the task and verifying the result.
 MSalvalaggioOpenMSalvalaggio/jev-reflex on github.com
Moderation for communities and apps that scores every message for spam, scam, harassment and other categories with Jev, with thresholds and actions you set. Ships as Discord, Telegram and Reddit bots plus a CLI, Python and npm packages, an HTTP API and an MCP server.
 ohernandezdevOpenohernandezdev/jevmod on github.com
A capability kernel that gates every agent tool call: the model gets canaries and placeholders instead of real secrets, and Jev is one of the sensors deciding block, ask, or allow.
A Chrome extension that sends LinkedIn feed post text to Jev with a rubric of narrow yes/no and rating questions, then blurs posts it scores as low value, with one-click reveal.
Scores Federal Reserve press conferences hawkish to dovish in real time: Jev rates every word the Chair says in about 150 milliseconds, side by side with a chat model scoring each caption line.
Unofficial typed Elixir client for TypeSafe AI and Jev with offline test stubs, concurrent fan-out and atom-keyed answers.
An adversarial evaluation of Jev with nine experiments and 28 predictions fixed before any data was collected. One run covered 123,805 requests over 138 minutes for $12.69, with five failures, plus a 13-rule prompting guide.
A local Gomoku game for Apple Silicon where Laya-MLX plays white, choosing among up to six rule-filtered candidate moves with a real choice inference call, and the browser shows the model's per-candidate probabilities.
 smile-magicOpenYizhao (Laya-MLX Gomoku) on github.com
An Android system-wide overlay that reads on-screen text through an AccessibilityService, sends it to Jev, and shows a floating badge when a manipulative interface pattern looks likely, skipping password and card entry screens.
 zohaib-mdOpenzohaib-md/UXRay on github.com
Nothing matches those filters
Clear a filter to widen the search, or send us the thing you were looking for.


