Laya Serve for macOS
A macOS menu bar app that serves Laya over an OpenAI-compatible HTTP endpoint, so n8n's Text Classifier node can run email classification locally with no cloud call and no Dock window.
Entries 49 to 96 of 106, in the hub's default order. The introduction is on page 1.
Showing 49 to 96 of 106
A macOS menu bar app that serves Laya over an OpenAI-compatible HTTP endpoint, so n8n's Text Classifier node can run email classification locally with no cloud call and no Dock window.
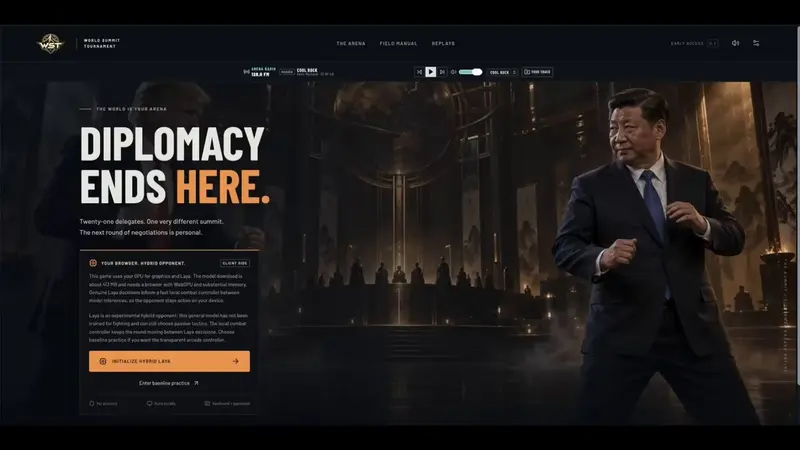
Browser fighting game with 21 satirical world-leader fighters, where the AI opponent's moves run on the Laya decision model client-side via WebGPU.
Machine client that browses HAL hypermedia by choosing the next link from what a page's ALPS profile declares, using Laya-MLX to pick among the server-offered affordances.
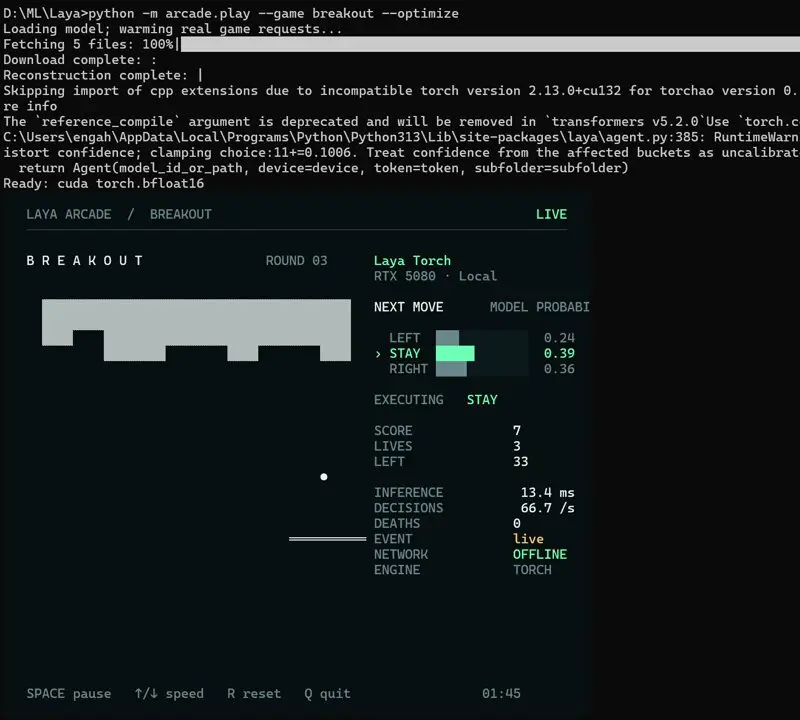
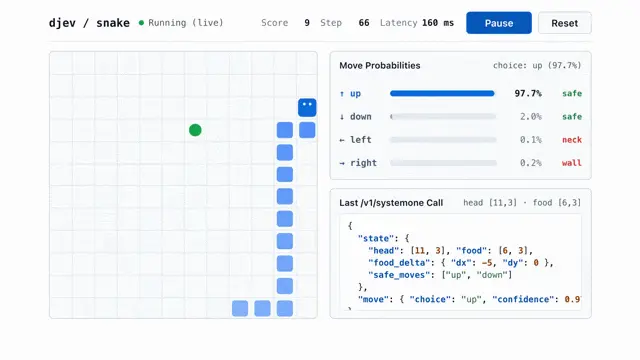
An open-weight Laya model plays Breakout live on Windows, choosing each paddle move as a single choice question at about 70 decisions per second on an RTX 5080, with no planner or safety shield.
PostgreSQL extension that runs Laya decision-model inference natively inside the database, using Rust and Candle.
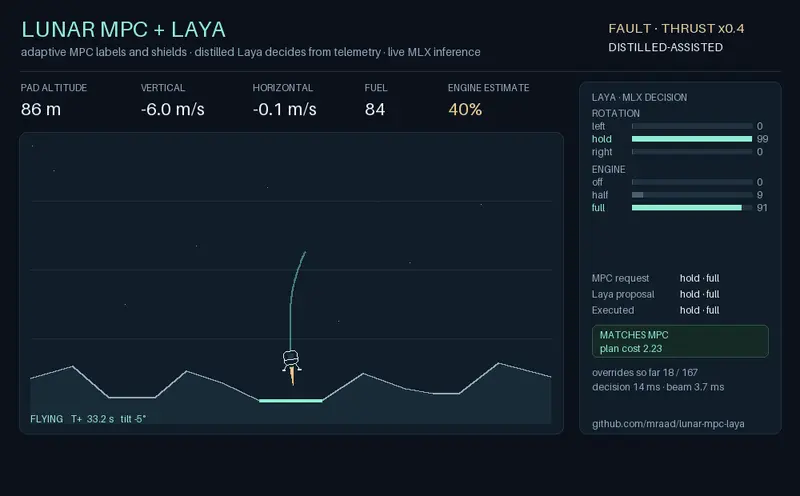
Adaptive model predictive control guides and vetoes a Laya decision model piloting a lunar lander. Laya alone lands 0/90; with MPC's veto it lands 90/90 through a 60% engine power loss.
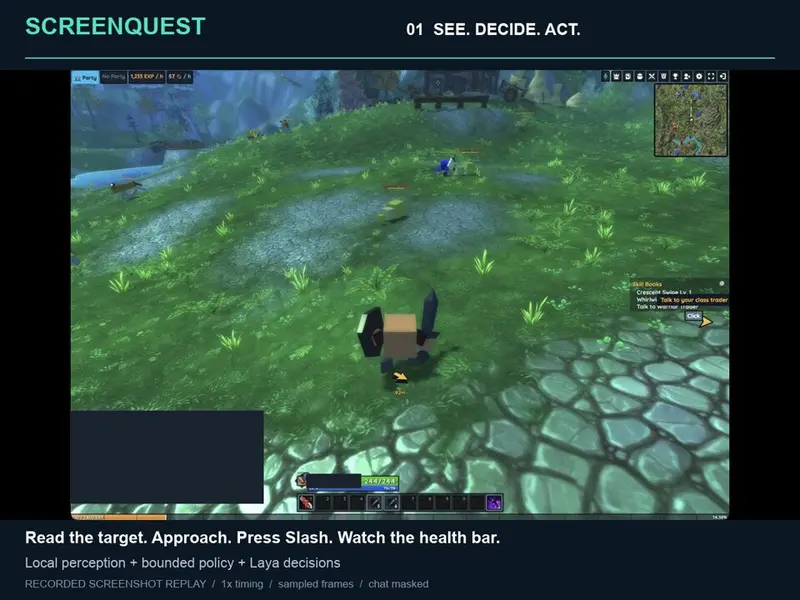
Screenshot-to-action game agent for Hordes.io: Qwen plans from screenshots, Laya makes the typed real-time decision, and Apple Vision OCR reads the screen, all running locally on Apple Silicon.
Runs Laya's English typed-decision checkpoint on a Windows machine with an AMD Radeon RX 6900 XT (gfx1030) GPU through a pinned PyTorch ROCm build, with an optional Jev-compatible HTTP loopback service.
A zero-shot benchmark of Jev, self-hosted Kev-9B and self-hosted Laya on 171 Moroccan Darija reviews in Arabic script and Arabizi. Jev scored 79.5 percent accuracy, Kev-9B 71.9 percent, and Laya 53.8 percent, tying an always-positive baseline.
A community Unity package, installable via the Package Manager git URL, giving a backend-independent C# client for typed Choice/Score/Noul decisions against local Laya servers or TypeSafe-compatible endpoints.
 0x440-1meOpenLaya Unity on github.com
A 322M-parameter Laya checkpoint plays a Pac-Man-inspired game on Windows with CUDA, using typed decisions and live probability output.
A simulated Swedish villa energy system compares Laya's live one-minute decisions against a naive charger, a tariff-aware controller and an optimal plan, cutting the naive controller's bill from 985 to 530 SEK.
A live tone checker that scores a draft message with Laya as you type: a choice question for tone, a score question for formality, and a noul question for fight risk, answered in 40 to 110 ms per check.
 roisol144OpenBefore You Send on github.com
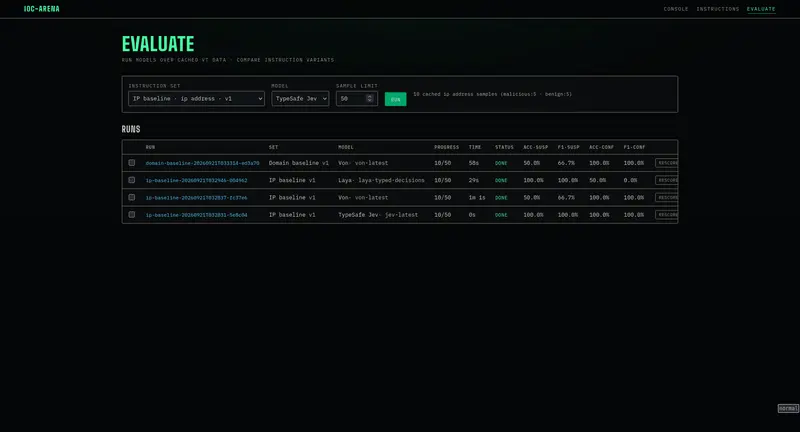
A self-hosted app that runs VirusTotal data on IP addresses, domains and file hashes through Jev, Von and Laya so you can compare the models against each other on the same labelled dataset.
 hc-nolanOpenIOCArena on github.com
Compares Jev with Laya before and after task-specific fine-tuning across Banking77 and five other public workflows, plus a chat-moderation study. Fine-tuning raised Laya's Banking77 accuracy from 51.3 to 79.4 percent, close to Jev's 80.0 percent.
 Alexander-OllmanOpenJev vs fine-tuned Laya on github.com
Benchmarks Jev against Laya on 14 PostgreSQL statements with deliberately planted bugs, scoring which model catches more of the SQL defects.
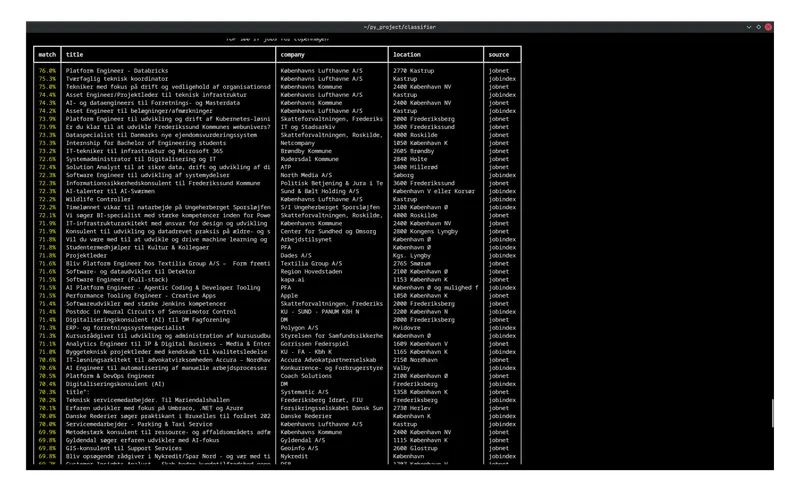
Collects job ads from two Danish job sites, filters them against a candidate profile, and ranks the rest with a multilingual Laya model answering nine typed questions per ad before printing ranked tables.
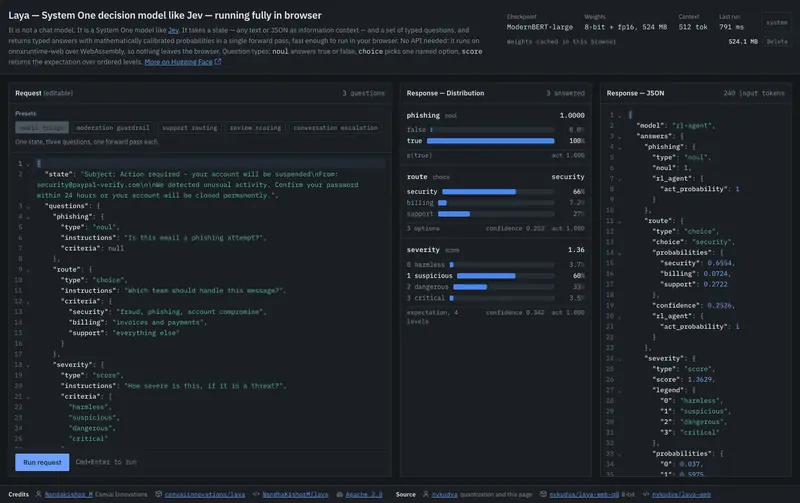
Laya's English checkpoint quantized to 8-bit and run entirely client-side via onnxruntime-web WebAssembly, with an editable JSON playground, three question types, calibrated confidence and weights cached in the browser.
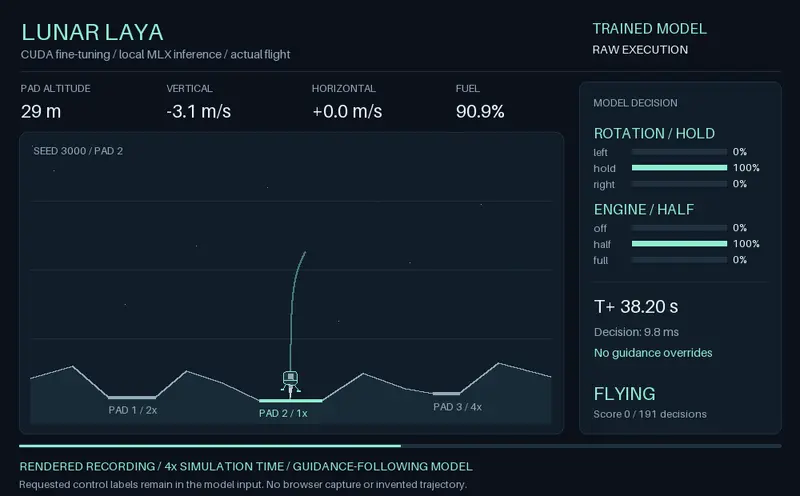
Atari-style lunar lander simulation with a CUDA-trained Laya checkpoint that lands 30/30 held-out flights locally on Apple MLX, plus a browser flight recorder.
Chromium extension that flags AI-slop writing style on X, LinkedIn and Reddit using a local Laya-MLX helper for detection.
 Code-Wizard-WilsonOpenSlop Finder on github.com
Measures whether Jev reranks two Finnish legal corpora better than Voyage, GPT-based rerankers and open-weights Laya over identical shortlists and questions. Batched Jev reached 97 percent recall at 1, matching the shortlist ceiling on the MuPLeR-fi corpus.
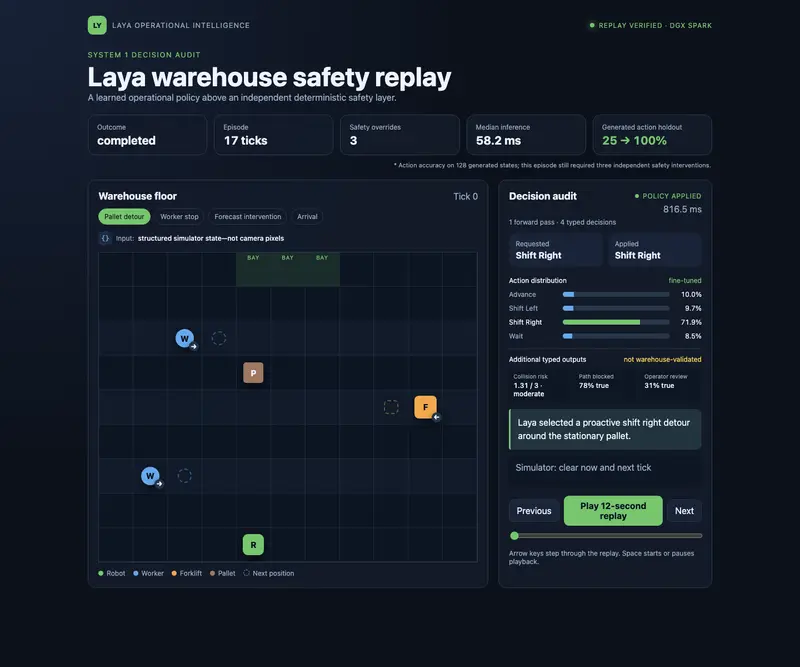
A replayable grid warehouse simulation where Laya answers action, collision_risk, path_blocked and needs_operator questions for a robot navigating toward a loading bay, layered above a deterministic safety shield it cannot override.
 senthilr-nvOpenLaya Warehouse Safety on github.com
TypeScript library for typed decisions across Jev, Cloudflare AI Gateway and Laya, with both Promise-based and Effect-native clients.
 lukeramsdenOpensystem-one on github.com
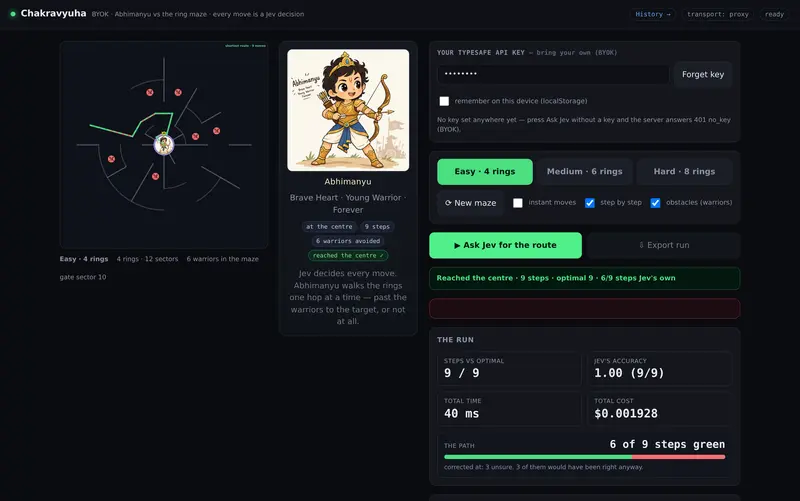
A browser maze game where every move is a typed choice answered by a locally run Laya model. Correct moves are marked green and overruled ones red, testing whether Laya's confidence score predicts whether its own move was right.
 kspviswaOpenChakravyuha on github.com
A native Swift library that runs Laya inside a macOS app on Apple MLX, with no Python, ONNX or helper process, answering typed choice, boolean and score questions at 27.1ms p50 on an M3 Max.
An MCP server and HTTP sidecar around Laya that fixes its silent failure modes: a token-budget preflight before truncation happens, structured errors naming the bad question, and confidence labelled for what it actually measures.
A local Gomoku game for Apple Silicon where Laya-MLX plays white, choosing among up to six rule-filtered candidate moves with a real choice inference call, and the browser shows the model's per-candidate probabilities.
 smile-magicOpenYizhao (Laya-MLX Gomoku) on github.com
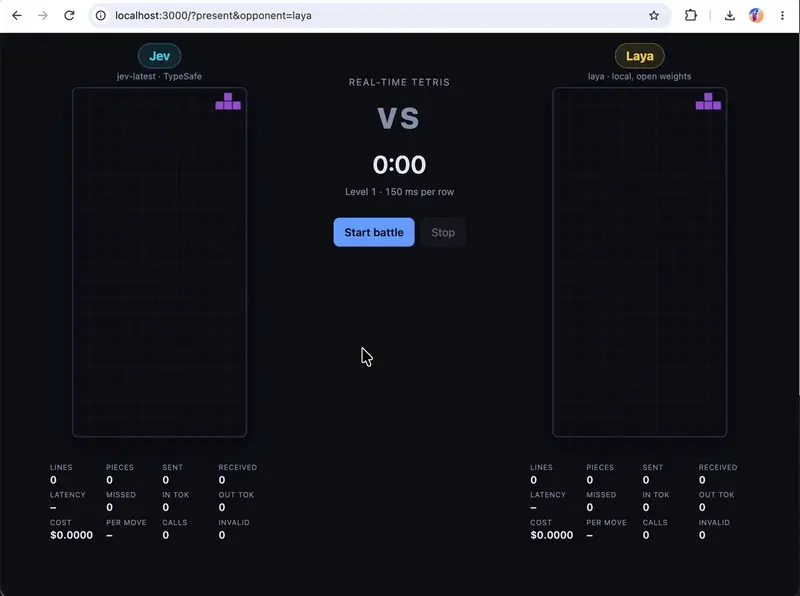
Video Tetris benchmark: Laya-MLX runs fast on a MacBook at about 84ms per decision but loses to Jev in all three rounds.
 Tony Dinh (@tdinh_me)OpenTetris Bench: Jev vs Laya-MLX on x.com
73k viewsLaya latency ~84 msResult Jev won 3/3
A leaderboard that runs Jev and 54 open System One models and clones through the same 120,000-question suite on one RTX PRO 6000, scoring accuracy and calibration. Jev leads the 0.2 edition at 51.67 on a chance-corrected scale, with AutoJev-27B close behind at 50.94.
 apolinario (poli) (@multimodalart)43k viewsOpenJev Decision Index: Jev against 50+ open decision models on huggingface.co
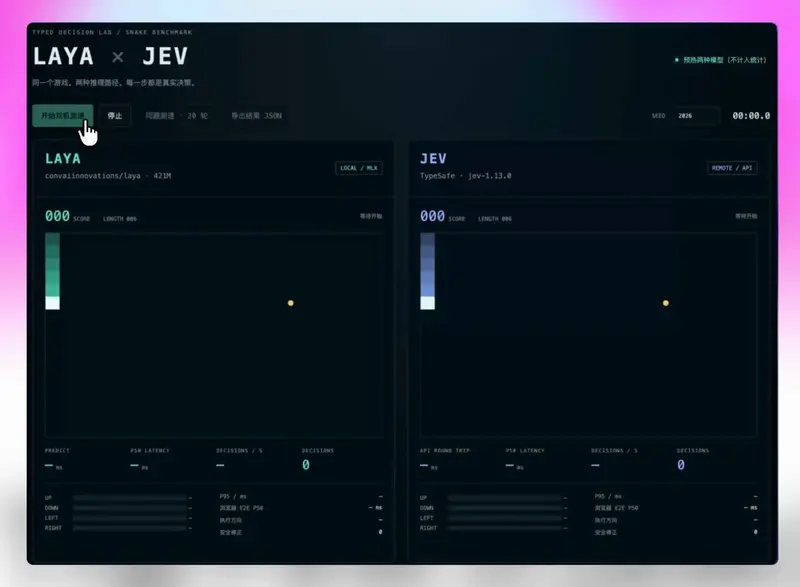
30-second Snake benchmark: a local 421M Laya checkpoint scores 46 at 86.5 decisions per second, while Jev 1.13.0 over the cloud API scores 1 at 3.2 decisions per second.
 Simplifying AI (@simplifyinAI)OpenLocal Laya vs Cloud Jev on the Same Snake Game on x.com
24k viewsLaya speed 86.5/sJev speed 3.2/s
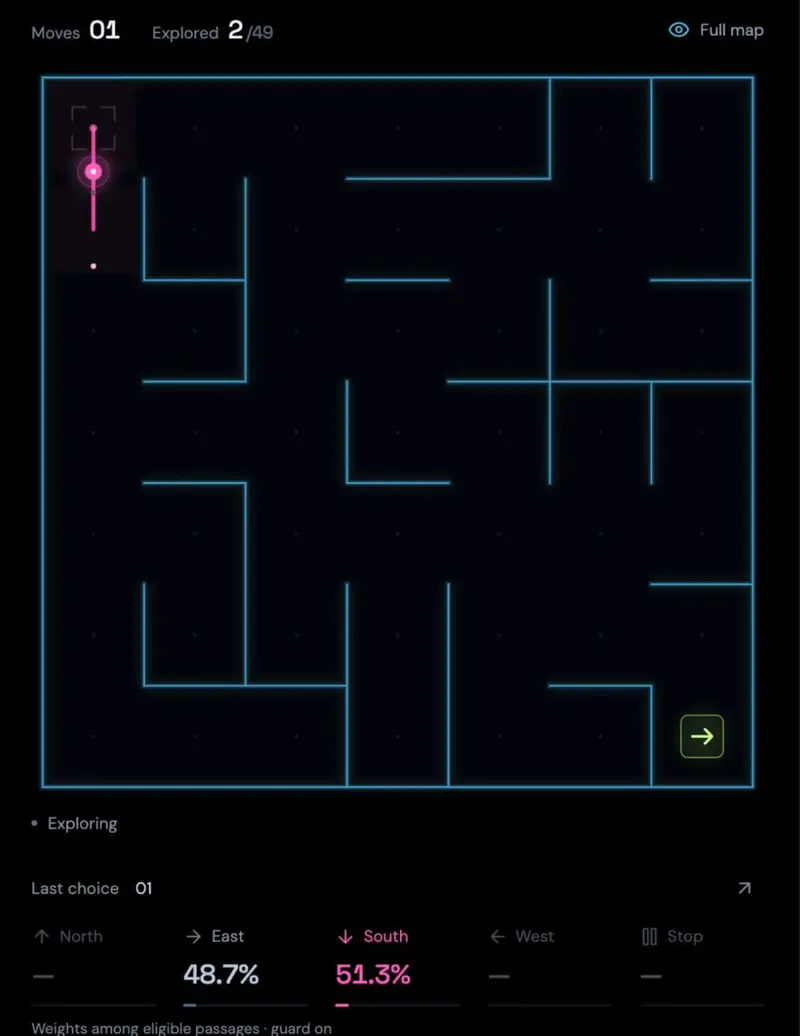
A maze demo comparing decision latency: local Laya on a base M5 responds at a 19ms median, versus roughly 300ms from Jev's cloud API for the same task.
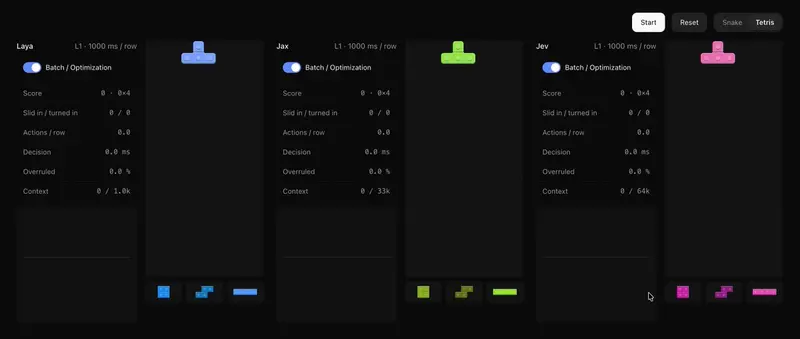
Video benchmark where Jev wins outright as a cloud model, while a self-built JAX model ties with Laya-MLX among the local, on-device options.
 Tom Siwik (@tomhacks)11k viewsOpenJev, Laya-MLX and a Custom JAX Build on a Local Game Benchmark on x.com
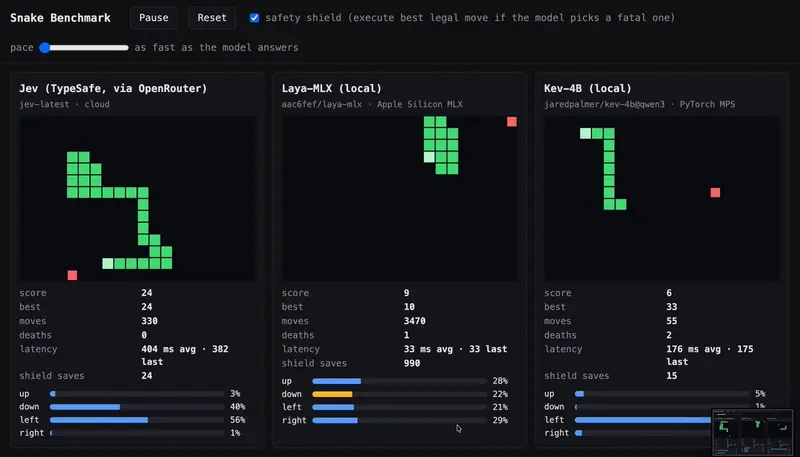
Custom Snake benchmark comparing Jev over the API against locally run Laya-MLX and Kev-4B: Jev had zero deaths, Kev died twice at about 175ms latency, and Laya died early despite roughly 33ms latency.
 Tobias Wupperfeld (@tobiaswup)3.1k viewsOpenHome-Made Snake Benchmark: Jev vs Laya-MLX vs Kev-4B on x.com
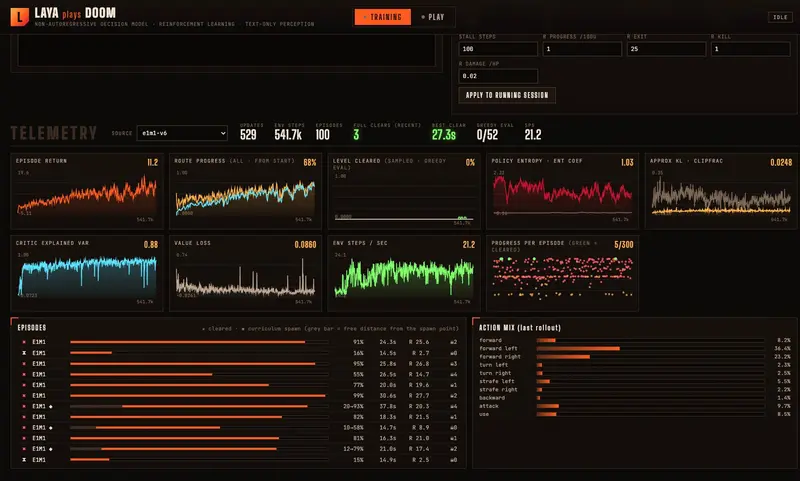
After close to 24 hours of reinforcement learning training on Doom, the author's Laya model still falls well short of Jev's zero-shot performance.
 Shantanu Goel (@shantanugoel)2.3k viewsOpen24 Hours of RL Training Laya on Doom, Still Behind Jev Zero-Shot on x.com
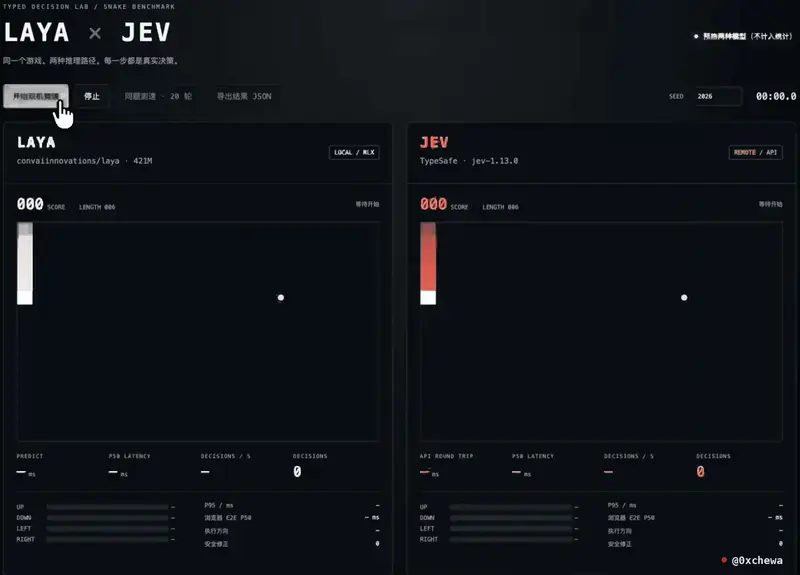
A video benchmark where local Laya beats API-hosted Jev 43-1 in Snake with wifi off: 86.4 decisions per second at 9.2ms P50 latency for Laya against 3.2 decisions per second at 308.7ms round trip for Jev, same schema and seed.
21-minute video scoring seven open-source Jev-family models on JevBench, ending with Laya, and noting write-ups conflate the multilingual 322M checkpoint's 1k context with the 421M English checkpoint's 512.
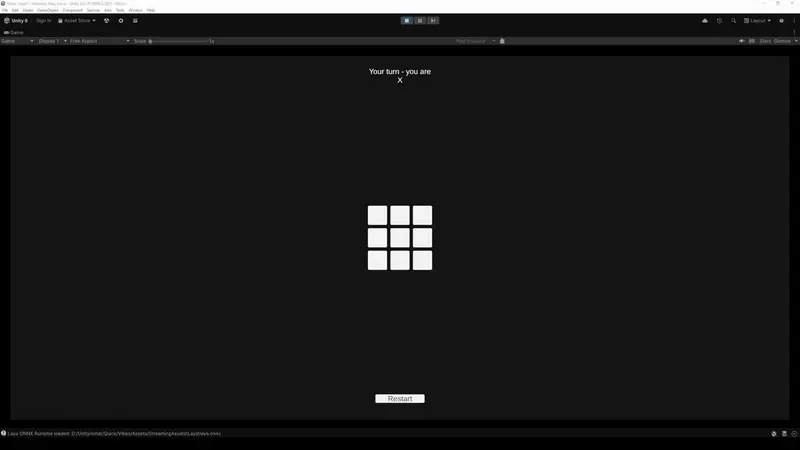
Video of a Unity scene running Laya locally as a tic-tac-toe opponent, using receptron's ONNX export of the model through asus4's onnxruntime-unity plugin.
Ran 996 questions adapted from Berkeley CS 70 finals through Jev, SemIf and Laya under the same grading. Jev scored 83.7 percent, SemIf 61.6 percent, and Laya 31.2 percent, close to the roughly 30 percent expected from random guessing.
Benchmarks Laya-MLX against Jev/Qwen3-4B inside an OpenClaw agent cascade on an M4 Pro: Laya scores 85% at 27.8ms, Jev scores 90% at 1,168ms, and 14 of 20 decisions resolve before reaching Jev.
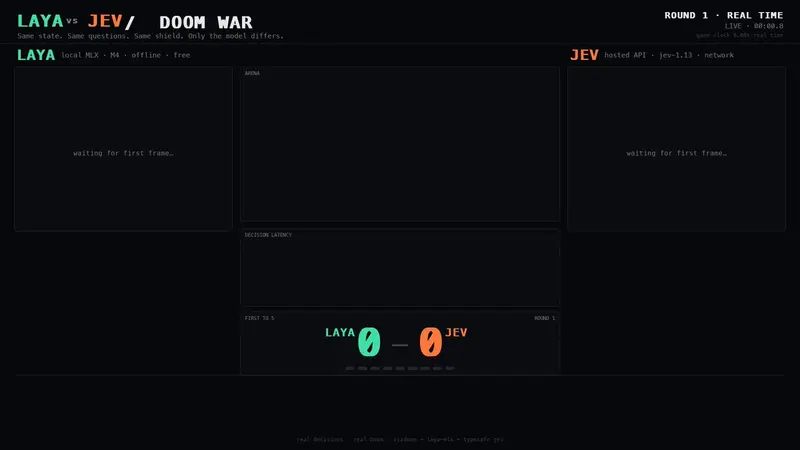
A video of Jev and Laya fighting a 1v1 Doom deathmatch with monsters between them, first to five kills wins. Jev's calls were sharper and needed fewer corrections, but Laya decided twice as often and won 5 to 1.
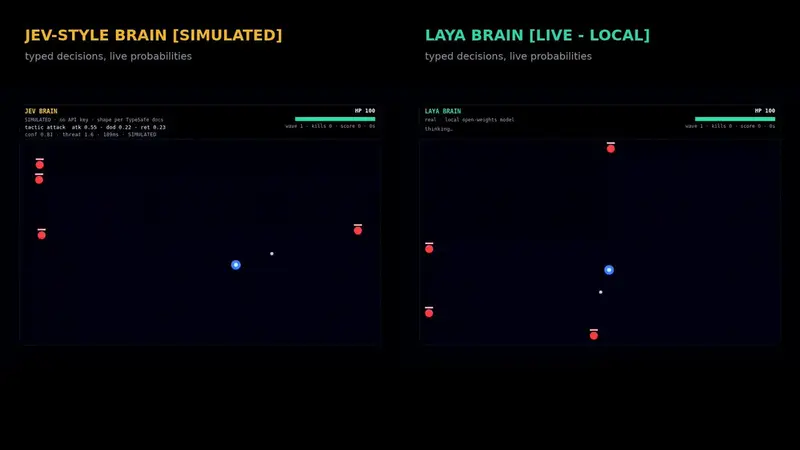
Built an arena survival game where every enemy's move is decided live by Jev or Laya, turning each moment into one typed question at about 30 decisions a second. Laya ran roughly 21ms per decision on a laptop for no cost, while Jev was more accurate out of the box on the poster's own benchmark.
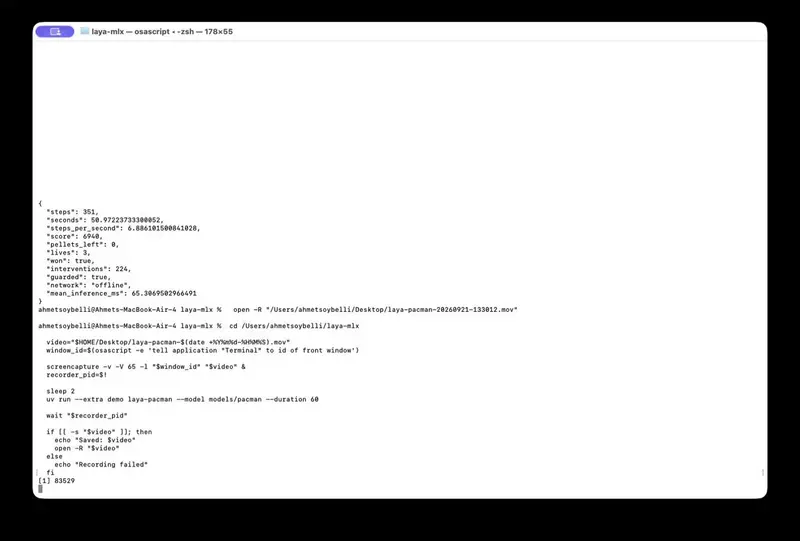
Video demo of Pac-Man controlled entirely by typed decisions from Laya-MLX running locally on Apple Silicon: 351 steps, a win, and 224 guardrail interventions logged.
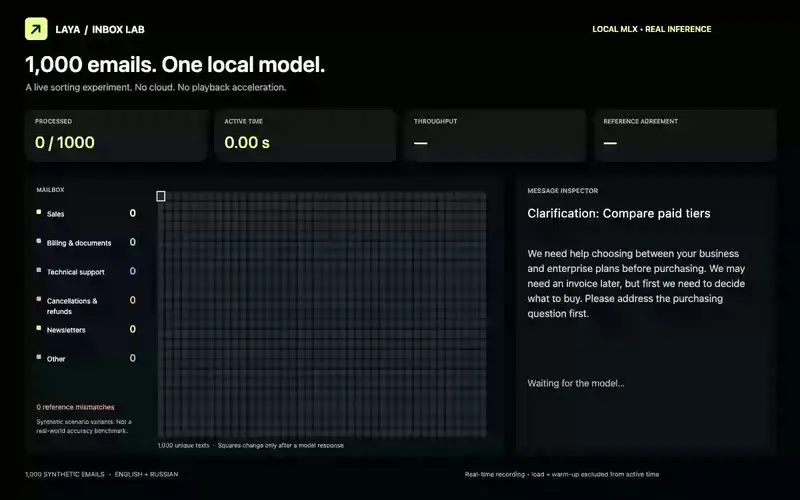
Ran 1,000 synthetic emails through a local 322M Laya multilingual checkpoint on a MacBook Air M3, sorting them into six folders. Reported 65.1 percent accuracy against reference labels, 28.6 seconds without screen recording, and 0 MB of swap.
Built a proof-of-concept Google ADK triage agent on 30 labeled tickets, swapping only the decision engine. Jev took 422ms at 53 percent accuracy, Laya took 152ms at 10 percent accuracy: faster but not more accurate.
Tested Jev against a local MLX build of Laya in zero-shot mode on 40 English and Thai support tickets. Jev scored 90 to 100 percent accuracy, Laya scored 30 to 80 percent, though Laya ran faster.
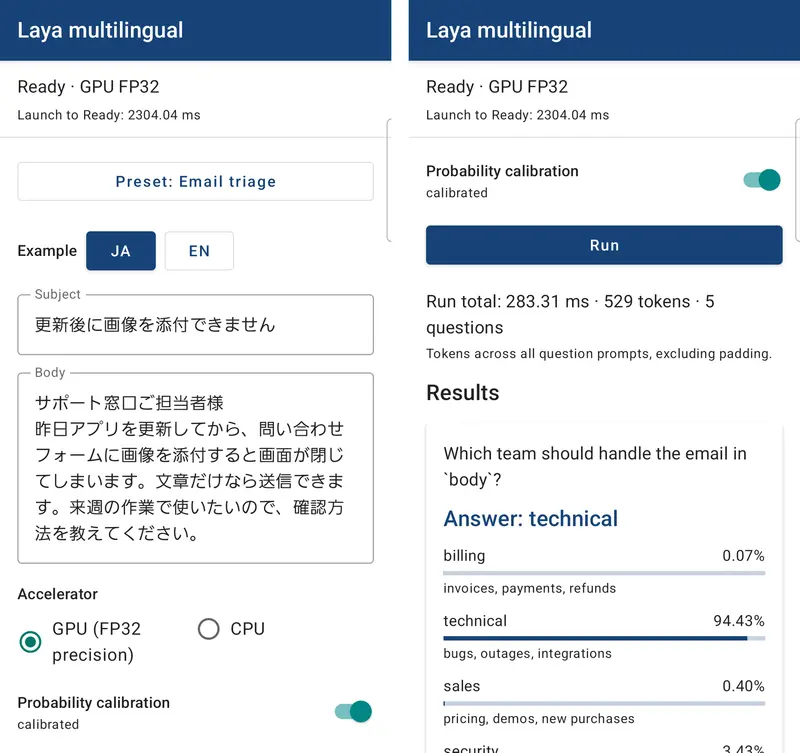
Google's LiteRT conversion of Laya's multilingual checkpoint for on-device Android GPU inference, matching the official CPU implementation on 201 validation rows with a Kotlin sample app answering typed choice, score and noul questions.
A vision variant of Laya, an independent SmolVLM-256M based fork, that answers calibrated choice, score and noul questions about an image plus optional text in one forward pass, with a trained score head.
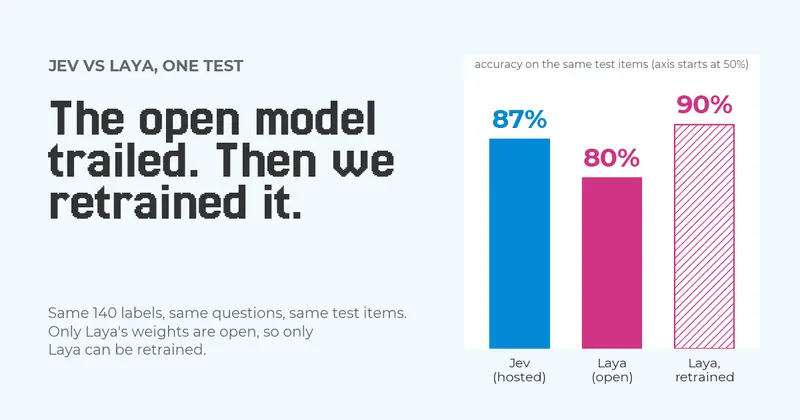
An independent benchmark testing Jev against Laya on the same 140 labels, checking whether each engine's own feedback loop finds a hidden labeling factor, and fine-tuning Laya on the same data to compare results.
Nothing matches those filters
Clear a filter to widen the search, or send us the thing you were looking for.


