Laya Burmese SIB-200
Laya's multilingual checkpoint fine-tuned on 701 Burmese SIB-200 examples for seven-way topic classification, reaching 0.716 test accuracy versus a 0.441 zero-shot baseline, with temperature-scaled calibrated probabilities.
Entries 97 to 106 of 106, in the hub's default order. The introduction is on page 1.
Showing 97 to 106 of 106
Laya's multilingual checkpoint fine-tuned on 701 Burmese SIB-200 examples for seven-way topic classification, reaching 0.716 test accuracy versus a 0.441 zero-shot baseline, with temperature-scaled calibrated probabilities.

A ready-to-run deployment package for all three Laya checkpoints (English, multilingual, typed-decisions) on Axera AX650/AX8850 edge NPUs, with sample requests, outputs and a demo app via the axllm runtime.
Laya fine-tuned for Arabic NLU on laya-multilingual, covering intent classification, natural language inference and offensive-language detection. On MASSIVE ar-SA intent classification it reached 81.6 percent accuracy against 38.6 percent for stock Laya.

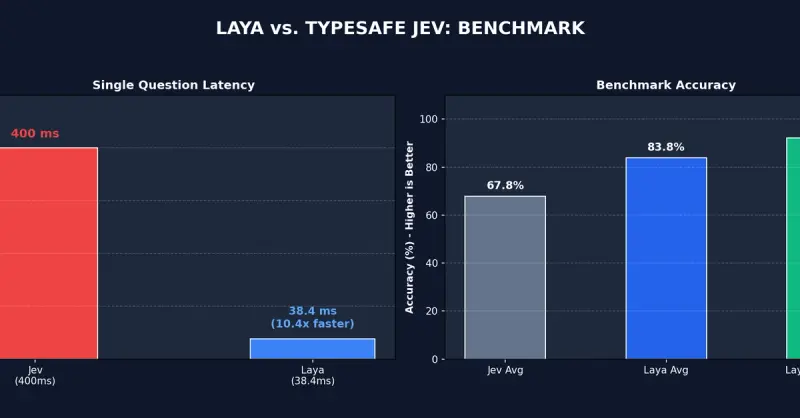
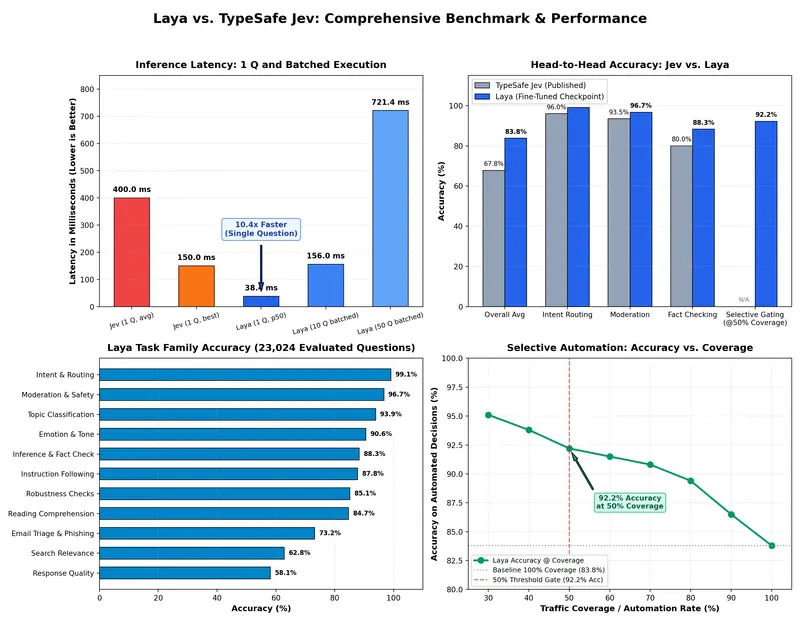
A live site where Laya plays Tetris, Flappy and a three-lane runner in the browser, with a measured Laya-vs-Jev benchmark and a free agent skill for local decision routing.
Laya's English checkpoint compiled to GGUF with ggmlc, scoring choice, score and noul questions in one encoder pass with a CLI that ships an injection-guard preset and a local serve/daemon mode.
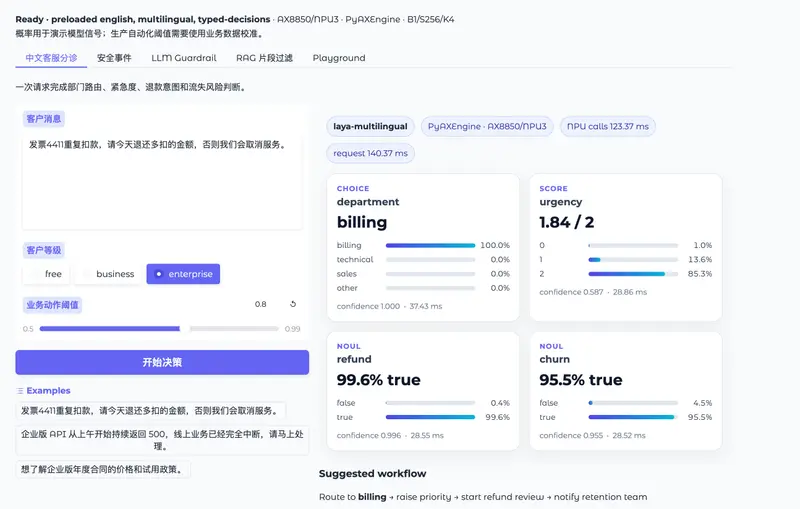
Convai's own Gradio Space running Laya live across eight workflow tabs, including support triage, LLM guardrails, RAG passage filtering and multilingual checkpoint routing, each returning typed choice, score and noul probabilities.

Laya's author argues his March 2025 non-autoregressive decision-model research predates Jev by over a year, and lays out his RLCD training method, calibration approach and sub-40ms latency figures.
Laya fine-tuned on 671 Mind2Web examples to predict the next browser action, an operation and a target element index, from a page's DOM and a goal, reaching 74.3% validation accuracy.

An ONNX export of Convai's Laya decision model, with int8 and fp16 variants and a Python quickstart that builds the marker-token sequence and runs one inference in about 15ms on CPU.

Benchmark Heaven's own leaderboard for Jev-class decision models, unrelated to the dhruvmehra/jevbench repo, ranking 106 of 112 systems on 1,624 choice, score and noul decisions each in release v1.5.4. Jev 1.13.0 leads on capability at 80.0, while on the four-axis composite that adds speed and cost, Cygnet and Winnow-12B Q8 tie first and Jev is third.
Nothing matches those filters
Clear a filter to widen the search, or send us the thing you were looking for.