GhalebDweikat/winnow
A Claude Code hook that splits large tool results into blocks and asks Jev a yes/no relevance question per block, replacing low-relevance blocks with a short recoverable stub before they enter context.

Tool
Entries 97 to 144 of 430, in the hub's default order. The introduction is on page 1.
Showing 97 to 144 of 430
A Claude Code hook that splits large tool results into blocks and asks Jev a yes/no relevance question per block, replacing low-relevance blocks with a short recoverable stub before they enter context.
Chrome extension that finds ad-shaped DOM elements in plain code, then asks Jev whether each candidate is an ad and pops it off the page. Bring your own key and there is no backend, and the author calls it a fun side project rather than a real ad blocker.
Codebase search that finds files matching a natural-language request through repeated Jev-guided passes over a directory tree.
Example server from vLLM PR 57250 that seeds a DiffusionGemma canvas with the answer template and reads one distribution per question slot after a denoise step. It serves a Jev-style question schema over chat completions and is the base djev-run deploys to Cloud Run.
Adds a bounded decision loop to Codex Computer Use: Codex prepares the goal and allowed actions, Jev selects the operation and target in one request, and Computer Use performs the click.
A VS Code extension that finds past Claude Code, Codex and OpenCode conversations from a plain-language description, using a local Laya model to rerank the keyword search results.
Semantic code search for coding agents: it scans an authorized repository, asks Jev to score all eligible fragments against a plain-English question, and returns the original source excerpts with their paths and line numbers.
Jev-inspired parallel decisions for CUDA LLMs: independent typed fields are batched through vLLM over one shared context prefix, single-token labels are scored with the pretrained model's own head, and JSON is assembled in code. No retraining. Includes a browser Super Mario run at 71 ms mean inference per action.
Jev-style parallel constrained decisions for any MLX model on Apple Silicon. It takes a schema of booleans, enums and multi-selects, scores every allowed answer for every field in one forward pass, and assembles the JSON itself, so the output is valid by construction and every field carries a probability.
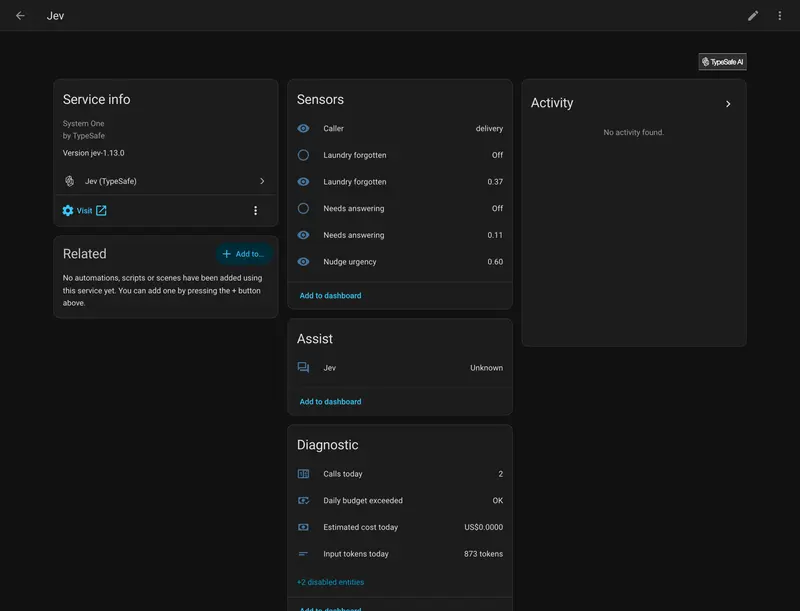
Unofficial Home Assistant integration that asks Jev questions about your house and turns each answer into an entity you can automate on. Questions in configuration.yaml become sensors, and four actions answer inside an automation and return a response variable.
Swift 6 bridge that maps Apple Foundation Models @Generable types onto Jev: Bool to noul, enum to choice, and @Guide range to score.
Zero-shot decision engine built on the MoritzLaurer ModernBERT-large NLI checkpoint, around 400M parameters, pulled from Hugging Face on first use. Exposes Choice, Noul and Score over natural-language criteria rather than structured question objects, and states that its confidence figure measures concentration in the returned distribution, not the chance the answer is correct.
A console whose whole design system is generated at runtime by Jev from a one-sentence brief.
A Python CLI that turns Jev calls into Unix-pipeline predicates, routing, scoring and JSONL filtering with stable exit codes, plus an agent-safety guard recipe for authorization and destructiveness checks.
Local UI and CLI for Instagram, TikTok, and LinkedIn research. At each step Jev picks the next read-only operation from a list built from earlier results, the socai CLI runs it in the user's Chrome, and the captured posts become a cited report.
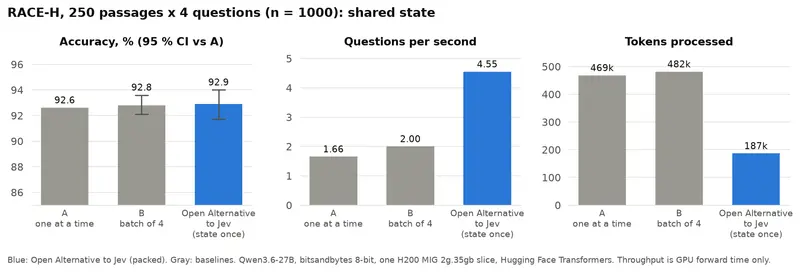
Typed, calibrated decisions from any open-weights model in one forward pass on your own GPU, through Hugging Face or vLLM, with no text generated. On RACE-H with Qwen3.6-27B, writing the passage once reached 92.9% accuracy at 4.55 questions per second against 2.00 for batching.
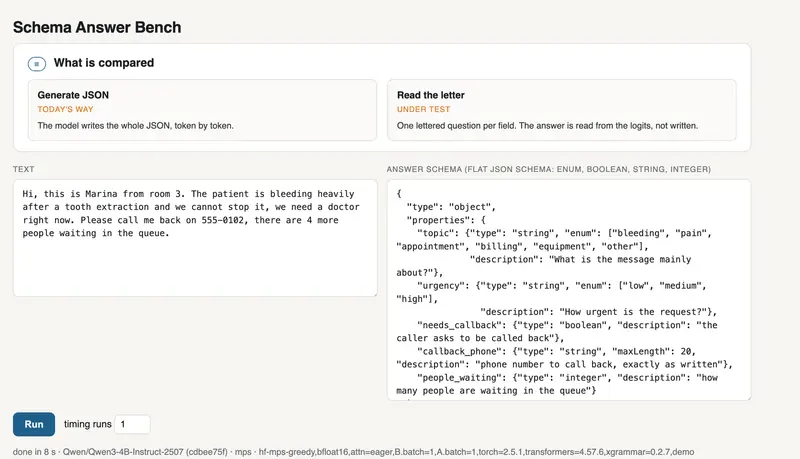
Measures whether an untrained frozen Qwen3-4B can classify against a schema by reading next-token logits for option letters, compared against grammar-constrained JSON generation. Implements analogues of Choice and Noul only; explicitly not a reproduction.
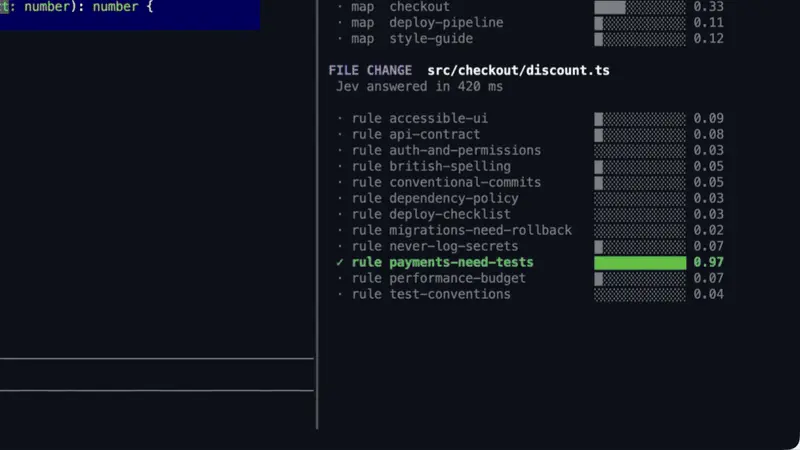
Uses Jev to pick which of your project's rules apply to a given prompt, so Claude only sees the relevant ones.
Rust and Python dataset sifter that streams Parquet and JSONL rows past Jev typed decisions at 1,500+ records per second, writing passed and rejected rows to disk. Uses speculative fan-out and calibrated post-training rubrics.
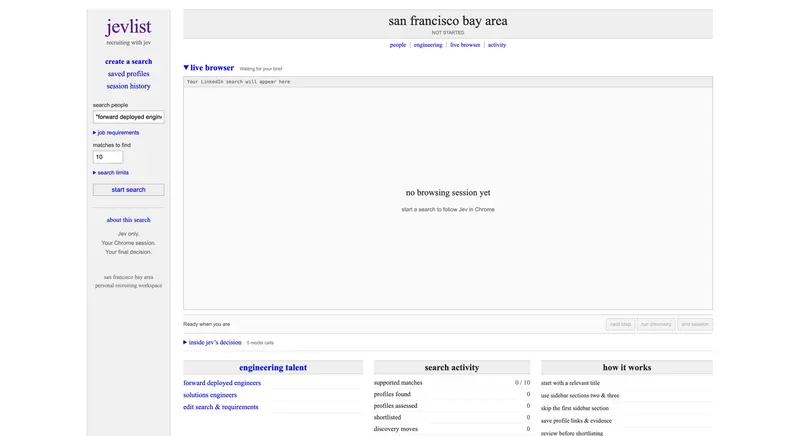
A local recruiting workspace built on Browser Use's Jev Ultrafast: Jev chooses which LinkedIn profiles to browse, screens titles, and assesses profiles against a hiring brief, keeping the evidence.
Adds semantic tool routing, skill discovery and typed Choice, Noul and Score judgments to the Pi coding agent. Opt-in modes pick the model per prompt and use Jev to decide which tool history survives compaction.
Experimental Hono router where you describe a request in plain words and Jev decides which description fits the incoming request. The author warns it is not an authorization boundary, and the values of Authorization, Cookie and API key headers are redacted before anything is sent.
An agent plugin and MCP tool that sends a query plus a batch of file paths, URLs or text straight to Jev and returns relevance probabilities, so the calling agent only opens what is worth a closer look.
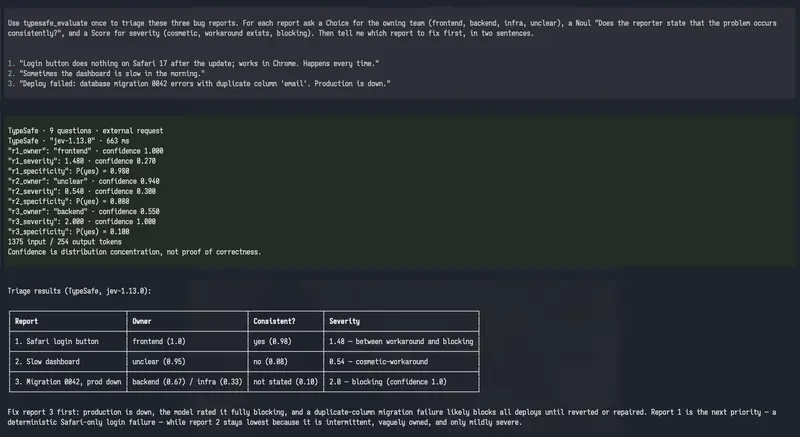
Pi extension that gives the agent and other extensions one key-managed TypeSafe client. A batched typesafe_evaluate tool hands classify, triage, compare and score judgments to Jev in a single call, and a terminal playground runs requests without touching the model's context.
Real-time Discord moderation bot that runs Jev evaluations over message text and metadata in parallel to catch phishing, spam and social engineering, with a progressive escalation ladder.
An agent-first SEO and GEO CLI and MCP server written in Rust, combining DuckDuckGo search with Jev for the judgment calls.
An independent reproduction of Jev's decision layer on Qwen checkpoints, serving the same /v1/systemone request and response schema with choice, score and noul question types, plus an MMLU-Pro benchmark.
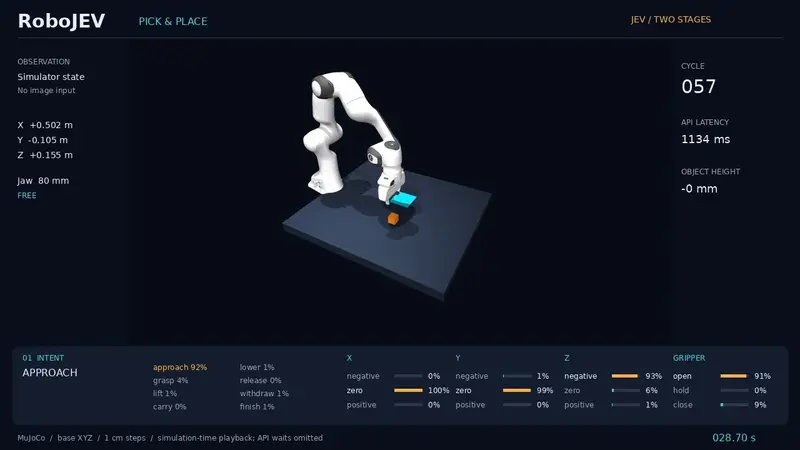
Two-stage Jev control of a Franka Panda arm in MuJoCo: Jev picks an intent from structured simulator state, then picks X/Y/Z motion and a gripper command, with a Cartesian controller executing the action against real physics.
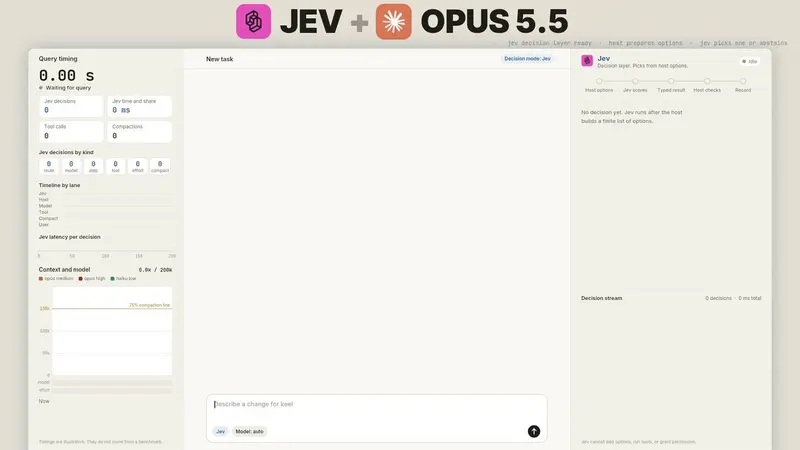
Local-first macOS coding workspace built in Rust with a local Laya selector and optional hosted Jev, routing fresh coding tasks and validating each chosen route on the host.
 Avid (@Av1dlive)Opencodejunkie99/keel on github.com
41 starsCost/time cut ~80%
ACP and MCP adapter that bridges Jev with any LLM, putting computer use and typed decisions alongside Codex, Claude, Grok and OpenCode.
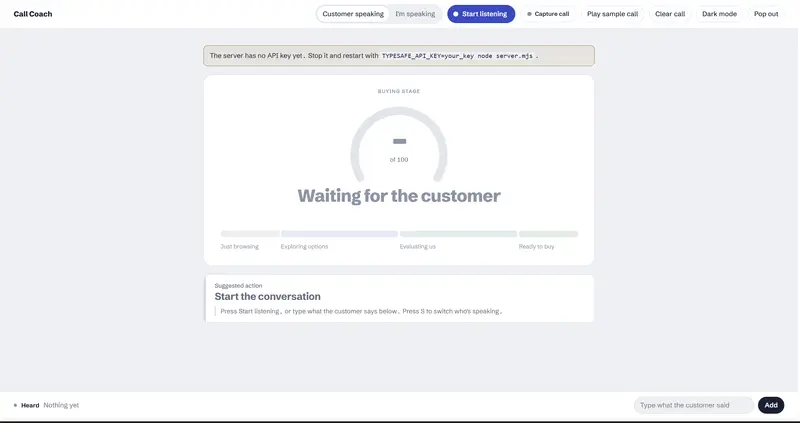
A live sales-call assistant that sends the conversation to Jev after every sentence and shows the rep what to do next along with a confidence score.
A macOS menu bar app that turns one typed or dictated sentence, in English or Japanese, into an Ableton Live action, using Jev to interpret the command.
Hermes skill that lets an agent call jev-latest as a typed tiebreaker, getting Choice, Score and Noul answers with probabilities so it can act or escalate. Documents when to call Jev, confidence gates and pitfalls, and ships a live reliability suite.
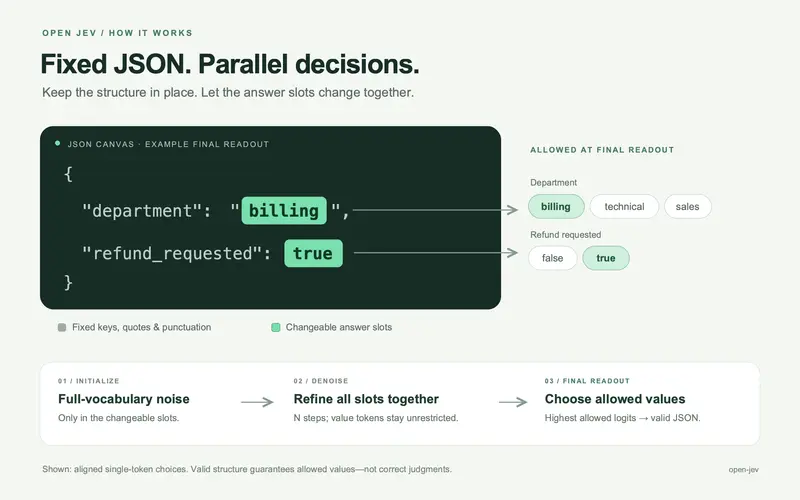
Experimental inference harness for typed JSON decisions with DiffusionGemma: denoise freely, then pick the most likely allowed tokens from the final logits, with no training or fine-tuning. Reports results against Jev benchmarks, measured on an H100.
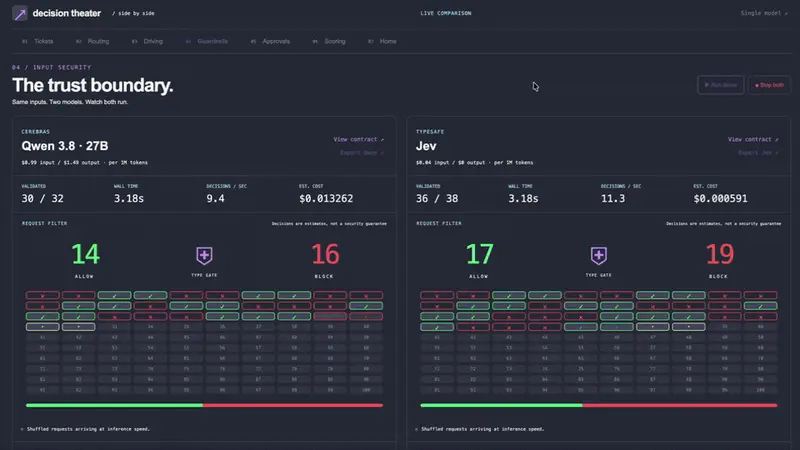
Runs Qwen 3.8 27B on Cerebras and Jev side by side across seven synthetic workloads, plus a local Needle 3 evaluation on the same contracts. Records validated outputs, mistakes, latency, token usage and estimated cost.
A Spring Boot 4 starter for calling Jev using Spring MVC and RestClient.
Rust CLI that classifies Git commit diffs and messages with Jev, labelling bug fixes, security fixes with CWEs, and change types. Scans a local repo or remote URL and exports HTML or CSV reports.
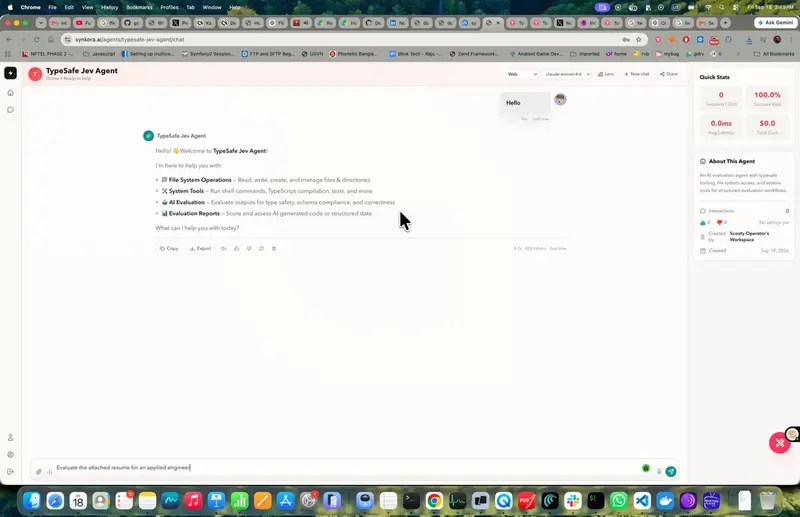
An open source AI agent platform for role-based agents such as PM, engineer, support and marketing, with custom tools and knowledge bases. The author gave Claude Sonnet access to Jev as a tool to score five resumes against one job profile, each evaluation finishing in milliseconds at near-zero API cost.
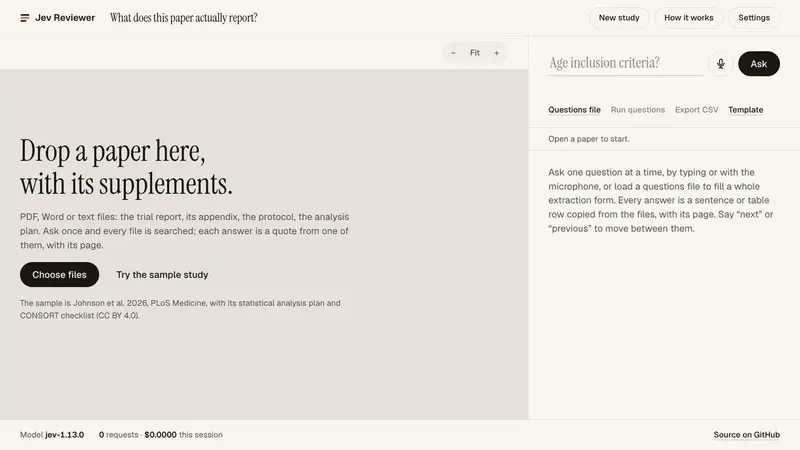
Data extraction for systematic reviewers, built on Jev. It answers extraction forms and risk-of-bias templates like RoB 2, ROBINS-I, QUADAS-2 and TIDieR against a trial report and its supplements, with every answer a verbatim quote and page number to check against the source. Files stay in the browser.
 Ahmad Sofi-Mahmudi (@ASofiMahmudi)OpenJev Reviewer on github.com
33 starsInput price $0.042/M tok
Jev for OTP, published on Hex as jev. The model is a peer process: you reply to it from a GenServer and its answer arrives as a message you pattern match on, so clause order becomes the routing and thresholds become guards.
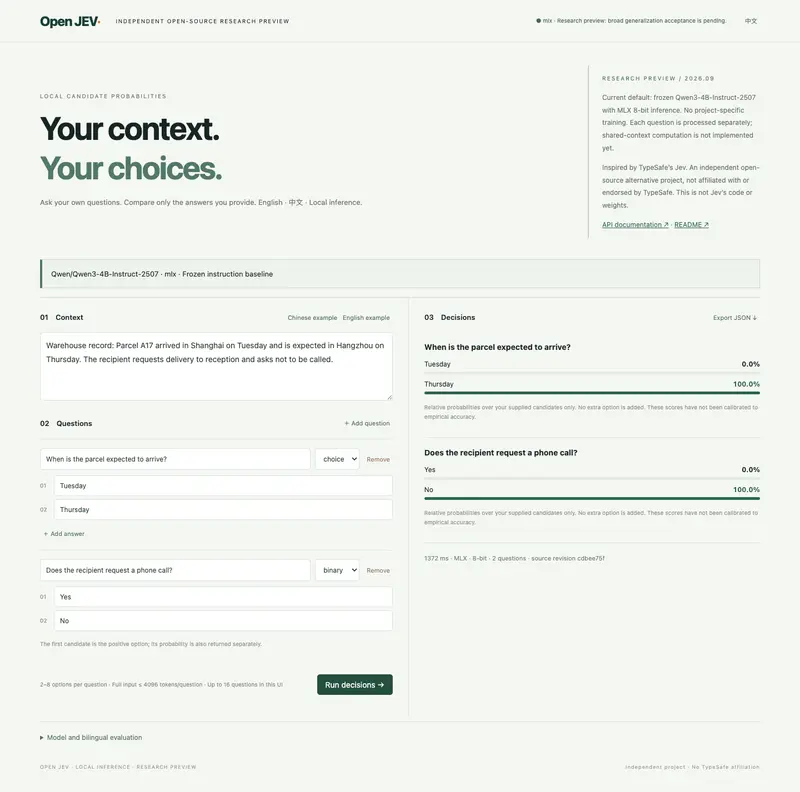
Research preview that takes context, questions and candidate answers and returns probability distributions, running on a frozen Qwen3-4B-Instruct-2507. README states it contains none of Jev's weights or RLCD implementation and claims no performance lead.
Ranks Pi agent skills for the task in front of it, using Jev to pick which skill to load.
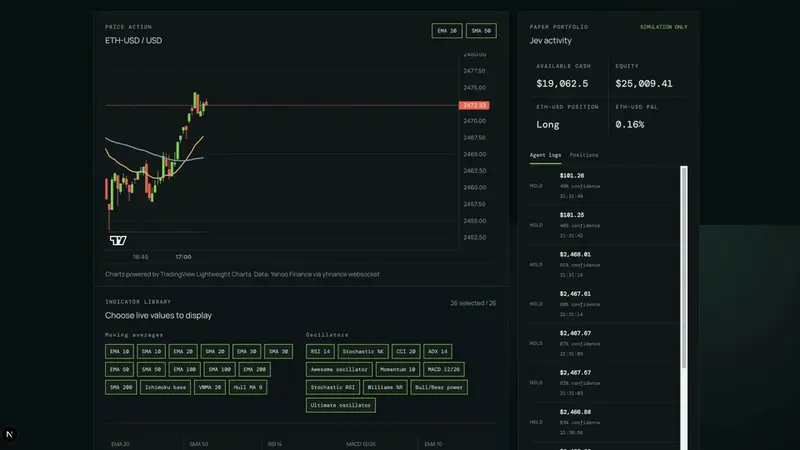
A Next.js dashboard that streams one-minute crypto candles from Yahoo Finance and applies TypeSafe decisions to a simulated paper-trading portfolio, gated by a confidence threshold per risk profile. No live broker or order API is connected.
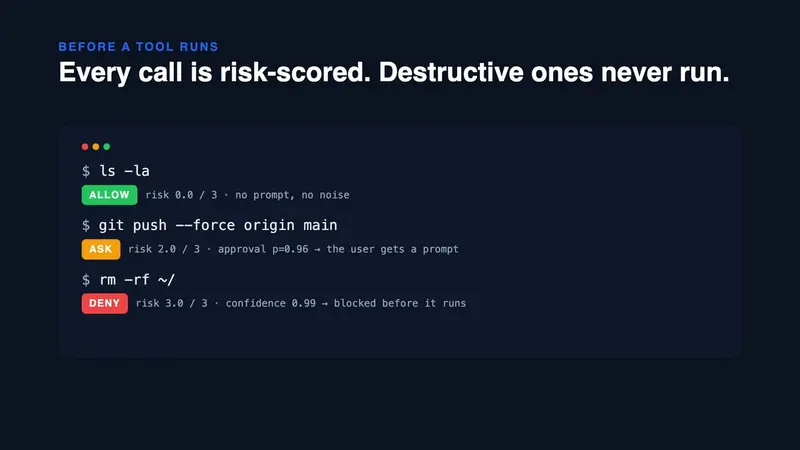
Security hook for coding agents that risk-scores every tool call with session context (deny/ask/allow), flags prompt injection in tool results and checks skills and plugins. Supports Claude Code, Codex, Copilot, Gemini, Cursor, pi, OpenCode and ACP.
A SillyTavern extension that has Jev read each chat message and answer rules you write, so a matched rule can add a prompt line, reroll a reply, or run an STscript.
Laya, running locally, and Jev, over TypeSafe's hosted API, face off in a snake race and a Mortal-Kombat-style fight, both answering the same typed questions on the same input; from a Prompt Engineer 48 video.
A prose linter that flags signs of AI-generated writing, combining zero-dependency countable rules with one judgment model call.
Nothing matches those filters
Clear a filter to widen the search, or send us the thing you were looking for.


