TypeSafe JavaScript SDK docs
Official documentation for the @typesafe-ai/sdk npm package, covering installation (Node 20+), client setup and the question DSL.
Tool
Entries 625 to 638 of 638, in the hub's default order. The introduction is on page 1.
Showing 625 to 638 of 638
Official documentation for the @typesafe-ai/sdk npm package, covering installation (Node 20+), client setup and the question DSL.
Newsletter explainer on how Jev answers typed questions and how software can branch on the confidence value. Lists target workloads including fraud review, lead routing, security alerts, moderation and document classification.
Review describing Jev as a general-purpose semantic classifier, reranker and risk gate exposed as an API. Cites 67.8% accuracy on TypeSafe's four-workflow benchmark against GPT-5.6 Terra's 67.9%, at roughly $0.0004 per case versus $0.03-$0.18.
Compares Jev's single-pass decision approach against autoregressive LLMs and masked diffusion language models, with pricing and latency figures. Positions it as a decision layer rather than a general-purpose model.
Developer guide noting Jev does five things: classify, route, score, extract and branch. Covers pricing of $0.042 per million input tokens with free output.
Release guide walking through benchmarks, pricing and the API surface, aimed at developers evaluating whether to swap an LLM classifier for Jev.
Company manifesto arguing for machine-native intelligence built for software rather than conversation.
Live Val Town demo: type a sentence and watch 16 calibrated judgments move on every keystroke, including passive-aggressive, AI-written, tone and urgency, all from one API call.
Official site publishing TypeSafe's four workflow evals (security incidents, agent-trace observability, invoice processing, customer service) with per-model accuracy, cost and latency, including Jev alongside Claude, GPT and Gemini models.
Hex package listing for the Elixir SDK, version 0.4.0, MIT licensed, last updated 2026-09-18.
Skeptical piece noting the 193x and 444x figures come from TypeSafe's own evaluations and that the eval grades against two other models' answers. Points out the Doom demo gives the model state a human player would not have.
Independent index of publicly demonstrated Jev capabilities, 29 records at the time of writing. Each one links to its evidence, shows how it was verified and says whether it came from TypeSafe or a community publisher.
Hands-on guide using the Python SDK for support routing, with a timing comparison against Claude (0.35s vs 8.83s) and a defect-detection comparison where Jev found six of seven defects to Claude's seven. Warns that high confidence does not guarantee correctness.
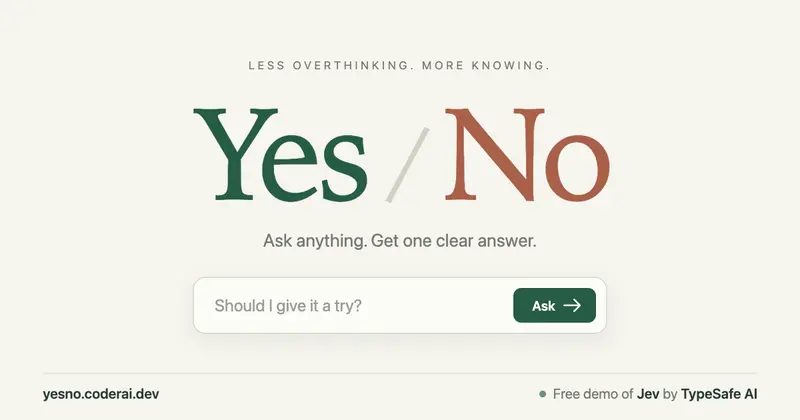
Free demo of Jev with no sign-up: ask any question and get Yes, No or Maybe, grounded in live web search when it matters. Calls jev-latest through TypeSafe's System One API.
Nothing matches those filters
Clear a filter to widen the search, or send us the thing you were looking for.