What Is Jev? How to Implement TypeSafe AI's Decision Model
Hands-on guide using the Python SDK for support routing, with a timing comparison against Claude (0.35s vs 8.83s) and a defect-detection comparison where Jev found six of seven defects to Claude's seven. Warns that high confidence does not guarantee correctness.
More like this
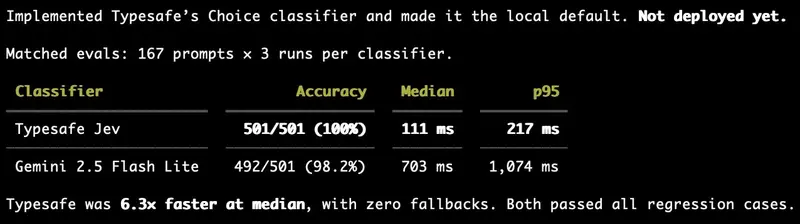
Ran Jev against an existing classifier eval that previously used Gemini 2.5 Flash Lite
Vercel CTO reports Jev saturated an existing classifier eval that had used Gemini 2.5 Flash Lite and ran about 6x faster. Original post; TypeSafe's quote-tweet is a separate item.
 Malte Ubl (@cramforce)OpenRan Jev against an existing classifier eval that previously used Gemini 2.5 Flash Lite on x.com
220k viewsSpeed vs Gemini 6x faster
Introducing Clef: our open-source decision models, and new RL fine-tuning platform
Cloudflare's launch post for Clef and Clef-flash, two decision models on Workers AI that accept the Jev request format and open weights under Apache 2.0. It covers the architecture, Cloudflare's own benchmark tables against Jev, Kev and Laya, and a new reinforcement learning service.
 Michelle Chen (@michellechen)140k viewsOpenIntroducing Clef: our open-source decision models, and new RL fine-tuning platform on blog.cloudflare.comArticleSupport inbox triage
[AINews] Jev: a System One Model that only decides/classifies/routes/scores
AI News daily roundup leading with the Jev launch, summarising RLCD and TypeSafe's 20-200x speed and 40-400x cost claims. Its recap of reactions notes posters using Jev as a structured classifier, judge and routing policy where text generation is unnecessary.
Introducing System One Models and Jev (Hacker News launch thread)
The 1,978-point, 513-comment launch thread. The top comment calls the speed comparison misleading, since Jev only returns structured output, and disputes the cannot-hallucinate claim because a valid type can still hold a wrong value. Others note ordinary LLMs can already be forced into structured output.
DSPy: programming, not prompting, language models
Declares typed input/output Signatures for LLM modules and optimizes the underlying prompts and weights against a metric. Its Signature abstraction is the closest widely-used open equivalent of Jev's typed-question interface. Star count is GitHub's rounded display figure.
Outlines: structured outputs for LLMs
Guarantees valid structured output during generation by constraining decoding to a grammar or schema. The mechanism HN commenters repeatedly cited as already covering Jev's cannot-produce-a-type-error guarantee on ordinary LLMs. Star count is GitHub's rounded display figure.

