tsai-sc (Jev plays StarCraft)
Harness that lets Jev control the original StarCraft shareware through synthetic keyboard and mouse input, recording action probabilities for each decision.

ProjectReal-time control
Entries 49 to 96 of 204, in the hub's default order. The introduction is on page 1.
Showing 49 to 96 of 204
Harness that lets Jev control the original StarCraft shareware through synthetic keyboard and mouse input, recording action probabilities for each decision.
Snake auto-played by Jev: one Choice per game tick, with legal moves and board facts computed in code before the call.
Community playground for Jev with around 110 use cases, games, dilemmas and model challenges. Supports editable prompts, A/B comparisons, conversation routing, document field extraction and code-policy inspection in a Next.js interface. Hosted at jev.works.
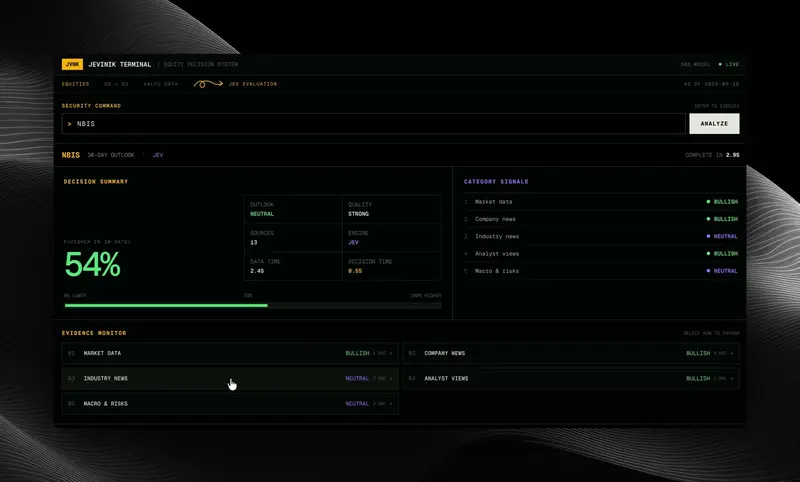
A stock decision terminal, self-titled Jevinik: it pulls live market evidence through Valyu and uses Jev to estimate the probability a stock trades higher in 30 days, without calling a general-purpose LLM.
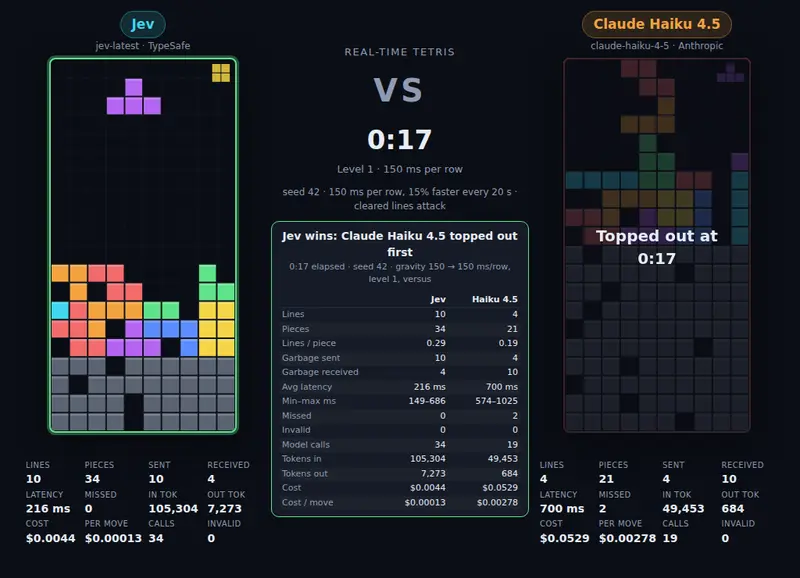
Two AI models play real-time Tetris against each other: Jev faces Claude Haiku, Gemini Flash, or an open-weight typed-decision model, with the same piece sequence and clock for both sides.
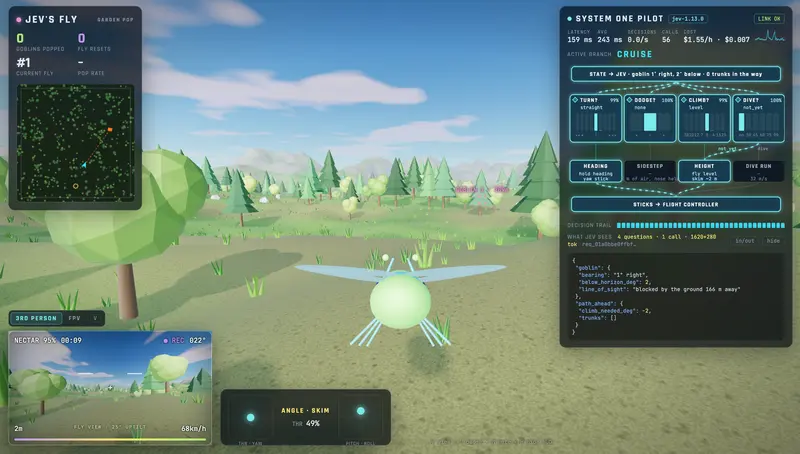
A Three.js first-person flight game where a glowing fly chases goblins in a garden; Jev chooses its heading and dive about five times per second.
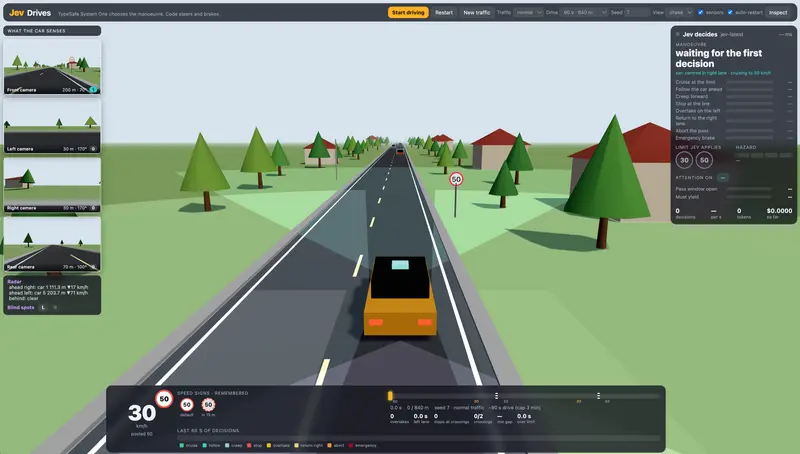
Three runnable experiments: support-message triage producing six independent judgments, a driving simulation where Jev picks lane and target speed against traffic and signs, and an alternative Fable implementation. Shows questions and probability distributions for each call.
Browser-native Doom agent using a Chocolate Doom WebAssembly runtime, structured spatial state, composable AI controls and live decision telemetry.
A minimal grammY Telegram bot that deletes only the messages Jev is confident are spam.
Zero-shot robot tasks on a simulated Franka Panda in ManiSkill. Given a plain English goal and the scene, Jev picks one of about 30 hardcoded primitives per step and Python runs it, at roughly one second per pick. No training, demos or policy.
Uses Jev as a calibrated reranker: one relevance question per document, up to 30 documents per call, returning a probability usable both as a ranking score and an absolute threshold. Apache-2.0; benchmarked on SciFact, NFCorpus and FiQA. The repo now redirects to hev/reranker.
Judges every code file in a pull request against Robert C. Martin's Clean Code with Jev, one calibrated probability per question, then has a writing model turn those findings into two sentences per file and a decision for the change. Runs on Vercel's eve framework as one Next.js project.
Async LangGraph workflow that sends an email to Jev, gets back a typed Choice of invoice or general, and routes it to a demo handler. Ships 10 labeled mock emails, and an API failure stops the run rather than assigning a fabricated intent.
An independent benchmark of Jev against Laya on 40 Chinese support-ticket classifications, plus a confidence-gated cascade that calls Laya first and escalates to Jev, matching Jev's 78% accuracy at 1.8x the speed.
An experimental language for composing Jev questions into methods, with a standalone Rust runtime and an earlier Python reference implementation kept for comparison.
A local browser-agent decider running Laya's open weights, speaking the same /v1/systemone wire format as Jev so existing jev-ultrafast tooling works by changing one base URL. Ships a head-to-head benchmark against hosted Jev.
An experiment that turns Jev's classifier into an autoregressive next-token predictor by having it repeatedly pick the next character from an alphabet of options.
Checks whether each cited paper actually supports the sentence citing it: Claude locates the quote, Jev scores the support, a human makes the final call. Live at verify.papertrellis.com.
Browser stealth game where Jev makes typed guard judgments while deterministic game code owns all world state.
Paste a public GitHub pull request URL and one Jev call returns risk bars and a verdict. The single request covers merge risk, review depth, whether design or security review is needed, missing tests, docs debt and how wide a bug could spread.
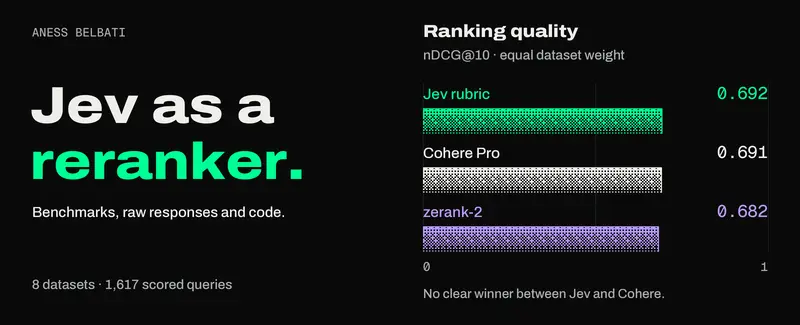
Benchmark comparing Jev against Cohere Rerank 4, ZeroEntropy zerank-2 and a chat-model baseline across 14 datasets, publishing every raw API response and bootstrap ranges on each gap.
Graded relevance eval of a Jev score rerank against BM25, bge-m3 and other rankers over the Agent Skills Hub catalog, with 164 queries, 9,831 labelled pairs and the judge-circularity bias measured. Jev alone does not beat a good embedding ranker, but fusing the two wins even with Jev removed from the judging.
Local CV screening workbench that asks Jev a small fixed set of typed questions about each CV in a folder, scores the answers with arithmetic you can read, and shows a sortable shortlist. Judgments are stored apart from the arithmetic, so editing the role policy re-scores every candidate in about 20 ms at no cost.
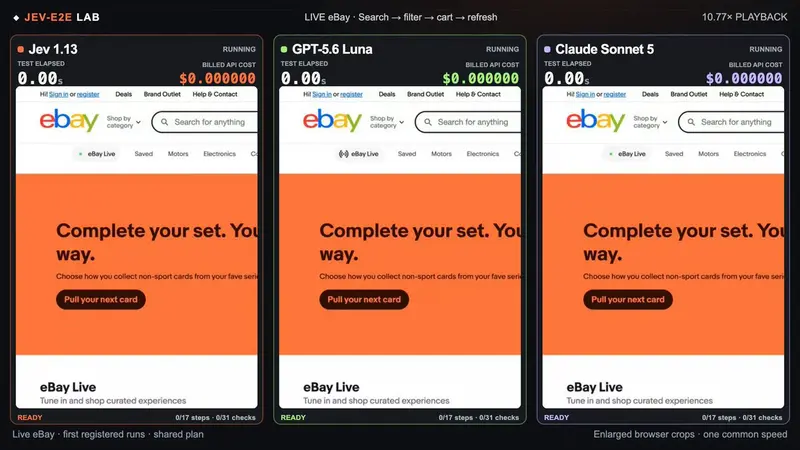
Turns a plain-English description of a web flow into a Playwright end-to-end test that Jev drives, with evidence for each result. The poster's eBay benchmark: 47 seconds and $0.0067 with Jev, versus $0.0277 and $0.4062 for two LLM alternatives.
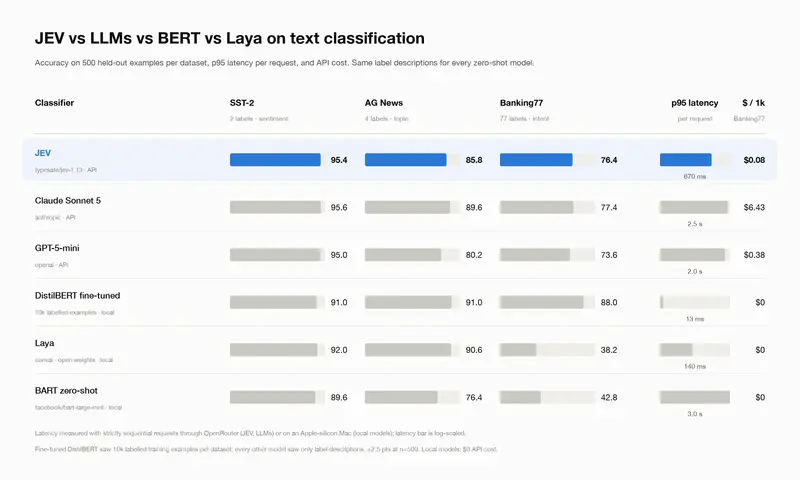
A reproducible benchmark running Jev, Laya and four other classifiers over three public datasets, reporting accuracy, calibration, latency, throughput and cost side by side. Jev answers one choice question per example through the Decisions API.
Unmodified Laya clears Super Mario Bros. 3 World 1-1 on an NVIDIA DGX Spark through Stable Retro NES emulation, with 16.79ms median inference and every frame's decision recorded for replay.
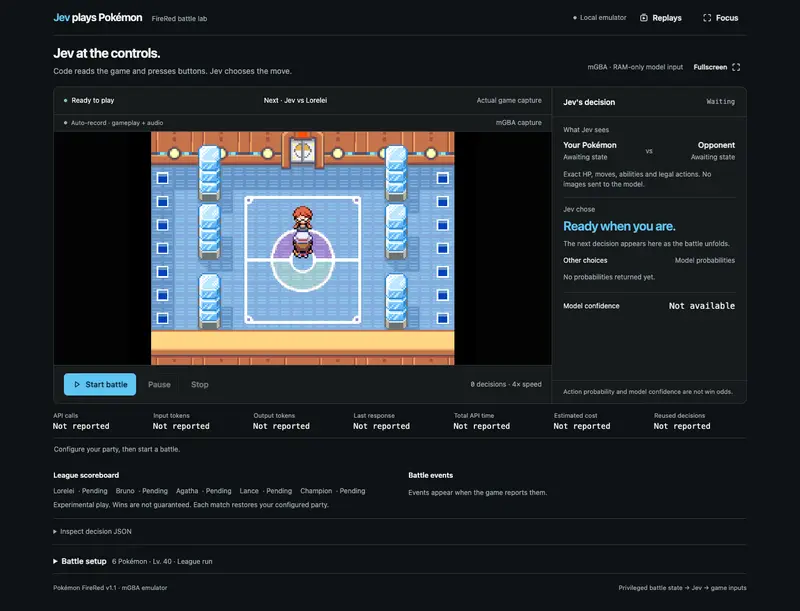
Jev plays Generation 3 Pokemon through Showdown and a real FireRed ROM, with no screenshots involved. Each turn the host reads the battle out of RAM and hands Jev the legal moves and switches; the author points a deliberately underlevelled party at the Elite Four.
Grades the sections of a web page for clarity, writing and on-page SEO with Jev, returning a score per section. Built as a browser extension with WXT.
Autonomous Pokemon Red agent on a PyBoy emulator. Jev reads a compact text snapshot of the game state, answers parallel yes/no questions each turn, and deterministic code turns the answers into button presses. Jev has no vision and no history, so the harness holds the short-term memory.
Recursive tournament engine that ranks texts such as poems, startup pitches and cold emails using Jev for pairwise judgments, Elo rating mechanics and Swiss matchmaking, with real-time WebSocket streaming.
Reproducible comparison of Jev and Claude Haiku 4.5 on 2,000 phishing emails, asking whether an email agent should click the link. Haiku wins on accuracy, 81.3% against 62.6%, while Jev is faster and cheaper, and a logistic regression over Jev's five signal questions reaches 95.1%.
Benchmark that tests whether models can forecast federal motion-to-dismiss rulings from the judge's written record, scored with claim-defendant micro-Brier metrics and clustered intervals. Ships a Jev integration under integrations/jev alongside the frontier-model workflows.
Toy archipelago where Jev makes every in-flight call: divert or continue, declare an emergency, give way, hold, and who lands first when two aircraft want the same runway. Each aircraft knows only itself and nearby traffic, asks four batched questions about every 1.6 s, and gets answers in roughly 150 ms.
Runs Laya and Jev on 751 byte-identical questions across nine suites; Jev sweeps triage, guardrails and moderation, Laya wins agnews and mnli, and both miscalibrate on emotion.
CLI that lints UI code, copy, and agent instructions for AI slop on every commit. Local rules handle the measurable checks; the judgement calls go to Jev as yes/no questions that come back as probabilities, and a set of rules can fail the run.
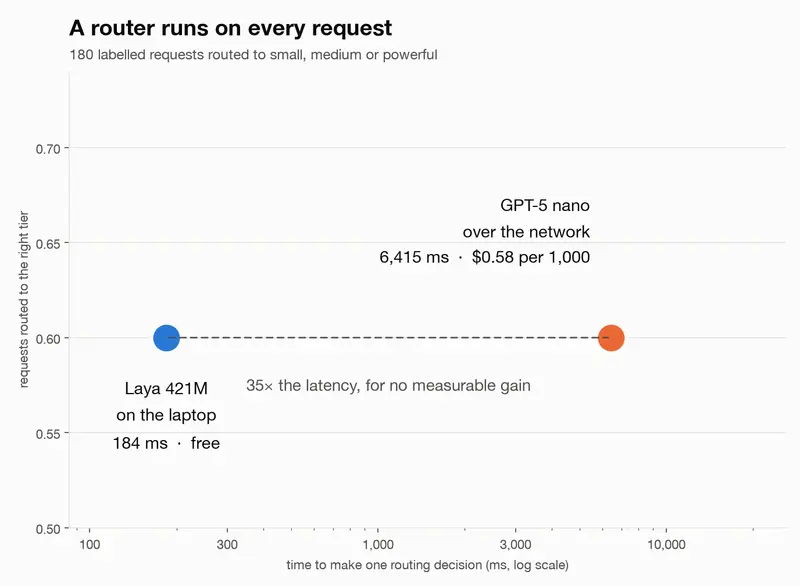
A FastAPI request router that uses Laya as a System 1 decision layer to pick between small, medium and powerful downstream models, matching GPT-5 nano's routing accuracy at far lower latency in the author's evaluation.
Proof of concept that turns a high-level Android goal into a bounded observe, stabilize, decide, act loop. Jev receives a compact semantic UI state and a short list of already-valid actions, and never generates coordinates, MCP calls or code. Exercised against Android Settings on a real device.
Hands Jev a piano and asks it typed questions about mood, having it decide notes continuously since it cannot generate music directly. Started as an X bet with @BaselAshraf81 over whether Jev could be made to play at all.
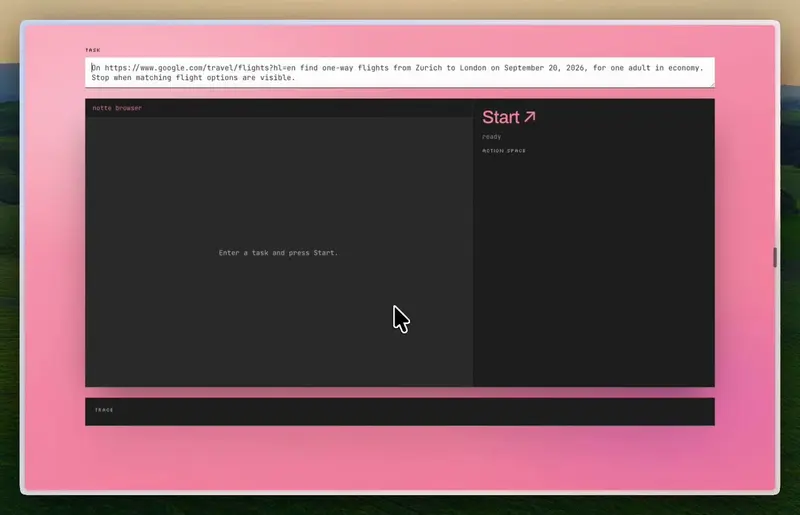
Jev picks every action for a Notte cloud browser session over CDP, choosing from a fresh action space at each step with a replay of every decision.
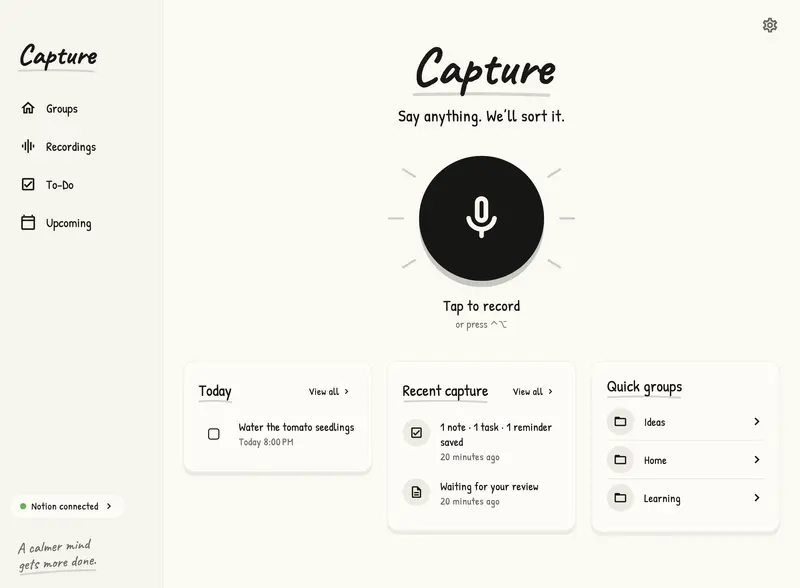
A private Mac voice diary that transcribes locally, uses Jev to sort each entry, and saves them to a Notion library.
Measures how Laya's decision head stops attending to input past roughly 200 tokens, then fixes it by chunking documents into passages and screening each one. Tested on 400 documents, and against Jev on a public needle benchmark.
A browser pong game whose left paddle is decided by one Laya choice question per frame, 18.7ms p50 on Metal, while the right paddle plays fixed arithmetic for comparison.
A local desktop and CLI coding agent where Jev selects the next tool from the user's request and recorded execution results, while DeepSeek or a local model supplies the arguments.
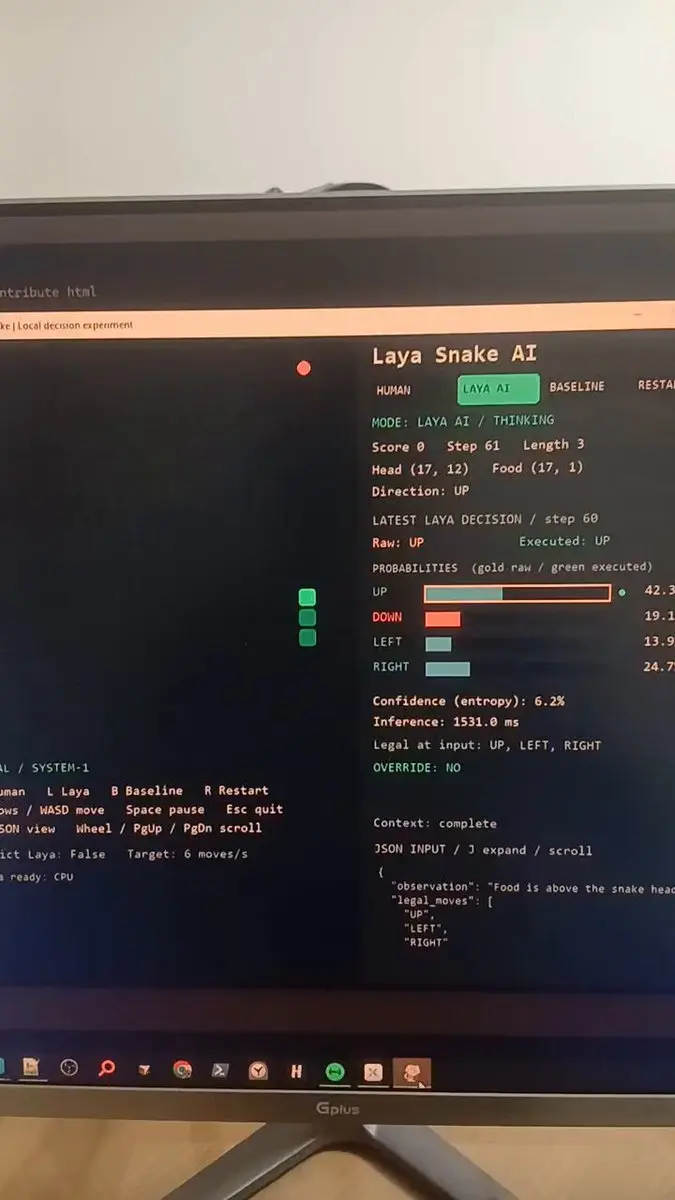
A desktop Pygame Snake game with HUMAN, Laya AI and greedy-baseline modes, showing a live decision dashboard with real SDK probability bars, entropy confidence and per-move inference time.
A live market news desk that takes yfinance headlines and returns ranked trade ideas, running 215 typed judgments through Jev per pass in 2.7 seconds for about a quarter of a cent. Built with Claude Code and TypeSafe's agent skill.
Two ComfyUI nodes that free VRAM between models on a single GPU: one unloads cached image models, and a Laya-based router classifies the enhanced prompt's style before an image model loads. Measured on a 12 GB RTX 3080 Ti.
A voice-driven control layer for macOS with a Rust core and Tauri shell, where Jev is a fallback rather than the main router.
A fully local Home Assistant Assist conversation agent that scores registered intents and exposed entities with Laya in one forward pass, dispatching simple commands directly and escalating compound or low-confidence requests to a fallback LLM.
Nothing matches those filters
Clear a filter to widen the search, or send us the thing you were looking for.


