What d1 is
d1 is Liquid AI’s first decision model, announced on X on 29 September 2026. Its current hosted version is d1.1, which Liquid’s docs call the default hosted decision model. It follows the same request shape as Jev, so it is a System One model: you send a state, which is plain text or a JSON object, plus one or more typed questions. d1.1 on Liquid’s API also takes an optional images array, as the paid d1 did. It returns one answer per question and generates no text. Liquid has not published the base model or the parameter count of the hosted d1 or d1.1.
On 7 October 2026 Liquid released two open-weight models it calls part of the d1 family, d1-3B and d1-omni-600M. On 24 October it added d1-2B and d1-Omni-2B, and its docs now mark d1-3B deprecated and point to d1-2B. Liquid trains and sells d1, so this page lists them as versions of it. Liquid does not say whether the hosted d1 or d1.1 is built on any of them.
What it returns
The three question types match Jev. A Noul returns one probability that the answer is yes. A Choice returns the chosen option, a probability for every option and a confidence value. A Score returns a value on a rubric you define, counted from 0, plus the probability of each level. The usage.output_tokens field in every response is 0.
Liquid’s docs call d1 through POST https://api.liquid.ai/decisions/v1/systemone and use TypeSafe’s Python and TypeScript SDKs with base_url set to https://api.liquid.ai.
What it is good at
Liquid lists classification, routing, scoring, moderation, guardrails, reranking, LLM-as-judge checks and model routing. Those map to support inbox triage, intent and model routing, LLM guardrails and semantic reranking. Its docs pair the probabilities with thresholds, such as blocking above 0.8 and sending the middle band to a person, which is confidence-gated actions.
The launch post says d1 wins on multilingual evals, resists prompt injection better and handles longer inputs more effectively than Jev. It gives no numbers for any of the three.
The one chart it does publish is Liquid’s own reproduction of the Jev Decision Index 0.2.1, multimodalart’s community board on Hugging Face. There d1 scores 58.9 overall against 57.9 for Jev 1.13. It leads on Arts (45.5 against 37.7), Language (67.6 against 62.0) and Retrieval (60.7 against 55.4). It trails on Tools (74.1 against 75.1) and Knowledge (43.3 against 51.3). The hosted d1 is not on the public Jev Decision Index. The 0.4.1 file, generated on 12 November 2026, lists only the open models, d1-2B, d1-Omni-2B, d1-3B and d1-omni-600M, so nobody outside Liquid has reproduced the hosted model’s figures on that board.
The hosted d1 is on the Artificial Analysis Decision Index, which runs its own tests rather than Liquid’s. On version 2.1, checked on 14 November 2026, AA has added a d1.1 row and marks it the default. d1.1 scores 66.5, 9th of 22 decision models, against 66.2 for Jev 1.14 and 70.6 for d1-ultra. The older d1 row stays at 60.8, 18th of the 22; it was 15th of 19 on 12 November. On version 1.0 d1 scored 50.3, 12th of 17 as of 23 October 2026. d1.1 trades knowledge for tool calling and calibration. Its When2Call tool-calling accuracy is 92.8%, against 77.9% for d1, and its calibration error, which this site computed from AA’s bins, is 0.059, against 0.120. Its accuracy on AA’s private knowledge questions falls to 24.2%, from d1’s 39.8%, and its Humanity’s Last Exam accuracy to 4.3%, the lowest of the 22. It answers “I don’t know” far more often when it is wrong: a non-hallucination rate of 73.4 on the knowledge questions, against 3.3 for d1. Both cost $63 per million tasks, the third and fourth lowest of the 22. d1.1 took 253 ms per task and d1 151 ms. For the older row AA names Liquid AI as the host but not the model id, so it is not clear whether it called d1 or d1:free.
d1-ultra
On 15 October 2026 Liquid added a larger hosted sibling, d1-ultra, at $0.042 per million input tokens. It has its own page because its price, context and benchmark results differ from d1’s.
The open d1 models
Liquid’s decision models page lists three open models today, checked on 14 November 2026. d1-2B (1.92B parameters, on LFM3-VL-2B) reads text, images and video. d1-Omni-2B (2.17B, on LFM3-Omni-2B) reads text, images, video and audio. Both have a 128K-token context and add typed answers beyond Choice, Score and Noul. The third is d1-omni-600M, described below. d1-3B, the first open release, is now marked deprecated, and Liquid says d1-2B is more accurate with a third fewer parameters.
d1-3B is a 3.12B decision model that Liquid post-trained from LFM2.5-VL-3B, its vision-language model. It reads text, JSON and images and has a 32,768-token context. d1-omni-600M is a 587M model on LFM2.5-Encoder-350M, a bidirectional encoder, with added vision and audio encoders. It reads text with images, or text with up to 30 seconds of speech. Liquid calls it an early research release. Both load in Transformers with trust_remote_code=True and answer named Noul, Choice and Score questions through a system_one method, with zero output tokens. Both also ship GGUF builds.
The weights are on Hugging Face under the LFM Open License v1.0, not Apache 2.0. The licence grants commercial use only to a company with annual revenue under $10 million. Liquid’s blog says the models can be deployed “without restrictions”, which the licence file does not bear out for larger companies. Liquid’s docs listed both for self-hosting only, and OpenRouter does not list either. On 9 October 2026, d1-3B had 5,370 Hugging Face downloads and d1-omni-600M 8,487. Liquid publishes no GitHub repository for either.
The model cards report vendor-run results. Liquid scored d1-3B at 48.57 on Jev Decision Index 0.2.1 with the Index’s own scorer, outside the leaderboard, and d1-omni-600M at 15.95. Liquid’s card calls d1-3B the best decision model under 10B on that edition. Its speed table gives 8 ms for one question on an NVIDIA RTX 4090 and 30 ms on an Apple M5 Pro.
Jev Decision Index 0.3 was the first board to list them. The figures here are from edition 0.4.1, in the file generated on 12 November 2026. Its headline Full score counts only private tests, 60% on the same skills and 40% in new domains, so it does not compare with the 0.2.1 figures. The newer d1-2B scores 34.39, 196th of 301 rows, and its calibration error of 0.012 is the lowest on the board. d1-Omni-2B scores 33.58. The older d1-3B scores 31.12 and d1-omni-600M 11.75, against Jev 1.14’s 60.24. On the public benchmarks alone they score 48.99 and 17.90. Their calibration errors are 0.047 and 0.128, against Jev 1.14’s 0.080. Liquid submitted the public-suite runs itself, on an AMD MI325X, and the Index ran the private tests. The public part no longer counts toward the Full score, so the Full score is fully independent. d1-3B’s weakest part is the private tasks from new domains, at 11.47. In the 0.3.1 file of 10 October 2026 the two scored 40.08 and 9.45.
What it is not for
Liquid says to use a language model for free-form text, creative writing, multi-turn conversation, multi-step reasoning, open-ended questions, summaries and code. d1 cannot explain an answer. The gap in Knowledge suggests testing it before you route fact-heavy questions to it. Liquid gives no limits on options, levels, questions per call or request rate, so test your largest case.
Access
Sign in at console.liquid.ai, create an API key that starts with liquid_, and call the model d1.1 for text and images. At launch the ids were d1:free for text and d1 for text and images; Liquid’s docs no longer list either on its own API as of 12 November 2026. Liquid does not label d1.1 beta or preview. Liquid’s pricing page lists d1.1 at $0.02 per million input tokens, checked on 12 November 2026.
OpenRouter added liquid/d1 on 1 October 2026, after the launch post said it would arrive soon. It launched at $0.04 per million input tokens, text only. On 16 October 2026 it listed $0.02 with free output, text and image input, and a 65,536-token context. It was fifth on OpenRouter’s decision leaderboard for the week to 8 October, with 3.96 million requests. Vercel’s AI Gateway also lists it as liquid/d1. OpenRouter added liquid/d1.1 on 27 October 2026 at $0.02 per million input tokens with a 65,536-token context. There are no downloadable weights for the hosted d1 or d1.1. The open d1-2B, d1-Omni-2B, d1-3B and d1-omni-600M download from Hugging Face and run on your own hardware.
Specifications
| System One Score | 75.3 from 3 of 3 boardsArtificial Analysis Decision Index 91.6, Jev Decision Index 46.9, JevBench 87.3. How the score works |
| Inputs | Text, imagesThe hosted d1.1 reads up to 8 JPEG, PNG, WebP or GIF images per request. Of the open weights, d1-2B also reads video, and d1-Omni-2B reads video and audio. |
| Question types | ChoiceScoreNoul |
| Max Choice options | Not documented |
| Score levels | Not documented |
| Questions per call | Not documented |
| Total context | 65,536 tokens |
| State budget | Not documented |
| Rate limit | Liquid documents no rate limits for d1. |
| Endpoint | POST https://api.liquid.ai/decisions/v1/systemone |
| Licence | LFM Open License v1.0 (open d1-2B, d1-Omni-2B, d1-3B and d1-omni-600M; the hosted d1.1 has no published licence) |
| SDKs | Python: typesafe-sdkTypeScript: @typesafe-ai/sdk |
Liquid publishes no context length for its hosted models. OpenRouter lists 65,536 tokens with a 58,982-token maximum completion for liquid/d1.1, checked on 2026-11-12. It lists the same for liquid/d1, and Vercel's AI Gateway now lists 65,536 too, both checked on 2026-10-16; Vercel listed 32,000 on 2026-09-30. Treat both as the gateways' figures. On Liquid's API d1.1 takes up to 8 images per request, as the paid d1 did, within a 4.5 MB body and 10,000 patches of 32 by 32 pixels; d1:free is text only. Liquid's docs do not give a maximum number of Choice options, Score levels or questions per call. Their examples use up to 5 options, 4 levels and 3 questions. The open models have their own limits: d1-3B has a 32,768-token context, and d1-omni-600M has 16,384 tokens shared by text, image and audio positions, with state and question text cut to 896 tokens when images are present. Both model cards allow 2 to 10 Score levels. Liquid's docs give d1-2B and d1-omni-2B a 128K-token context, and say d1-2B answers get less reliable past about 64K tokens of state.
Versions
- d1.1, 27 Oct 2026, The current hosted version. Liquid's docs call it the default hosted decision model and list it beside d1-ultra as the only hosted ids, reading text and images, checked on 2026-11-12. Liquid gives no release date; the date is when OpenRouter created liquid/d1.1, which it calls the successor to d1, along with a ~liquid/d1-latest alias at the same price and context. $0.02 per million input tokens, cached input $0.02, output free, 65,536-token context on OpenRouter. Same endpoint and request format as d1. Release notes
- d1:free, 29 Sep 2026, The launch model id, text only. It was the only id in Liquid's docs on 2026-09-30. Liquid's docs no longer list it as of 2026-11-12. Liquid's model library lists d1 as API only, with no GGUF, MLX or ONNX files, and not trainable. Vercel's AI Gateway lists it as liquid/d1. Release notes
- d1, The paid model id in Liquid's docs, checked on 2026-10-09. Liquid says vision is available only on d1, while d1:free is text only. Liquid gives no release date for it. Liquid's pricing page listed it at $0.02 per million input tokens, checked on 2026-10-16. On 2026-11-12 Liquid's docs call it the earlier d1 model, list d1.1 in its place on Liquid's API, and link to d1 on OpenRouter and Vercel's AI Gateway. Release notes
- liquid/d1 on OpenRouter, 1 Oct 2026, OpenRouter's paid listing, snapshot liquid/d1-20260930, named LiquidAI: d1, served by Liquid. It launched text only at $0.04 per million input tokens. On 2026-10-16 it listed text and image input at $0.02. Release notes
- LiquidAI/d1-3B, 7 Oct 2026, Open weights on Hugging Face under the LFM Open License v1.0, with a GGUF build at LiquidAI/d1-3B-GGUF. 3.12B parameters, post-trained from LFM2.5-VL-3B with a SigLIP2 NaFlex 400M vision encoder. Reads text, JSON and images, with a 32,768-token context. Liquid's docs list it for self-hosting only, not on its API. 5,370 Hugging Face downloads and 205 likes, checked on 2026-10-09. Jev Decision Index 0.3: Full score 40.08, Public only 48.99, calibration error 0.047, with the public part run by Liquid. Liquid's docs say d1-2B replaces it and no longer list it among the d1 models, checked on 2026-11-12. Its own docs page now marks it deprecated, and the docs' model library table no longer lists it, checked on 2026-11-14. Its weights are still on Hugging Face, with 27,868 downloads and 503 likes on that date. Release notes
- LiquidAI/d1-2B, 24 Oct 2026, Open weights on Hugging Face under the LFM Open License v1.0, with GGUF, MLX and ONNX builds. 1.92B parameters, built on LFM3-VL-2B. Reads text, pictures and video with a 128K-token context. Liquid's docs mark it recommended and say it replaces d1-3B with a third fewer parameters. Beyond Choice, Score and Noul it adds typed answers: multiple choice, text, number and date spans, estimates with an interval, and bounding boxes. 11,252 Hugging Face downloads and 270 likes, checked on 2026-11-12. Release notes
- LiquidAI/d1-Omni-2B, 24 Oct 2026, Open weights on Hugging Face under the LFM Open License v1.0, with GGUF, MLX and ONNX builds. 2.17B parameters, built on LFM3-Omni-2B. Reads text, pictures, video and audio with a 128K-token context (video per the inputs table on Liquid's decision models page, checked on 2026-11-14), and takes the same typed answers as d1-2B. 4,094 Hugging Face downloads and 106 likes, checked on 2026-11-12. Release notes
- LiquidAI/d1-omni-600M, 7 Oct 2026, Open weights on Hugging Face under the LFM Open License v1.0, with a GGUF build at LiquidAI/d1-omni-600M-GGUF. 587M parameters: a 381M shared trunk and decision head, a 94M vision encoder and a 112M audio encoder, built on the bidirectional LFM2.5-Encoder-350M. Reads text with images, or text with up to 30 seconds of speech, not both at once. 16,384-token context. Liquid calls it an early research release. 8,487 Hugging Face downloads and 82 likes, checked on 2026-10-09. Jev Decision Index 0.3: Full score 9.45, Public only 17.90, calibration error 0.128, with the public part run by Liquid. Release notes
Use cases
What people use d1 for, one page per pattern.
Support inbox triage with System One models
Send a support ticket to Jev once with every question attached. Category comes back as a selected label, severity and frustration as numbers on scales you wrote, refund intent as a probability. Your code reads those values and decides what happens to the ticket.
Intent and model routing with System One models
One Jev call reads an incoming request and returns its intent as a label plus a difficulty rating on a scale you wrote. Your router reads both numbers and picks the handler: deterministic code, a cheap model, an expensive one, or a human queue.
Confidence-gated actions with System One models
Jev returns a confidence value from 0 to 1 alongside every Choice and Score answer. Your code treats it as a separate axis: act automatically when it's high, confirm or flag when it's middling, hand the decision to a person when it's low. Riskier actions get higher bars.
LLM guardrails with System One models
Put one Jev request in front of an LLM and one behind it. Yes/no questions return the probability that each hazard holds, a Score rates how much harm complying would do, and your thresholds turn those numbers into pass, review, block, or a crisis path.
Semantic reranking with System One models
Keyword or vector search narrows thousands of documents to a shortlist but rarely puts the right one first. Ask Jev one yes/no question about each query and candidate pair, take the probability it returns as the score, and sort the shortlist by it, highest first.
Examples built with d1
The most-starred and most-viewed entries in the directory. All d1 examples.
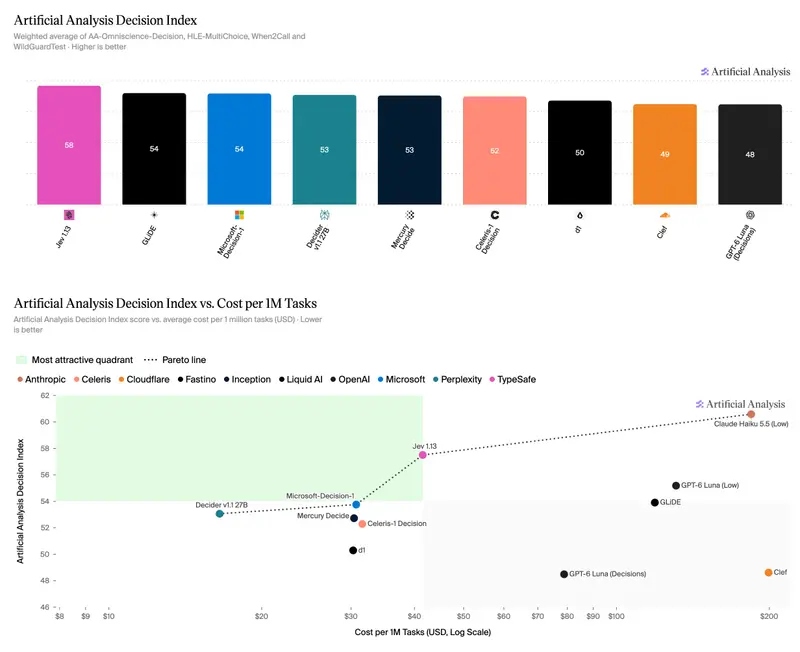
Artificial Analysis Decision Index: 11 hosted decision models against language models
Artificial Analysis scores 11 hosted decision models on knowledge, reasoning, tool-calling and safety tests, with cost and time per task, and runs language models on the same tests. Jev 1.13 led the decision models at launch at 58, and on version 2.1, checked 12 November, Nace.AI's Drex Max v1.1 leads at 72.6; at launch Claude Haiku 5.5 (Low) scores 61 but takes 1.4 seconds per task against 0.13.
 Artificial Analysis (@ArtificialAnlys)45k viewsOpenArtificial Analysis Decision Index: 11 hosted decision models against language models on artificialanalysis.ai
Benchmarks
Published scores, each linked to its source. A row marked vendor-run was measured by the vendor itself, so read it as one side's result. The compare hub sets these beside the other models.
| Benchmark | Metric | Score | Run by | Date |
|---|---|---|---|---|
| JevBench 1.8.10 | Capability Score | 74.4 score | Independent | 15 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Index score | 66.5 score | Independent | 14 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Expected calibration error | 0.0585 ECE | Independent | 14 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Cost per 1M tasks | 63 USD | Independent | 14 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Time per task | 253 ms | Independent | 14 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Index score | 60.8 score | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Expected calibration error | 0.1205 ECE | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Cost per 1M tasks | 63 USD | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 2.1 | Time per task | 151 ms | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Full score | 34.39 score | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Public score | 51.1 score | vendor-run | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Expected calibration error | 0.0116 ECE | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Full score | 33.58 score | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Public score | 49.02 score | vendor-run | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Expected calibration error | 0.0593 ECE | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Full score | 31.12 score | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Public score | 48.99 score | vendor-run | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Expected calibration error | 0.0468 ECE | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Full score | 11.75 score | Independent | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Public score | 17.9 score | vendor-run | 12 Nov 2026 |
| Jev Decision Index 0.4.1 | Expected calibration error | 0.1284 ECE | Independent | 12 Nov 2026 |
| Artificial Analysis Decision Index 1.0 | Cost per 1M tasks | 15 USD | Independent | 23 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Index score | 50.3 score | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Expected calibration error | 0.1442 ECE | Independent | 13 Oct 2026 |
| Artificial Analysis Decision Index 1.0 | Time per task | 299 ms | Independent | 13 Oct 2026 |
| JevBench 1.8.10 | Capability Score | 49.5 score | Independent | 12 Oct 2026 |
| JevBench 1.8.10 | Capability Score | 32.8 score | Independent | 12 Oct 2026 |
| Jev Decision Index 0.3.1 | Full score | 40.08 score | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Public score | 48.99 score | vendor-run | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Expected calibration error | 0.0468 ECE | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Full score | 9.45 score | Independent | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Public score | 17.9 score | vendor-run | 10 Oct 2026 |
| Jev Decision Index 0.3.1 | Expected calibration error | 0.1284 ECE | Independent | 10 Oct 2026 |
| Jev Decision Index 0.2.1 | Overall | 48.57 score | vendor-run | 7 Oct 2026 |
| Jev Decision Index 0.2.1 | Overall | 15.95 score | vendor-run | 7 Oct 2026 |
- JevBench, Capability Score: Row: d1, Liquid AI's hosted API, measured 2026-10-06; dated by the day this release was read so it stays the headline over the open rows below. Intelligence 62.1, Calibration 86.8. 17th by Capability Score on the hosted API board. The open d1-3B and d1-omni-600M rows below are unchanged. Board release v1.8.10, read 2026-11-15.
- Artificial Analysis Decision Index, Index score: Row: d1.1, host Liquid AI. Raw value 66.487. 9th of 22 decision models on version 2.1, checked 2026-11-14. AA marks it the default d1 row. Sub-scores: When2Call accuracy 92.8, Omniscience accuracy 24.2, HLE-MultiChoice accuracy 4.3. Version 2.1 figures do not compare with version 1.0 figures.
- Artificial Analysis Decision Index, Expected calibration error: Row: d1.1. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: d1.1. AA's measured cost per million tasks on its version 2.1 evals.
- Artificial Analysis Decision Index, Time per task: Row: d1.1. Time per task.
- Artificial Analysis Decision Index, Index score: Row: d1, host Liquid AI. Raw value 60.781. 15th of 19 decision models on version 2.1 on 2026-11-12, and 18th of 22 on 2026-11-14, when AA kept it as a second, non-default row behind d1.1. Sub-scores: When2Call accuracy 77.9, Omniscience accuracy 39.8, HLE-MultiChoice accuracy 11.8. Version 2.1 figures do not compare with version 1.0 figures.
- Artificial Analysis Decision Index, Expected calibration error: Row: d1. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: d1. AA's measured cost per million tasks on its version 2.1 evals.
- Artificial Analysis Decision Index, Time per task: Row: d1. Time per task.
- Jev Decision Index, Full score: Row: LiquidAI d1-2B, 196th of 301 rows by this score. Listed first because Liquid's docs point from the deprecated d1-3B to d1-2B. Counts 60% private same-skill tests and 40% private new-domain tests; public benchmarks no longer count. 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: LiquidAI d1-2B, 163rd of 301 rows by this score. Public run; this site treats it as vendor-submitted, like Liquid's other d1 runs.
- Jev Decision Index, Expected calibration error: Row: LiquidAI d1-2B, the lowest of 301 rows. Lower is better. Jev 1.14 scores 0.0799.
- Jev Decision Index, Full score: Row: LiquidAI d1-Omni-2B, 203rd of 301 rows by this score. Counts 60% private same-skill tests and 40% private new-domain tests; public benchmarks no longer count.
- Jev Decision Index, Public score: Row: LiquidAI d1-Omni-2B, 173rd of 301 rows by this score. Public run; this site treats it as vendor-submitted, like Liquid's other d1 runs.
- Jev Decision Index, Expected calibration error: Row: LiquidAI d1-Omni-2B. Lower is better.
- Jev Decision Index, Full score: Row: LiquidAI d1-3B. Counts 60% private same-skill tests and 40% private new-domain tests; public benchmarks no longer count. 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: LiquidAI d1-3B. Public run submitted by Liquid AI.
- Jev Decision Index, Expected calibration error: Row: LiquidAI d1-3B. Lower is better.
- Jev Decision Index, Full score: Row: LiquidAI d1-omni-600M. Counts 60% private same-skill tests and 40% private new-domain tests; public benchmarks no longer count. 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: LiquidAI d1-omni-600M. Public run submitted by Liquid AI.
- Jev Decision Index, Expected calibration error: Row: LiquidAI d1-omni-600M. Lower is better.
- Artificial Analysis Decision Index, Cost per 1M tasks: Row: d1. AA's measured cost at list prices on its four evals. AA showed $30 when first checked on 2026-10-13 and $15 on 2026-10-23.
- Artificial Analysis Decision Index, Index score: Row: d1. Sub-scores: Omniscience accuracy 41.0, non-hallucination 1.7, HLE-MultiChoice 11.5, When2Call 77.4, WildGuardTest F1 90.9. AA names the host as Liquid AI and does not give the model id (d1 or d1:free); this is the hosted model, not d1-3B.
- Artificial Analysis Decision Index, Expected calibration error: Row: d1. Computed by this site from AA's published calibration bins (all answers pooled); AA does not publish an ECE. Lower is better.
- Artificial Analysis Decision Index, Time per task: Row: d1. Median time per task.
- JevBench, Capability Score: Row: Liquid AI d1-3B, measured 2026-10-10. Intelligence 22.1, Calibration 76.9. 183rd among open-weights systems by Capability Score. Board release v1.8.10, read 2026-11-15.
- JevBench, Capability Score: Row: Liquid AI d1-omni-600M, measured 2026-10-10. Intelligence 3.3, Calibration 62.3. 227th among open-weights systems by Capability Score. Board release v1.8.10, read 2026-11-15.
- Jev Decision Index, Full score: Row: LiquidAI d1-3B. Counts 20% public benchmarks and 80% private tests; 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: LiquidAI d1-3B. Public run submitted by Liquid AI.
- Jev Decision Index, Expected calibration error: Row: LiquidAI d1-3B. Lower is better.
- Jev Decision Index, Full score: Row: LiquidAI d1-omni-600M. Counts 20% public benchmarks and 80% private tests; 0 is random guessing, 100 is perfect.
- Jev Decision Index, Public score: Row: LiquidAI d1-omni-600M. Public run submitted by Liquid AI.
- Jev Decision Index, Expected calibration error: Row: LiquidAI d1-omni-600M. Lower is better.
- Jev Decision Index, Overall: Open d1-3B, from Liquid's model card, scored with the Index's own scorer outside the leaderboard.
- Jev Decision Index, Overall: Open d1-omni-600M, from Liquid's model card.