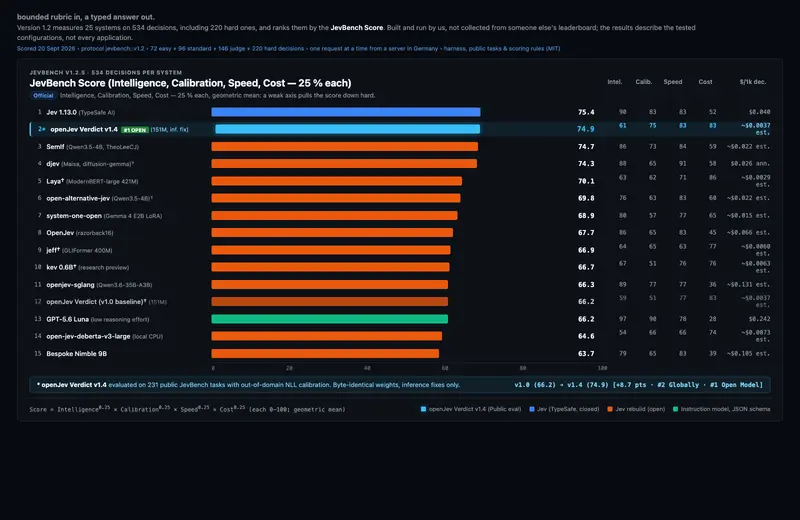
Heman10x-NGU/Verdict-open-jev on GitHub
- Stars
- 91
- Forks
- 11
- Language
- Python
- Last push
- 20 Sep 2026
Read from GitHub on . Counts change daily.
A 151M-parameter non-autoregressive decision model on ModernBERT with calibrated uncertainty, inspired by Jev but trained independently, including a benchmark audit against Jev and an in-browser WebGPU playground.
Read from GitHub on . Counts change daily.
Declares typed input/output Signatures for LLM modules and optimizes the underlying prompts and weights against a metric. Its Signature abstraction is the closest widely-used open equivalent of Jev's typed-question interface. Star count is GitHub's rounded display figure.
Cua's own family of small System 1 models for computer-use decisions, separate from TypeSafe's Jev. CUA-S1-FORMS is the first release, with weights and a dataset on Hugging Face.
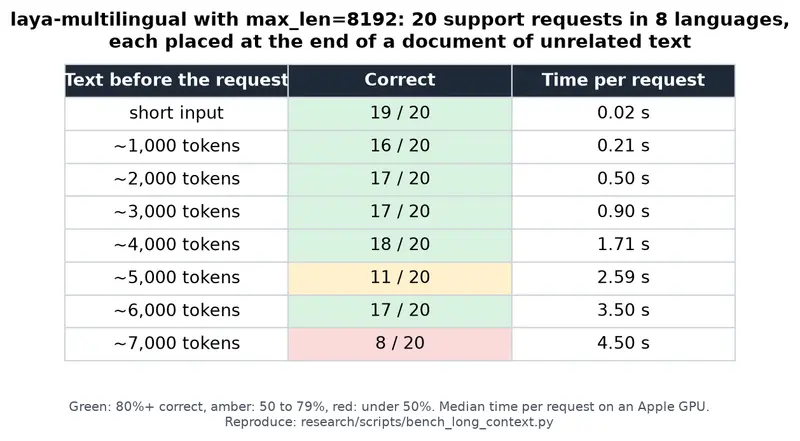
Decision model from Convai Innovations that fully fine-tunes an encoder and adds a typed-decision head: a 421M English checkpoint on ModernBERT-large and a 322M multilingual one on mmBERT-base, with a router picking between them by detected language. Returns choice, score and noul answers, and reports expected calibration error of 0.081 after temperature fitting, down from 0.466 as shipped.
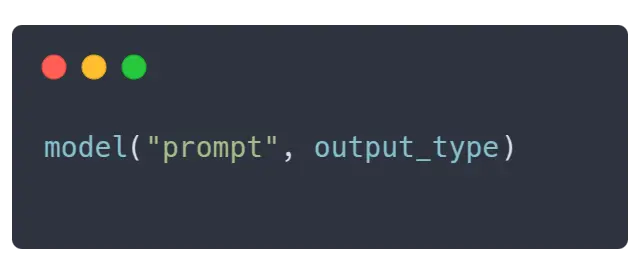
Guarantees valid structured output during generation by constraining decoding to a grammar or schema. The mechanism HN commenters repeatedly cited as already covering Jev's cannot-produce-a-type-error guarantee on ordinary LLMs. Star count is GitHub's rounded display figure.
Pydantic-based library that extracts typed, validated structured data from LLMs across providers with automatic retries. The established way teams get Jev-style typed answers today, at LLM latency and cost. Star count is GitHub's rounded display figure.
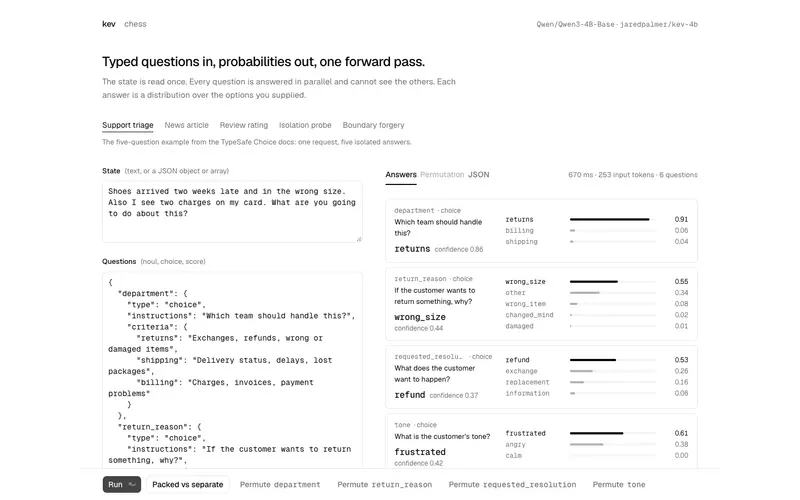
A family of small, self-hosted decision models built on Qwen3.5 at 0.8B, 4B and 9B, with training code and an API that matches TypeSafe's System One so TypeSafe's own Python SDK can point at a local server.


